Lab · runnable experiments
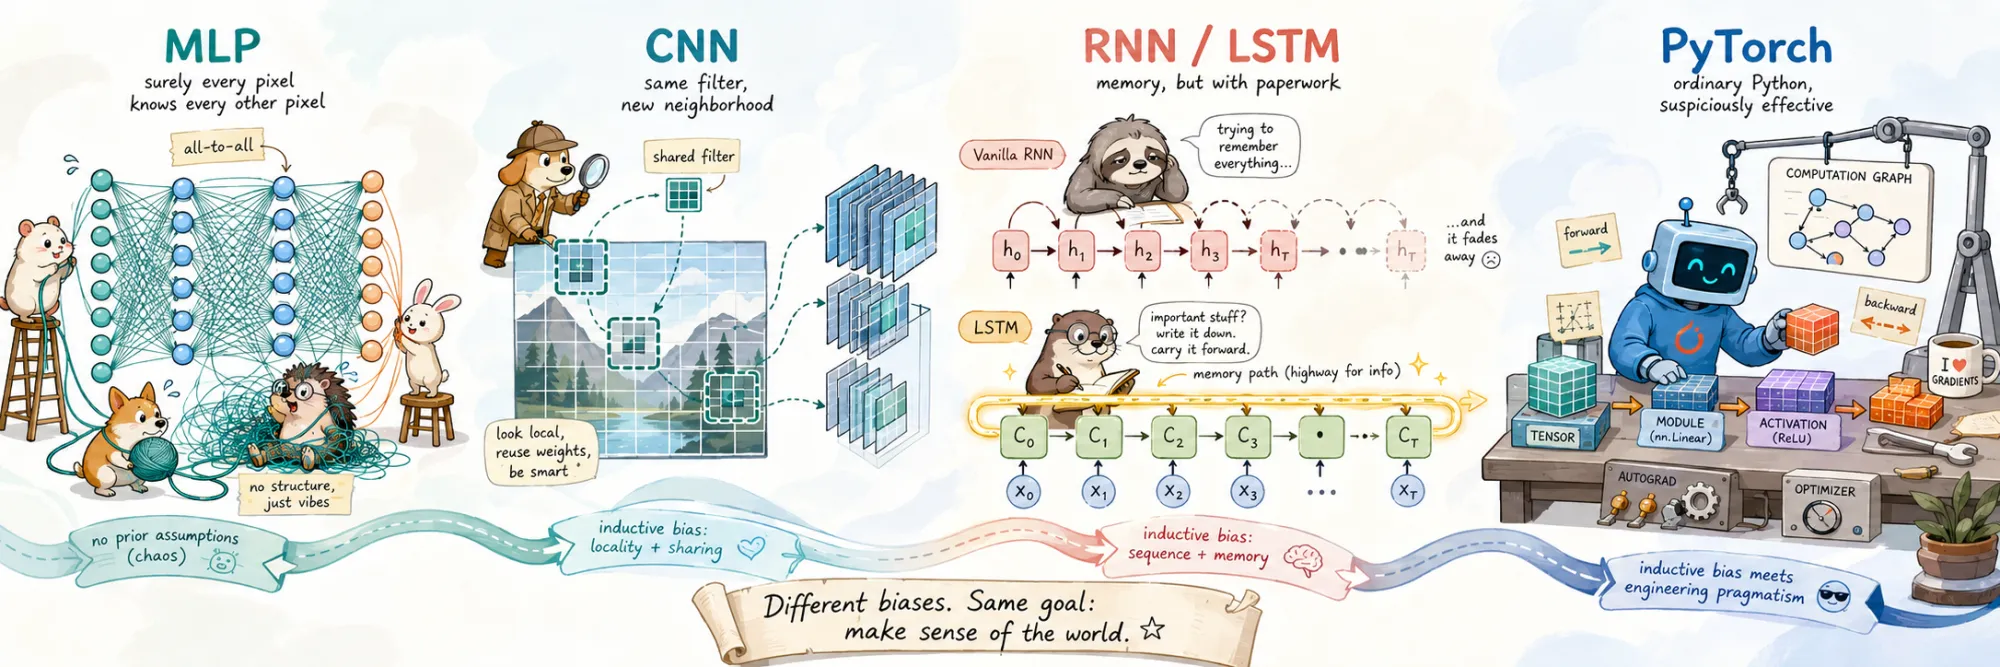
Neural Network Architectures and PyTorch (MLP, CNN, RNN/LSTM)
Created Jul 5, 2026 Updated Jul 21, 2026
Read the parent noteThe note argues the three classical architectures from the inside — what a nonlinearity buys, why a convolution is cheap, how an LSTM keeps a gradient alive. This lab makes each claim run, in two parts. Part 1 reproduces the five experiments behind the note’s widgets end to end: the linear net that can’t bend, the initialization that decides a net’s fate before training, the convolutional filters that become edge detectors on their own, the receptive field that grows with depth, and the vanishing gradient that an LSTM’s cell state carries where a vanilla RNN drops it. Part 2 turns the same skepticism on the framework itself: strides and silent broadcasting bugs, the true byte cost of training, the price of backward, the logits trap, the GPU’s asynchronous stopwatch, and what torch.compile does and does not buy. Nothing is asserted that isn’t measured.
Setup
pip install torch torchvision numpy pandas matplotlibimport time, datetime
import numpy as np, pandas as pd, torch, torch.nn as nn, torch.nn.functional as F
import matplotlib.pyplot as plt
torch.manual_seed(0); np.random.seed(0)
# training here is small enough for CPU; a GPU, if present, only speeds it up — the
# conclusions don't depend on it, though tiny numerical differences can occur across platforms
device = "cuda" if torch.cuda.is_available() else ("mps" if torch.backends.mps.is_available() else "cpu")
INK, LINE, CREAM = "#2a2a2a", "#d9d3c7", "#f6f2e9"
BLUE, EMBER, FOREST, GRAY = "#3b6ea5", "#c4521e", "#2e7d5b", "#9a9384"
plt.rcParams.update({"font.size": 9, "axes.edgecolor": LINE, "axes.spines.top": False,
"axes.spines.right": False, "figure.dpi": 120})
print("executed:", datetime.date.today().isoformat())executed: 2026-07-21An MLP is only as good as its nonlinearity
A fully-connected network is a stack of affine maps Wx + b with an activation between them. Strip the activation and the algebra collapses: two linear layers compose to one, W2(W1x) = (W2W1)x, so any depth of linear layers is a single linear map with a straight-line boundary. We test that on a two-spiral problem, and in the same breath ask the other question everyone has — does depth beat width at a fixed parameter budget? Three nets, same ~900 parameters: a linear stack, a wide one-layer ReLU net, and a narrow five-layer ReLU net.
def spirals(n=3000, turns=4.0, noise=0.02, seed=0):
    g = torch.Generator().manual_seed(seed)
    t = torch.rand(n, generator=g) ** 0.5
    ang = t * turns * 2 * np.pi
    s = torch.randint(0, 2, (n,), generator=g)
    ang = ang + s * np.pi
    return torch.stack([t * torch.cos(ang), t * torch.sin(ang)], 1) + noise * torch.randn(n, 2, generator=g), s

Xs, ys = spirals()
sidx = torch.randperm(len(Xs)); str_, ste = sidx[:2100], sidx[2100:]

def make(kind):
    if kind == "linear":  return nn.Sequential(nn.Linear(2, 181), nn.Linear(181, 2))     # no activation
    if kind == "shallow": return nn.Sequential(nn.Linear(2, 181), nn.ReLU(), nn.Linear(181, 2))
    layers, d = [], 2                                                                     # deep-narrow
    for _ in range(5): layers += [nn.Linear(d, 14), nn.ReLU()]; d = 14
    return nn.Sequential(*layers, nn.Linear(14, 2))

def train_spiral(kind, seed, epochs=4000):
    torch.manual_seed(seed); m = make(kind); opt = torch.optim.Adam(m.parameters(), 5e-3)
    for _ in range(epochs):
        opt.zero_grad(); F.cross_entropy(m(Xs[str_]), ys[str_]).backward(); opt.step()
    acc = (m(Xs[ste]).argmax(1) == ys[ste]).float().mean().item()
    return acc, m

SEEDS = 5
rows, models = [], {}
for kind, label in [("linear", "linear (no activation)"), ("shallow", "1 ReLU layer, wide"), ("deep", "5 ReLU layers, narrow")]:
    runs = [train_spiral(kind, s) for s in range(SEEDS)]
    accs = [a for a, _ in runs]; best = int(np.argmax(accs)); models[kind] = runs[best][1]
    p = sum(pr.numel() for pr in make(kind).parameters())
    rows.append({"architecture": label, "params": p, "test acc": f"{np.mean(accs):.2f} ± {np.std(accs):.2f}"})
pd.DataFrame(rows)| architecture | params | test acc | |
|---|---|---|---|
| 0 | linear (no activation) | 907 | 0.58 ± 0.00 |
| 1 | 1 ReLU layer, wide | 907 | 0.86 ± 0.01 |
| 2 | 5 ReLU layers, narrow | 912 | 0.87 ± 0.06 |
gg = np.linspace(-1.15, 1.15, 120); XX, YY = np.meshgrid(gg, gg)
grid = torch.tensor(np.stack([XX.ravel(), YY.ravel()], 1), dtype=torch.float32)
fig, axs = plt.subplots(1, 3, figsize=(7.4, 2.7))
for ax, (kind, label) in zip(axs, [("linear", "linear"), ("shallow", "1 ReLU · wide"), ("deep", "5 ReLU · narrow")]):
    with torch.no_grad(): P = torch.softmax(models[kind](grid), 1)[:, 1].numpy().reshape(120, 120)
    ax.imshow(P, extent=[-1.15, 1.15, -1.15, 1.15], origin="lower", cmap="RdBu", alpha=0.8)
    ax.scatter(Xs[:, 0], Xs[:, 1], c=ys, cmap="RdBu", s=2, edgecolors="k", linewidths=0.1)
    ax.set_title(label, fontsize=9); ax.set_xticks([]); ax.set_yticks([])
plt.tight_layout(); plt.show()
The linear panel is the lesson: no matter how many linear layers you stack, the boundary is one straight line, and accuracy sits at chance. The activation is the entire reason a deep stack is more than one layer. And the two ReLU panels — wide-shallow versus narrow-deep — tie, which is the honest correction to “deeper is always better”: on a low-dimensional problem, they are interchangeable.
Initialization decides whether the net is alive at birth
He init is not folklore: every layer multiplies the signal’s scale by a near-constant factor, so the initial weight variance compounds geometrically with depth. We push a real MNIST batch through a 40-layer, 256-wide ReLU stack — no training, just one forward and one backward pass — at three scales around He’s √(2/d), and record the standard deviation of the signal at every layer.
from torchvision import datasets, transforms
mte0 = datasets.MNIST("scripts/.cache/mnist", train=False, download=True,
                      transform=transforms.ToTensor())
xb0 = torch.stack([mte0[i][0] for i in range(256)]).reshape(256, -1).double()
xb0 = (xb0 - xb0.mean()) / xb0.std()                     # standardized real pixels

def signal(gain, depth=40, width=256, seeds=4):
    fwd, bwd = np.zeros(depth), np.zeros(depth)
    for s in range(seeds):
        torch.manual_seed(s)
        lins = [nn.Linear(784 if i == 0 else width, width, bias=False).double()
                for i in range(depth)]
        for l in lins:
            nn.init.normal_(l.weight, std=gain * np.sqrt(2.0 / l.weight.shape[1]))
        acts, h = [], xb0
        for l in lins:
            h = torch.relu(l(h)); h.retain_grad(); acts.append(h)
        acts[-1].mean().backward()                       # one backward, no training
        fwd += [np.log10(max(float(a.detach().std()), 1e-300)) for a in acts]
        bwd += [np.log10(max(float(a.grad.std()), 1e-300)) for a in acts]
    return fwd / seeds, bwd / seeds

sig = {g: signal(g) for g in (0.5, 1.0, 2.0)}
pd.DataFrame([{"init scale": f"{g} × He std", "activation std @ layer 40": f"1e{round(sig[g][0][-1]):+d}",
"gradient std @ layer 1": f"1e{round(sig[g][1][0]):+d}"} for g in sig])| init scale | activation std @ layer 40 | gradient std @ layer 1 | |
|---|---|---|---|
| 0 | 0.5 × He std | 1e-12 | 1e-16 |
| 1 | 1.0 × He std | 1e+0 | 1e-4 |
| 2 | 2.0 × He std | 1e+12 | 1e+8 |
fig, ax = plt.subplots(figsize=(6.6, 3.2))
ax.set_axisbelow(True); ax.grid(axis="y", color=LINE, alpha=0.7)
for (g, (f, b)), col in zip(sig.items(), [BLUE, FOREST, EMBER]):
    ax.plot(range(1, 41), f, color=col, label=f"{g} × He", linewidth=2)
ax.axhspan(-0.5, 0.5, color=FOREST, alpha=0.05)
ax.set_xlabel("layer"); ax.set_ylabel("log10 activation std")
ax.legend(fontsize=8)
plt.tight_layout(); plt.show()
One constant in the initializer, twelve orders of magnitude at the far end — the difference between a trainable net and a dead one, decided before the first gradient step.
A convolution shares its weights — and learns edge detectors on its own
A fully-connected first layer on a 224×224×3 image needs 150 million parameters. A convolution reuses one small kernel at every position, so its parameter count doesn’t depend on image size at all.
def mlp_p(hw, c, n): return hw * hw * c * n + n
def conv_p(f, k, c): return f * k * k * c + f
pd.DataFrame([
    {"first layer": "MLP  224×224×3 → 1000", "parameters": mlp_p(224, 3, 1000)},
    {"first layer": "Conv 3×3×3 × 64 filters", "parameters": conv_p(64, 3, 3)},
    {"first layer": "MLP  28×28×1 → 128", "parameters": mlp_p(28, 1, 128)},
    {"first layer": "Conv 3×3×1 × 32 filters", "parameters": conv_p(32, 3, 1)},
])| first layer | parameters | |
|---|---|---|
| 0 | MLP 224×224×3 → 1000 | 150529000 |
| 1 | Conv 3×3×3 × 64 filters | 1792 |
| 2 | MLP 28×28×1 → 128 | 100480 |
| 3 | Conv 3×3×1 × 32 filters | 320 |
Now the full training loop the note describes — define the architecture, then just write the forward pass and let autograd do the rest. This trains a small CNN on MNIST.
from torchvision import datasets, transforms
tf = transforms.ToTensor()
mtr = datasets.MNIST("scripts/.cache/mnist", train=True, download=True, transform=tf)
mte = datasets.MNIST("scripts/.cache/mnist", train=False, download=True, transform=tf)

class CNN(nn.Module):
    def __init__(self):
        super().__init__()
        self.c1 = nn.Conv2d(1, 8, 7, padding=3)          # 8 learned 7×7 filters
        self.c2 = nn.Conv2d(8, 16, 3, padding=1)
        self.fc = nn.Linear(16 * 7 * 7, 10)
    def feat(self, x): return F.relu(self.c1(x))          # first-layer feature maps
    def forward(self, x):
        x = F.max_pool2d(self.feat(x), 2)
        x = F.max_pool2d(F.relu(self.c2(x)), 2)
        return self.fc(x.flatten(1))

torch.manual_seed(0)
cnn = CNN().to(device)
opt = torch.optim.AdamW(cnn.parameters(), 1e-3, weight_decay=1e-4)
loader = torch.utils.data.DataLoader(mtr, batch_size=128, shuffle=True)
t0 = time.time()
for epoch in range(6):
    cnn.train()
    for xb, yb in loader:
        xb, yb = xb.to(device), yb.to(device)
        opt.zero_grad(); F.cross_entropy(cnn(xb), yb).backward(); opt.step()

cnn.eval(); correct = 0
with torch.no_grad():
    for xb, yb in torch.utils.data.DataLoader(mte, 512):
        correct += (cnn(xb.to(device)).argmax(1).cpu() == yb).sum().item()
print(f"trained 6 epochs in {time.time()-t0:.0f}s  ·  test accuracy {correct/len(mte):.3f}")
trained 6 epochs in 15s · test accuracy 0.986W = cnn.c1.weight.detach().cpu().numpy(); W = W / np.abs(W).max()
def sample(t):
for x, y in mte:
if y == t: return x
digs = [7, 3]
fig, axs = plt.subplots(len(digs) + 1, 9, figsize=(7.6, 3.4))
for j in range(8): axs[0, j].imshow(W[j, 0], cmap="RdBu_r", vmin=-1, vmax=1); axs[0, j].set_title(f"f{j}", fontsize=7)
axs[0, 8].axis("off"); axs[0, 0].set_ylabel("filters", fontsize=8)
for r, d in enumerate(digs):
x = sample(d)
with torch.no_grad(): fm = cnn.feat(x.unsqueeze(0).to(device))[0].cpu().numpy()
axs[r + 1, 0].imshow(x.numpy()[0], cmap="gray_r"); axs[r + 1, 0].set_title(f"digit {d}", fontsize=7)
for j in range(8): axs[r + 1, j + 1].imshow(fm[j], cmap="magma")
for ax in axs.flat: ax.set_xticks([]); ax.set_yticks([])
plt.tight_layout(); plt.show()
How far one neuron sees: the receptive field
The region of the input a single deep neuron can see — its receptive field — is pure arithmetic: rℓ = rℓ − 1 + (k − 1) ⋅ jumpℓ − 1, with the jump multiplying by the stride each layer. Plain 3×3 stride-1 grows it by +2 per layer; adding pooling makes it grow with the stride product.
def rf(layers):
    r, jump, out = 1, 1, []
    for i, (k, s) in enumerate(layers, 1):
        r += (k - 1) * jump; jump *= s; out.append((i, r, jump))
    return out
plain = rf([(3, 1)] * 12)
pooled = rf(sum([[(3, 1), (3, 1), (2, 2)] for _ in range(4)], []))
print("plain 3×3 stride-1 : RF after 12 layers =", plain[-1][1], "px  (→ 112 layers to cover 224px)")
print("with 2×2 pooling   : RF after", len(pooled), "ops =", pooled[-1][1], "px")

# the VGG argument: stacked small kernels vs one big kernel
pd.DataFrame([
    {"stack": f"{n} × (3×3)", "field": f"{1+2*n}×{1+2*n}", "params": n*9,
     "nonlin": n, "one big kernel": (1+2*n)**2, "param saving": f"{(1+2*n)**2/(n*9):.2f}×"}
    for n in (2, 3)
])
plain 3×3 stride-1 : RF after 12 layers = 25 px (→ 112 layers to cover 224px)
with 2×2 pooling : RF after 12 ops = 76 px| stack | field | params | nonlin | one big kernel | param saving | |
|---|---|---|---|---|---|---|
| 0 | 2 × (3×3) | 5×5 | 18 | 2 | 25 | 1.39× |
| 1 | 3 × (3×3) | 7×7 | 27 | 3 | 49 | 1.81× |
fig, ax = plt.subplots(figsize=(6.4, 3))
ax.set_axisbelow(True); ax.grid(axis="y", color=LINE, alpha=0.8)
ax.plot([p[0] for p in plain], [p[1] for p in plain], "o-", color=BLUE, label="plain 3×3 stride-1")
ax.plot(range(1, len(pooled) + 1), [p[1] for p in pooled], "o-", color=EMBER, label="3×3 + 2×2 pooling")
ax.set_xlabel("layers / operations"); ax.set_ylabel("receptive field (px)"); ax.legend()
plt.tight_layout(); plt.show()
The vanishing gradient, and the LSTM highway
A vanilla RNN backpropagates through time by chaining one factor of Wh per step, so the gradient reaching an early input is a geometric product that collapses toward zero. An LSTM routes memory through a cell state whose step-to-step derivative is just the forget gate — an additive highway. We measure it directly: unroll each cell, put a loss on the last state, and read ‖∂loss/∂xt‖ at every step, relative to the last.
torch.set_default_dtype(torch.float64)                   # clean magnitudes across 20 decades
H, T, VS = 32, 60, 12
def reach(kind, forget_bias=None):
    curves = []
    for s in range(VS):
        torch.manual_seed(s)
        x = torch.randn(T, 1, H, requires_grad=True)
        if kind == "rnn":
            cell = nn.RNNCell(H, H); h = torch.zeros(1, H)
            for t in range(T): h = cell(x[t], h)
            out = h
        else:
            cell = nn.LSTMCell(H, H)
            if forget_bias is not None:
                with torch.no_grad():
                    cell.bias_ih[H:2*H] = forget_bias/2; cell.bias_hh[H:2*H] = forget_bias/2
            h, c = torch.zeros(1, H), torch.zeros(1, H)
            for t in range(T): h, c = cell(x[t], (h, c))
            out = h
        g, = torch.autograd.grad(out.pow(2).sum(), x)
        n = g.reshape(T, -1).norm(dim=1).detach().numpy(); curves.append(n / (n[-1] + 1e-300))
    return np.mean(curves, axis=0)[::-1]                  # index 0 = last step

curves = {"vanilla RNN": reach("rnn"), "LSTM (default)": reach("lstm"), "LSTM · forget-bias=3": reach("lstm", 3.0)}
# the forget-bias sweep from the note's slider: gradient ~ sigmoid(b)^k, decade by decade
sweep = {f"LSTM · forget-bias={b}": reach("lstm", float(b)) for b in (0, 1, 2, 4)}
torch.set_default_dtype(torch.float32)
pd.DataFrame([{"model": k, "reach @10 back": f"{v[10]:.0e}", "reach @30 back": f"{v[30]:.0e}",
"reach @59 back": f"{v[59]:.0e}"} for k, v in {**curves, **sweep}.items()])| model | reach @10 back | reach @30 back | reach @59 back | |
|---|---|---|---|---|
| 0 | vanilla RNN | 3e-04 | 5e-11 | 3e-20 |
| 1 | LSTM (default) | 3e-03 | 2e-07 | 2e-13 |
| 2 | LSTM · forget-bias=3 | 2e-01 | 2e-01 | 3e-01 |
| 3 | LSTM · forget-bias=0 | 3e-03 | 8e-08 | 3e-14 |
| 4 | LSTM · forget-bias=1 | 6e-02 | 7e-04 | 1e-06 |
| 5 | LSTM · forget-bias=2 | 2e-01 | 6e-02 | 1e-02 |
| 6 | LSTM · forget-bias=4 | 2e-01 | 3e-01 | 9e-01 |
fig, ax = plt.subplots(figsize=(6.6, 3.2))
ax.set_axisbelow(True); ax.grid(axis="y", color=LINE, alpha=0.7)
for (label, v), col in zip(curves.items(), [EMBER, BLUE, FOREST]):
    ax.semilogy(range(T), np.maximum(v, 1e-21), color=col, label=label, linewidth=2)
ax.axhspan(1e-21, 1e-6, color=EMBER, alpha=0.05)
ax.set_xlabel("steps back from the output"); ax.set_ylabel("gradient reach (relative)")
ax.set_ylim(1e-21, 2); ax.legend(fontsize=8)
plt.tight_layout(); plt.show()
Part 2 — the framework itself, measured
The note’s second half makes claims about PyTorch’s machinery: that a tensor is strides over memory, that broadcasting fails silently, that training costs ~16 bytes per parameter before the first activation, that backward is a couple of forwards, that the GPU lies to a naive stopwatch, that torch.compile wins exactly where memory bandwidth is the bottleneck. Frameworks deserve the same treatment as architectures: measure, don’t trust. Everything below runs on this machine.
A tensor is a pointer, a shape, and strides
transpose is free because it touches no data — it returns a view with swapped strides over the same memory. The price is deferred: a later view() can refuse, because the memory order no longer matches the shape it is asked to produce.
t = torch.arange(12.).reshape(3, 4)
v = t.t()
try:
    v.view(12); view_err = "worked"
except RuntimeError:
    view_err = "RuntimeError — memory order no longer matches the shape"
pd.DataFrame([
    {"tensor": "t = arange(12).reshape(3,4)", "shape": str(tuple(t.shape)), "strides": str(t.stride()),
     "same memory as t": "—"},
    {"tensor": "t.t()", "shape": str(tuple(v.shape)), "strides": str(v.stride()),
     "same memory as t": str(v.data_ptr() == t.data_ptr())},
    {"tensor": "t.t().contiguous()", "shape": str(tuple(v.contiguous().shape)), "strides": str(v.contiguous().stride()),
     "same memory as t": str(v.contiguous().data_ptr() == t.data_ptr())},
    {"tensor": "t.t().view(12)", "shape": "—", "strides": "—", "same memory as t": view_err},
])| tensor | shape | strides | same memory as t | |
|---|---|---|---|---|
| 0 | t = arange(12).reshape(3,4) | (3, 4) | (4, 1) | — |
| 1 | t.t() | (4, 3) | (1, 4) | True |
| 2 | t.t().contiguous() | (4, 3) | (3, 1) | False |
| 3 | t.t().view(12) | — | — | RuntimeError — memory order no longer matches ... |
big = torch.randn(8192, 8192)                      # 256 MB
t0 = time.perf_counter(); bt = big.t();                     t_view = (time.perf_counter() - t0) * 1e6
t0 = time.perf_counter(); bc = bt.contiguous();             t_copy = (time.perf_counter() - t0) * 1e6
pd.DataFrame([{"op": "transpose (new strides)", "time": f"{t_view:.0f} µs"},
{"op": ".contiguous() (real copy of 256 MB)", "time": f"{t_copy/1000:.0f} ms"}])| op | time | |
|---|---|---|
| 0 | transpose (new strides) | 47 µs |
| 1 | .contiguous() (real copy of 256 MB) | 88 ms |
Stride arithmetic versus a genuine copy — orders of magnitude apart, on the same nominal “reshaping”.
Broadcasting failures are silent
Subtract a (B,) target from a (B,1) prediction and nothing errors: broadcasting produces a (B,B) matrix of all pairwise differences, the “loss” averages over it, the optimizer happily minimizes the wrong quantity. We fit y = 3x + 1 both ways.
torch.manual_seed(0)
Xr = torch.randn(512, 1); yr = 3 * Xr[:, 0] + 1 + 0.05 * torch.randn(512)   # target shape (512,)

def fit(buggy):
    torch.manual_seed(1)
    lin = nn.Linear(1, 1); opt = torch.optim.Adam(lin.parameters(), 5e-2)
    for _ in range(600):
        opt.zero_grad()
        pred = lin(Xr)                              # shape (512, 1)
        diff = pred - yr if buggy else pred.squeeze(1) - yr
        loss = (diff ** 2).mean()
        loss.backward(); opt.step()
    true_mse = ((lin(Xr).squeeze(1) - yr) ** 2).mean().item()
    return loss.item(), true_mse, lin.weight.item(), lin.bias.item(), str(tuple(diff.shape))

rows = []
for buggy, name in [(True, "buggy: (512,1) − (512,)"), (False, "fixed: (512,) − (512,)")]:
    l, mse, w, b, shp = fit(buggy)
    rows.append({"version": name, "diff shape": shp, "training 'loss'": f"{l:.3f}",
                 "true MSE": f"{mse:.3f}", "learned w": f"{w:.2f}", "learned b": f"{b:.2f}"})
pd.DataFrame(rows)| version | diff shape | training 'loss' | true MSE | learned w | learned b | |
|---|---|---|---|---|---|---|
| 0 | buggy: (512,1) − (512,) | (512, 512) | 9.254 | 9.254 | 0.00 | 1.19 |
| 1 | fixed: (512,) − (512,) | (512,) | 0.003 | 0.003 | 3.00 | 1.00 |
The buggy run’s loss goes down and converges — to a model with the slope near zero: minimizing the mean over all pairs is solved by predicting the target’s mean, so the optimizer diligently destroys the model while every number on the screen improves. No crash, no warning. This is why the discipline is to know the intended shape of every tensor, and assert when in doubt.
Training memory: ~16 bytes per parameter, then activations
The note’s arithmetic — weight + gradient + two Adam moments — measured on a real model, by asking every tensor its actual byte size.
mem_net = nn.Sequential(*[l for _ in range(6) for l in (nn.Linear(2048, 2048), nn.GELU())])
mem_opt = torch.optim.AdamW(mem_net.parameters(), 1e-3)
xm = torch.randn(256, 2048)
mem_net(xm).pow(2).mean().backward(); mem_opt.step()

pbytes = sum(p.numel() * p.element_size() for p in mem_net.parameters())
gbytes = sum(p.grad.numel() * p.grad.element_size() for p in mem_net.parameters())
sbytes = sum(t.numel() * t.element_size() for st in mem_opt.state.values()
             for t in st.values() if torch.is_tensor(t))
pd.DataFrame([
    {"tensors": "weights", "size": f"{pbytes/1e6:.0f} MB"},
    {"tensors": "gradients", "size": f"{gbytes/1e6:.0f} MB"},
    {"tensors": "AdamW moments (m, v)", "size": f"{sbytes/1e6:.0f} MB"},
    {"tensors": "total held for training", "size": f"{(pbytes+gbytes+sbytes)/1e6:.0f} MB  =  {(pbytes+gbytes+sbytes)/pbytes:.2f} × weights"},
])| tensors | size | |
|---|---|---|
| 0 | weights | 101 MB |
| 1 | gradients | 101 MB |
| 2 | AdamW moments (m, v) | 201 MB |
| 3 | total held for training | 403 MB = 4.00 × weights |
And the part that scales with batch, not with the model: the activations autograd keeps alive for backward. We count them with forward hooks.
def act_bytes(batch):
    seen = []
    hooks = [m.register_forward_hook(lambda _m, _i, o: seen.append(o.numel() * o.element_size()))
             for m in mem_net if isinstance(m, (nn.Linear, nn.GELU))]
    mem_net(torch.randn(batch, 2048))
    for h in hooks: h.remove()
    return sum(seen)

pd.DataFrame([{"batch": b, "activation memory (one forward)": f"{act_bytes(b)/1e6:.0f} MB"}
for b in (32, 128, 512)])| batch | activation memory (one forward) | |
|---|---|---|
| 0 | 32 | 3 MB |
| 1 | 128 | 13 MB |
| 2 | 512 | 50 MB |
Linear in the batch size — which is why the standard out-of-memory fix is a smaller batch, and why gradient checkpointing (recompute instead of store) exists at all.
Backward costs a couple of forwards — and no_grad drops the tape
for _ in range(3): mem_net(xm)                     # warmup
t0 = time.perf_counter()
for _ in range(10):
    with torch.no_grad(): mem_net(xm)
t_ng = (time.perf_counter() - t0) / 10 * 1000
t0 = time.perf_counter()
for _ in range(10): mem_net(xm)
t_fwd = (time.perf_counter() - t0) / 10 * 1000
t0 = time.perf_counter()
for _ in range(10): mem_net(xm).pow(2).mean().backward()
t_full = (time.perf_counter() - t0) / 10 * 1000
pd.DataFrame([
    {"pass": "forward under no_grad", "time": f"{t_ng:.1f} ms", "vs forward": f"{t_ng/t_fwd:.2f}×"},
    {"pass": "forward (tape recording)", "time": f"{t_fwd:.1f} ms", "vs forward": "1.00×"},
    {"pass": "forward + backward", "time": f"{t_full:.1f} ms", "vs forward": f"{t_full/t_fwd:.2f}×"},
])| pass | time | vs forward | |
|---|---|---|---|
| 0 | forward under no_grad | 9.8 ms | 0.99× |
| 1 | forward (tape recording) | 9.9 ms | 1.00× |
| 2 | forward + backward | 32.8 ms | 3.31× |
One scalar loss, ~100 MB of parameters, every gradient — for roughly the price of two extra forwards. That asymmetry is reverse-mode differentiation, and it is why training giant models is affordable at all.
Gradient accumulation is exact, not approximate
The note calls accumulating gradients “a feature and a bug magnet”. The feature part is provable: gradients are sums over examples, so four backward passes over quarters of a batch accumulate to the same gradient as one pass over all of it.
def grads_of(fn):
    mem_net.zero_grad(); fn()
    return [p.grad.clone() for p in mem_net.parameters()]

xb_ = torch.randn(256, 2048)
g_full = grads_of(lambda: mem_net(xb_).pow(2).sum().backward())
g_acc = grads_of(lambda: [mem_net(chunk).pow(2).sum().backward() for chunk in xb_.split(64)])
max_diff = max((a - b).abs().max().item() for a, b in zip(g_full, g_acc))
print(f"max |full-batch grad − accumulated grad| = {max_diff:.2e}")
max |full-batch grad − accumulated grad| = 3.58e-07Float rounding, nothing more. Splitting a batch that doesn’t fit in memory into micro-batches is mathematically free — as long as you remember which side of zero_grad you are on.
The logits trap: why CrossEntropyLoss wants raw scores
logits = torch.tensor([[89.0, 0.0]])               # a confident model, nothing exotic
e = torch.exp(logits)                              # softmax by its textbook formula
naive = -torch.log(e / e.sum(1, keepdim=True))[0, 1]
fused = F.cross_entropy(logits, torch.tensor([1]))
pd.DataFrame([
    {"quantity": "exp(89) in float32", "value": str(torch.exp(torch.tensor(89.0)).item())},
    {"quantity": "softmax by the formula, −log p₁", "value": str(naive.item())},
    {"quantity": "F.cross_entropy (fused, log-sum-exp)", "value": f"{fused.item():.1f}"},
])| quantity | value | |
|---|---|---|
| 0 | exp(89) in float32 | inf |
| 1 | softmax by the formula, −log p₁ | inf |
| 2 | F.cross_entropy (fused, log-sum-exp) | 89.0 |
exp overflows float32 at logits a confident model produces without effort, and the textbook softmax collapses — inf/inf gives nan for the top class, exactly 0 for every other, so the loss comes out inf and one optimizer step later the weights are NaN. Every stable implementation — including torch.softmax itself — subtracts the max logit first; the fused loss does it for you in log space, which is the whole reason the API wants logits, not probabilities. (The subtraction changes nothing mathematically and everything numerically — the same trick as the log-sum-exp identity in the note.)
model.eval() is not a formality
torch.manual_seed(0)
dnet = nn.Sequential(nn.Flatten(), nn.Linear(784, 256), nn.ReLU(), nn.Dropout(0.5),
                     nn.Linear(256, 10))
dopt = torch.optim.Adam(dnet.parameters(), 1e-3)
sub = torch.utils.data.Subset(mtr, range(10_000))
for xb, yb in torch.utils.data.DataLoader(sub, batch_size=128, shuffle=True):
    dopt.zero_grad(); F.cross_entropy(dnet(xb), yb).backward(); dopt.step()

xt = torch.stack([mte[i][0] for i in range(2000)]); yt = torch.tensor([mte[i][1] for i in range(2000)])
def acc():
    with torch.no_grad(): return (dnet(xt).argmax(1) == yt).float().mean().item()
dnet.train()
runs = [f"{acc():.3f}" for _ in range(3)]
dnet.eval()
pd.DataFrame([{"mode": "train() during evaluation — dropout still active", "accuracy": " / ".join(runs)},
{"mode": "eval() — dropout off", "accuracy": f"{acc():.3f}"}])| mode | accuracy | |
|---|---|---|
| 0 | train() during evaluation — dropout still active | 0.834 / 0.828 / 0.822 |
| 1 | eval() — dropout off | 0.858 |
Forget the switch and evaluation runs with dropout still zeroing half the activations: accuracy drops and changes from run to run on identical data. The failure is silent — nothing errors, the numbers are just quietly wrong.
The GPU lies to a naive stopwatch
Kernel launches are asynchronous: Python enqueues work and returns immediately. On this machine’s Apple-silicon GPU (MPS — same execution model as CUDA):
if torch.backends.mps.is_available():
    am = torch.randn(4096, 4096, device="mps"); bm = torch.randn(4096, 4096, device="mps")
    for _ in range(3): am @ bm
    torch.mps.synchronize()
    t0 = time.perf_counter(); cm_ = am @ bm;                          naive = (time.perf_counter() - t0) * 1000
    t0 = time.perf_counter(); cm_ = am @ bm; torch.mps.synchronize(); synced = (time.perf_counter() - t0) * 1000
    display(pd.DataFrame([
        {"measurement": "time.perf_counter around the matmul", "time": f"{naive:.2f} ms", "what it measured": "how fast Python can enqueue"},
        {"measurement": "same, + torch.mps.synchronize()", "time": f"{synced:.2f} ms", "what it measured": "the actual computation"},
    ]))
else:
print("no GPU available on this machine — on CUDA the same experiment uses torch.cuda.synchronize()")| measurement | time | what it measured | |
|---|---|---|---|
| 0 | time.perf_counter around the matmul | 0.17 ms | how fast Python can enqueue |
| 1 | same, + torch.mps.synchronize() | 24.00 ms | the actual computation |
Two orders of magnitude apart. Every “my GPU op takes 0.2 ms” benchmark that forgot to synchronize measured the queue, not the compute.
torch.compile: fusion pays where memory is the bottleneck — measure it
The note claims compile’s speedup comes from kernel fusion on memory-bound chains. We test the mechanism three ways: an elementwise chain (eight memory round trips that fusion collapses into one loop) pinned to a single core, the same chain with all cores, and a matmul-heavy MLP where BLAS is already optimal and there is nothing to fuse.
def chain(x):                                     # 8 elementwise ops = 8 memory round trips
    return ((x.sin() + x.cos()) * x.sigmoid() - x.tanh()).relu().sqrt().log1p().exp()

xc = torch.randn(4_000_000)
cchain = torch.compile(chain)
mlp_c = nn.Sequential(nn.Linear(1024, 1024), nn.GELU(), nn.Linear(1024, 1024), nn.GELU(),
                      nn.Linear(1024, 1024))
cmlp = torch.compile(mlp_c)
xm_c = torch.randn(256, 1024)
with torch.no_grad(): cchain(xc); cmlp(xm_c)      # first calls pay for compilation

def bench(fn, arg, reps=10):
    with torch.no_grad():
        for _ in range(3): fn(arg)
        t0 = time.perf_counter()
        for _ in range(reps): fn(arg)
        return (time.perf_counter() - t0) / reps * 1000

rows = []
nthreads = torch.get_num_threads()
torch.set_num_threads(1)
rows.append(("elementwise chain · 1 core", bench(chain, xc), bench(cchain, xc)))
torch.set_num_threads(nthreads)
rows.append((f"elementwise chain · {nthreads} cores", bench(chain, xc), bench(cchain, xc)))
rows.append(("matmul MLP (compute-bound)", bench(mlp_c, xm_c), bench(cmlp, xm_c)))
pd.DataFrame([{"workload": n, "eager": f"{e:.2f} ms", "compiled": f"{c:.2f} ms",
"speedup": f"{e/c:.2f}×"} for n, e, c in rows])| workload | eager | compiled | speedup | |
|---|---|---|---|---|
| 0 | elementwise chain · 1 core | 40.21 ms | 5.72 ms | 7.03× |
| 1 | elementwise chain · 12 cores | 6.48 ms | 8.18 ms | 0.79× |
| 2 | matmul MLP (compute-bound) | 1.87 ms | 1.70 ms | 1.11× |
The first row is the mechanism, isolated: per core, fusing eight memory round trips into one loop is worth ~6×, exactly as the bandwidth arithmetic predicts. The other two rows are the honest print: with all cores, eager hides the memory traffic behind threading while this machine’s generated code runs single-threaded, and the win evaporates (or inverts); on the matmul MLP the time already lives inside optimized BLAS kernels and fusion has next to nothing to save — the ratio hovers around 1× either way. On server CPUs and GPUs the fused kernel parallelizes too, which is where the typical 1.3–2× whole-model speedups come from — but the lesson survives any hardware: torch.compile is not magic, it is saved memory traffic, and the only benchmark that matters is your workload on your machine.
What we just did
We built the three classical architectures in a few lines of PyTorch each and let real data settle five claims the note makes. A linear stack, however deep, can only draw a straight line — the nonlinearity is what makes an MLP an MLP — while depth and width tie on a low-dimensional task, exactly as the universal approximation theorem says. Initialization compounds geometrically: half the He scale and the signal reaches layer 40 twelve orders of magnitude too small, double and it explodes just as far — the net’s fate is decided before the first gradient step. A convolution reuses one kernel everywhere, costing thousands of times fewer parameters than a fully-connected layer, and its filters became oriented edge detectors with no supervision beyond the label. The receptive field is arithmetic that explains why stride and pooling exist, and why VGG stacked 3×3s instead of using big kernels. And the vanishing gradient is real and catastrophic for a vanilla RNN, while the LSTM’s additive cell state carries the gradient back across sixty steps — with the forget-gate sweep confirming the σ(bf)k law decade by decade.
Then we put the framework itself under the same microscope. A transpose costs microseconds because it is stride bookkeeping, and the copy it defers costs milliseconds. A one-character shape mismatch trains a model to garbage while its loss happily decreases. Training holds four bytes of weight, four of gradient and eight of optimizer state per parameter — measured at exactly 4× the model’s size — plus activations that scale with the batch, which is what no_grad discards and gradient checkpointing trades away. Backward is a couple of forwards; accumulated micro-batch gradients match the full batch to float precision; the naive softmax overflows at logits a confident model produces routinely; a forgotten model.eval() makes accuracy both worse and non-deterministic; the GPU answers a naive stopwatch a hundred times too fast; and torch.compile is saved memory traffic — ~6× where fusion has eight round trips to collapse and nothing at all where BLAS already owns the time. Every number here came from the code above; change it and rerun, and the lessons hold.