Chapter 2 of 2
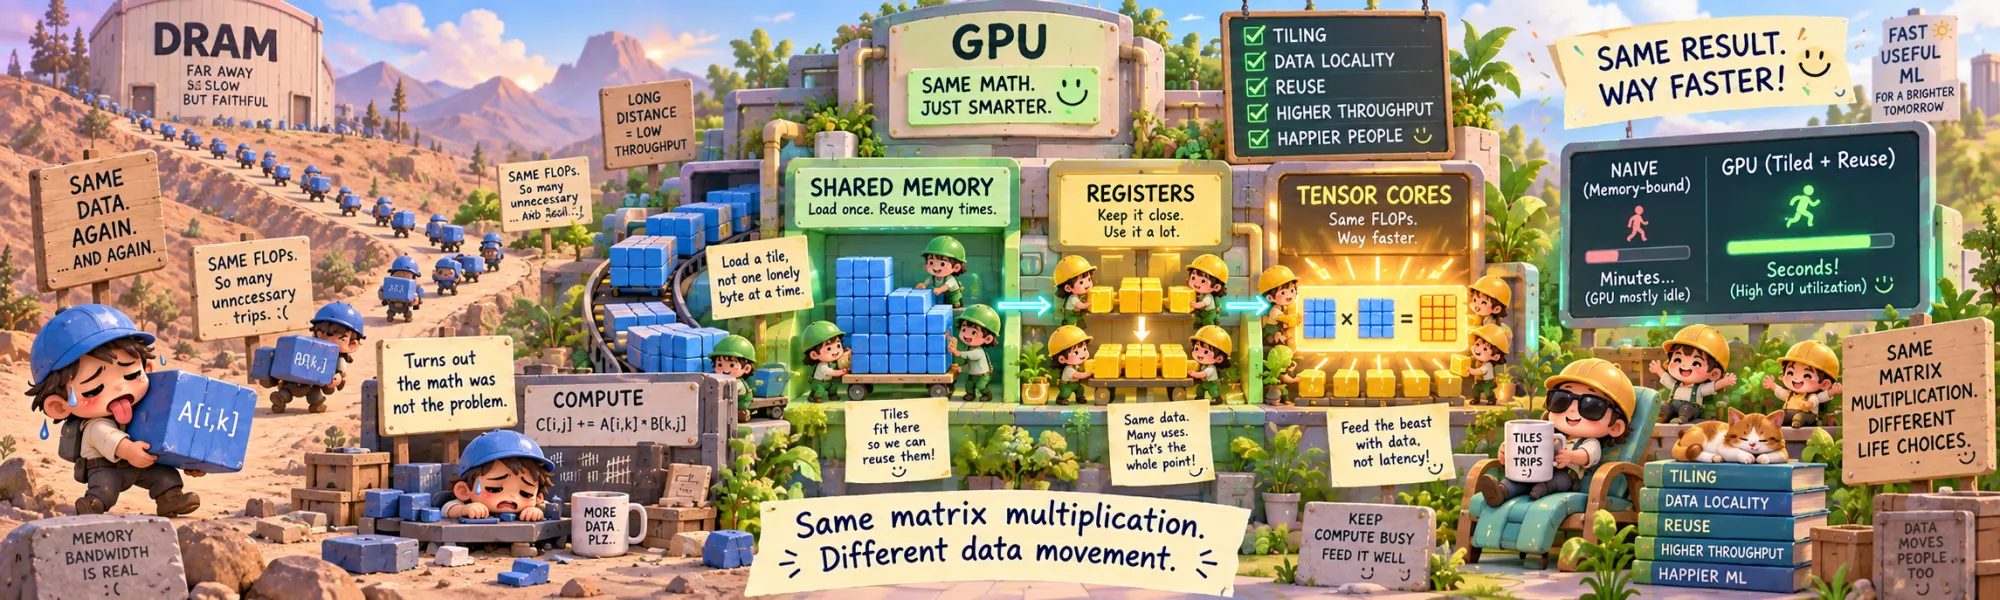
Matrix Multiplication: The Operation Behind Modern AI
Created Sep 12, 2026
Every model calls A @ B somewhere, usually many times per layer. It is the kind of operation nobody stops to look at. Have you ever wondered what actually happens at that moment? The GPU note treated it the same way: matrix multiplication was simply the operation that lives on the fast side of the roofline, as if it had been born there.
It isn't born there. It gets put there, and it is worth seeing how.
So here is the experiment this note is built on. Write the multiplication yourself, the obvious way — three nested loops, one GPU thread for every element of the result — and compare it with the torch.mm you would normally call, on the same card. The obvious version is correct; checked against a float64 answer it agrees to six digits. It is also fifty times slower.
That is a strange result when you look at it closely, because both versions do the same thing. Same numbers, same multiplications and additions, the same of them. So where do fifty times come from? About eight of them, it turns out, come from nothing but arrangement — the same FP32 arithmetic, with the operands kept in better places. The rest come from changing the arithmetic itself: half-width numbers, and a different part of the chip to multiply them.
The GPU note already has the vocabulary for the first half. A GPU has a ceiling for how fast it computes and a ceiling for how fast it moves bytes, and which one you hit depends on how many operations you do per byte you touch. Adding two vectors does one operation for every twelve bytes, and no amount of cleverness changes that. Multiplication is different: operations over numbers means every element of is needed by different outputs, so the reuse is sitting there waiting to be collected. The obvious kernel collects none of it. Everything between the obvious kernel and the library — coalescing, tiles, shared memory, registers, tensor cores — is a different way of collecting it, and this note walks through them one change at a time.
The operation everything is made of
Each output element is a dot product: one row of against one column of . For times , that is multiply-adds, or FLOPs by the usual convention.
A neural network is mostly this. A linear layer is a matrix multiplication — a batch of input vectors stacked into a matrix, times the weight matrix. A transformer block is a handful of them: the projections that make queries, keys and values; the two of attention itself (, then the weighted sum of ); the output projection; and the two large ones in the feed-forward network. Convolutions are lowered to matmuls or computed by kernels built on the same idea. When people say a model is "1.4 × 10²⁴ FLOPs of training", they are almost entirely counting this operation.
Which makes it the one operation worth understanding to the bottom. So: the machine it runs on, measured first, because everything below is judged against it.
| the Tesla T4, measured | |
|---|---|
| FP32 compute roof (multiply-adds in registers) | 6.41 TFLOP/s at 1,335 MHz, 70 W |
| memory roof (streaming read) | 265 GB/s |
| ridge point — where the two cross | 24 FLOPs per byte |
(The GPU note put the same card's memory roof at 230 GB/s and its ridge at 30. The difference is what is being measured: that figure was for a kernel that reads and writes, this one for a pure read, and a matmul's inner loop only reads. Same card, two honest numbers, and the roofs move a few percent between runs anyway.)
An operation that does fewer than 24 FLOPs per byte it reads cannot reach the compute roof on this card, however perfect its arithmetic. Keep the number in view; the whole ladder is a climb toward it and past it.
The naive kernel
The direct translation. One thread per output element; each thread walks the whole dimension:
__global__ void mm_naive(const float* A, const float* B, float* C, int M, int N, int K) {
    int col = blockIdx.x * blockDim.x + threadIdx.x;
    int row = blockIdx.y * blockDim.y + threadIdx.y;
    if (row >= M || col >= N) return;
    float acc = 0.f;
    for (int k = 0; k < K; ++k)
        acc += A[row * K + k] * B[k * N + col];
    C[row * N + col] = acc;
}
It takes 4.6 ms: 0.46 TFLOP/s, or 7% of the card's compute roof. Before improving it, two questions are worth answering properly, because the answers decide everything that follows: how is this work divided up, and what does it cost to feed?
How the work is cut up
A GPU kernel doesn't say "do this in parallel"; it says what one thread does, and you choose how many. The natural division for a matmul is the obvious one: one thread per element of the output. Threads are grouped into blocks — here 16×16 = 256 of them — and the blocks tile the output matrix, so a 1024×1024 product launches 4,096 blocks of 256 threads: a little over a million threads, one per element of , each running the same twelve lines with a different pair of indices.
A million is a lot. The card can hold 40,960 threads resident at once, so the work is oversubscribed twenty-five times over — the scheduler always has warps to run, which is exactly the condition the GPU note says you need for latency hiding. There is no shortage of parallelism, and adding more threads would change nothing. That is worth saying plainly, because "make it more parallel" is the reflex and here it is already maxed out. The lanes are not idle for lack of work. They are idle waiting for operands.
What it costs to feed
Count the reads. Each thread walks a row of and a column of : numbers for one output element. Over the whole product that is reads of 4 bytes each — for , 8.6 GB of traffic to multiply two matrices that together hold 8 MB. The same numbers are fetched again and again, a thousand times each, because nothing in the kernel remembers them.
Put that against the machine: 8.6 GB at 265 GB/s is 32 ms of pure memory time, against 2.1 GFLOP of arithmetic which the compute roof would finish in 0.3 ms. In roofline terms, the kernel does 0.25 FLOPs per byte — a hundredth of the ridge point — so it is memory-bound by two orders of magnitude.
The measurement is kinder than that: 4.6 ms, not 32. The difference is the caches, which catch most of those repeated reads without being asked — L2 is 4 MB and the matrices are 4 MB each, so a good fraction of the traffic never reaches DRAM. That free help is real, and it is still not enough: at 7% of the compute roof, the arithmetic units spend thirteen cycles out of every fourteen waiting. The operands are the problem, not the operations — and every rung from here is about operands.
The same kernel, one index swapped
Before making anything better, here is how much worse it gets from one apparently cosmetic change. Swap which thread index runs along the rows and which along the columns — so consecutive threads now walk down a column of instead of across a row — and nothing about the work changes. Each thread still does the same 1024 multiply-adds on the same numbers.
It takes 17.9 ms instead of 4.6. Four times slower.
int col = blockIdx.x * blockDim.x + threadIdx.x;   // before: neighbouring threads → neighbouring columns
int row = blockIdx.y * blockDim.y + threadIdx.y;

int row = blockIdx.x * blockDim.x + threadIdx.x;   // after: neighbouring threads → neighbouring rows
int col = blockIdx.y * blockDim.y + threadIdx.y;
The reason is the warp. Threads execute in groups of 32 and their loads are served together: when consecutive threads read consecutive addresses, the 32 loads become a handful of memory transactions, and every byte fetched is used. In the original mapping, neighbouring threads share a row, so their loads from are the very same numbers and their loads from sit side by side. After the swap, neighbouring threads share a column instead: their loads from now coincide, but their loads from are a whole row — 4,096 bytes — apart, and their writes into are strided too. Each of those loads drags in a separate chunk of memory of which one float is wanted. Same arithmetic, same parallelism, four times the traffic per useful byte. (The GPU note measures this effect on its own, stride by stride.)
So the units are idle, and the reason is bytes. Every rung from here is about bytes.
Tiling: choosing your own intensity
Here is the key move, and it is worth stating as a principle before the code. The naive kernel reads an element of from DRAM, uses it once, and forgets it — even though that element is needed by 1,024 different output elements. Tiling is the arrangement that remembers it.
A block of threads claims a tile of . Together the block loads a tile of and one of into shared memory, and then every thread reads those tiles from there, times each, before the block moves to the next tile along .
Shared memory deserves its own sentence, because it is the one piece of GPU hardware with no equivalent on a CPU. It is a scratchpad: a small block of fast storage on each SM — 96 KB on this card, carved out of the same silicon as L1 — that the program manages. A cache decides for you what to keep, and guesses from the access pattern. Shared memory doesn't guess: a block writes what it wants into it, every thread in that block can read it, and it stays until the block says otherwise. That is exactly what a matmul needs, because the reuse pattern is known in advance and no guessing is required. The price is threefold: it is small (the pair of 32×32 float tiles below takes 8 KB, and several blocks share each SM's 96 KB), it is shared by the block, so threads must wait at a barrier — the __syncthreads() in the code below — until everyone has loaded their part, and whatever it takes comes out of L1's capacity.
The arithmetic is untouched. The traffic falls by a factor of , which is the same as saying the intensity rises by a factor of : for FP32, a tile of side gives FLOPs per byte.
template <int T>
__global__ void mm_tiled(const float* A, const float* B, float* C, int M, int N, int K) {
    __shared__ float As[T][T], Bs[T][T];
    int tx = threadIdx.x, ty = threadIdx.y;
    int col = blockIdx.x * T + tx, row = blockIdx.y * T + ty;
    float acc = 0.f;
    for (int k0 = 0; k0 < K; k0 += T) {
        As[ty][tx] = A[row * K + k0 + tx];      // the block loads two tiles…
        Bs[ty][tx] = B[(k0 + ty) * N + col];
        __syncthreads();
        for (int k = 0; k < T; ++k)             // …and reads them T times each
            acc += As[ty][k] * Bs[k][tx];
        __syncthreads();
    }
    C[row * N + col] = acc;
}
The two __syncthreads() are the cooperation made explicit: nobody may read the tile until everybody has finished writing it, and nobody may start overwriting it for the next step until everybody has finished reading. That is the cost of sharing — the block moves at the speed of its slowest thread — and it is why tiles are loaded in one burst rather than on demand.
Measured, with the tile as the only variable:
| tile | intensity (model) | time | speed |
|---|---|---|---|
| none (naive) | 0.25 FLOP/B | 4.65 ms | 0.46 TFLOP/s |
| 8×8 | 2 | 4.23 ms | 0.51 TFLOP/s |
| 16×16 | 4 | 2.93 ms | 0.73 TFLOP/s |
| 32×32 | 8 | 2.47 ms | 0.87 TFLOP/s |
Each doubling of the tile doubles the intensity and buys between 1.1× and 1.5×, never 2×. The model says traffic is no longer the binding constraint — at 8 FLOPs per byte the memory roof would allow 2.1 TFLOP/s and the kernel delivers 0.87 — so DRAM traffic is no longer the active bottleneck. The kernel has moved one level inward. Every multiply-add still needs two loads from shared memory, and each thread carries a single accumulator, so its whole inner loop is one dependent chain with nothing to overlap while a load is pending. Shared-memory throughput, the barriers and the missing instruction-level parallelism are now all part of the limit, and this kernel alone can't say which one dominates. What it does show is that a roofline drawn against DRAM is not the last model you need: the same reasoning has to be repeated one level in.
Registers: the same trick, one level higher
The fix rhymes, because the problem does. Tiling fixed DRAM traffic by making a byte serve a whole block; the new constraints are the same shape one level in — a byte of shared memory serving a single multiply-add, and a single dependent chain per thread. So do the same thing again: give each thread a small patch of outputs instead of one element.
If a thread owns a 4×4 patch of , it loads 4 values of and 4 of from shared memory — eight reads — and combines them into all sixteen products. Eight reads, sixteen multiply-adds, where before it was two reads for one. And it fixes the other problem at the same time: sixteen accumulators are sixteen independent chains, so a thread always has a multiply-add it can issue while other work waits on a load. The register kernel changes several things at once, which is part of why it is the biggest jump on the ladder — and why this measurement can't split the credit between them. Registers are where those sixteen running sums live: the fastest storage on the chip, private to the thread, and the reason the GPU note found more register file on this card than L2 cache.
Why not a bigger patch? Because registers are a budget, not a free resource. An SM on this card has 64 registers per thread at full occupancy. A 4×4 patch needs about thirty — sixteen accumulators plus operands and indices — but an 8×8 patch needs nearly ninety, more than the whole share, so fewer threads can be resident at once. More reuse, less occupancy. The lab measured the trade directly, growing the patch while keeping everything else fixed:
| patch | shared-memory reads per multiply-add | registers per thread (estimate) | speed |
|---|---|---|---|
| 1×1 | 2 | ~11 | 0.72 TFLOP/s |
| 2×2 | 1 | ~16 | 1.35 TFLOP/s |
| 4×4 | ½ | ~32 | 2.28 TFLOP/s |
| 8×8 | ¼ | ~88 | 2.51 TFLOP/s |
Going from 2×2 to 4×4 buys 69%. Going from 4×4 to 8×8 buys 10%, even though it halves the shared-memory reads again. The budget doesn't make the bigger patch slower on this card; it eats almost all of what the extra reuse should have bought. That flattening is what "registers are a budget" looks like when measured. (The register counts are estimates from the kernel's variables; the compiler's exact allocation isn't visible from outside.)
Each block now owns a 64×64 tile of ; its 16×16 threads each keep a 4×4 patch, and fmaf is the fused multiply-add — the single instruction the whole ladder has been trying to keep busy:
float acc[4][4] = {{0.f}};
for (int k = 0; k < 16; ++k) {
    float a[4], b[4];
    for (int i = 0; i < 4; ++i) { a[i] = As[ty*4+i][k]; b[i] = Bs[k][tx*4+i]; }
    for (int i = 0; i < 4; ++i)
        for (int j = 0; j < 4; ++j)
            acc[i][j] = fmaf(a[i], b[j], acc[i][j]);   // 8 reads → 16 multiply-adds
}
0.93 ms: 2.32 TFLOP/s, 36% of the compute roof and 5.0× the naive kernel. Nothing was removed from the arithmetic; the same 2.1 GFLOP were performed. What changed is that the operands now come from progressively closer places, and each trip serves more work: DRAM → shared memory → registers, with the reuse factor multiplying at every step. That pyramid — not any single trick — is what a fast matmul is.
That still leaves cuBLAS in FP32 55% ahead — 3.60 TFLOP/s against 2.32 — with the same hierarchy underneath, and what closes the rest is less a new idea than keeping every level busy at once. The register kernel waits: a block loads a tile, stops, consumes it, then loads the next. Production matmul kernels overlap those stages — the next tile already moving inward while the current one is being consumed, loads vectorised, tiles sized to the warp, register use tuned against occupancy. cuBLAS's source isn't public, so exactly which of these it uses on a T4 isn't something this lab can see; but they are the standard toolkit, and overlap of this kind is part of every fast GPU kernel.
Tensor cores, and the difference between using and feeding them
At this point the FP32 lanes are the limit, and the card has other arithmetic units that are eight times faster: the tensor cores. They don't work one multiply-add at a time. A warp issues one matrix-multiply operation that represents a whole 16×16×16 tile — 4,096 multiply-adds, FP16 inputs into an FP32 accumulator — and the compiler lowers it to the tensor-core instructions underneath (on Turing, several of them per tile).
They are also astonishingly easy to program. This is the whole kernel:
#include <mma.h>
using namespace nvcuda;

__global__ void mm_wmma(const half* A, const half* B, float* C, int M, int N, int K) {
    int warp = (blockIdx.x * blockDim.x + threadIdx.x) / 32;
    int tileRow = warp / (N / 16), tileCol = warp % (N / 16);

    wmma::fragment<wmma::matrix_a, 16, 16, 16, half, wmma::row_major> a_frag;
    wmma::fragment<wmma::matrix_b, 16, 16, 16, half, wmma::row_major> b_frag;
    wmma::fragment<wmma::accumulator, 16, 16, 16, float> acc;
    wmma::fill_fragment(acc, 0.0f);

    for (int k0 = 0; k0 < K; k0 += 16) {
        wmma::load_matrix_sync(a_frag, A + tileRow * 16 * K + k0, K);
        wmma::load_matrix_sync(b_frag, B + k0 * N + tileCol * 16, N);
        wmma::mma_sync(acc, a_frag, b_frag, acc);          // 4,096 multiply-adds
    }
    wmma::store_matrix_sync(C + tileRow * 16 * N + tileCol * 16, acc, N, wmma::mem_row_major);
}
Twenty lines, correct to 6 × 10⁻⁵ against float64, and it uses the tensor cores.
It runs at 3.3 TFLOP/s. cuBLAS, handed exactly the same formats — FP16 in, FP32 accumulated and written out — runs at 21.9. And the two produce the same answer: their error against float64 is identical to three significant figures. Same inputs, same precision, same result, almost seven times apart.
That gap is the most useful number in this note. The kernel above is using the fastest arithmetic units on the chip, and it is still almost seven times off, because it reads its operands straight from DRAM: each 16×16 tile of pulls in a 16×K strip of and a K×16 strip of , which works out to 8 FLOPs per byte — left of the ridge, memory-bound. The memory roof allows 2.1 TFLOP/s at that intensity; the kernel got 3.3, the usual bit extra that the caches hand over. The tensor cores spend most of their time waiting, exactly like the FP32 lanes did in the naive kernel, four rungs ago.
Two more readings of the same rows. First, the hand-written tensor-core kernel is slower than cuBLAS in plain FP32 (3.30 against 3.60 TFLOP/s): half-precision arithmetic on dedicated silicon, beaten by ordinary lanes running a well-fed kernel — and those lanes are themselves held back, since the GPU note found that under this card's 70-watt limit a cuBLAS FP32 matmul runs at about 700 MHz, half the clock. Second, the width of the output hardly matters: let cuBLAS write FP16 instead of FP32, the ordinary torch.mm on half-precision tensors, and it gains only 6% (21.9 → 23.3 TFLOP/s). Everything between the two tensor-core kernels is how the tiles get to them.
Issuing the instruction is easy. Feeding it is the entire job, and it is the same job as before: tiles in shared memory, tiles in registers, and now also the layouts the tensor cores want. That is what cuBLAS does, and it is most of the reason calling the library beats writing the loop yourself.
What the precision buys, and what it costs
The tensor cores take FP16 inputs, so the last rungs of the ladder change the arithmetic rather than only its arrangement. Both halves of that trade are measurable. On a 2048×2048 product, against a float64 reference:
| speed | largest error ÷ largest entry | relative Frobenius error | |
|---|---|---|---|
| FP32, CUDA cores | 3.69 TFLOP/s | 1.0 × 10⁻⁶ | 5.7 × 10⁻⁷ |
| FP16, tensor cores | 20.0 TFLOP/s | 4.6 × 10⁻⁴ | 3.3 × 10⁻⁴ |
5.4× the speed for about 500× the error. Whether that is a bargain or a disaster is not a property of the hardware — it is a property of what the numbers are for. Neural network weights and activations are noisy estimates to begin with, trained with stochastic gradients; an error in the fourth decimal of one layer's output is far below the noise the model already tolerates, which is why mixed FP16/BF16 inference is common — models often tolerate this error well, provided end-to-end quality is actually checked rather than assumed. The same error inside an iterative linear solver, where residuals are supposed to shrink over dozens of iterations, is fatal.
Two details of the trade are worth keeping. First, the accumulator stays FP32 even when the inputs are FP16 — the products are summed in the wider format, which is what keeps a 1024-term dot product from drifting badly. Second, FP16 buys two different things depending on where the operation sits. A large square product like this one is compute-bound, so the 5.4× is the tensor cores doing arithmetic faster, and nothing else. For a memory-bound shape — a skinny matmul, a batch of one — the same change halves the dominant traffic — the weights and inputs, not necessarily the accumulator or the output — and that is where the speed comes from, with the tensor cores barely relevant.
Even two FP32 implementations need not agree bit for bit. Floating-point addition is not associative, and an optimised kernel sums in a different order from a naive one — which is why, in the ladder, every hand-written FP32 kernel lands at the same error against float64 while cuBLAS in FP32 lands at a different, smaller one. Same precision, same answer to six digits, different last bits.
The datasheet promises eight times more FP16 than FP32; the measurement gives 5.4. The missing part is not the tensor cores under-delivering but the card's power limit, which the GPU note measured directly: FP16 tensor work pulls this T4 down to around 600 MHz, so the two precisions are not compared at the same clock.
cuBLAS is not one kernel
The top rung is a library, and the useful way to think about it is not "highly optimised code" but "a few hundred kernels and a policy for choosing between them". Each is a tiling — a block tile, a warp tile, a thread tile, an instruction — tuned for a shape and a data type. What that means shows up the moment you vary the shape:
Size (all figures FP16). A matmul has to be big before the machine is busy: n = 128 gets 0.1 TFLOP/s, n = 512 already 9, and past n = 1024 the curve stops rising and starts wobbling between 14 and 21 — the kernel is against the roof, and what moves it now is how neatly the size divides into tiles and waves.
Alignment. That wobble becomes absurd up close. Still in FP16, n = 4096 runs at 19.3 TFLOP/s and n = 4097 at 12.9 — 50% more time for 0.07% more work, and 2048 → 2049 costs 54%. Each size was measured three times in shuffled order, so this is not the card warming up.
The obvious suspect is the ragged edge: a dimension that isn't a multiple of the tile leaves a strip of partial tiles that still cost a full tile to compute. The lab checked by taking the same one-element step with its own 32×32 tiled kernel, whose tiling can't change. Its time goes up 4.4% at 4097 and 9.3% at 2049 — single digits, the price of one extra strip of partial tiles. So the edge accounts for a few percent, not fifty. The other forty-odd point to cuBLAS doing something different for the slightly different shape — and that part doesn't have to be guessed. PyTorch's profiler records the name of every kernel launched on the GPU:
| n | FP16 kernel |
|---|---|
| 4088, 4096 | turing_fp16_s1688gemm_fp16_256x128_ldg8_f2f_stages_32x1_nn |
| 4104 | turing_fp16_s1688gemm_fp16_128x256_ldg8_f2f_stages_32x1_nn |
| 4092, 4100 | cutlass_75_tensorop_f16_s1688gemm_f16_256x128_nn_align2 |
| 2049, 4097 | cutlass_75_tensorop_f16_s1688gemm_f16_256x128_nn_align1 |
At sizes divisible by 8, cuBLAS runs NVIDIA's hand-tuned Turing kernels. At 4097 it can't, and falls back to a kernel generated from CUTLASS, NVIDIA's template library; align1 in its name means it accepts dimensions with any alignment, and it pays for that generality. Divisible by 4 is not enough: 4092 and 4100 get the align2 sibling and are just as slow, 52% and 55% behind 4096. Padding confirms it from the other side: 4104×4104 is more work than 4097×4097, but it gets a Turing kernel back and runs 18% faster.
FP32 shows the contrast. There every size, 4097 included, runs the same volta_sgemm_128x64_nn, and the one-element step costs about 11% — the ragged edge inside one kernel, with no switch. The 50% is a property of the library's choices, not of the FLOP count, and it is one reason model dimensions are usually chosen as convenient multiples of 64, 128 or 256 rather than arbitrary numbers.
Layout. Storing an operand transposed barely matters: 0.97× to 1.14× of the plain case, because cuBLAS keeps a kernel for each of the four combinations and stages everything through shared memory anyway. (Timed in short bursts these four look like they differ by 2–3×, which is the card's clock moving between runs — the reason every number in this note is taken in steady state.)
One formula for every matmul
The ladder has been climbing toward a number worth writing down. Multiply an matrix by a one, with bytes per number. The arithmetic is FLOPs. The least traffic any kernel could possibly get away with is reading each input once and writing each output once: bytes. So the best intensity a matmul can ever have is
For a square FP32 product, and , this is . It grows with the matrix: 171 FLOPs per byte at , about seven times past this card's ridge. That is what the ladder was climbing toward. The naive kernel re-reads everything and sits at 0.25; the tiles bring it to 2, 4 and 8; the register kernel to 16; a kernel that reached the ideal would be firmly compute-bound. Every rung is a step from re-reading toward reading once.
Now put in the shape a model runs while it generates one token: FP16, , .
One. Not what some kernel achieves — the best any kernel could achieve. It is the same number the GPU note measured for the batch-1 linear layer, now falling straight out of the shape.
The shape a language model actually runs
Here is that shape measured. A single 4096×4096 FP16 weight matrix, multiplied by input vectors at once:
At — what a model runs to produce one token — it reaches 0.19 TFLOP/s, one percent of what the same multiplication does at , and sixty-four tokens take no longer than one: 0.17 ms against 0.18.
The GPU note showed that much. What this note adds is why no kernel can fix it. Every rung of the ladder raised intensity by finding reuse: a byte of serving a whole tile, a byte of shared memory serving a patch of registers. At there is essentially no weight reuse to collect. Each of the 16 million weights is consumed once, by one multiply-add. The input vector is reused heavily — each of its 4,096 numbers feeds every output — but it is 8 KB and lives comfortably in cache; the 32 MB weight matrix is the traffic. Tiling has almost nothing to collect, and registers almost nothing to hold. The kernel is already reading those weights at 190 GB/s, nearly three quarters of the memory roof; it is nearly perfect at the only thing it can do. The only way out is more work per weight, which means more tokens at once — which is why an inference server's whole job is finding them.
The ladder, end to end
All ten rungs, same product, same number of multiply-adds, correctness checked before every timing:
| rung | FLOPs per byte | speed | × naive |
|---|---|---|---|
| naive, uncoalesced mapping | 0.25 | 0.12 TFLOP/s | 0.26× |
| naive | 0.25 | 0.46 | 1× |
| shared-memory tiles, 8×8 | 2 | 0.51 | 1.1× |
| shared-memory tiles, 16×16 | 4 | 0.73 | 1.6× |
| shared-memory tiles, 32×32 | 8 | 0.87 | 1.9× |
| register tiles, 64×64 block | 16 | 2.32 | 5.0× |
| cuBLAS, FP32 | tuned per shape | 3.60 | 7.8× |
| hand-written tensor cores, FP16 in → FP32 out | 8 | 3.30 | 7.1× |
| cuBLAS, FP16 in → FP32 out | tuned per shape | 21.9 | 47× |
| cuBLAS, FP16 | tuned per shape | 23.3 | 50× |
The left column is the argument and the right column is the consequence. Nothing in that table changed the number of multiply-adds — 2.1 billion of them in every row — and the FP16 rows didn't change it either, only the width of the numbers going in. What changed, rung by rung, is how many operations happen per byte fetched, and speed followed.
It followed loosely, not exactly, and the two rows at 8 FLOPs per byte say why: the 32×32 tiles got 0.87 TFLOP/s and the tensor-core kernel 3.30, almost four times apart at identical intensity. Intensity buys a ceiling. What you get under it depends on everything else — which units do the arithmetic, how many warps are resident, whether the clock is holding.
And the fifty splits cleanly in two. Naive to cuBLAS FP32 is 7.8×, every bit of it rearrangement: same precision, same operations, better-placed operands. The remaining 6.5× is the second act — half-width inputs, which halve the traffic, and tensor cores, which multiply tiles instead of numbers. Even inside that second act, most of the gain is feeding again: the same FP16-in, FP32-out product is 3.30 TFLOP/s written by hand and 21.9 in cuBLAS. The first half is craft anyone can practise on any operation. The second is the hardware offering a different deal, and taking it means accepting the error budget of the previous section.
Which is the transferable part, because the pyramid generalises far beyond matmul. DRAM → L2 → shared memory → registers, with a reuse factor collected at each level, is what every fast GPU kernel looks like: FlashAttention is this argument applied to attention, so that the score matrix never reaches DRAM; the fused kernels torch.compile generates are this argument applied to element-wise chains. The specific numbers belong to one Tesla T4. The shape of the answer doesn't.
Two more things the ladder implies for anyone not writing kernels. First: use the library. Six of these rungs are a demonstration, not advice — cuBLAS earns its 50× on shapes it has been tuned for, and the way to beat it is to fuse the matmul with what comes next, not to rewrite it. Second: your model's shapes are a performance decision. A hidden size that is a multiple of the tile, a batch big enough to amortise the weight read — those are worth more than anything you can do inside the loop.
One caveat about the hardware. A Tesla T4 makes this hierarchy unusually easy to see: everything on it is small, and nothing hides the seams. Newer GPUs change almost every number here — far wider HBM, tensor cores for more formats (BF16 and TF32 since Ampere, FP8 since Ada and Hopper), and better machinery for moving tiles inward — but not the central problem. A fast matmul is still a matter of bringing a tile inward once and using it as many times as possible before it has to leave.