Chapter 1 of 2
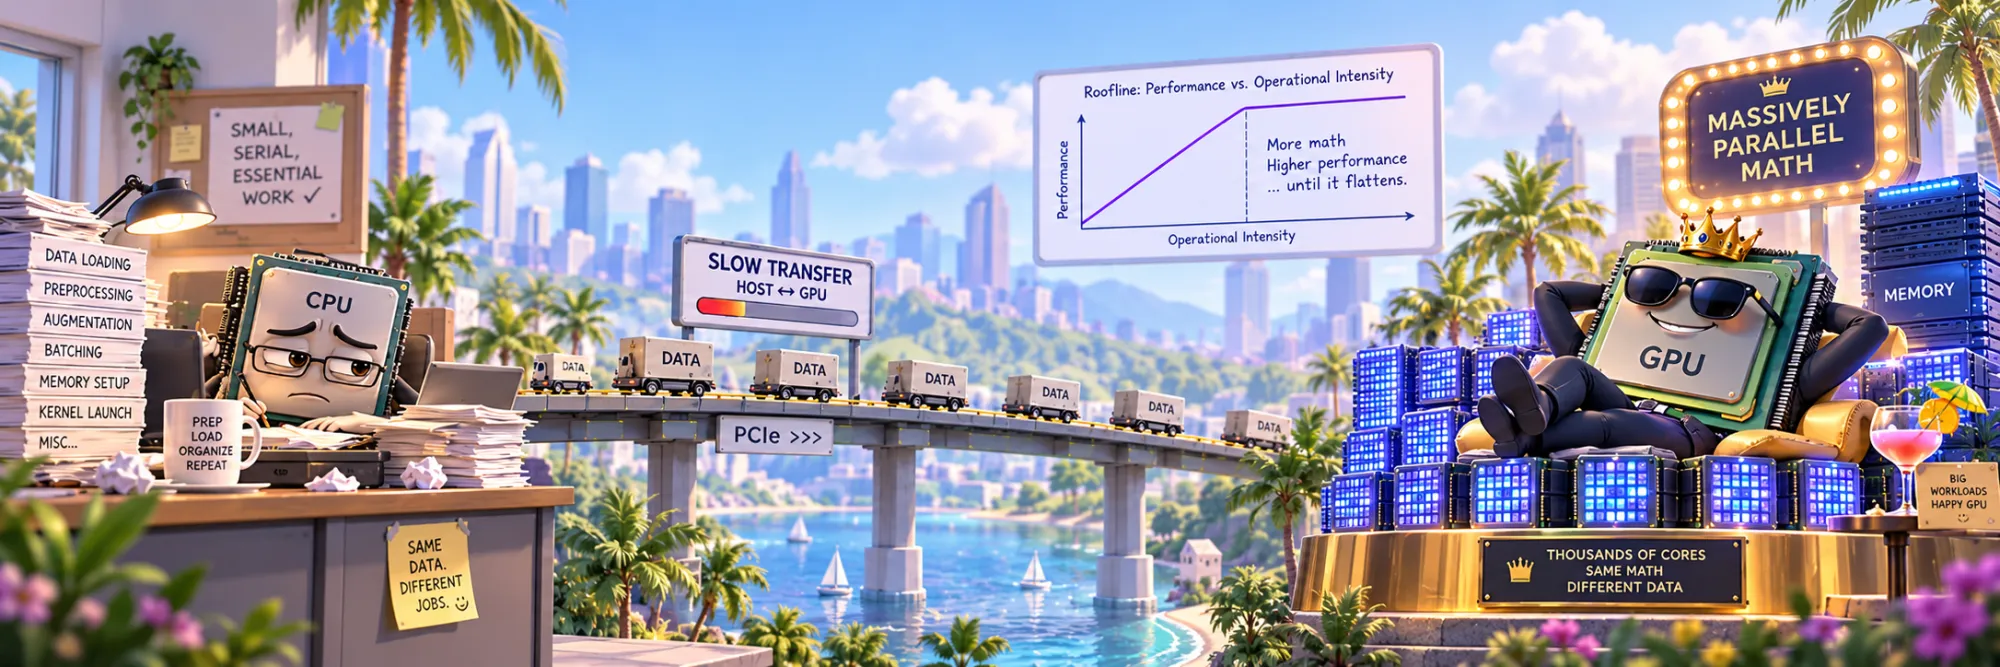
How GPUs Actually Run Machine Learning
Created Sep 11, 2026
Take one GPU and the CPU sitting next to it, and give them the same four jobs.
Multiply two 4096×4096 matrices: the GPU finishes 19 times sooner. Add two vectors of 268 million numbers: 11 times sooner. Add two vectors of a thousand numbers: the GPU loses, taking almost eight times as long. And add the large vectors again, but this time count the trip the data has to make into the GPU and back: now the GPU is slower than the CPU at every size we tried — ten times slower for the large vectors.
Same chip, same software, same afternoon. Which raises the question this note is about: why is a GPU sometimes incredibly fast, and sometimes barely faster at all — or slower?
The answer needs surprisingly little. Each machine is described, to a first approximation, by two numbers: how many floating-point operations it can do per second, and how many bytes per second it can move to and from memory. Add a third — the fixed cost of getting any operation started at all — and you can predict most of the four results above. Each operation, in turn, is described by one number: how many operations it performs for every byte it touches. Everything else in the vocabulary of GPUs — threads, warps, SIMT, latency hiding, caches, HBM, tensor cores, the roofline — is either how the machine reaches its numbers, or why a given operation can't.
So the note has two halves. The first works out what happens, and ends with the paradox resolved. The second opens the machine up and asks how: how a chip whose every memory load takes hundreds of cycles still streams data faster than anything else in the computer, and why its ceiling is not where the datasheet says.
Everything the T4 does in this note was measured, on one Tesla T4 on Kaggle, mostly with small CUDA kernels written so that each one isolates one mechanism. Where a figure comes from a datasheet instead, it says so.
The paradox, measured
The machines first. The GPU is a Tesla T4: a 70-watt inference card from 2018, NVIDIA's Turing generation, and the GPU Kaggle gives away for free. The CPU is what the same Kaggle machine provides: an Intel Xeon at 2.0 GHz, which PyTorch drives with two threads — its default of one per physical core. It is a modest CPU. A large server CPU would shrink every ratio below; it would not change their shape, and the shape is the point.
Two operations, each swept from tiny to as large as fits:
- Matrix multiplication, by in 32-bit floats (FP32), for from 16 to 4096.
- Element-wise addition, in FP32, from a thousand elements to 268 million.
Each is timed three ways: on the CPU; on the GPU with the data already in the GPU's memory; and on the GPU the way a naive script would use it — copy the inputs over, compute, copy the result back.
Read the two curves from left to right and three regimes appear.
At the small end, the GPU loses both operations, by a factor of five to eight. A 32×32 matrix multiplication takes the CPU 7 µs and the GPU 34 µs. The GPU is not slow at arithmetic here; it has barely started. Every operation handed to a GPU pays a fixed toll — Python, the PyTorch dispatcher, the CUDA driver, the trip to the device and back — before a single number is computed. For one operation that we launch and then wait for, that toll is about 20 µs for an addition and 35 µs for a matrix multiplication, against 3–6 µs on the CPU. When the work itself takes less than the toll, the toll is all you measure.
That figure deserves a warning before it misleads anyone, because a PyTorch model doesn't normally wait for each operation. Kernel launches are asynchronous: Python queues them and moves on while the GPU works. Queued back to back, each launch cost about 9 µs of CPU time here, and it overlaps with the GPU's own work. Recorded once as a CUDA graph and replayed — which is what torch.compile(mode="reduce-overhead") does — it dropped to 1.4 µs per kernel. The full round trip comes back whenever Python has to stop and wait for the GPU: a .item(), a print(loss), a .cpu() in the middle of a training loop.
In the middle, both curves cross break-even — matrix multiplication between and , addition somewhere between 131 thousand and 262 thousand elements — and climb.
At the large end they separate. Matrix multiplication keeps climbing to 19×. Addition flattens at 11× and will not go higher however large the vectors get.
And the copies change everything. Matrix multiplication survives them — at the GPU is still almost 6 times faster including the round trip, because the work grows as while the data grows as . Addition does not survive them at any size.
Where does "a hundred times faster" come from, then? Not from FP32. Run a large multiplication in 16-bit floats (FP16), which is how neural networks actually run on GPUs, and it goes to a different part of the chip, the tensor cores. Those sustained about 21 TFLOP/s in our measurements — roughly a hundred times the CPU's best FP32 rate — and in short bursts reached 40, nearly two hundred times. That range is the one the marketing quotes. It just belongs to one operation, in one precision, at one end of the size range.
So there are at least four different answers to "how much faster is the GPU", from 0.1× to nearly 200×, and they are not noise around some true speed-up. They are different bottlenecks.
Two machines built on opposite bets
A CPU and a GPU are both made of transistors, and the difference between them is what those transistors are spent on.
A CPU core is built to make one stream of instructions finish as soon as possible. Most of its area goes to things that are not arithmetic at all: large caches, so that data is usually close; branch predictors, so that the core can guess which way an if goes before it knows; out-of-order machinery that finds independent instructions and runs them early. All of it serves latency — the time until one particular answer is ready. A CPU is a machine for doing one thing quickly.
A GPU is built on the opposite bet. It assumes the work arrives as an enormous number of independent, identical little computations — every pixel, every element of a tensor, every entry of an output matrix — and that nobody cares when any particular one finishes, only when all of them do. So it spends its transistors on arithmetic units and on registers to feed them, and very little on making any single thread fast. All of it serves throughput — the amount of work completed per second. A GPU is a machine for doing a million things at once, each slowly.
Here is how the T4 describes itself:
| Tesla T4 (as the card reports itself) | |
|---|---|
| streaming multiprocessors (SMs) | 40 |
| FP32 arithmetic lanes per SM | 64 (2,560 in total) |
| threads that can be resident on one SM | 1,024 |
| register file per SM | 256 KB — 10 MB across the chip |
| L1 / shared memory per SM | 96 KB, split between the two |
| L2 cache (shared by all SMs) | 4 MB |
| DRAM | 15 GB of GDDR6 |
| max clock / power limit | 1,590 MHz / 70 W |
The unit to notice is the streaming multiprocessor, or SM. It is the GPU's equivalent of a core, and the T4 has forty of them. Each SM contains 64 FP32 lanes — simple units that each do one multiply-add per clock — plus its own registers, its own L1 cache and its own schedulers.
One line of that table deserves a second look. The register file — the fastest, closest storage there is, private to each SM — adds up to 10 MB. The L2 cache that all SMs share is 4 MB. On this GPU there is more register storage than there is cache. On a CPU core the proportion is reversed by orders of magnitude. That single fact tells you most of what you need to know about how differently the two machines work, and the second half of this note shows why it has to be that way.
The first number: FLOPs
A FLOP is one floating-point operation: an addition or a multiplication. The workhorse instruction of every GPU (and every CPU) is the fused multiply-add, in one step, which by convention counts as two FLOPs. Speed is measured in FLOP/s: FLOPs per second.
From the table we can compute the most arithmetic the T4 can possibly do in FP32. Every lane can finish one FMA per clock:
A kernel built to do nothing but multiply-adds got 6.8 TFLOP/s out of it. Why not 8.1 is a story of its own, and it is the last section of this note. The CPU, timed on the largest matrix multiplications of the sweep, manages about 215 GFLOP/s. The ratio, about 32, is the most the GPU could ever win by on FP32 arithmetic. Hold on to that; the matrix multiplication curve topped out at 19, and we will want to know why.
The second number: bytes per second
The other half of a machine is how fast it can feed itself. The T4's datasheet says its memory delivers 320 GB/s — a 5 GHz memory clock, two transfers per clock, 32 bytes per transfer. What a kernel actually gets is less: about 275 GB/s when it only reads, about 230 GB/s when it writes as much as it reads, as addition does. That is normal. The datasheet figure is the width of the pipe, not what flows through it.
The CPU's memory, timed on the largest additions of the sweep, delivers about 23 GB/s.
Now look at that ratio: 230 against 23 is ten. Addition's speed-up flattened at eleven. That is not a coincidence, and it is the first real clue. Adding two vectors does almost no arithmetic — one addition for every 12 bytes read and written — so neither machine is ever limited by arithmetic. Both are just moving bytes, and the GPU wins by exactly as much as its memory is faster. Which leaves the obvious question: why isn't matrix multiplication stuck at the same ratio?
Arithmetic intensity and the roofline
Here is an experiment that shows the answer better than any definition. The lab's intensity kernel reads four floats, does multiply-adds on each of them, and writes them back. Nothing else changes: the same 512 MB go in and out of memory every time, and only the arithmetic per byte grows with .
Up to — sixteen FLOPs for every byte moved — the kernel's time doesn't move. 2.3 ms, whether it does one multiply-add per float or sixty-four. The extra arithmetic is free: the lanes finish each element long before the next bytes arrive, and then they wait. Only past that point does every extra multiply-add start to cost time — and from there on, it is the bytes that are free.
So what decides the speed of an operation is not how much arithmetic it does, or how much data it moves, but the ratio of the two. That ratio has a name, arithmetic intensity:
Adding two FP32 vectors reads 8 bytes and writes 4 for every single FLOP: . Multiplying two FP32 matrices does FLOPs while reading and writing bytes at minimum: . For that is almost 700 FLOPs per byte. Addition's intensity is fixed forever. Multiplication's grows with the matrix.
A machine has a matching number. Divide its FLOP/s by its bytes per second and you get the intensity at which both limits bind at once, the ridge point:
For the T4 in FP32 that is about 30 FLOPs per byte. An operation below it is memory-bound: the arithmetic units idle while they wait for data, its speed is bandwidth × intensity, and faster arithmetic would change nothing. An operation above it is compute-bound: memory idles while the arithmetic grinds. Put the attainable speed, , on a log-log plot against intensity, and it looks like a roof — a slope for memory, a flat top for compute, meeting at the ridge. That is the roofline model.
Before the full chart, the same idea for one operation at a time. Every operation has a fixed toll, some bytes to move and some FLOPs to do, and the GPU does the last two at once — so whichever takes longer sets the time. Pick addition or multiplication, drag the size, and watch which bar wins and where the dot sits against the ridge:
And here is the whole roof, with the knob kernel walking along it:
The measured kernel follows the roof closely. It turns a little earlier and rounder than the sharp corner the model draws — between 16 and 24 FLOPs per byte rather than at 30 — because real kernels never overlap memory and arithmetic perfectly, and near the ridge the imperfection shows. The roofline is a bound, not a prediction of every point under it.
(The chart has two FP16 roofs, one above the other, for the tensor cores. Why one GPU should have two ceilings for the same operation is the story of the last section.)
Real operations on the roof
The same chart has the operations a neural network is actually made of placed on it, each at the intensity of its compulsory traffic — every input read once, every output written once — so its -coordinate is the best intensity that operation could possibly have.
Element-wise operations — addition, ReLU, a multiply-add — sit far to the left of any ridge and reach 84–90% of the memory roof. They are as fast as they can be, and they are bandwidth, not arithmetic. Reductions and normalizations (sum, softmax, layer norm) sit just to their right. Nothing you could do to the arithmetic units would speed any of them up.
Matrix multiplication walks across the chart with its size. A 256³ product has plenty of intensity but only 34 million FLOPs — too little work to fill 40 SMs, and over in 34 µs, no longer than the toll of launching it — and reaches 4% of its roof. At 2048³ it reaches the higher of the two tensor-core roofs, the burst one.
Convolution reaches 60% of its roof and attention 40%. Attention is low not because of the operation but because of the software available for this card: PyTorch's fastest attention kernels, FlashAttention and cuDNN's, both refuse to run on the T4 — they need the sm80 generation or newer, and the T4 is sm75 — so it falls back to a slower one. Attention has a note of its own coming.
The linear layer is the most important row, and it is easy to miss. One 4096×4096 FP16 weight matrix, applied to a batch of input vectors:
| batch | time | speed | bound |
|---|---|---|---|
| 1 | 0.19 ms | 0.2 TFLOP/s | memory |
| 4 | 0.21 ms | 0.7 TFLOP/s | memory |
| 16 | 0.23 ms | 2.3 TFLOP/s | memory |
| 64 | 0.21 ms | 10 TFLOP/s | memory |
| 256 | 0.48 ms | 18 TFLOP/s | compute |
Sixty-four inputs take about the same time as one. At batch 1 the layer reads a 32 MB weight matrix to do 34 MFLOP of work — an intensity of 1 — and almost all of the time goes to reading the weights. Every extra input vector reuses the same weights and rides along almost for free, until around batch 256 the layer finally becomes compute-bound. A language model generating text one token at a time is running exactly this layer at batch 1 — hundreds of times per token, once for every weight matrix in every layer.
It is also why a data-centre GPU is sold on its memory as much as on its arithmetic. The T4's memory is GDDR6, chips on the board around the GPU, the same kind of memory a gaming card uses. The GPUs that serve large models use HBM — high-bandwidth memory — stacks of memory dies placed right next to the GPU on the same package, connected by interfaces thousands of bits wide. Nothing about HBM is faster per wire. It is simply an enormously wider pipe. The vendor datasheets (not measurements):
| GPU | memory | bandwidth | dense FP16 tensor | FLOPs per byte |
|---|---|---|---|---|
| T4 | GDDR6 | 0.32 TB/s | 65 TFLOP/s | 203 |
| A100 | HBM2e | 2.0 TB/s | 312 TFLOP/s | 153 |
| H100 | HBM3 | 3.35 TB/s | 989 TFLOP/s | 295 |
| H200 | HBM3e | 4.8 TB/s | 989 TFLOP/s | 206 |
The H200 is the instructive row. It has exactly the H100's compute and 43% more bandwidth, and it was sold as the better chip for serving LLMs. After the linear-layer table, that makes sense: an LLM generating one token at a time spends its life on the left side of the roofline, where only bytes per second matter.
The chart makes one more point. "Compute-bound" and "memory-bound" are not properties of an operation; they are properties of an operation on a machine. The batch-256 linear layer has an intensity of 228. On the T4, whose FP16 ridge sits around 150 in bursts, it is compute-bound. Against the H100's datasheet ridge of nearly 300 it would land on the memory-bound side — at least on paper, and the T4 is a reminder of how far paper can be from the card.
The cheapest byte is the one never moved
If an operation is memory-bound, the only way to make it faster is to move fewer bytes. The simplest way to move fewer bytes is not to write intermediate results to memory only to read them straight back.
relu(x * 1.5 + 0.5), written the obvious way in PyTorch, is three kernels. The multiplication reads and writes a temporary; the addition reads the temporary and writes another; the ReLU reads that and writes the result. In FP16 that is 12 bytes of memory traffic per element. Fused into a single kernel — which is what torch.compile does automatically — each element is read once, transformed in registers, and written once: 4 bytes per element, the same FLOPs.
The roofline predicts a 3× speed-up. Measured: 3.32 ms unfused, 1.17 ms fused, 2.83×. Both versions were running at the memory roof; the fused one just had a third of the bytes to move. This is the entire idea behind kernel fusion, and a large part of the idea behind FlashAttention: when you are memory-bound, arithmetic is free, and bytes are the only currency.
The paradox, resolved
Now back to the four numbers from the opening. The model is the roofline plus the launch toll. For any operation, on any machine:
Three numbers per machine. The GPU's roofs are the ones above: TFLOP/s, GB/s. The CPU's come from the largest sizes in the opening sweep: GFLOP/s, GB/s. The toll for each operation is its time at the smallest size. Nothing is fitted to the curves. What does the model predict?
Where the GPU starts to win. For matrix multiplication the model puts break-even between and — exactly where the measurement crossed. For addition it predicts break-even around 32–64 thousand elements; the measurement crossed later, between 131 and 262 thousand. The reason is instructive: the model assumed the CPU reads its memory at 23 GB/s, but three arrays of 64 thousand floats are 768 KB, which fits in the CPU's own caches, and the CPU added them at 68 GB/s. The CPU has a memory hierarchy too.
Large additions. Memory-bound on both machines, so the speed-up is the ratio of their bandwidths. Predicted 10×; measured 11×. It flattens because the intensity is fixed at 1/12 and no amount of size changes that.
Large multiplications. Compute-bound on both machines, so the speed-up should be the ratio of their compute roofs, 6.8 against 0.215. Predicted 32×; measured 19×. This is not a small miss: cuBLAS ran the 4096³ product at about 4 TFLOP/s, well below the roof. Keep that gap in mind. It is closed at the very end.
Addition, including the copies. This is the one the opening made the most of, and it needs a fourth number: the PCIe link between the CPU's memory and the GPU's, which delivers about 12 GB/s at best. The lab took the naive line — copy in, copy in, add, copy the result back — apart stage by stage for 268 million elements. The addition itself took 13 ms. Copying the two inputs in took almost half a second, because ordinary (pageable) CPU memory can't be read by the GPU directly and gets staged through a buffer on the way, at under 5 GB/s. And copying the result back took almost a full second, the slowest step of all: .cpu() has to create a brand-new 1 GB tensor, and about half of that second is simply the operating system handing out fresh memory pages. The whole trip: 1.45 s, against 0.14 s for the CPU to just add the vectors itself.
Then the best case the link allows: memory pinned for the GPU in advance, buffers allocated once and reused, so nothing crosses PCIe but the 12 bytes per element themselves. The model predicts s; measured, 0.27 s. And even that is twice as slow as the CPU, because the PCIe link, at 12 GB/s, is slower than the CPU's own memory, at 23. For an operation that does one FLOP per 12 bytes, the trip is the work, and no amount of engineering on the GPU side can win it back.
So, the answer to the question this note opened with:
- A GPU is incredibly fast when an operation has a lot of arithmetic for every byte — a large matrix multiplication, a convolution, a large-batch linear layer — so that the GPU's thousands of lanes, not its memory, are the limit. That is the regime of 19× in FP32 and a hundred-odd times in FP16.
- It is only somewhat faster when an operation has little arithmetic per byte — anything element-wise, any normalization, a linear layer at batch 1 — because then both machines are limited by memory, and the GPU wins only by the ratio of their bandwidths. That is the regime of 11×.
- It is slower when the operation is too small to pay the toll of being launched, or when the data has to cross PCIe to get there.
That answers what. It leaves the how wide open. The GPU's memory takes about five hundred clock cycles to answer a single load — how does it still stream 275 GB/s? Why are its 2,560 lanes grouped the way they are? And why did the multiplication stop at 4 TFLOP/s on a chip that manages 6.8? The rest of the note opens the machine up.
Threads, blocks, and warps
To use two and a half thousand lanes, you need at least two and a half thousand things for them to do. The GPU's programming model is built around exactly that. You do not write a loop over the data. You write what happens to one element, and ask the GPU to run it for all of them at once.
That function is called a kernel, and here is a complete one, in CUDA:
__global__ void add(const float* x, const float* y, float* out, int n) {
    int i = blockIdx.x * blockDim.x + threadIdx.x;   // which element is mine?
    if (i < n) out[i] = x[i] + y[i];
}

// launch it: enough 256-thread blocks to cover all n elements
add<<<(n + 255) / 256, 256>>>(x, y, out, n);
Every thread runs the same code. The only thing that distinguishes one thread from another is its index, and the first line of the kernel turns that index into "the element this thread is responsible for". Threads are grouped into blocks (here, of 256 threads), and the blocks together form the grid — as many blocks as it takes to cover the data. When x + y runs in PyTorch on a CUDA tensor, something very much like this is what actually executes.
The grid is how you describe the work. How the hardware executes it has one more level, and it is the level everything else hangs on.
Each block is assigned to one SM, and stays there. Up to 1,024 threads can be resident on a T4 SM at once. But the SM does not run them as 1,024 independent threads. It runs them in groups of 32 called warps. At each step the SM's scheduler picks a warp that is ready and issues one instruction for all 32 threads in it. The threads of a warp don't just run the same program. They run the same instruction, at the same time.1
SIMD and SIMT
A CPU has a related trick called SIMD — single instruction, multiple data. A single SIMD instruction operates on a short vector: with AVX-512, sixteen FP32 numbers at once. But SIMD is explicit. The programmer, or the compiler, has to arrange the data into vectors and use vector instructions.
The GPU's version is called SIMT — single instruction, multiple threads — and it hides the vector. You write scalar code for one thread, with ordinary ifs and loops, and the hardware bundles 32 threads into a warp and executes them together as if they were one 32-wide vector. It is SIMD with the vector made invisible.
Invisible is not the same as absent. The question that separates SIMT from genuinely independent threads is: what happens when the 32 threads of a warp disagree? Say half of them take the if branch and half take the else. The warp can only issue one instruction at a time, so it runs the if path with the else threads masked off, then runs the else path with the if threads masked off. Both halves pay for both paths. This is called divergence, and it can be measured.
The lab's diverge kernel gives every thread one of several different loops to run, with the same total amount of arithmetic in every configuration. The only thing that changes is who gets which loop. Either the split runs between warps — warp 0 takes path 0, warp 1 takes path 1 — or it runs through every warp: lane 0 takes path 0, lane 1 takes path 1, and so on.
| paths | split between whole warps | split through every warp |
|---|---|---|
| 1 | 1.0× | 1.0× |
| 2 | 1.0× | 2.0× |
| 4 | 1.0× | 3.9× |
Split between warps, four different loops cost nothing: every warp agrees with itself, so every warp makes one pass. Split through every warp, the same four loops cost almost four times as much: each warp makes four passes, with three quarters of its lanes idle on each. Nothing about the amount of work changed. Only the granularity of the disagreement did.
The same fact from the other side: make exactly one thread in every run a long loop, and let all the others do nothing. If threads were independent, cost would follow the fraction of threads that work. It follows the fraction of warps that contain a working thread:
With one busy thread in every 32 — 97% of the threads idle — the kernel takes exactly as long as with every thread busy. Every warp still contains one working lane, so every warp still runs the whole loop. At one in 64, half the warps are empty and the time drops to 57%. The unit of cost on a GPU is the warp, not the thread.
At the far right the curve stops following the warps and flattens onto a floor: the time one warp takes on its own. The loop in that kernel is a chain of 20,000 multiply-adds, each needing the previous one's result, and a single warp cannot finish it faster than 20,000 × 3.5 ns, however idle the rest of the GPU is. With only a handful of warps left, the SM has nothing to switch to while each result is pending. That floor is latency, and it is the key to everything that follows.
For machine learning, divergence is mostly good news. Addition and matrix multiplication both run exactly the same instructions on every element; their warps never disagree, and none of this separates the two. It becomes a real cost at the ragged edges — sequences of different lengths in one batch, sparse data, tokens routed to different experts. What separates them, as the first half showed, is arithmetic per byte. The question now is how the GPU reaches its byte roof at all — and for that we need latency.
Latency, and how a GPU hides it
Every load from memory takes time to come back, and that time depends on how far away the data is. It can be measured with the simplest possible experiment: one thread follows a chain of pointers laid out in random order, so every load needs the address that the previous load returned. Nothing can overlap, nothing can be prefetched, and the time per step is the pure latency of whichever level of memory the chain fits in.
Nanoseconds are hard to feel, so here are the measurements stretched to human time, with one load from L1 taking a second:
A multiply-add waiting on the previous one: a tenth of a second. L1: a second. L2: six seconds. DRAM, the memory where every large tensor lives: twelve seconds — about 500 clock cycles for a single load, and the same number of cycles all the way out to an 8 GB chain, half the card. A copy from the CPU over PCIe: thirteen minutes.
A CPU core's loads from its main memory also take hundreds of cycles, but a CPU spends its transistors on avoiding them: deep caches that usually have the data already, prefetchers that guess the next address. A GPU SM has neither to anything like the same degree. What it has instead is other warps.
When a warp issues a load, it doesn't wait. It is simply marked "not ready", and on the very next cycle the scheduler issues an instruction from some other warp that is ready. Switching costs nothing, because nothing has to be saved or restored: the registers of every resident warp live on the SM permanently. This is why the register file is 10 MB. Holding 32 warps of 32 threads per SM, each with its own registers, is what makes zero-cost switching possible, and zero-cost switching is how a GPU hides latency — not by making any load faster, but by always having something else to do while loads are in flight.
It also makes registers a budget. A T4 SM has 65,536 32-bit registers. Divided among 1,024 resident threads, that is 64 registers each. A kernel whose threads need more can't have all 1,024 threads resident; fewer warps fit, and there is less to switch between. The fraction of the maximum that is actually resident is called occupancy, and a kernel with low occupancy has less latency to hide behind.
Little's law
How much has to be in flight to hide the latency completely? Think of memory as a pizzeria with a very long delivery road. On a quiet day every order takes the same 12 human seconds — about 314 ns — to arrive, and the kitchen can send out at most about 275 GB/s. If you want to eat at 275 GB/s, you have to keep 12 seconds' worth of orders on the road at all times. Order less and the kitchen is idle most of the time; you get only what you ordered, one delivery later.
That is Little's law from queueing theory — items in the system equal the rate of flow times the time each one spends inside — and for memory it reads:
One warp loading 16 bytes per thread has 512 bytes on order; on its own it gets GB/s, and measured it got 1.5. It takes something like 170 warps, spread across the SMs, to keep the road full:
There are two ways to put more bytes on the road: more warps, or more independent loads per thread — instruction-level parallelism, or ILP. If Little's law is the right picture, it should not matter which. Plotted against warps, runs with 1, 2, 4 and 8 loads per thread give four different curves; plotted against bytes in flight, they should fall onto one.
They do. With 1 load per thread memory saturates at 256 warps, with 4 loads per thread at 64 warps — both at around 130 KB in flight, a bit more than the 85 KB the law asks for. The extra is queueing, and the widget's second view measures it: one thread chases pointers while the rest of the GPU streams, and near saturation each load takes a third longer than on an idle memory system. Past saturation the pizzeria picture holds exactly: more orders don't arrive any sooner, they just queue. Bandwidth stays flat while the latency of a single load climbs to 10 µs — thirty times its idle value. And pack all the warps onto one SM instead of forty, and bandwidth stops at 49 GB/s however much is in flight: a single SM can only keep so many orders open. To fill the road, many SMs have to be ordering at once.
This is the deep reason a GPU wants big problems. To keep 85 KB of loads on the road, you need thousands of threads, each with something to load. A problem too small to supply them leaves the memory idle between deliveries, whatever the datasheet bandwidth says.
The memory hierarchy
Latency is the cost of one load. Bandwidth is how many bytes per second a level of memory delivers when the whole GPU is asking at once. Every level has both, and together they make a staircase: the closer and smaller the memory, the faster it is on both counts.
| level | size | bandwidth (whole GPU) |
|---|---|---|
| registers | 256 KB per SM (10 MB total) | — |
| L1 cache | 56 KB per SM usable | 3.9 TB/s |
| L2 cache | 4 MB, shared | 1.1 TB/s |
| DRAM (GDDR6) | 15 GB | 0.27 TB/s |
| host RAM, over PCIe | the CPU's memory | 0.012 TB/s |
Each step down the staircase costs a factor. Data in L1 arrives about fourteen times faster than data from DRAM; data in L2 about four times. Everything a kernel does over and over should come from the top of the staircase, and a large part of writing fast GPU code — tiling a matrix multiplication, fusing kernels, FlashAttention — is arranging for exactly that. (L1 shares its silicon with shared memory, a scratchpad a kernel manages by hand; how much of the 96 KB each gets is decided per kernel, and the matrix-multiplication note is where that trade starts to matter.)
The bottom row is the one the opening paradox tripped over. The CPU's memory sits at the end of a PCIe link that delivered 12.3 GB/s at best — 22 times slower than the GPU's own memory — and every copy, however small, costs about 20 µs. For a model this simply means one rule: the weights and activations live on the GPU for the model's whole life, and nothing crosses that link in the middle of a computation that doesn't have to.
A warp reads together: coalescing
The warp matters for memory as much as for arithmetic. When the 32 threads of a warp each load a 4-byte float, the memory system doesn't serve 32 separate requests. It serves them together, in fixed-size pieces. If the 32 threads read 32 consecutive floats, that is 128 bytes, every byte fetched is used, and the access is called coalesced. Spread the threads out and every piece carries less of what was actually asked for:
The pieces come in two sizes, and the lab found both by reading with a stride from two places. When the data sits in L2, the waste grows until stride 8 and then stops: the caches hand out 32-byte sectors, and at stride 8 every thread already has a sector to itself. When the data comes from DRAM, it keeps growing until stride 16, because DRAM itself is read 64 bytes at a time. A random gather is the worst of all: 14 GB/s of useful data, where the same kernel reading in order managed 240. The same data, in the wrong order, is seventeen times slower.
You rarely write a strided kernel on purpose; PyTorch hands you strided data without asking. x.t() and x.permute(...) don't move anything — they return a view of the same memory with different strides — and a kernel that then walks the view row by row reads with a stride. That is what .contiguous() is for: one copy that puts the data back in reading order, so every kernel after it gets coalesced loads. And an embedding lookup, the first layer of every language model, is a gather.
Why the roof moves
One gap is left from the first half: the multiplication that ran at 4 TFLOP/s on a chip that manages 6.8. It turns out to be the same question as a smaller one asked much earlier — why 6.8, and not the 8.14 that the arithmetic says.
The FMA kernel does nothing but multiply-adds in registers, so there is nothing to wait for. And yet it got 84% of the peak. While it ran, the lab polled the card's own sensors: the clock was 1,365 MHz, not the 1,590 in the datasheet, and the card was drawing 67 of its 70 watts. At the clock it actually ran at, the peak is 7.0 TFLOP/s, and the kernel reached 97% of it. The T4 is a 70-watt card, and 2,560 lanes doing a multiply-add every cycle at full clock would draw more than 70 watts. So when the power approaches the limit, the card lowers its clock. The ceiling is real, but it isn't fixed: it is set by how much power the work draws.
Tensor cores, and a ceiling that sinks further
Matrix multiplication has hardware of its own. Alongside the FP32 lanes, every SM has tensor cores: units that don't do one multiply-add at a time but a small matrix multiply-accumulate — a whole tile of products summed in one operation, in FP16. They are why the T4's datasheet promises 65 TFLOP/s in FP16, eight times its FP32 figure. Here is what the card sustained when kept busy for several seconds:
| workload | speed | clock | power |
|---|---|---|---|
| FMA kernel, FP32 lanes | 6.8 TFLOP/s | 1,365 MHz | 67 W |
| matrix multiplication, FP32 | 3.5 TFLOP/s | 705 MHz | 66 W |
| matrix multiplication, FP16 tensor cores | 21 TFLOP/s | 570 MHz | 67 W |
On the tensor cores the card sits at its power limit with the clock at 570 MHz — little more than a third of its maximum — and delivers a third of the datasheet. Scale the datasheet by the clock it actually got and the gap nearly closes: cuBLAS reached 89% of what 570 MHz allows. The tensor cores are not inefficient. They are being starved of power.
And yet short FP16 multiplications — a 2048³ product that takes less than half a millisecond — reached 40 TFLOP/s in the operation sweep. The first time that showed up in the lab it looked like a measurement error — it was more than the roof the same card had just been measured at. At 570 MHz it is physically impossible. So the lab measured the clock inside a burst: after every multiplication, a tiny kernel spins for twenty microseconds of wall time, read from the GPU's own nanosecond timer, and counts the clock cycles that pass. The same burst was run twice, after two different preludes:
After ten seconds of idling, the card sits at its idle clock of about 580 MHz, and it barely moves from there: tensor-core work at that clock already draws close to 70 watts, so there is no headroom to climb, and the whole burst runs at around 18 TFLOP/s (a little under the table's 21, because a 2048³ product gets slightly less out of each clock than an 8192³ one). There is no boost to lose.
After three seconds of streaming memory — busy, but drawing little power per cycle — the clock was high, and the burst starts there: 1,409 MHz and 41 TFLOP/s. Then the power controller notices and pulls the clock down: halfway down within 37 milliseconds, and at the sustained level — around 580 MHz, 18 TFLOP/s — within about 50. The T4 can sprint; it can't hold the pace. A multiplication that starts right after lighter work and finishes inside that window runs at more than twice the sustained rate — which is where the fast bursts in the operation sweep came from, and why whether a given multiplication in a real model gets the fast clock depends on what ran just before it.
It also explains something I noticed while running the lab four times. The GPU's time for the 4096 multiplication was 32.6 ms on the coolest card (58 °C) and 35.4 ms on the warmest (68 °C) — and the four runs lined up in exact order of temperature. A warmer card reaches its power limit sooner. (The speed-up over the CPU wandered more, between 16× and 19×, because the CPU side varied even more from run to run: Kaggle doesn't always give you the same host.)
And it closes the last gap. At the 705 MHz the FP32 multiplication was held to, the lanes' peak is 40 × 64 × 2 × 0.705 GHz = 3.61 TFLOP/s, and cuBLAS sustained 3.52 — 97% of it. cuBLAS is nearly perfect. It draws more power per FLOP than a loop of multiply-adds in registers — it also moves data through caches and shared memory — so the power limit pulls its clock lower. The whole distance between the model's 32× and the measured 19× is the clock.
How much of this carries over to other GPUs is a matter of degree. A 70-watt card is the extreme case: the T4 lost almost two thirds of its clock to its power limit. Data-centre GPUs are given hundreds of watts and lose far less. But every GPU has a power limit, and the lesson holds for all of them: a datasheet peak is a ceiling, not a promise. It tells you what the silicon could do at full clock with unlimited power. What a card actually delivers depends on the work, the temperature, and what it was doing a moment ago — and has to be measured.
Both halves together
Put the two halves together and the paradox from the opening reads differently. A GPU is not "faster than a CPU" by some factor. It is a machine with a very high ceiling for arithmetic, a high but much lower ceiling for moving bytes, a fixed toll at the door, and a power limit that decides how high the first ceiling really is on a given afternoon. Matrix multiplication does enough arithmetic per byte to live under the first ceiling. Addition never leaves the second. Tiny operations never get past the toll. And a round trip over PCIe spends its whole budget on the road.
Footnotes
-
Since NVIDIA's Volta generation (and so on the Turing T4), each thread formally has its own program counter, which lets threads of a warp diverge and reconverge more flexibly than before. The execution cost is the same: a warp issues one instruction at a time, for whichever of its threads are on that path. ↩