Lab · runnable experiments
Matrix Multiplication: The Operation Behind Modern AI
Created Sep 12, 2026 Updated Sep 12, 2026
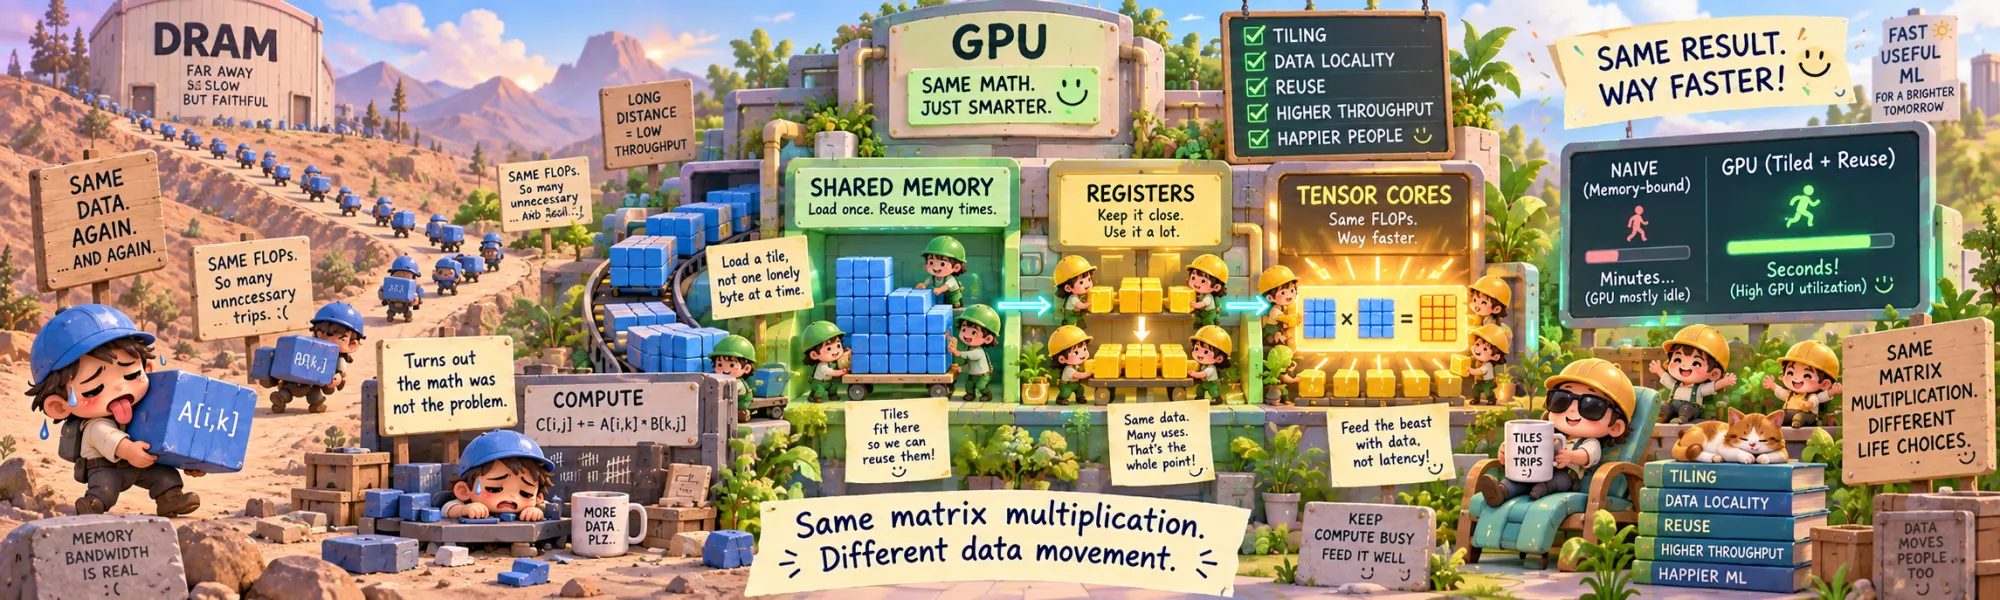
Read the parent noteOne operation, ten rungs, and a stopwatch. Every rung here computes the same C = AB with the same arithmetic — 2MNK floating-point operations, not one more — and they differ by two orders of magnitude in speed. This lab measures the whole ladder on one GPU, and checks every rung against the roofs the hardware actually has.
Part 1 measures this card’s two roofs again, so the lab stands on its own: the FP32 compute roof and the memory roof. Part 2 climbs the ladder — naive, uncoalesced, shared-memory tiles, register tiles, tensor cores — with every result checked for correctness against a float64 reference. Part 3 varies the tile size, which is the same thing as varying arithmetic intensity, and places each kernel on the roofline. Part 4 is precision: what FP16 and the tensor cores buy in speed and cost in accuracy. Part 5 is cuBLAS itself — how its speed depends on shape, alignment and layout, which kernel it picks, and where the ladder ends up against it.
Setup
Run on Kaggle with Settings → Accelerator → GPU T4 x2 (the lab uses one card) and Internet on, which is only needed if the image has no CuPy.
import os
os.environ.setdefault("CUDA_DEVICE_ORDER", "PCI_BUS_ID")

import sys, json, time, datetime, platform, subprocess, threading, traceback, contextlib
import numpy as np, pandas as pd, torch
import matplotlib.pyplot as plt

assert torch.cuda.is_available(), "No GPU: Settings → Accelerator → GPU T4 x2"
DEV = torch.device("cuda:0")
torch.cuda.set_device(DEV)
torch.backends.cuda.matmul.allow_tf32 = False     # Turing has no TF32; keep fp32 meaning fp32
torch.backends.cudnn.allow_tf32 = False

try:
    import cupy as cp
except ImportError:
    subprocess.run([sys.executable, "-m", "pip", "install", "-q", "cupy-cuda12x"], check=True)
    import cupy as cp
cp.cuda.Device(0).use()
assert cp.cuda.get_current_stream().ptr == 0 and torch.cuda.current_stream().cuda_stream == 0

INK, LINE, CREAM = "#2a2a2a", "#d9d3c7", "#f6f2e9"
BLUE, EMBER, FOREST, GRAY, PLUM = "#3b6ea5", "#c4521e", "#2e7d5b", "#9a9384", "#7a4f8c"
plt.rcParams.update({"font.size": 9, "axes.edgecolor": LINE, "axes.spines.top": False,
                     "axes.spines.right": False, "figure.dpi": 120})

RESULTS = {"meta": {}, "errors": {}}


@contextlib.contextmanager
def experiment(name):
    """One experiment per cell. A failure is printed and recorded, and the run moves on."""
    t0 = time.time()
    try:
        yield
    except Exception:
        RESULTS["errors"][name] = traceback.format_exc()
        print(f"!! {name} failed:\n{traceback.format_exc()}")
    finally:
        print(f"[{name}: {time.time() - t0:.1f} s]")


print("executed:", datetime.date.today().isoformat())
print("torch", torch.__version__, "| CUDA", torch.version.cuda, "| CuPy", cp.__version__)
executed: 2026-09-12
torch 2.10.0+cu128 | CUDA 12.8 | CuPy 14.0.1The stopwatches. CUDA events time the GPU; a sampler polls the card’s sensors while a workload runs; and one more, steady, exists because of what the GPU note measured: on this card a short burst of tensor-core work runs at more than twice the clock of sustained work. Comparing a kernel timed in a burst against one timed after the power limit has bitten would measure the card’s mood, not the code. So every number in this lab that is compared with another number is taken after half a second of the same work, with the clock already settled.
def gpu_time(fn, iters=15, warmup=3, budget=1.0):
    """Median seconds of fn(), measured on the GPU with CUDA events."""
    for _ in range(warmup):
        fn()
    torch.cuda.synchronize()
    s, e = torch.cuda.Event(enable_timing=True), torch.cuda.Event(enable_timing=True)
    s.record(); fn(); e.record(); e.synchronize()
    n = int(min(iters, max(3, budget / max(s.elapsed_time(e) / 1e3, 1e-6))))
    ts = []
    for _ in range(n):
        s.record(); fn(); e.record(); e.synchronize()
        ts.append(s.elapsed_time(e) / 1e3)
    return float(np.median(ts))


def smi(fields="clocks.sm,power.draw,temperature.gpu"):
    out = subprocess.run(["nvidia-smi", "-i", "0", f"--query-gpu={fields}",
                          "--format=csv,noheader,nounits"], capture_output=True, text=True).stdout
    res = {}
    for key, val in zip(fields.split(","), (v.strip() for v in out.strip().split(","))):
        try:
            res[key] = float(val)
        except ValueError:
            res[key] = val
    return res


class Sampler:
    def __init__(self, period=0.2):
        self.period, self.samples, self._stop = period, [], threading.Event()

    def _loop(self):
        while not self._stop.is_set():
            self.samples.append(smi())
            self._stop.wait(self.period)

    def __enter__(self):
        self._thread = threading.Thread(target=self._loop, daemon=True)
        self._thread.start()
        return self

    def __exit__(self, *exc):
        self._stop.set(); self._thread.join()

    def summary(self):
        df = pd.DataFrame(self.samples[1:] or self.samples)
        return {k: float(df[k].median()) for k in df.columns if pd.api.types.is_numeric_dtype(df[k])}


def sustained(fn, seconds=2.0):
    """Seconds per call under continuous load, plus the clocks it ran at."""
    fn(); torch.cuda.synchronize()
    s, e = torch.cuda.Event(enable_timing=True), torch.cuda.Event(enable_timing=True)
    with Sampler() as smp:
        s.record()
        n, t0 = 0, time.perf_counter()
        while time.perf_counter() - t0 < seconds:
            fn(); n += 1
            if n % 4 == 0:
                torch.cuda.synchronize()
        e.record(); e.synchronize()
    return s.elapsed_time(e) / 1e3 / n, smp.summary()


def steady(fn, seconds=0.5, min_calls=3):
    """Median seconds per call once the card has settled into its power-capped state.

    Short bursts on this card run at a much higher clock than sustained work (the GPU note
    measures the effect), so any comparison between shapes or kernels has to be made in the
    same state. Every number in this lab that is compared with another comes from here.

    CUDA launches are asynchronous, so both phases synchronise after every call: otherwise
    the host could queue thousands of calls in a quarter of a second and the GPU would spend
    minutes — and degrees — draining them before the measurement even starts."""
    t0 = time.perf_counter()
    while time.perf_counter() - t0 < seconds / 2:          # settle the clock, one call at a time
        fn()
        torch.cuda.synchronize()
    s_ev, e_ev = torch.cuda.Event(enable_timing=True), torch.cuda.Event(enable_timing=True)
    ts, t0 = [], time.perf_counter()
    while time.perf_counter() - t0 < seconds or len(ts) < min_calls:
        s_ev.record(); fn(); e_ev.record(); e_ev.synchronize()
        ts.append(s_ev.elapsed_time(e_ev) / 1e3)
    return float(np.median(ts))


def sweep(configs, measure, repeats=3, seed=0):
    """Measure every config `repeats` times in a freshly shuffled order each round, so that a
    card warming up over the sweep can't masquerade as an effect of the config.
    Returns {config: [seconds, ...]}."""
    rng = np.random.default_rng(seed)
    out = {c: [] for c in configs}
    for _ in range(repeats):
        for i in rng.permutation(len(configs)):
            out[configs[i]].append(measure(configs[i]))
    return out


def jsonable(o):
    if isinstance(o, np.bool_):
        return bool(o)
    if isinstance(o, np.integer):
        return int(o)
    if isinstance(o, np.floating):
        return float(o)
    if isinstance(o, np.ndarray):
        return o.tolist()
    return str(o)


def free_gpu():
    cp.get_default_memory_pool().free_all_blocks()
    torch.cuda.empty_cache()
Part 1 — the two roofs, again
A matmul kernel can only be judged against what the card can do, so the lab re-measures both ceilings rather than importing them: the FP32 arithmetic roof (a kernel of nothing but independent multiply-adds in registers) and the memory roof (a streaming read).
ROOF_SRC = r'''
extern "C" __global__ void fma_peak(float* out, int iters) {
    float a0 = 1e-6f * threadIdx.x, a1 = a0 + 0.1f, a2 = a0 + 0.2f, a3 = a0 + 0.3f,
          a4 = a0 + 0.4f, a5 = a0 + 0.5f, a6 = a0 + 0.6f, a7 = a0 + 0.7f;
    const float b = 0.99999f, c = 1e-5f;
    #pragma unroll 4
    for (int k = 0; k < iters; ++k) {
        a0 = fmaf(a0, b, c); a1 = fmaf(a1, b, c); a2 = fmaf(a2, b, c); a3 = fmaf(a3, b, c);
        a4 = fmaf(a4, b, c); a5 = fmaf(a5, b, c); a6 = fmaf(a6, b, c); a7 = fmaf(a7, b, c);
    }
    out[blockIdx.x * blockDim.x + threadIdx.x] = a0 + a1 + a2 + a3 + a4 + a5 + a6 + a7;
}

extern "C" __global__ void stream_read(const float4* __restrict__ x, long long n4, float* sink) {
    long long tid = blockIdx.x * (long long)blockDim.x + threadIdx.x;
    long long nth = (long long)gridDim.x * blockDim.x;
    float acc = 0.f;
    #pragma unroll 4
    for (long long i = tid; i < n4; i += nth) {
        float4 v = x[i];
        acc += v.x + v.y + v.z + v.w;
    }
    if (acc == 1234.5f) sink[0] = acc;
}
'''
ROOFS = cp.RawModule(code=ROOF_SRC)

with experiment("roofs"):
    props = cp.cuda.runtime.getDeviceProperties(0)
    name = props["name"].decode() if isinstance(props["name"], bytes) else props["name"]
    sms = props["multiProcessorCount"]
    stat = smi("clocks.max.sm,power.limit")
    full_blocks = sms * (props["maxThreadsPerMultiProcessor"] // 256)

    out = cp.empty(full_blocks * 8 * 256, dtype=cp.float32)
    nth = out.size
    iters = 30000
    t, clocks = sustained(lambda: ROOFS.get_function("fma_peak")(
        (full_blocks * 8,), (256,), (out, np.int32(iters))))
    fp32_roof = nth * iters * 16 / t
    del out

    buf = cp.random.random(256 * 2**20 // 4, dtype=cp.float32)
    sink = cp.zeros(1, dtype=cp.float32)
    t = gpu_time(lambda: ROOFS.get_function("stream_read")(
        (full_blocks,), (256,), (buf, np.int64(buf.size // 4), sink)), iters=7)
    bw_roof = buf.nbytes / t
    del buf
    free_gpu()

    spec = {"gpu": name, "sms": int(sms), "max_clock_mhz": stat["clocks.max.sm"],
            "power_limit_w": stat["power.limit"], "fp32_roof": fp32_roof, "bw_roof": bw_roof,
            "ridge_fp32": fp32_roof / bw_roof, "clocks_under_fma": clocks}
    RESULTS["spec"] = spec
    print(f"{name}: {sms} SMs")
    print(f"FP32 compute roof : {fp32_roof / 1e12:6.2f} TFLOP/s  (at {clocks.get('clocks.sm', 0):.0f} MHz, "
          f"{clocks.get('power.draw', 0):.0f} W)")
    print(f"memory roof       : {bw_roof / 1e9:6.0f} GB/s")
    print(f"ridge point       : {fp32_roof / bw_roof:6.1f} FLOP per byte")
Tesla T4: 40 SMs
FP32 compute roof : 6.41 TFLOP/s (at 1335 MHz, 67 W)
memory roof : 265 GB/s
ridge point : 24.1 FLOP per byte
[roofs: 2.8 s]Part 2 — the ladder
Four hand-written kernel designs, in full — one in two thread mappings, one in three tile sizes, one with a register patch from 1×1 to 8×8 — and then cuBLAS in three precision setups. They are the same algorithm — three nested loops — arranged differently in memory. Read them as a sequence: each one changes exactly one thing about where the operands come from, and nothing about the arithmetic.
MM_SRC = r'''
// ── 1. naive: one thread per output element, everything from global memory ────
extern "C" __global__ void mm_naive(const float* __restrict__ A, const float* __restrict__ B,
                                    float* __restrict__ C, int M, int N, int K) {
    int col = blockIdx.x * blockDim.x + threadIdx.x;   // consecutive threads → consecutive columns
    int row = blockIdx.y * blockDim.y + threadIdx.y;
    if (row >= M || col >= N) return;
    float acc = 0.f;
    for (int k = 0; k < K; ++k) acc += A[row * K + k] * B[k * N + col];
    C[row * N + col] = acc;
}

// ── 2. the same kernel with the thread mapping transposed ────────────────────
// Consecutive threads now differ in *row*, so their loads from A are a whole row —
// K floats — apart, and their stores into C are strided by N. (Their loads from B
// coincide instead; it is A's traffic that stops coalescing.)
extern "C" __global__ void mm_naive_uncoalesced(const float* __restrict__ A, const float* __restrict__ B,
                                                float* __restrict__ C, int M, int N, int K) {
    int row = blockIdx.x * blockDim.x + threadIdx.x;
    int col = blockIdx.y * blockDim.y + threadIdx.y;
    if (row >= M || col >= N) return;
    float acc = 0.f;
    for (int k = 0; k < K; ++k) acc += A[row * K + k] * B[k * N + col];
    C[row * N + col] = acc;
}

// ── 3. shared-memory tiling ──────────────────────────────────────────────────
// The block cooperates: it loads a T×T tile of A and of B into shared memory,
// and every thread reads those tiles T times. Each byte fetched from DRAM is
// now used T times instead of once.
template <int T>
__device__ __forceinline__ void mm_tiled_impl(const float* __restrict__ A, const float* __restrict__ B,
                                              float* __restrict__ C, int M, int N, int K) {
    __shared__ float As[T][T], Bs[T][T];
    int tx = threadIdx.x, ty = threadIdx.y;
    int col = blockIdx.x * T + tx, row = blockIdx.y * T + ty;
    float acc = 0.f;
    for (int k0 = 0; k0 < K; k0 += T) {
        As[ty][tx] = (row < M && k0 + tx < K) ? A[row * K + k0 + tx] : 0.f;
        Bs[ty][tx] = (col < N && k0 + ty < K) ? B[(k0 + ty) * N + col] : 0.f;
        __syncthreads();
        #pragma unroll
        for (int k = 0; k < T; ++k) acc += As[ty][k] * Bs[k][tx];
        __syncthreads();
    }
    if (row < M && col < N) C[row * N + col] = acc;
}
extern "C" __global__ void mm_tiled8 (const float* __restrict__ A, const float* __restrict__ B, float* __restrict__ C, int M, int N, int K) { mm_tiled_impl<8>(A, B, C, M, N, K); }
extern "C" __global__ void mm_tiled16(const float* __restrict__ A, const float* __restrict__ B, float* __restrict__ C, int M, int N, int K) { mm_tiled_impl<16>(A, B, C, M, N, K); }
extern "C" __global__ void mm_tiled32(const float* __restrict__ A, const float* __restrict__ B, float* __restrict__ C, int M, int N, int K) { mm_tiled_impl<32>(A, B, C, M, N, K); }

// ── 4. register tiling: 16×16 threads per block, each owning a TT×TT patch of C ──
// Shared memory raised the reuse of DRAM bytes; registers now raise the reuse of
// shared-memory bytes. One load feeds TT multiply-adds instead of one, and every
// thread carries TT² independent accumulators instead of one dependent chain.
// The block tile grows with the patch (16·TT) so only the patch size changes.
template <int TT>
__device__ __forceinline__ void mm_reg_impl(const float* __restrict__ A, const float* __restrict__ B,
                                            float* __restrict__ C, int M, int N, int K) {
    __shared__ float As[16 * TT][16], Bs[16][16 * TT];
    int tx = threadIdx.x, ty = threadIdx.y;          // 16 × 16 threads
    int row0 = blockIdx.y * 16 * TT + ty * TT;
    int col0 = blockIdx.x * 16 * TT + tx * TT;
    float acc[TT][TT] = {{0.f}};
    for (int k0 = 0; k0 < K; k0 += 16) {
        #pragma unroll
        for (int i = 0; i < TT; ++i) {
            int r = row0 + i;
            As[ty * TT + i][tx] = (r < M && k0 + tx < K) ? A[r * K + k0 + tx] : 0.f;
            int c = col0 + i;
            Bs[ty][tx * TT + i] = (c < N && k0 + ty < K) ? B[(k0 + ty) * N + c] : 0.f;
        }
        __syncthreads();
        #pragma unroll
        for (int k = 0; k < 16; ++k) {
            float a[TT], b[TT];
            #pragma unroll
            for (int i = 0; i < TT; ++i) { a[i] = As[ty * TT + i][k]; b[i] = Bs[k][tx * TT + i]; }
            #pragma unroll
            for (int i = 0; i < TT; ++i)
                #pragma unroll
                for (int j = 0; j < TT; ++j) acc[i][j] = fmaf(a[i], b[j], acc[i][j]);
        }
        __syncthreads();
    }
    #pragma unroll
    for (int i = 0; i < TT; ++i) {
        #pragma unroll
        for (int j = 0; j < TT; ++j) {
            int r = row0 + i, c = col0 + j;
            if (r < M && c < N) C[r * N + c] = acc[i][j];
        }
    }
}
extern "C" __global__ void mm_reg1(const float* __restrict__ A, const float* __restrict__ B, float* __restrict__ C, int M, int N, int K) { mm_reg_impl<1>(A, B, C, M, N, K); }
extern "C" __global__ void mm_reg2(const float* __restrict__ A, const float* __restrict__ B, float* __restrict__ C, int M, int N, int K) { mm_reg_impl<2>(A, B, C, M, N, K); }
extern "C" __global__ void mm_reg4(const float* __restrict__ A, const float* __restrict__ B, float* __restrict__ C, int M, int N, int K) { mm_reg_impl<4>(A, B, C, M, N, K); }
extern "C" __global__ void mm_reg8(const float* __restrict__ A, const float* __restrict__ B, float* __restrict__ C, int M, int N, int K) { mm_reg_impl<8>(A, B, C, M, N, K); }
'''
MM = cp.RawModule(code=MM_SRC)
KERNELS = ["mm_naive", "mm_naive_uncoalesced", "mm_tiled8", "mm_tiled16", "mm_tiled32",
           "mm_reg1", "mm_reg2", "mm_reg4", "mm_reg8"]
COMPILE_ERRORS = {}
for k in KERNELS:
    try:
        MM.get_function(k)      # force compilation now, so errors surface here
    except Exception as exc:    # a patch too large for the register budget may not compile at all
        COMPILE_ERRORS[k] = str(exc).splitlines()[0][:200]
RESULTS["compile_errors"] = COMPILE_ERRORS
print("compiled:", ", ".join(k for k in KERNELS if k not in COMPILE_ERRORS), "| failed:", COMPILE_ERRORS or "none")
compiled: mm_naive, mm_naive_uncoalesced, mm_tiled8, mm_tiled16, mm_tiled32, mm_reg1, mm_reg2, mm_reg4, mm_reg8 | failed: noneThe tensor-core kernel is separate, because it needs a header (mma.h) and a different way of thinking: the unit of work is no longer a thread but a warp, and the warp issues one matrix-multiply operation for a whole 16×16×16 tile, which the compiler lowers to the tensor-core instructions underneath.
WMMA_SRC = r'''
#include <mma.h>
using namespace nvcuda;

// One warp computes one 16×16 tile of C. Inputs are FP16; the accumulator is FP32.
extern "C" __global__ void mm_wmma(const half* __restrict__ A, const half* __restrict__ B,
                                   float* __restrict__ C, int M, int N, int K) {
    int warp = (blockIdx.x * blockDim.x + threadIdx.x) / 32;
    int tilesN = N / 16;
    int tileRow = warp / tilesN, tileCol = warp % tilesN;
    if (tileRow * 16 >= M) return;

    wmma::fragment<wmma::matrix_a, 16, 16, 16, half, wmma::row_major> a_frag;
    wmma::fragment<wmma::matrix_b, 16, 16, 16, half, wmma::row_major> b_frag;
    wmma::fragment<wmma::accumulator, 16, 16, 16, float> acc;
    wmma::fill_fragment(acc, 0.0f);

    for (int k0 = 0; k0 < K; k0 += 16) {
        wmma::load_matrix_sync(a_frag, A + tileRow * 16 * K + k0, K);
        wmma::load_matrix_sync(b_frag, B + k0 * N + tileCol * 16, N);
        wmma::mma_sync(acc, a_frag, b_frag, acc);
    }
    wmma::store_matrix_sync(C + tileRow * 16 * N + tileCol * 16, acc, N, wmma::mem_row_major);
}
'''
WMMA, WMMA_BACKEND = None, None
with experiment("compile_wmma"):
    import glob, shutil, site

    def cuda_includes():
        """Where mma.h might live: a system CUDA install, or the pip packages torch pulls in."""
        roots = glob.glob("/usr/local/cuda*/include")
        for sp in site.getsitepackages() + [site.getusersitepackages()]:
            roots += glob.glob(os.path.join(sp, "nvidia", "*", "include"))
        return [d for d in roots if os.path.exists(os.path.join(d, "mma.h"))]

    def find_nvcc():
        found = shutil.which("nvcc") or next(iter(glob.glob("/usr/local/cuda*/bin/nvcc")), None)
        if found:
            return found
        for sp in site.getsitepackages() + [site.getusersitepackages()]:
            hit = glob.glob(os.path.join(sp, "nvidia", "cuda_nvcc", "bin", "nvcc"))
            if hit:
                return hit[0]
        return None

    incs, nvcc = cuda_includes(), find_nvcc()
    if not incs or not nvcc:
        print("  no local CUDA toolkit — pulling the compiler and headers from pip")
        subprocess.run([sys.executable, "-m", "pip", "install", "-q",
                        "nvidia-cuda-nvcc-cu12", "nvidia-cuda-runtime-cu12"], check=False)
        incs, nvcc = cuda_includes(), find_nvcc()
    print("  mma.h in:", incs[0] if incs else "nowhere")
    print("  nvcc    :", nvcc or "not found")

    attempts = []
    if incs:
        attempts.append(("nvrtc", dict(options=("-std=c++14", *[f"-I{d}" for d in incs]))))
    if nvcc:
        os.environ["CUDA_PATH"] = os.path.dirname(os.path.dirname(nvcc))
        os.environ["PATH"] = os.path.dirname(nvcc) + os.pathsep + os.environ.get("PATH", "")
        attempts.append(("nvcc", dict(options=("-std=c++14",), backend="nvcc")))
    for label, kwargs in attempts:
        try:
            mod = cp.RawModule(code=WMMA_SRC, **kwargs)
            mod.get_function("mm_wmma")
            WMMA, WMMA_BACKEND = mod, label
            break
        except Exception as exc:
            print(f"  {label}: {str(exc).splitlines()[0][:160]}")
    print("tensor-core kernel:", WMMA_BACKEND or "not compiled — cuBLAS fp16 stands in for this rung")
mma.h in: /usr/local/cuda-12.8/include
nvcc : /usr/local/cuda/bin/nvcc
tensor-core kernel: nvrtc
[compile_wmma: 0.2 s]Now run them. Every kernel is checked against a float64 reference before it is timed: a fast wrong answer is worth nothing, and the tiling kernels are exactly where an off-by-one hides.
with experiment("ladder"):
    N_LADDER = 1024
    cp.random.seed(0)
    A = cp.random.random((N_LADDER, N_LADDER), dtype=cp.float32)
    B = cp.random.random((N_LADDER, N_LADDER), dtype=cp.float32)
    ref = A.astype(cp.float64) @ B.astype(cp.float64)
    ref_t = torch.as_tensor(ref, device=DEV)
    C = cp.empty((N_LADDER, N_LADDER), dtype=cp.float32)
    n32 = [np.int32(N_LADDER)] * 3
    flops = 2 * N_LADDER ** 3
    rows = []

    def errors(out):
        """Normalized max error (largest error ÷ largest entry) and relative Frobenius error."""
        if isinstance(out, cp.ndarray):
            diff = out.astype(cp.float64) - ref
            return (float(cp.abs(diff).max() / cp.abs(ref).max()), float(cp.linalg.norm(diff) / cp.linalg.norm(ref)))
        diff = out.double() - ref_t
        return (float(diff.abs().max() / ref_t.abs().max()), float(torch.linalg.norm(diff) / torch.linalg.norm(ref_t)))

    def record(label, fn, out, fp32=True):
        out.fill(0) if isinstance(out, cp.ndarray) else out.zero_()
        fn(); torch.cuda.synchronize()
        e_max, e_fro = errors(out)                  # correctness first: a fast wrong answer is worth nothing
        t = steady(fn)
        rows.append(dict(kernel=label, seconds=t, flops_per_s=flops / t, err_max_norm=e_max, err_fro=e_fro,
                         pct_of_roof=100 * (flops / t) / RESULTS["spec"]["fp32_roof"] if fp32 else None))
        print(f"{label:44s} {t * 1e3:8.2f} ms  {flops / t / 1e9:8.1f} GFLOP/s   max {e_max:.1e}  Frobenius {e_fro:.1e}")

    f = MM.get_function("mm_naive")
    record("naive", lambda: f((N_LADDER // 16, N_LADDER // 16), (16, 16), (A, B, C, *n32)), C)
    f = MM.get_function("mm_naive_uncoalesced")
    record("naive, uncoalesced mapping", lambda: f((N_LADDER // 16, N_LADDER // 16), (16, 16), (A, B, C, *n32)), C)
    for T in (8, 16, 32):
        f = MM.get_function(f"mm_tiled{T}")
        record(f"shared-memory tiles {T}×{T}", lambda f=f, T=T: f((N_LADDER // T, N_LADDER // T), (T, T), (A, B, C, *n32)), C)
    f = MM.get_function("mm_reg4")
    record("register tiles, 64×64 block", lambda: f((N_LADDER // 64, N_LADDER // 64), (16, 16), (A, B, C, *n32)), C)

    tA, tB = torch.as_tensor(A, device=DEV), torch.as_tensor(B, device=DEV)
    tC = torch.empty((N_LADDER, N_LADDER), device=DEV, dtype=torch.float32)
    record("cuBLAS fp32 (torch.mm)", lambda: torch.mm(tA, tB, out=tC), tC)

    Ah, Bh = A.astype(cp.float16), B.astype(cp.float16)
    C32 = cp.empty((N_LADDER, N_LADDER), dtype=cp.float32)
    if WMMA is not None:
        warps = (N_LADDER // 16) * (N_LADDER // 16)
        fw = WMMA.get_function("mm_wmma")
        record("hand-written tensor cores (fp16 in, fp32 acc)",
               lambda: fw((warps * 32 // 256,), (256,), (Ah, Bh, C32, *n32)), C32, fp32=False)

    # cuBLAS with exactly the hand-written kernel's formats: FP16 inputs, FP32 accumulator and output.
    # torch.mm can't express that, so this calls cuBLAS GemmEx directly. Row-major C = A·B is the
    # column-major product Cᵀ = Bᵀ·Aᵀ, so B goes in the first operand slot.
    try:
        from cupy_backends.cuda.libs import cublas as cublas_lib
        handle = cp.cuda.device.get_cublas_handle()
        one, zero = np.array(1.0, np.float32), np.array(0.0, np.float32)
        R16F, R32F, TENSOR_OP = 2, 0, 99
        def gemmex(compute):
            cublas_lib.gemmEx(handle, 0, 0, N_LADDER, N_LADDER, N_LADDER, one.ctypes.data,
                              Bh.data.ptr, R16F, N_LADDER, Ah.data.ptr, R16F, N_LADDER,
                              zero.ctypes.data, C32.data.ptr, R32F, N_LADDER, compute, TENSOR_OP)
        compute_type, last_exc = None, None
        for candidate in (68, 0):                   # CUBLAS_COMPUTE_32F, then the legacy CUDA_R_32F
            try:
                gemmex(candidate); cp.cuda.Device().synchronize()
                compute_type = candidate
                break
            except Exception as exc:
                last_exc = exc
        if compute_type is None:
            raise last_exc
        record("cuBLAS fp16 in → fp32 out (GemmEx)", lambda: gemmex(compute_type), C32, fp32=False)
    except Exception as exc:
        RESULTS["errors"]["gemmex"] = traceback.format_exc()
        print("  GemmEx fp16 → fp32 not available here:", str(exc).splitlines()[0][:160])

    tAh, tBh = tA.half(), tB.half()
    tCh = torch.empty((N_LADDER, N_LADDER), device=DEV, dtype=torch.float16)
    record("cuBLAS fp16 tensor cores", lambda: torch.mm(tAh, tBh, out=tCh), tCh, fp32=False)

    ladder = pd.DataFrame(rows)
    ladder["vs_naive"] = ladder.flops_per_s / ladder.flops_per_s.iloc[0]
    RESULTS["ladder"] = {"n": N_LADDER, "rows": ladder.to_dict("records"), "wmma_backend": WMMA_BACKEND}
    del A, B, C, C32, Ah, Bh, ref, ref_t, tA, tB, tC, tAh, tBh, tCh
    free_gpu()

    fig, ax = plt.subplots(figsize=(7.2, 3.6))
    ax.barh(range(len(ladder)), ladder.flops_per_s / 1e12,
            color=[GRAY if "naive" in k else BLUE if "cuBLAS" in k else FOREST for k in ladder.kernel])
    ax.set_yticks(range(len(ladder))); ax.set_yticklabels(ladder.kernel, fontsize=8)
    ax.invert_yaxis(); ax.set_xlabel("TFLOP/s"); ax.set_xscale("log")
    plt.tight_layout(); plt.show()
naive 4.65 ms 462.1 GFLOP/s max 1.9e-06 Frobenius 4.3e-07
naive, uncoalesced mapping 17.92 ms 119.8 GFLOP/s max 1.9e-06 Frobenius 4.3e-07
shared-memory tiles 8×8 4.23 ms 507.3 GFLOP/s max 1.9e-06 Frobenius 4.3e-07
shared-memory tiles 16×16 2.93 ms 733.6 GFLOP/s max 1.9e-06 Frobenius 4.3e-07
shared-memory tiles 32×32 2.47 ms 870.9 GFLOP/s max 1.9e-06 Frobenius 4.3e-07
register tiles, 64×64 block 0.93 ms 2317.7 GFLOP/s max 1.9e-06 Frobenius 4.3e-07
cuBLAS fp32 (torch.mm) 0.60 ms 3601.7 GFLOP/s max 4.5e-07 Frobenius 1.0e-07
hand-written tensor cores (fp16 in, fp32 acc) 0.65 ms 3296.3 GFLOP/s max 5.7e-05 Frobenius 1.5e-05
cuBLAS fp16 in → fp32 out (GemmEx) 0.10 ms 21938.2 GFLOP/s max 5.7e-05 Frobenius 1.5e-05
cuBLAS fp16 tensor cores 0.09 ms 23293.6 GFLOP/s max 4.7e-04 Frobenius 2.2e-04
[ladder: 9.3 s]The register patch: reuse against occupancy
The register rung used a 4×4 patch. A bigger patch collects more reuse — one shared-memory read feeds more multiply-adds — but every accumulator is a register, registers are divided among the resident threads, and a thread that needs more than its share means fewer threads fit. So the patch is swept from 1×1 to 8×8, with the block growing alongside (16 threads per side, always) so that nothing but the patch changes. The register count is an estimate from the kernel’s live variables; the compiler’s exact allocation isn’t visible from Python.
with experiment("register_patch"):
    n = 1024
    cp.random.seed(0)
    A = cp.random.random((n, n), dtype=cp.float32)
    B = cp.random.random((n, n), dtype=cp.float32)
    ref = A.astype(cp.float64) @ B.astype(cp.float64)
    C = cp.empty((n, n), dtype=cp.float32)
    flops = 2 * n ** 3
    budget = props["regsPerMultiprocessor"] // props["maxThreadsPerMultiProcessor"]   # registers per thread at full occupancy
    rows = []
    for TT in (1, 2, 4, 8):
        name, BT = f"mm_reg{TT}", 16 * TT
        regs = TT * TT + 2 * TT + 8          # accumulators + operand registers + indices and counters
        row = dict(patch=TT, block=BT, reads_per_fma=2 / TT, registers_est=regs,
                   occupancy_est=min(1.0, budget / regs), seconds=None, flops_per_s=None, err_fro=None, note="")
        if name in COMPILE_ERRORS:
            row["note"] = COMPILE_ERRORS[name]
        else:
            f = MM.get_function(name)
            run = lambda f=f, BT=BT: f((n // BT, n // BT), (16, 16), (A, B, C, np.int32(n), np.int32(n), np.int32(n)))
            C.fill(0); run(); cp.cuda.Device().synchronize()
            row["err_fro"] = float(cp.linalg.norm(C.astype(cp.float64) - ref) / cp.linalg.norm(ref))
            row["seconds"] = steady(run)
            row["flops_per_s"] = flops / row["seconds"]
        rows.append(row)
    patch = pd.DataFrame(rows)
    RESULTS["register_patch"] = {"n": n, "register_budget_per_thread": int(budget), "rows": patch.to_dict("records")}
    del A, B, C, ref
    free_gpu()
    print(f"register budget at full occupancy: {budget} per thread")
    print(patch.to_string(index=False, float_format=lambda v: f"{v:.3g}"))
register budget at full occupancy: 64 per thread
patch block reads_per_fma registers_est occupancy_est seconds flops_per_s err_fro note
1 16 2 11 1 0.003 7.17e+11 4.28e-07
2 32 1 16 1 0.00159 1.35e+12 4.28e-07
4 64 0.5 32 1 0.000944 2.28e+12 4.28e-07
8 128 0.25 88 0.727 0.000857 2.51e+12 4.28e-07
[register_patch: 3.0 s]Part 3 — the tile is the intensity
A tile of side T means each byte brought from DRAM is used T times, so the kernel’s arithmetic intensity is T/4 FLOPs per byte in FP32. That is the whole reason tiling works, and it is measurable: the tile sweep of Part 2 becomes a walk along the roofline.
with experiment("tiles_on_roofline"):
    spec = RESULTS["spec"]
    rows = []
    for r in RESULTS["ladder"]["rows"]:
        k = r["kernel"]
        if k.startswith("shared-memory tiles"):
            T = int(k.split()[2].split("×")[0])
            rows.append(dict(kernel=k, tile=T, ai=T / 4, flops_per_s=r["flops_per_s"]))
        elif k.startswith("naive") and "uncoalesced" not in k:
            rows.append(dict(kernel=k, tile=1, ai=0.25, flops_per_s=r["flops_per_s"]))
        elif k.startswith("register"):
            rows.append(dict(kernel=k, tile=64, ai=64 / 4, flops_per_s=r["flops_per_s"]))
    tiles = pd.DataFrame(rows)
    tiles["roof_here"] = np.minimum(spec["fp32_roof"], spec["bw_roof"] * tiles.ai)
    tiles["pct_of_roof_here"] = 100 * tiles.flops_per_s / tiles.roof_here
    RESULTS["tiles"] = tiles.to_dict("records")
    print(tiles.to_string(index=False, float_format=lambda v: f"{v:.3g}"))

    ai = np.logspace(-1.2, 3, 200)
    fig, ax = plt.subplots(figsize=(6.8, 3.8))
    ax.plot(ai, np.minimum(spec["fp32_roof"], spec["bw_roof"] * ai) / 1e12, color=INK, lw=1.4)
    ax.scatter(tiles.ai, tiles.flops_per_s / 1e12, s=30, color=EMBER, zorder=3)
    for _, r in tiles.iterrows():
        ax.annotate(f"tile {r.tile}", (r.ai, r.flops_per_s / 1e12), textcoords="offset points",
                    xytext=(6, -3), fontsize=8, color=INK)
    ax.set_xscale("log"); ax.set_yscale("log")
    ax.set_xlabel("arithmetic intensity (FLOP/byte), from the tile size")
    ax.set_ylabel("TFLOP/s")
    plt.tight_layout(); plt.show()
kernel tile ai flops_per_s roof_here pct_of_roof_here
naive 1 0.25 4.62e+11 6.64e+10 696
shared-memory tiles 8×8 8 2 5.07e+11 5.31e+11 95.5
shared-memory tiles 16×16 16 4 7.34e+11 1.06e+12 69.1
shared-memory tiles 32×32 32 8 8.71e+11 2.12e+12 41
register tiles, 64×64 block 64 16 2.32e+12 4.25e+12 54.6
[tiles_on_roofline: 0.4 s]Part 4 — precision
The tensor cores only take FP16 (on this card), so the ladder’s last rungs change the arithmetic, not just its arrangement. Two questions, both measurable: how much speed does the lower precision buy, and how much accuracy does it cost against a float64 answer?
with experiment("precision"):
    n = 2048
    cp.random.seed(0)
    A = cp.random.random((n, n), dtype=cp.float32) - 0.5
    B = cp.random.random((n, n), dtype=cp.float32) - 0.5
    ref = A.astype(cp.float64) @ B.astype(cp.float64)
    ref_t = torch.as_tensor(ref, device=DEV)
    flops = 2 * n ** 3
    rows = []
    for label, dt in [("fp32 (CUDA cores)", torch.float32), ("fp16 (tensor cores)", torch.float16)]:
        tA = torch.as_tensor(A, device=DEV).to(dt)
        tB = torch.as_tensor(B, device=DEV).to(dt)
        out = torch.empty((n, n), device=DEV, dtype=dt)
        t = steady(lambda: torch.mm(tA, tB, out=out))
        diff = out.double() - ref_t
        rows.append(dict(precision=label, seconds=t, flops_per_s=flops / t,
                         err_max_norm=float(diff.abs().max() / ref_t.abs().max()),
                         err_fro=float(torch.linalg.norm(diff) / torch.linalg.norm(ref_t)),
                         bytes_per_element=out.element_size()))
        del tA, tB, out, diff
    prec = pd.DataFrame(rows)
    prec["speedup_vs_fp32"] = prec.flops_per_s / prec.flops_per_s.iloc[0]
    RESULTS["precision"] = {"n": n, "rows": prec.to_dict("records")}
    del A, B, ref, ref_t
    free_gpu()
    print(prec.to_string(index=False, float_format=lambda v: f"{v:.4g}"))
precision seconds flops_per_s err_max_norm err_fro bytes_per_element speedup_vs_fp32
fp32 (CUDA cores) 0.004657 3.689e+12 1e-06 5.741e-07 4 1
fp16 (tensor cores) 0.0008585 2.001e+13 0.0004605 0.0003334 2 5.424
[precision: 2.3 s]Part 5 — cuBLAS, and what shape does to it
cuBLAS is the ladder’s top rung, but it is not one kernel: it picks a tiling for the shape it is given. Three sweeps show what that means in practice — size, alignment, and layout.
with experiment("cublas_size"):
    DT = {"fp32": torch.float32, "fp16": torch.float16}
    configs = [(n, pr) for n in [128, 256, 512, 1024, 1536, 2048, 3072, 4096, 6144, 8192] for pr in ("fp32", "fp16")]

    def measure(cfg):
        n, pr = cfg
        A = torch.randn(n, n, device=DEV, dtype=DT[pr])
        B = torch.randn(n, n, device=DEV, dtype=DT[pr])
        t = steady(lambda: A @ B, seconds=0.4)
        del A, B
        return t

    res = sweep(configs, measure, repeats=3)
    free_gpu()
    size = pd.DataFrame([dict(n=n, precision=pr, seconds=float(np.median(ts)), seconds_min=min(ts), seconds_max=max(ts),
                              flops_per_s=2 * n ** 3 / float(np.median(ts))) for (n, pr), ts in res.items()])
    RESULTS["cublas_size"] = size.to_dict("records")
    print(size.pivot(index="n", columns="precision", values="flops_per_s").apply(lambda c: c / 1e12).round(1).to_string())

    fig, ax = plt.subplots(figsize=(6.8, 3.4))
    for label, color in [("fp32", GRAY), ("fp16", BLUE)]:
        d = size[size.precision == label].sort_values("n")
        ax.plot(d.n, d.flops_per_s / 1e12, "-o", ms=3, color=color, label=label)
    ax.set_xscale("log", base=2); ax.set_xlabel("n (n×n @ n×n)"); ax.set_ylabel("TFLOP/s")
    ax.legend(frameon=False); plt.tight_layout(); plt.show()
precision fp16 fp32
n
128 0.1 0.1
256 1.1 0.9
512 8.7 3.4
1024 20.5 3.1
1536 21.2 3.3
2048 19.0 3.3
3072 20.0 3.2
4096 18.8 3.4
6144 14.0 3.1
8192 20.4 3.3
[cublas_size: 39.7 s]Alignment next. A GPU matmul is cut into tiles of a fixed size — commonly 128 or 64 elements on a side — so a matrix whose dimensions are not multiples of that leaves ragged tiles at the edge, and a grid that doesn’t divide evenly across the SMs leaves some of them idle on the last wave. Both show up as a sawtooth around the “nice” sizes — and cuBLAS may also simply pick a different kernel for a slightly different shape. To tell these apart, the same one-element step is measured for a kernel whose tiling can’t change: this lab’s own 32×32 shared-memory tiles. Every size is measured three times in shuffled order, so a card warming up over the sweep can’t pass for an effect of size.
with experiment("cublas_quantization"):
    cu_sizes = list(range(4088, 4105)) + [2048, 2049, 2056, 2064, 2080, 2112, 2176, 2304]

    def measure_cublas(n):
        A = torch.randn(n, n, device=DEV, dtype=torch.float16)
        B = torch.randn(n, n, device=DEV, dtype=torch.float16)
        t = steady(lambda: A @ B, seconds=0.35)
        del A, B
        return t

    res = sweep(cu_sizes, measure_cublas, repeats=3)
    quant = pd.DataFrame([dict(n=n, seconds=float(np.median(ts)), seconds_min=min(ts), seconds_max=max(ts),
                               flops_per_s=2 * n ** 3 / float(np.median(ts))) for n, ts in res.items()]).sort_values("n")

    # The same one-element step for a kernel whose tiling can't change: shared-memory tiles of 32.
    # Its ragged edge costs exactly one more partial tile per dimension, so any extra slowdown
    # cuBLAS shows beyond this is not the edge itself.
    f32 = MM.get_function("mm_tiled32")
    def measure_fixed(n):
        A = cp.random.random((n, n), dtype=cp.float32)
        B = cp.random.random((n, n), dtype=cp.float32)
        C = cp.empty((n, n), dtype=cp.float32)
        g = -(-n // 32)
        t = steady(lambda: f32((g, g), (32, 32), (A, B, C, np.int32(n), np.int32(n), np.int32(n))), seconds=0.4)
        del A, B, C
        return t

    res_fixed = sweep([2048, 2049, 4096, 4097], measure_fixed, repeats=3, seed=1)
    free_gpu()
    fixed = pd.DataFrame([dict(n=n, seconds=float(np.median(ts)), seconds_min=min(ts), seconds_max=max(ts),
                               flops_per_s=2 * n ** 3 / float(np.median(ts))) for n, ts in res_fixed.items()]).sort_values("n")
    RESULTS["cublas_quantization"] = quant.to_dict("records")
    RESULTS["fixed_tiling_alignment"] = fixed.to_dict("records")

    def step(df, a, b):
        ra, rb = df[df.n == a].iloc[0], df[df.n == b].iloc[0]
        return 100 * (rb.seconds / ra.seconds - 1), 100 * (1 - rb.flops_per_s / ra.flops_per_s)
    for a, b in [(2048, 2049), (4096, 4097)]:
        ct, cf = step(quant, a, b); ft, ff = step(fixed, a, b)
        print(f"{a} → {b}:  cuBLAS fp16 time +{ct:.0f}% (throughput −{cf:.0f}%)   "
              f"fixed 32×32 tiles time +{ft:.1f}% (throughput −{ff:.1f}%)")
    near = quant[(quant.n >= 4088) & (quant.n <= 4104)]
    print(near.assign(tflops=near.flops_per_s / 1e12)[["n", "tflops"]].to_string(index=False, float_format=lambda v: f"{v:.1f}"))
2048 → 2049: cuBLAS fp16 time +54% (throughput −35%) fixed 32×32 tiles time +9.3% (throughput −8.4%)
4096 → 4097: cuBLAS fp16 time +50% (throughput −33%) fixed 32×32 tiles time +4.4% (throughput −4.2%)
n tflops
4088 17.3
4089 13.8
4090 12.9
4091 14.6
4092 12.7
4093 14.6
4094 13.7
4095 14.0
4096 19.3
4097 12.9
4098 13.0
4099 12.8
4100 12.5
4101 13.2
4102 12.4
4103 12.6
4104 15.8
[cublas_quantization: 49.1 s]Timing shows the jump but not its cause. PyTorch’s profiler does: it records the name of every kernel launched on the GPU, so the next cell asks which kernel cuBLAS runs at each size, in FP16 and in FP32. The sizes include 4092 and 4100 — multiples of 4 but not of 8 — to see where the fast kernels stop. FP32 gets its own timing, measured the same way as the FP16 sweep above.
with experiment("cublas_kernels"):
    from torch.autograd import DeviceType
    from torch.profiler import ProfilerActivity, profile
    import warnings

    def kernel_names(A, B, calls=3):
        """The GPU kernels one A @ B launches, as named in PyTorch's profiler (fills excluded)."""
        for _ in range(3):
            A @ B
        torch.cuda.synchronize()
        with warnings.catch_warnings():
            warnings.simplefilter("ignore")
            with profile(activities=[ProfilerActivity.CPU, ProfilerActivity.CUDA]) as prof:
                for _ in range(calls):
                    A @ B
                torch.cuda.synchronize()
        return sorted({e.name for e in prof.events() if e.device_type == DeviceType.CUDA and "Memset" not in e.name})

    k_sizes = [2048, 2049, 4088, 4092, 4096, 4097, 4100, 4104]
    DT = {"fp16": torch.float16, "fp32": torch.float32}
    names = {}
    for pr, dt in DT.items():
        for n in k_sizes:
            A = torch.randn(n, n, device=DEV, dtype=dt)
            B = torch.randn(n, n, device=DEV, dtype=dt)
            names[(pr, n)] = kernel_names(A, B)
            del A, B

    def measure_fp32(n):
        A = torch.randn(n, n, device=DEV, dtype=torch.float32)
        B = torch.randn(n, n, device=DEV, dtype=torch.float32)
        t = steady(lambda: A @ B, seconds=0.35)
        del A, B
        return t

    res32 = sweep(k_sizes, measure_fp32, repeats=3, seed=2)
    free_gpu()
    fp16_seconds = dict(zip(quant.n, quant.seconds))
    kernels = pd.DataFrame([dict(n=n, precision=pr, kernels=names[(pr, n)],
                                 seconds=fp16_seconds[n] if pr == "fp16" else float(np.median(res32[n])))
                            for pr in DT for n in k_sizes])
    RESULTS["cublas_kernels"] = kernels.to_dict("records")
    for pr in DT:
        d = kernels[kernels.precision == pr]
        base = d[d.n == 4096].seconds.iloc[0]
        print(f"\n{pr}")
        for r in d.itertuples():
            print(f"  n = {r.n}  {r.seconds * 1e3:7.2f} ms  ({100 * (r.seconds / base - 1):+5.1f}% vs 4096)  {' + '.join(r.kernels)}")
fp16
  n = 2048     0.95 ms  (-86.7% vs 4096)  turing_fp16_s1688gemm_fp16_128x128_ldg8_f2f_nn
  n = 2049     1.46 ms  (-79.5% vs 4096)  void cutlass::Kernel2<cutlass_75_tensorop_f16_s1688gemm_f16_256x128_nn_align1>(cutlass_75_tensorop_f16_s1688gemm_f16_256x128_nn_align1::Params)
  n = 4088     7.89 ms  (+11.0% vs 4096)  turing_fp16_s1688gemm_fp16_256x128_ldg8_f2f_stages_32x1_nn
  n = 4092    10.82 ms  (+52.2% vs 4096)  void cutlass::Kernel2<cutlass_75_tensorop_f16_s1688gemm_f16_256x128_nn_align2>(cutlass_75_tensorop_f16_s1688gemm_f16_256x128_nn_align2::Params)
  n = 4096     7.11 ms  ( +0.0% vs 4096)  turing_fp16_s1688gemm_fp16_256x128_ldg8_f2f_stages_32x1_nn
  n = 4097    10.67 ms  (+50.0% vs 4096)  void cutlass::Kernel2<cutlass_75_tensorop_f16_s1688gemm_f16_256x128_nn_align1>(cutlass_75_tensorop_f16_s1688gemm_f16_256x128_nn_align1::Params)
  n = 4100    11.01 ms  (+54.9% vs 4096)  void cutlass::Kernel2<cutlass_75_tensorop_f16_s1688gemm_f16_256x128_nn_align2>(cutlass_75_tensorop_f16_s1688gemm_f16_256x128_nn_align2::Params)
  n = 4104     8.73 ms  (+22.7% vs 4096)  turing_fp16_s1688gemm_fp16_128x256_ldg8_f2f_stages_32x1_nn

fp32
  n = 2048     5.15 ms  (-87.1% vs 4096)  volta_sgemm_128x64_nn
  n = 2049     5.53 ms  (-86.1% vs 4096)  volta_sgemm_128x64_nn
  n = 4088    42.36 ms  ( +6.1% vs 4096)  volta_sgemm_128x64_nn
  n = 4092    42.53 ms  ( +6.6% vs 4096)  volta_sgemm_128x64_nn
  n = 4096    39.91 ms  ( +0.0% vs 4096)  volta_sgemm_128x64_nn
  n = 4097    44.37 ms  (+11.2% vs 4096)  volta_sgemm_128x64_nn
  n = 4100    44.74 ms  (+12.1% vs 4096)  volta_sgemm_128x64_nn
  n = 4104    44.66 ms  (+11.9% vs 4096)  volta_sgemm_128x64_nn
[cublas_kernels: 20.9 s]
Layout last: the same numbers, multiplied in the same order, but stored transposed. cuBLAS is column-major underneath, so a PyTorch A @ B is already a transposed problem for it; asking for A.T @ B or A @ B.T changes which operand it has to read across its stride.
with experiment("cublas_layout"):
    n = 4096
    A = torch.randn(n, n, device=DEV, dtype=torch.float16)
    B = torch.randn(n, n, device=DEV, dtype=torch.float16)
    At, Bt = A.t().contiguous(), B.t().contiguous()
    flops = 2 * n ** 3
    cases = {
        "A @ B": lambda: A @ B,
        "A.T @ B (A stored transposed)": lambda: At.t() @ B,
        "A @ B.T (B stored transposed)": lambda: A @ Bt.t(),
        "A.T @ B.T": lambda: At.t() @ Bt.t(),
    }
    res = sweep(list(cases), lambda k: steady(cases[k]), repeats=3)
    layout = pd.DataFrame([dict(case=k, seconds=float(np.median(ts)), seconds_min=min(ts), seconds_max=max(ts),
                                flops_per_s=flops / float(np.median(ts))) for k, ts in res.items()])
    layout["vs_plain"] = layout.flops_per_s / layout.flops_per_s.iloc[0]
    RESULTS["cublas_layout"] = layout.to_dict("records")
    del A, B, At, Bt
    free_gpu()
    print(layout.to_string(index=False, float_format=lambda v: f"{v:.4g}"))
case seconds seconds_min seconds_max flops_per_s vs_plain
A @ B 0.007533 0.007319 0.007536 1.825e+13 1
A.T @ B (A stored transposed) 0.007452 0.007451 0.007455 1.844e+13 1.011
A @ B.T (B stored transposed) 0.007756 0.007736 0.007973 1.772e+13 0.9712
A.T @ B.T 0.006582 0.006578 0.006748 2.088e+13 1.144
[cublas_layout: 9.1 s]The last sweep is the one that matters for language models: a matmul where one dimension is tiny. For (M × K)(K × N) with s bytes per number, the arithmetic is 2MKN FLOPs and the least traffic any kernel can have — each input read once, each output written once — is s (MK + KN + MN) bytes, so the best possible intensity is
$$I = \frac{2MKN}{s\,(MK + KN + MN)}$$
With M = 1 — the shape a model runs when it generates a single token — that is about 1, and no amount of tiling can give the operation intensity the formula doesn’t allow. The sweep below computes exactly this quantity for each M, so the table is a check of the formula against the measured bytes per second.
with experiment("skinny"):
    K = N = 4096
    W = torch.randn(K, N, device=DEV, dtype=torch.float16)
    Ms = [1, 2, 4, 8, 16, 32, 64, 128, 256, 512, 1024, 2048]
    X = {M: torch.randn(M, K, device=DEV, dtype=torch.float16) for M in Ms}
    res = sweep(Ms, lambda M: steady(lambda: X[M] @ W, seconds=0.35), repeats=3)
    rows = []
    for M, ts in sorted(res.items()):
        t = float(np.median(ts))
        flops = 2 * M * K * N
        nbytes = 2 * (M * K + K * N + M * N)          # s·(MK + KN + MN), s = 2 bytes in FP16
        rows.append(dict(M=M, seconds=t, seconds_min=min(ts), seconds_max=max(ts), flops_per_s=flops / t,
                         bytes_per_s=nbytes / t, ai=flops / nbytes))
    skinny = pd.DataFrame(rows)
    RESULTS["skinny"] = skinny.to_dict("records")
    del W, X
    free_gpu()
    print(skinny.to_string(index=False, float_format=lambda v: f"{v:.4g}"))
M seconds seconds_min seconds_max flops_per_s bytes_per_s ai
1 0.0001771 0.0001763 0.000178 1.895e+11 1.896e+11 0.9995
2 0.0001737 0.0001736 0.0001739 3.864e+11 1.934e+11 1.998
4 0.0001754 0.000175 0.000176 7.654e+11 1.917e+11 3.992
8 0.0001785 0.0001784 0.0001789 1.504e+12 1.888e+11 7.969
16 0.0001851 0.0001849 0.0001852 2.901e+12 1.827e+11 15.88
32 0.0001641 0.000164 0.0001643 6.541e+12 2.076e+11 31.51
64 0.00017 0.0001693 0.0001705 1.263e+13 2.036e+11 62.06
128 0.0002827 0.0002756 0.0002872 1.52e+13 1.261e+11 120.5
256 0.0004379 0.0004299 0.0004495 1.962e+13 8.62e+10 227.6
512 0.001106 0.001074 0.001121 1.553e+13 3.792e+10 409.6
1024 0.00174 0.001702 0.001781 1.974e+13 2.892e+10 682.7
2048 0.003447 0.003362 0.003537 1.993e+13 1.947e+10 1024
[skinny: 18.9 s]Everything in one place
with experiment("summary"):
    spec = RESULTS["spec"]
    ladder = pd.DataFrame(RESULTS["ladder"]["rows"])
    best = ladder.loc[ladder.flops_per_s.idxmax()]
    naive = ladder.iloc[0]
    print(f"card              : {spec['gpu']}, FP32 roof {spec['fp32_roof'] / 1e12:.2f} TFLOP/s, "
          f"memory roof {spec['bw_roof'] / 1e9:.0f} GB/s, ridge {spec['ridge_fp32']:.0f} FLOP/B")
    print(f"naive kernel      : {naive.flops_per_s / 1e9:.1f} GFLOP/s "
          f"({100 * naive.flops_per_s / spec['fp32_roof']:.1f}% of the FP32 roof)")
    print(f"best of the ladder: {best.kernel} — {best.flops_per_s / 1e12:.2f} TFLOP/s "
          f"({best.flops_per_s / naive.flops_per_s:.0f}× the naive kernel)")
    print("\nerrors:", list(RESULTS["errors"]) or "none")
card : Tesla T4, FP32 roof 6.41 TFLOP/s, memory roof 265 GB/s, ridge 24 FLOP/B
naive kernel : 462.1 GFLOP/s (7.2% of the FP32 roof)
best of the ladder: cuBLAS fp16 tensor cores — 23.29 TFLOP/s (50× the naive kernel)
errors: none
[summary: 0.0 s]RESULTS["meta"].update(
executed=datetime.datetime.now(datetime.timezone.utc).isoformat(timespec="seconds"),
torch=torch.__version__, cuda=torch.version.cuda, cupy=cp.__version__,
python=platform.python_version(), kaggle=bool(os.environ.get("KAGGLE_KERNEL_RUN_TYPE")),
)
out_dir = "/kaggle/working" if os.path.isdir("/kaggle/working") else "."
with open(os.path.join(out_dir, "matmul_results.json"), "w") as f:
json.dump(RESULTS, f, default=jsonable, indent=1)
print("saved", os.path.join(out_dir, "matmul_results.json"))saved /kaggle/working/matmul_results.json