Chapter 2 of 4
Mechanistic Interpretability: Looking Inside the Black Box
Created Jun 17, 2026 Updated Jul 3, 2026
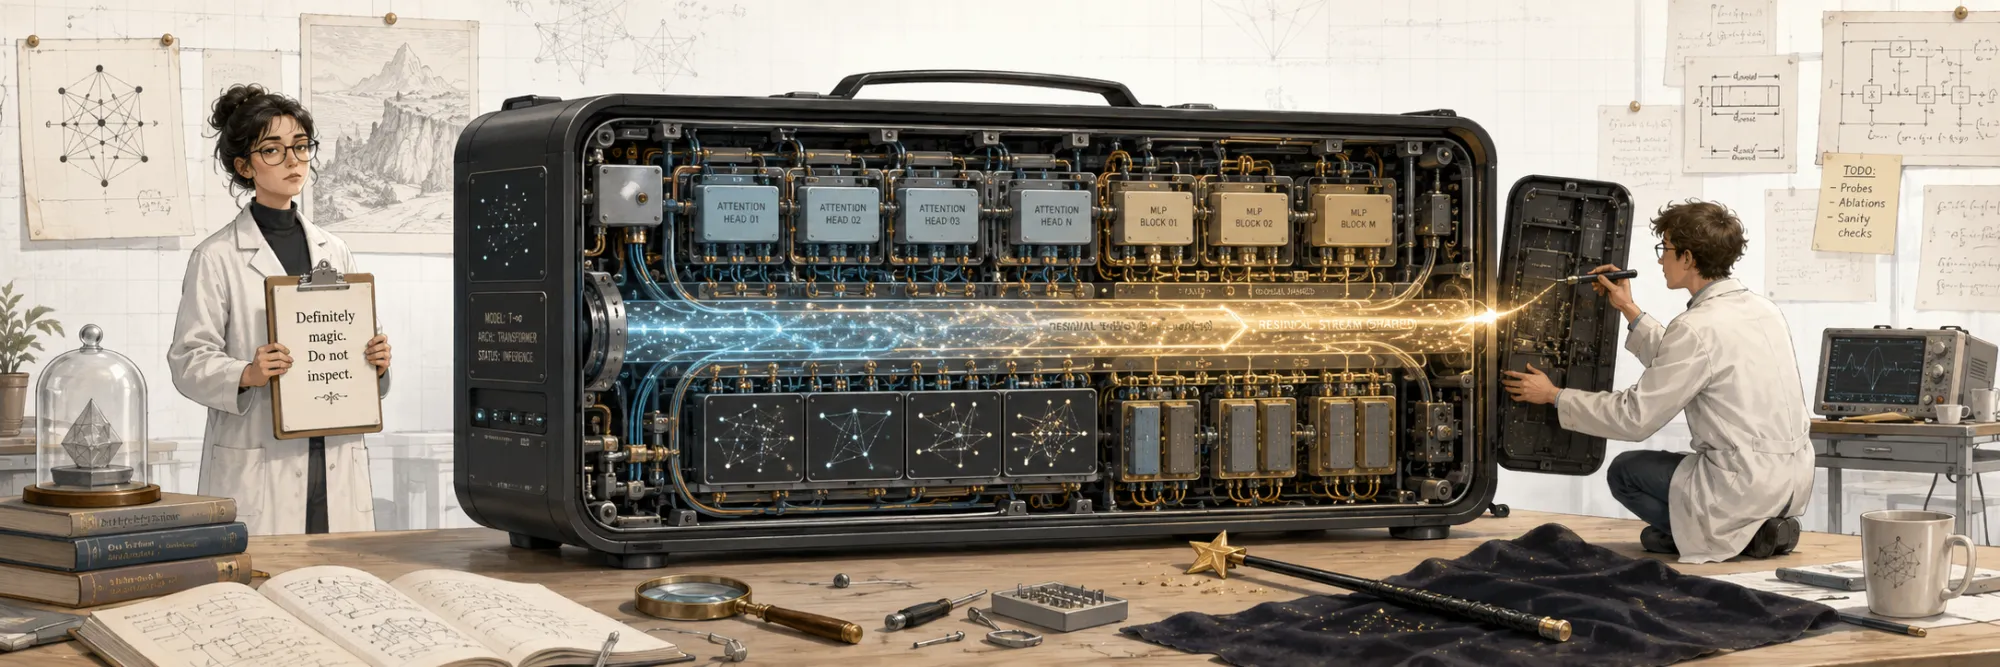
We call a trained network a "black box," and the phrase quietly smuggles in a claim: that what happens between input and output is not merely unknown but unknowable — an opaque tangle of billions of numbers with no human-legible structure inside. Mechanistic interpretability (MI) is the bet that this claim is false. A transformer is not an oracle. It is a specific, finite computation written almost entirely in linear algebra, run over a few hundred layers of matrix multiplies and pointwise nonlinearities. Its intermediate states are not noise. They carry structure we can read, decompose, and — increasingly — edit.
Make that concrete before the theory starts. A model completes "Michael Jordan plays the sport of" with "basketball." A behavioral eval records one bit — correct — and stops. Mechanistic interpretability asks the questions the eval can't: where in the network that fact was stored, which component carried it to the output, and what happens to the answer if you reach in and overwrite that single activation. Everything below is the machinery for answering questions of exactly that shape — and for proving the answers are real rather than merely plausible. Keep that prompt in mind: it is the note's running example. GPT-2 small is not impressive — that is the point; it is small enough to poke, break, and put back — and we return to it, run for real, in the causal-interventions section.
The goal of MI is to do for a neural network what reverse-engineering does for a compiled binary: recover the algorithm the weights implement, stated in terms a human can check. Two objects organize the whole field. Features — what the network represents, the variables it computes over. Circuits — how its components read those features, transform them, and write new ones. Everything below is some way of finding one of these, or of proving that what you found is really there.
It helps to say what MI is not. It is not behavioral evaluation: a benchmark tells you what a model does, not how. And it is not post-hoc input attribution — saliency maps, SHAP, integrated gradients — which highlight which inputs mattered for a prediction without recovering the internal computation that turned those inputs into it. MI asks the harder question: what mechanism, inside the weights, produced this behavior — and can we intervene on it to prove the mechanism is causal rather than merely correlated?
The spine of this note is a single move, repeated: find structure in activation space, then verify it by intervention. Hold onto that. Reading is cheap and always finds something; the discipline is in the causal check.
The residual stream: a linear object you can decompose
Start with the architecture, because the architecture is what makes everything else possible. A decoder-only transformer is a stack of layers, each of which reads from and writes to a shared vector per token — the residual stream , where is the model dimension. (The same object that the first LLM note introduced as the thing attention mixes; here we treat it as the central character.) A layer's attention and MLP blocks each compute an update and add it back:
That plus sign is doing enormous work. Because every block adds rather than overwrites, the residual stream at the top of the network is literally a sum of the embedding plus every component's contribution along the way:
The residual stream is therefore best understood not as "the activations" but as a communication channel — a shared bus that early components write information onto and later components read off. Each component reads with a linear projection (its input weights) and writes with a linear map (its output weights). The picture that follows from this — and it is the foundational reframing of the field — is that a transformer is a large number of small, mostly-linear operations communicating through a common vector space, rather than a monolithic nonlinear function.
The immediate payoff is direct logit attribution (DLA). The model's output logits are an unembedding applied to the final stream,
and the final layer norm is, per token, just a rescale plus a learned affine map — close enough to linear that to first order we can push the unembedding through the sum above. Then the logit for a candidate token decomposes into one additive term per component:
This is the first concrete instrument: you can ask, for a given prediction, which head or MLP wrote the vector that pushed this token's logit up, by reading off each component's dot product with the token's unembedding direction. No retraining, no probing — it falls straight out of the additivity of the stream.
DLA is a first-order read, and it pays to know where it can lie. It attributes a logit to where a direction was written, but a later component can rotate, amplify, or partially erase that direction before the unembedding ever sees it. A head can look innocent because its contribution was overwritten downstream, or look decisive because it merely relayed a direction another component will finish. And the "push the unembedding through the sum" step leans on the final layer norm being approximately affine per token — locally useful, not exact. Treat DLA as a fast, honest sketch of an additive channel, not a full account of the nonlinear computation stacked on top of it.
The residual stream is not "linear" in the sense that the whole transformer is linear. The useful fact is narrower: components write additive updates into a shared vector space. That lets you decompose the writes and ask how each contributes to a logit direction — while remembering that the nonlinear computation stacked on top (softmax, MLP activations, layer norm) can still transform, amplify, or erase what was written.
The linear representation hypothesis
If the stream is the medium, what is the message? The dominant working hypothesis — supported by a decade of evidence from word embeddings onward — is the linear representation hypothesis: human-interpretable features are encoded as directions in activation space, and the intensity of a feature is (to a good approximation) the projection of the activation onto its direction.
Formally, a feature has a direction , and its activation on input is up to scale. The strong evidence for this is twofold.
Linear probes. Train a linear classifier on frozen activations to predict some concept — sentiment, part of speech, the truth value of a statement, the player to move in a board game. If a simple
recovers the concept with high accuracy, the concept is linearly decodable from the representation — it lives along a direction, namely . Probing is cheap and revealing, but it comes with a sharp caveat that motivates half of this note: a probe that reads a feature does not prove the model uses it. Decodability is correlational. The information might be present and ignored, or present as a by-product. To promote "the feature is there" to "the feature is used," you need to intervene.
Steering vectors. The cleanest intervention is to add the direction back and watch behavior change:
If injecting for "this text is formal," or "the topic is the Golden Gate Bridge," reliably bends the model's output that way — monotonically in — then is not just decodable, it is a causal handle on behavior. Activation steering is where the linear representation hypothesis stops being a statistical convenience and starts being an engineering primitive.
That monotonic bend is really a dose–response — nudge the activation along and behavior nudges, push harder and the effect grows in proportion — and it is what separates a causal handle from a probe artifact. The cheap control is to build a second direction the same way but from shuffled labels: if the real direction produces a clean dose–response and the shuffled one does not, you steered a feature rather than merely shoving a large vector into the stream.
A real dose-response on GPT-2 small. A sentiment direction — the positive-minus-negative mean at the best held-out SST-2 layer — is added to the residual stream on unseen prompts as we sweep α; the mean positive−negative logit gap climbs monotonically. A control direction built the same way from shuffled labels barely moves and even drifts the wrong way. So it isn't that any large vector moves sentiment; it's this specific, label-derived direction. Real experiment — scripts/compute_mi_steering.py.
Superposition: why features outnumber neurons
Here is the puzzle that breaks the naive picture. If features are directions, the tidy hypothesis would be that each neuron is a feature — one coordinate axis, one concept. Reality is messier: individual neurons are overwhelmingly polysemantic. A single MLP neuron fires for academic citations, and English dialogue, and a specific kind of HTTP header — concepts with nothing in common. Meanwhile the model clearly represents far more distinct features than it has neurons. How?
The answer is superposition: the network stores more features than dimensions by packing them as non-orthogonal directions and tolerating a little interference, exploiting the fact that features are sparse — only a few are active on any given input.
The geometry is real, and it is the most important math in the field. In you can place only mutually orthogonal vectors. But if you relax "orthogonal" to "almost orthogonal," the capacity explodes. The Johnson–Lindenstrauss lemma and its relatives say that the number of unit vectors you can fit with pairwise near-orthogonality
grows exponentially in the dimension:
A 4096-dimensional space has room for billions of directions that are all "90° give or take a few degrees" apart. So a layer can assign each of a huge number of features its own near-orthogonal direction. The price is crosstalk: when feature is active, it leaks a little signal onto the read-out of feature . Superposition is the bet that, because features fire sparsely, this interference rarely matters in practice.
That exponent is not a curiosity — it is the budget, and large models appear to exploit it heavily. It is the concrete reason that prying a single layer of a frontier model apart (with the next section's tool) surfaces not thousands of clean features but a vast number of them: a sparse autoencoder scaled to 34 million latents on one middle layer of Claude 3 Sonnet (Scaling Monosemanticity, 2024) pulled out a correspondingly huge, interpretable set. The geometry leaves room to hide that many in a few thousand dimensions — which is exactly why the inside looks like mush until you go looking for the directions.
Anthropic's toy model of superposition makes the trade-off concrete and reproducible. Take synthetic inputs that are sparse and nonnegative, squeeze them through a bottleneck with , and reconstruct:
Everything interesting lives in the Gram matrix . Its diagonal says how strongly feature is represented; its off-diagonal is the interference between features and . As you crank the sparsity of the inputs, the learned visibly reorganizes: at low sparsity the model represents only the top- features orthogonally and drops the rest; as sparsity rises it packs more features in, arranging their directions into strikingly regular structures — antipodal pairs, triangles, pentagons — that minimize worst-case interference. Superposition is not a bug or an artifact; it is the optimal code when features are sparse and dimensions are scarce.
The consequence for interpretability is severe. The neuron basis is the wrong basis. If features are stored in superposition across many neurons, then reading neurons one at a time will keep showing you polysemantic mush, no matter how hard you look. You need to recover the feature directions — the basis the model is actually computing in — which is not aligned with the coordinate axes.
A real trained run of the toy model above (m=5 features, d=2 bottleneck). Drag the sparsity slider: at low sparsity the model keeps only d features and represents them as orthogonal axes; raise it and watch the model cram in extra features, arranging their directions into a pentagon. The right panel is the Gram matrix WᵀW — diagonal is how strongly each feature is stored, off-diagonal is the interference it chose to tolerate. Every number is read off the trained weights (scripts/compute_superposition.py).
Sparse autoencoders: recovering the features
If features are directions in superposition, recovering them is a dictionary learning problem: find an overcomplete set of atoms such that any activation is a sparse nonnegative combination of them,
The dictionary is overcomplete ( can be 8×, 32×, or more times ) precisely because there are more features than dimensions. The tool that has dominated recent interpretability work is the sparse autoencoder (SAE), which learns exactly this dictionary with a single hidden layer:
The columns of the decoder are the candidate feature directions; the encoder is the learned detector for each. Training minimizes reconstruction error plus a sparsity penalty on the codes:
The term is the whole trick, and it is worth being precise about why it works. What we actually want is small — few active features — but is non-differentiable and combinatorial. The norm is its tightest convex surrogate: geometrically, the ball is a cross-polytope whose corners sit on the coordinate axes, so pushing a solution toward small pushes it toward the corners, i.e. toward sparse codes with most entries exactly zero. Minimize this loss over a large activation dataset and, empirically, many of the dictionary atoms come out substantially more monosemantic than the raw neurons: individual features that fire for one human-legible thing — a specific person, a syntactic construction, the concept of unsafe code, "the Golden Gate Bridge" — where the underlying neurons were hopelessly polysemantic. Not all atoms, and not perfectly; the failure modes below are the fine print.
There is no free lunch, and the failure modes are instructive. The penalty pushes on magnitudes, not just on the count, so it shrinks the activations it keeps — a systematic bias that newer variants (TopK, JumpReLU, gated SAEs) fix by decoupling which features fire from how strongly. Dictionaries also exhibit feature splitting (one coarse feature in a small SAE fractures into many fine-grained ones in a larger SAE) and dead features (atoms that never activate and waste capacity). And the choice of and is a genuine trade-off, not a setting with a right answer. There is also a subtler trap that no metric catches for you: an atom's top-activating examples can look like a crisp concept — a convincing one-line label almost writes itself — while the atom actually fires on a broader or subtly different set. A tidy label is a hypothesis about a feature, not proof of one; the honest check is whether clamping the feature moves behavior the way the label predicts.
The tooling here is moving fast, and 2025 brought a healthy reckoning. Standardized benchmarks (SAEBench) showed that the usual proxy metrics don't track downstream usefulness; a steering benchmark (AxBench) found simple baselines and plain prompting often beating SAEs outright; and transcoders — which reconstruct a component's output from its input rather than autoencoding its activations — are emerging as a serious alternative, especially for circuit tracing, and are what the 2025 attribution-graph work is built on. Treat the SAE as the current best tool for this job, not the last word on it.
That trade-off is the honest way to evaluate an SAE: there is no ground-truth feature set to score against, so you measure the Pareto frontier between fidelity and sparsity. Fidelity is how much of the model you preserve when you splice the reconstruction back in — usually reported as fraction of variance explained, or, more faithfully, the fraction of the model's cross-entropy loss recovered. Sparsity is the average — how many features fire per token. A good SAE is one that sits on the outer edge of that frontier: high loss-recovered at low . Push up and you move along the curve toward sparser, less faithful; down and toward denser, more faithful.
Real TopK SAEs of three dictionary widths, trained on GPT-2 small's residual stream (WikiText-2). The plot is the fidelity–sparsity frontier — fraction of cross-entropy loss recovered (splice the reconstruction back in) against average L0 — one curve per width. Then browse the learned features: the token contexts each fires on and the tokens it most promotes in the logits. Some atoms are crisply monosemantic where the raw neurons were polysemantic; some are not — which is the honest state of the tool. Real experiment — scripts/compute_sae_pareto.py.
Circuits: the QK and OV decomposition of attention
Features are half the story. The other half is the computation over them — the circuits. The cleanest worked example is attention, because a single head decomposes into two independent, low-rank objects that you can study separately. (The mechanics of the head itself — queries, keys, values, the KV-cache — are the subject of the attention-variants note; here we factor it for interpretability.)
A head computes a pattern and then moves information along it:
The key observation — from the "Mathematical Framework for Transformer Circuits" — is that the learnable behavior of a head is governed not by the four matrices separately, but by two products:
These two circuits answer cleanly separated questions. The QK circuit scores how much query position wants to attend to key position — the attention logit is the bilinear form — so entirely determines the attention pattern. The OV circuit determines what gets written to the destination when attention does fire: if position attends to with weight , the vector added to 's residual stream is . Where to read and what to write are independent — you can analyze the pattern without ever looking at the values, and vice versa.
Both circuits are low-rank (rank , typically 64 or 128), which is exactly why they are tractable to inspect: their effective behavior lives in a tiny subspace. And because the residual stream is a shared bus, the output of one head's OV circuit can become the input another head reads through its QK circuit a few layers later. This cross-layer interaction — composition, via virtual weights that chain of an early head into or of a later one — is how multi-step algorithms get built out of single-head primitives.
Induction heads: a circuit reverse-engineered end to end
The canonical success story is the induction head — one of the clearest end-to-end mechanistic results we have. The behavior is simple to state: given a sequence that contains ... [A][B] ... [A], predict [B] — copy what followed the last time this token appeared. It is implemented by a two-head circuit spanning two layers:
previous-token head  (layer ℓ):
    at each position, attend one step back and copy the
    previous token's identity into the current residual stream
    → now each position "knows" what preceded it

induction head  (layer ℓ+k):
    QK circuit: match the *current* token A against positions
                whose stored "previous token" is also A
                (prefix matching — find where A occurred before)
    OV circuit: copy the token sitting *after* that match (B)
                into the output → predict B
This is a complete, falsifiable account: a named pair of components, a specific QK matching rule, a specific OV copying rule, composed through the residual stream. It matters beyond the toy task because the formation of induction heads during training coincides with a sudden drop in loss and a jump in in-context ability (Olsson et al., 2022) — a rare case where a measurable capability is pinned to an identified mechanism appearing at an identifiable moment. Two caveats keep this honest: the causal evidence is strongest for the copying behavior in small, attention-only models, and the broader claim that induction heads explain in-context learning in large models with MLPs is suggestive and largely correlational, not a closed case.
There is a clean way to show those heads are load-bearing and not merely correlated with the behavior: ablate them. Score every head by how much of its attention lands on the induction stripe, knock out the top-scoring ones, and watch the in-context copying degrade — while knocking out an equal number of low-scoring heads barely dents it. An attention heatmap on its own is only a suggestive picture; when the metric that found the heads also predicts which ones, removed, break the behavior, the pattern has earned the word "circuit."
A real induction-head experiment on GPT-2 small. Left: the top head's attention pattern on a doubled random sequence — the bright off-diagonal stripe is the "look back to the previous occurrence" rule, drawn by the model itself. Right: an ablation — zeroing the four heads the stripe metric picked wrecks the in-context copying (second-copy loss 0.16 → 1.04), while zeroing four low-scoring heads barely moves it (→ 0.46). The metric that found the circuit predicts which heads are load-bearing. Real experiment — scripts/compute_mi_induction.py.
From correlation to mechanism: causal interventions
Everything so far can produce a story: this direction encodes formality, that head copies tokens, this feature means "Golden Gate Bridge." Stories are cheap, and a model with billions of parameters will furnish a plausible one for almost any hypothesis you bring. The discipline of MI is refusing to believe a story until you have intervened on the mechanism and watched the behavior move. A mechanism earns belief in stages — read the structure, check it against a control, then break or steer it and confirm behavior moves the way the story predicts: a pretty pattern is only a suspect, and the intervention that survives a control is what turns it into evidence. This is the difference between interpretability and pareidolia.
The workhorse is activation patching (causal tracing). You construct two inputs that differ in exactly the thing you care about: a clean run where the model does the behavior, and a corrupted run where it does not (often the same prompt with one entity swapped). You pick a metric — typically the logit difference between the correct token and a foil. Then you run the corrupted input but patch in the clean activation of one component , and measure how much of the clean behavior that single substitution restores:
means component alone carries the effect — patching it flips the corrupted run all the way back to clean behavior. means is irrelevant to this behavior. Sweeping over every (layer, token position) gives a heatmap that localizes where in the network, and at which token, the relevant information lives. This is how concrete computations get pinned down — where in a model a factual association is stored, or which heads carry a name to the correct slot in a sentence — narrowed from "somewhere in the weights" to specific layers and heads.
Two ways this bites in practice, and both produce confident nonsense. First, the whole result hinges on the clean/corrupt pair: if the two prompts differ in more than the one thing you meant to isolate, the heatmap localizes a mixture of effects and means little — a carelessly chosen corruption is the fastest route to a crisp, meaningless picture. Second, a beautiful heatmap can still be an artifact of the metric: a patch that merely lowers the foil's logit can look like it "restored" the correct answer even when it did not recover the computation you actually care about. A patching map is only ever as trustworthy as the contrast and the metric behind it — Heimersheim & Nanda's methodology guide catalogs exactly these traps.
Path patching sharpens this. Activation patching tells you a component matters; path patching tells you through which downstream path it matters, by patching only the contribution that flows along a specific edge of the computational graph (say, head 's output as read by head 's query) while leaving its other routes untouched. A circuit hypothesis is precisely a claim about which paths carry the effect, and causal scrubbing is the stress test: resample everything off the hypothesized circuit and check that behavior survives. If the model still works when you scramble everything your hypothesis says is irrelevant, the hypothesis has earned some trust; if it breaks, your story was missing something.
The catch is cost. Naive patching re-runs the model once per component — thousands of forward passes for a full sweep. Attribution patching approximates the entire map in two passes plus one backward pass with a first-order Taylor expansion:
The gradient says how sensitive the metric is to 's activation; the activation difference says how far patching would move it; their inner product estimates the effect. It is a linear approximation, so it is honest only where the function is locally linear — it degrades exactly where you might most want it, at saturated softmaxes and other sharp nonlinearities — but it makes whole-model attribution tractable, after which you verify the top candidates with exact patching.
A real causal trace on GPT-2 small. The prompt “Michael Jordan plays the sport of” → “ basketball”; the subject tokens are noised, then one clean activation at a time is restored and the recovered answer probability — the normalized indirect effect — is drawn as a heatmap over layers × token positions. Toggle the component: the early MLP at the subject token writes the stored fact, the residual stream carries it up, and attention moves it to the final token in the late layers. Every cell is a rerun of the model (scripts/compute_activation_patching.py).
That closes the running example, and the moral is deliberately narrow — it is the whole discipline in miniature. We did not prove where "basketball" knowledge lives in GPT-2 in general. We proved something cleaner and checkable: for this prompt contrast and this metric, those activations causally carry the answer — change the internal state and the answer moves. A story would have named a head and stopped there; the mechanism is the part that survived the intervention.
The logit lens: watching a prediction form across depth
One more instrument follows directly from the linearity of the residual stream and is worth its own paragraph because it is so cheap. The logit lens applies the final unembedding to an intermediate residual stream, asking "what would the model predict if it stopped thinking here?":
Tracking this distribution layer by layer shows predictions crystallizing with depth: early layers carry diffuse, often token-level guesses; the answer sharpens in the middle-to-late layers. The basic logit lens is biased, because intermediate layers do not live in quite the same basis the unembedding expects. The tuned lens (Belrose et al., 2023) corrects this by learning a small affine probe per layer to translate each layer into the final basis before unembedding:
with trained to match the model's final-layer distribution. The lens is a reminder that depth is temporal: a prediction is not computed all at once but refined, and you can watch the refinement happen.
One discipline note, because the logit lens is seductive: it is a reading, not a proof. Seeing the answer token climb to the top at layer 12 shows the answer is legible in the stream there — it does not show the model has finished computing it, or that later layers won't overturn it, or that the model is even using that representation downstream. It is a wonderful diagnostic and an easy one to over-read into a claim the picture doesn't support.
What MI can and cannot claim
It would be dishonest to present this as a solved program. The same tools that make MI powerful carry the seeds of its failure modes, and a careful practitioner keeps all of them in view.
-
Features may not exist cleanly. Superposition means the model's features need not be orthogonal, need not align with neurons, and need not even be cleanly linear. SAEs assume a sparse linear dictionary; that is a hypothesis about the model, baked into the method, not a fact read off it. Different SAEs — different widths, penalties, seeds — find different dictionaries, and there is no ground truth to declare a winner.
-
Plausibility is not faithfulness. A story that fits the observations is not a verified mechanism. The whole reason causal scrubbing and path patching exist is that the field has repeatedly caught interpretability illusions — accounts that looked compelling and turned out to describe a path the model does not actually use. Reading is hypothesis generation; only intervention is evidence.
-
It does not yet scale cleanly. The cleanest fully reverse-engineered circuits live in small models. On frontier models, SAEs now surface millions of features and coverage is improving fast, but a complete circuit-level account of a large model's behavior remains out of reach. Automated interpretability — using a strong model to label features and propose circuits — buys scale but trades human bias for model bias, and its labels themselves need validation.
-
The streetlight problem. We find the structure our methods are built to see — linear features, low-rank circuits, sparse codes. Mechanisms that are nonlinear, distributed in ways our dictionaries miss, or smeared across components in unanticipated ways are, almost by construction, the ones we are least equipped to notice.
Reading activations always finds a story. Mechanistic interpretability is the practice of not believing it until an intervention forces the behavior to move. Treat every probe as a hypothesis and every claim as causal-until-proven.
An aside: the same tools, other networks
The sharpest test of everything above is not another language model. It is whether the methods — SAEs, superposition, circuit tracing, steering — survive contact with transformers trained on data that looks nothing like text. If features and circuits are a fact about language, they should evaporate off-distribution. If they are a fact about the architecture and about learned representation, they should reappear. As of 2026, the early evidence points in that direction: the same toolbox is transferring to brain signals, speech, and proteins — warts included. It is fresh, mostly preprint work, so read it as promising cross-domain evidence rather than a settled result.
On EEG foundation models, TopK sparse autoencoders pull interpretable features out of three architecturally distinct clinical transformers (SleepFM, REVE, LaBraM), and a single hyperparameter recipe transfers across all three. The features ground to a clinical taxonomy — abnormality, age, sex, medication — and a spectral decoder even maps latent edits back to physiological frequency signatures. The failure modes transfer too: the study finds entanglement, where suppressing "age" corrupts "pathology" — the exact "features are not cleanly separable" caveat from the superposition section, now with clinical stakes (Lehn-Schiøler et al., 2026).
On speech, a sparse autoencoder trained on Whisper's encoder recovers monosemantic features that straddle linguistic and non-linguistic boundaries, and — the primitive from the steering-vectors section, intact — supports cross-lingual feature steering: nudge a direction and the behavior bends across languages (Pluth et al., 2026). Circuits cross over as well as features: on the protein language model ESM2, cross-layer transcoders — the same successor architecture the 2025 attribution-graph work introduced — trace circuits that compress the model to under 1% of its latent space while keeping most of its accuracy, and those circuits line up with real biological motifs (binding, signaling, stability) (Tsui et al., 2026).
That last result also changes what interpretability is for. In the LLM framing MI is mostly a microscope: read the mechanism, audit for trouble. On ESM2 it starts to double as a design tool — steering along a discovered circuit produces higher-fitness proteins, beating baseline methods in over 70% of cases. At its most optimistic, reading the model begins to surface hypotheses about the biology — sometimes actionable ones — though what you are reading is still the model's representation of a protein, not the protein itself. The through-line is that "features and circuits" was never really a fact about English; it looks more and more like a fact about what trained transformers are — which is why it is so striking to see the same small toolbox starting to work in rooms it was never built for.
Why it matters
The point of looking inside is not aesthetic. A model whose mechanisms you can read is a model you can audit and steer rather than only test from the outside.
For safety, this is the difference between only hoping a model is honest and being able to look — to search for the features and circuits that would implement deception or sandbagging, and to test candidate interventions on them. This is real, early progress, not a shipped capability: Anthropic has surfaced safety-relevant features (deception, sycophancy, bias) and shown they causally move behavior when clamped, but reliable, complete detection of a deceiving model from the inside is an open problem, not a solved lie detector. The promise is being able to audit from the inside — potentially on inputs your evaluations never thought to try — not a guarantee that you will catch what a capable model is hiding. For debugging, it reframes failures mechanistically: a hallucination becomes a question of which circuit fired when the evidence was absent and the model fell back on priors, and a sycophantic tilt becomes a feature you can locate rather than a vibe you can only describe. It even connects to training: much of what preference learning installs — dispositions, warmth, the tendency to agree — is, in the end, features and circuits that were strengthened, and MI is how you would go looking for them in the weights.
The black box may not be opaque by nature. It is high-dimensional computation with a surprisingly linear, inspectable skeleton: sparse features packed in superposition, read and written through low-rank circuits across an additive residual stream, refined layer by layer into a prediction. None of that is unknowable. It is, for now, mostly unmapped — which is a very different, and far more hopeful, thing. Mechanistic interpretability is the cartography.
References and further reading
Foundations. These are "old" only in the sense that they are bedrock — the load-bearing theory the whole field still cites daily.
- A Mathematical Framework for Transformer Circuits (Elhage et al., 2021) — the residual stream as a communication channel, the QK/OV decomposition, virtual weights, and composition.
- Toy Models of Superposition (Elhage et al., 2022) — sparse features, superposition, interference, and the polytope geometry the toy widget above reproduces.
- In-context Learning and Induction Heads (Olsson et al., 2022) — the induction-head mechanism, and the evidence — and its limits — linking it to in-context learning.
- Eliciting Latent Predictions from Transformers with the Tuned Lens (Belrose et al., 2023) — the tuned lens, and why the raw logit lens is biased.
- Scaling Monosemanticity (Templeton et al., 2024) — SAEs scaled to Claude 3 Sonnet: the 34-million-latent dictionary, safety-relevant features, and the authors' own stated limitations.
- How to use and interpret activation patching (Heimersheim & Nanda, 2024) — patching methodology, the choice of metric, and the pitfalls that turn a clean heatmap into a wrong conclusion.
Where the field is now (2025–2026). The frontier has moved fast: better tools, a healthy reckoning with the limits of the old ones, and the whole toolbox crossing into non-language domains.
- Circuit Tracing / On the Biology of a Large Language Model (Anthropic, 2025) — attribution graphs and cross-layer transcoders: end-to-end circuits traced in a production model, well beyond classic head-level analysis.
- SAEBench: A Comprehensive Benchmark for Sparse Autoencoders (Karvonen et al., 2025) — a real benchmark, built after finding that the usual proxy metrics don't track downstream usefulness.
- Transcoders Beat Sparse Autoencoders for Interpretability (Paulo, Shabalin & Belrose, 2025) — transcoders (reconstruct a component's output from its input) found more interpretable than plain SAEs on the same model, especially for circuit tracing.
- AxBench: Even Simple Baselines Outperform Sparse Autoencoders (Wu et al., 2025) — a sobering steering benchmark where plain prompting and simple baselines beat SAEs, sharpening what SAEs are and aren't for.
- Mechanistic Interpretability of EEG Foundation Models via Sparse Autoencoders (Lehn-Schiøler et al., 2026) — the SAE recipe carried to clinical brain-signal transformers: clinical-taxonomy features, cross-architecture transfer, and the entanglement failure mode.
- Mechanistic Interpretability of ASR Models using Sparse Autoencoders (Pluth et al., 2026) — SAEs and cross-lingual feature steering on Whisper's encoder.
- Protein Circuit Tracing via Cross-layer Transcoders (Tsui et al., 2026) — circuits in the protein model ESM2 that map to biological motifs, with steering along them used for protein design.