Chapter 3 of 4
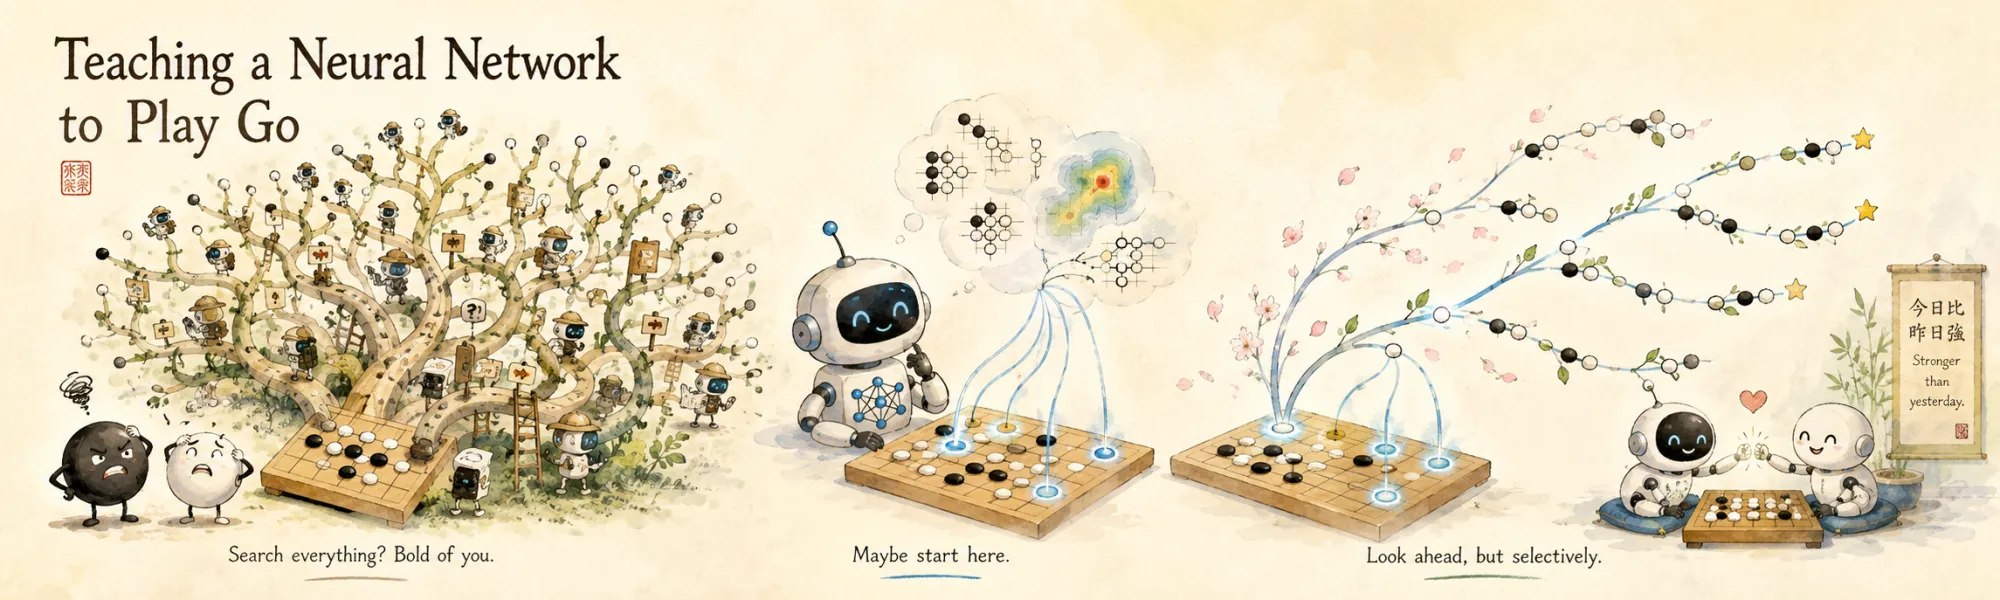
Teaching a Neural Network to Play Go
Created Aug 9, 2026
In 2016, AlphaGo defeated Lee Sedol, one of the strongest Go players in the world. The result was remarkable not simply because a computer had become good at a board game — computers had already surpassed humans at plenty of those. Go was interesting because the strategy that had worked everywhere else, brute-force search, was hopeless here. A chess position offers a few dozen reasonable moves; a Go position offers hundreds, and a game runs for hundreds of moves. Enumerating the game tree stops being an option almost immediately.
But tree size is only half the story, and the less interesting half — chess engines faced an enormous tree too, and beat it. The deeper problem is that chess has a cheap static evaluation: count material, add a few positional bonuses, and any leaf deep in the tree gets a usable score. Go has nothing of the kind. The worth of a stone depends on whether its group ends up alive or dead, and that question may only resolve fifty moves later. Minimax without an evaluation function is blind — you can search as deep as you like and still not know what you are looking at. This is why Go didn't fall to faster hardware. It waited for a different idea: if nobody can write the evaluation function, perhaps it can be learned.
AlphaGo's answer was not to abandon search but to make it selective. Neural networks learned which moves looked promising and which positions looked good, and tree search spent its computation only on the parts of the tree that seemed worth the trouble. That combination is more interesting than the historical result, because the two halves are good at genuinely different things. A network does something that resembles intuition — this move looks promising — while search does something else entirely: let's find out what happens if we actually follow this possibility.
This note builds a very small version of that idea and asks, at each step, why the next piece is needed at all. We are obviously not reproducing AlphaGo; we're shrinking the world instead. Go on a 5×5 board, a small convolutional network taught to evaluate moves and positions, and then tree search wrapped around it. The questions worth answering along the way are concrete: can a small network learn anything useful about Go positions, what does a policy network actually learn, what is different about a value network, how much stronger does the same network become once it is allowed to search, what exactly does the network contribute to that search — and finally, can the whole system improve by playing against itself?
Why 5×5: small enough to build, small enough to be solved
A 5×5 board is small enough that every part can be written from scratch, trained on ordinary hardware, and actually watched. What makes that size right is that neural-guided search emerges here as the answer to a problem the reader has already run into, at the moment they run into it.
It is worth being straight about the trade, because it runs the other way for playing than it does for experimenting. 5×5 is not a good game. Measured on our own engine, the average winning margin is 23.4 points out of 25 — the winner takes essentially the whole board, so games are routs rather than territorial arguments, and with perfect play Black simply takes all of it. Anyone who wants to play Go wants 7×7 at least, where corners, territory and life-and-death at a distance become real subjects.
What 5×5 offers instead is the thing no larger board can: it is solved. Exhaustive search (van der Werf, van den Herik and Uiterwijk, Solving Go on Small Boards, ICGA Journal, 2003) established the game-theoretic value of the opening — with perfect play from the central point Black takes the entire board, a 25-point win at zero komi — so every claim in this note can be checked against a known answer rather than against another program's opinion. Add to that games of about forty moves and a pipeline that runs in minutes, and you get a board where a result can be measured, doubted and re-measured rather than taken on trust. That is the right trade for a note about how the machinery works — and the wrong one for an evening's game.
That result comes attached to a specific rule set. A game-theoretic value is a property of a game, and changing the komi, the scoring convention, or the repetition rule changes the game. Our own choices below — positional superko, area scoring, and a komi we pick ourselves — are close to the solved setting but not automatically identical to it, and at nonzero komi the solved value is simply a different number. So the published solution is usable as ground truth only where our rules genuinely coincide with it; treated carelessly it turns the note's strongest claim into its weakest. The clean way to have both is to keep one configuration that matches the solved setting exactly, for verification, and vary komi elsewhere if we want a more balanced game to train on.
With that caveat honoured, we get something rare: a known optimum to check the finished system against. When we reach self-play we won't merely be able to say that generation 40 beats generation 0; we'll be able to ask whether it is converging toward provably optimal play. The first question, meanwhile, is deliberately simple: how can a neural network look at a Go board and decide where to move? Everything else unrolls from there.
The rules
Everything below depends on games that genuinely end and get scored, so the rule set has to be pinned down before any network appears. Fortunately it's short. Players alternate placing stones on intersections; the empty points adjacent to a connected group are its liberties, and a group left with zero liberties is captured and removed. Suicide — placing a stone so that your own group ends with no liberties — is illegal, unless the move captures first and thereby creates liberties.
Ko is the rule that stops infinite repetition: without it, two single-stone captures could undo each other forever. On a small board the cleanest choice is positional superko — no board position from earlier in the game may be recreated at all. Fixing this explicitly rather than discovering it later also answers the "how do we represent ko?" question that comes up in the next section: with full superko, the legality check needs the game's position history, not just the current board.
The game ends after two consecutive passes, and we score by area — stones on the board plus surrounded empty territory — which is by some distance the easiest scheme to implement correctly. Komi, White's compensation for moving second, matters enormously at this size, where the first-move advantage is overwhelming. Whatever value we choose has to be held fixed across every experiment for results to stay comparable. Komi is part of the game, not a tuning knob: the solved 5×5 result quoted above holds at zero komi, so that is the setting to use whenever we want to compare against it. Of all the code in this project, the scoring and game-end logic is the most fragile, and it deserves a test suite before a single tensor is allocated.
These rules already determine a great deal. A thousand games between two random players that respect their own eyes run 46 moves on average and never end early; the final board carries 20.7 stones out of 25, which is exactly what makes area scoring meaningful without dead-stone detection. Black wins 52% — near even. And the margin is almost always near-maximal: 23.4 points out of 25. On a board this small the winner takes essentially the whole board, which is why the value target throughout this note is win/loss rather than score. The margin would carry almost no extra information.
Two of the constraints the agents work under are not rules at all, and the distinction matters more than it looks. Every agent in this note searches a restricted action set: it will not fill one of its own eyes, and it will not pass while any other move remains. Both restrictions are standard, both make search enormously cheaper, and both are heuristics rather than laws. Filling your own eye is perfectly legal Go, and so is passing at any time — in seki and in zugzwang-like positions, passing can even be correct.
That has a consequence to keep for the rest of the note. The published solution of 5×5 Go is a statement about Go, and our agents play a variant of it. Where the two agree, that is evidence the restriction costs nothing here; it is not a proof, and no result below is presented as one. Where an exact value is quoted it comes either from the rules directly — as the pair in the next section does — or from a search over the same restricted set, and it is labelled as such.
Passing needs one more rule, because getting it wrong poisons everything downstream. Under area scoring a stone placed inside your own territory still counts as your area, so playing on is never worse than passing while a move that doesn't fill your own eye exists. Passing early isn't a strategic option to weigh — it's a mistake. The first version of this project let search consider passing at every turn, and the result was immediate: the teacher put about 20% of its visit mass on pass, some games ended after 8 moves, and the final boards were far emptier than they should be, so the scoring counted large neutral regions as somebody's territory. Restricting agents to pass only when nothing else remains fixed it — pass mass fell to 9%, the shortest game grew from 8 moves to 23. The pass pathology the note discusses much later, in the self-play section, arrived here first, before a single network existed.
Experiment 0: a hand-written evaluation function, and what it cannot see
Go resisted computers because a decent static evaluation is hard to write. That is testable on our own board, so before any network exists we write the naive evaluator and hold it against the truth.
The obvious features are the ones anyone would reach for: stones captured so far, total liberties of each player's groups, and some territory proxy such as empty points closer to one player's stones than the other's. Combine them with hand-tuned weights, wrap the result in shallow minimax or a small MCTS, and you have a complete non-neural Go player — the same shape of program that a competent engineer would write for chess and get something respectable.
What we're looking for is not that it plays badly — a weak player is unremarkable. It's how it goes wrong. And on a board this small the question can be settled rather than argued, because the sharpest cases need no search at all: sometimes the rules alone decide a position, and then there is nothing left to have an opinion about. (Sparse positions can also be searched exhaustively, but only over the agents' restricted action set — with every legal move available an eye-fill hands back a captured group and reopens the board, and the search stops terminating. Those values are quoted as what they are.)
Here is the pair that settles it, and it needs no solver at all — only the rules. Two positions differing by a single stone:
| Position | Hand-written evaluation | The truth |
|---|---|---|
| Black's group has two eyes | +25.70 for Black | White has no legal move at all: the group can never be captured |
| Black's group has one eye | +25.35 for Black | White plays the eye and captures all 24 stones |
The evaluator separates a won game from a catastrophe by 0.35 points — noise, on a scale where the whole board is worth 25. Its own score for White then swings by +75.75 the instant that capture lands. Nothing in the feature set is wrong, exactly; stones, liberties and a distance-based territory estimate are the right instincts, and they are what works in chess. They simply cannot express life and death, and life and death is what a Go position is about. One eye or two is the entire difference between those two boards, and no amount of counting liberties will see it.
The same lesson arrives from a second direction, and this one needs no hand-written features at all. 5×5 Go is solved: the centre point wins by 25 at komi 0. Ask classical MCTS — search with random rollouts and no learned evaluation — which opening it prefers:
| Simulations | Chose the centre | Rank it gave the centre (4 seeds) | Its value for the empty board |
|---|---|---|---|
| 200 | 0 of 4 | 20, 19, 22, 5 | +0.07 |
| 2 000 | 0 of 4 | 10, 19, 10, 8 | +0.15 |
| 10 000 | 0 of 4 | 3, 18, 15, 16 | +0.14 |
The truth is +1.0. Not one of the twelve runs picked the centre, and fifty times more computation barely moves the estimate. This is not a search that is short of thinking time in the ordinary sense — it is one whose leaf estimates answer a different question. With random rollouts each leaf is scored by , the value under random play, and under random play the empty board really is close to even (Black wins 52% of playouts).
Be careful with how strong a claim that supports. UCT-style search is consistent: as the budget grows the tree deepens, the rollout policy is consulted further and further from the root, and in the limit the probability of choosing a wrong move at the root goes to zero. So it is not true that no amount of computation could ever fix this. What is true — and what matters for anyone actually building this — is that at the budgets available here, fifty times more simulations bought essentially nothing, because the leaf estimator is wrong in a way that extra simulations correct only very slowly. Replacing the estimator is the cheap fix; out-computing it is not. That is the gap the value network is introduced to close.
Finally, the evaluator earns its keep as a baseline. Over 20 games with colours alternated it beats a random player 20–0 and the eye-respecting rollout player 20–0, and loses 5–15 to 100-simulation MCTS. So the hand-written engine sits above random play and below a hundred simulations of search — which is the bar every network in this note has to clear. "Beats a random player" would have proved nothing.
Representing a position: from one matrix to three channels
The simplest possible encoding is a single 5×5 matrix with one number per intersection:
 0 = empty
 1 = black
-1 = white
It's a reasonable starting point, and it immediately raises the questions that make representation interesting. Is one channel enough? How does the network learn whose turn it is, given that the same board means opposite things depending on who moves? Do we need previous positions? How is ko represented, if legality depends on history? Should legal moves be encoded explicitly, or should the network work them out?
The standard answer is to stop cramming everything into one number per point and stack planes instead, each one a clean binary indicator:
channel 0: black stones
channel 1: white stones
channel 2: current player
The two-plane split for stones removes an awkward burden from the first convolution, which no longer has to learn that 1 and -1 are opposites rather than magnitudes. The current-player plane — all ones or all zeros — is the cheapest way to tell a convolutional network something global about a position. AlphaGo used a much richer stack, including several previous positions; on 5×5 the three planes above are a sensible default, and the difference is itself measurable — one-channel board vs multi-channel board becomes one of the controls in Experiment 1.
The policy network: a distribution over moves
The most understandable learning task on this data is to map a board to a distribution over the moves available in it:
On 5×5 that's 25 intersections plus pass, so 26 outputs, and the network's answer for a given position looks like a ranked list of candidates:
A1   0.01
A2   0.03
...
C3   0.31
...
pass 0.001
This is the policy network, and it can start about as small as a network can: a couple of convolutional layers with ReLU, then a linear layer producing 26 logits, then a softmax.
board
  ↓
Conv → ReLU
  ↓
Conv → ReLU
  ↓
Linear
  ↓
26 logits
  ↓
softmax
The architecture choice is worth pausing on, because "why a CNN rather than an MLP?" has a particularly concrete answer in Go. Players literally think in local patterns, and the recurring ones are named: the tiger's mouth, the ladder, the empty triangle. A convolutional filter is a shape detector sliding across the board, firing wherever its pattern occurs — which is locality and weight sharing, the two standard justifications, in the form the game itself uses. The CNN's inductive bias matches how the board is actually read by the people who play it.
One implementation detail belongs here rather than later. At play time we mask illegal moves before the softmax, so the agent physically cannot play into a filled point or violate superko. But when evaluating the raw network we deliberately leave the mask off, because the probability mass the unmasked distribution puts on illegal points tells us something we want to know: whether the network picked up the rules on its own from watching legal games. That measurement is the "illegal move rate" in the experiment below, and it only means anything if the mask is off while we take it.
Where the training data comes from
Supervised learning needs pairs of the form board → move worth imitating, and 5×5 Go has no corpus of human games waiting to be downloaded. So we manufacture one, which means choosing a teacher.
The obvious candidates are worse than they look. A random player produces data that is almost pure noise. The hand-written evaluator from Experiment 0 is better, but we have just spent a section watching it misjudge exactly the positions that matter. An external engine like GNU Go would be stronger than either, and it is a reasonable choice, but it brings an installation, a protocol to speak, and — more importantly — its own rule set, which we would have to reconcile with the komi and superko conventions we fixed earlier.
The teacher worth using is one we are already committed to writing: classical MCTS with random rollouts. No network, no evaluation function, uniform prior, a few hundred simulations per move. It is exactly the uniform prior + rollout configuration from the ablation grid at the end of the note, so it costs no extra code; it has no external dependencies and no rule-set mismatch, since it plays by our engine's rules by construction; it transfers to 7×7 unchanged; and despite knowing nothing about Go beyond the rules, it plays a decent game — search of this kind is what carried computer Go from hopeless to strong-amateur before neural networks arrived. A strong modern engine like KataGo would fill a different role — an external referee, so the strength numbers aren't entirely self-referential — but nothing here ends up needing one: where an outside answer is called for, this board has something better, the published solution itself.
This choice has a consequence that only becomes visible later. Classical MCTS is precisely what the self-play loop reduces to at generation 0 — before any network exists, the prior is uniform and the leaves have to be evaluated by rollout. So the supervised phase isn't scaffolding to be discarded once the real method arrives; it is the first turn of the crank we keep turning for the rest of the note. What we do here — distil the result of search into a single forward pass — is what we will keep doing, with a search that gets better each round because it is built from the student it is teaching.
That framing also sharpens what goes wrong. Training a network to reproduce a fixed teacher's moves means the target it chases is that teacher. It isn't impossible to end up slightly stronger — a network averaging over many noisy decisions can denoise them, and generalization sometimes lands on a better move than the demonstrated one — but pure imitation provides no systematic signal for becoming better than the teacher, because nothing in the loss ever says "that move was worse than one you could have found." The ceiling isn't imitation as such; it's imitation of something fixed. Everything after this section is about removing that word — but first the network has to work at all.
A note on why we bother with a supervised phase at all: AlphaZero skips it, starting from random weights and learning entirely by self-play. We keep it because it makes the ceiling something the reader watches happen rather than takes on faith — and because having a strong network in hand lets us ask a sharper question later: the self-play section runs the loop from that network and from nothing, and only one of the two answers what the loop is for.
Experiment 1: Can a CNN learn Go from examples?
Train the CNN on the teacher's games and measure it four ways: how often it picks the teacher's move, how much probability it puts on illegal ones, and whether it beats a random player and the hand-written engine from Experiment 0. The last is the only one that decides anything — beating a random player proves nothing, while beating the naive evaluator means the learned representation captured something the hand-written features could not. Alongside the CNN run the controls that isolate each design choice: no normalisation, no symmetry augmentation, a single input plane, and an MLP with no convolutions at all.
The small board offers one free multiplier. Every position has eight symmetric variants — four rotations times two reflections — and a correct move maps to a correct move under the same transformation. Applying a random one of the eight to each batch costs nothing and shows the network essentially the whole set over a dozen epochs. (Materialising all eight copies of the dataset instead multiplies every epoch by eight for no extra information per step — a mistake worth not making, since it turns a two-minute run into an hour.)
Here is what came out, on 20 000 teacher games — 861 000 positions, split by game so no position leaks between train and validation:
| Variant | Parameters | Policy CE (median) | Spread over 5 seeds | Illegal mass | vs MCTS-100 |
|---|---|---|---|---|---|
| CNN | 79 282 | 1.738 | 1.731 – 1.740 | 0.007 | 57/60 |
| CNN, no normalisation | 78 898 | 1.754 | 1.747 – 3.220 | 0.009 | 55/60 |
| CNN, no augmentation | 79 282 | 1.742 | 1.737 – 1.742 | 0.009 | 54/60 |
| CNN, one input plane | 78 130 | 1.869 | 1.865 – 3.221 | 0.058 | 54/60 |
| MLP | 108 443 | 1.855 | 1.855 – 1.857 | 0.043 | 55/60 |
Cross-entropy needs two anchors to mean anything. Guessing uniformly over the 26 moves costs nats. The teacher's own distributions are soft rather than one-hot, so even a perfect model cannot go below their entropy, which is 1.29 here. The CNN lands at 1.74 — well into the useful range, and better than the MLP's 1.86 despite having a third fewer parameters. The convolutional prior earns its place, but not overwhelmingly: this is a 5×5 board, where the "same shape anywhere" argument has little room to pay off.
Two rows deserve more attention than the medians. The spread column is the real finding. Look at the two variants without normalisation: their best seeds are fine, and one seed in five lands at 3.22 — essentially uniform guessing. It is not a slow divergence that a learning-rate schedule or gradient clipping would catch; both were on, and neither helped. It is a bad initialisation basin the network never leaves. Adding GroupNorm removes it entirely — six seeds, zero failures, spread in the third decimal. This is the practical reason normalisation sits in every block of AlphaZero's architecture, and it is also a methodological warning: with a single seed, that 3.22 is indistinguishable from a discovery about convolutions, and it cost this project several wrong architectural conclusions before five seeds replaced one.
One input plane cripples the value head specifically. Its policy is merely worse; its ability to call the winner collapses to 0.684 against 0.889 for the three-plane version. That is exactly what the representation section predicted: with a single ±1 matrix the network cannot tell whose turn it is, and "who is winning" is meaningless without that. It also puts eight times more probability on illegal moves.
The metric that matters least is the one that looks most like a score. Every variant beats the random player 60 of 60 and the hand-written evaluator 60 of 60; those opponents stopped discriminating long ago. The interesting column is the last one — and there the plain CNN, playing with no search at all, beats 100-simulation MCTS 57 games out of 60. A single forward pass reproduces what the teacher needed a hundred simulations to find.
That last number also disposes of the natural expectation: that the policy network plays sensibly and then blunders horribly. It does not. It plays well. What it cannot do is something else entirely, and we come back to it once the second head exists.
How good can a student get? As good as its teacher, roughly
Earlier we chose a teacher and argued that imitation cannot systematically exceed one. That is testable directly: hold everything fixed and vary only the teacher's search budget. Four students, the same architecture, the same 20 000 games, the same training loop, three seeds each.
| Teacher | Student's policy CE | Student's top-1 | vs its own teacher | vs MCTS-200 | vs the hand-written engine |
|---|---|---|---|---|---|
| MCTS-2 | 0.485 | 0.894 | 30/60 | 1/60 | 0/60 |
| MCTS-10 | 1.378 | 0.489 | 15/60 | 0/60 | 0/60 |
| MCTS-50 | 1.758 | 0.384 | 26/60 | 11/60 | 30/60 |
| MCTS-200 | 1.738 | 0.375 | 54/60 | 54/60 | 60/60 |
Read the second and third columns together, because they point in opposite directions. Top-1 agreement falls monotonically as the teacher gets stronger — 0.894 down to 0.375 — while playing strength rises from hopeless to dominant. The student that predicts its teacher best is the worst player in the table. A 2-simulation teacher is nearly deterministic and its visit distribution is sharply peaked, so copying it is easy; a 200-simulation teacher spreads its visits over genuinely considered alternatives, and matching that is hard. If you had tuned this project on move-prediction accuracy you would have chosen the weakest agent available, with the metric improving all the way down.
The fourth column is the one that revises the claim above. Three of the four students sit at or below their teacher, as the ceiling argument predicts. The fourth beats the teacher it copied, 54 games out of 60. That is not a contradiction of the argument, it is the caveat inside it made real: MCTS with random rollouts is noisy, and a network trained on twenty thousand of its games learns the average of its judgments rather than any one of them. Averaging away a noisy teacher's mistakes is exactly the kind of improvement imitation can deliver.
What imitation still cannot deliver is a second step. The student has extracted what its teacher had; nothing in the loss can push it further, because there is no signal in the data about moves the teacher never played well. To keep going, the target itself has to improve — and everything from here to the self-play section is machinery for making that possible.
The value network: how good is this position?
The policy network answers where should I move? The second network answers a question that sounds similar and turns out to be structurally different: who is winning from here? Let the game's outcome from the current player's perspective be — loss or win. The value network estimates its expectation:
That superscript is not decoration, and it is the single most important thing to understand about this network. There is no such object as "the value of a position" in the abstract — only the value under some way of playing on from it. Go is deterministic and perfect-information, so a position already has a game-theoretic value under optimal play; but our network never sees optimal play. It sees games generated by whatever policy produced its training data, and what it learns is the expected outcome under that policy. Train on games from our rollout-MCTS teacher and you get a network that predicts how a few hundred random playouts tend to resolve such positions — a useful thing to know, but not the same thing as who should win. This has a consequence we'll hit later: once self-play starts changing the policy every generation, the meaning of the value target changes with it, and the network is chasing a moving target by design.
So the network takes a board and returns a single number in , where is a certain loss, a certain win, and a position it considers balanced. If probabilities feel more natural, the same quantity rescales to one directly: . The convention with a tanh output head is what AlphaZero uses, and it earns its keep later — it makes the backup step in tree search symmetric between the two players, since flipping perspective is just a sign change.
What makes this the harder of the two networks is that the target is much further from the input. A good move is often a local matter, visible in a 3×3 neighbourhood; who wins is a global property of the whole board that may hinge on a fight not yet resolved. The two stay conceptually separate here because they answer different questions and fail in different ways; the implementation can and eventually should merge them into a single network with two heads on a shared trunk, which is what AlphaZero does and what the self-play loop below assumes. Nothing in the exposition changes when they merge — only the parameter count.
| Network | Question it answers | Used in search as |
|---|---|---|
| Policy | Where should I move? | The prior — which branches get explored |
| Value | How good is this position? | The leaf estimate — what an unfinished line is worth |
Experiment 2: Can a network recognise who is winning?
The training data for this one is free. Take the games already played, and note that for every position in them the final winner is known — so every position in the archive is a labelled example of position → eventual result, with no annotation effort at all.
The interesting question isn't the aggregate accuracy but where it comes from: at which point in a game does the value head start to genuinely know the winner? Bucketed by move number, over 86 000 held-out positions:
| Move | Accuracy | Mean |
|---|---|---|
| 0–5 | 0.647 | 0.28 |
| 5–10 | 0.735 | 0.49 |
| 10–15 | 0.823 | 0.67 |
| 15–20 | 0.900 | 0.81 |
| 20–25 | 0.958 | 0.90 |
| 25–30 | 0.985 | 0.96 |
| 30+ | 0.998 | 1.00 |
Two columns, and the second is the one that makes the first trustworthy. Accuracy climbs from a shaky 0.65 to essentially perfect — but so does the network's confidence: early on it outputs values near zero, and by move 30 it is committing to ±1. It is not guessing early and getting lucky late; it is hedging early and committing late, which is what a calibrated estimate looks like.
Read that curve carefully, though, because it is easy to over-interpret. The early uncertainty is not the game being undecided — in a deterministic perfect-information game the outcome under perfect play is fixed from the first move. It is that many continuations remain open, and the result under the policy that generated these games is only weakly determined by what is on the board. The network is being an honest estimator of , and genuinely is near a coin flip on an empty 5×5 board — the random-rollout measurement earlier put Black at 52%.
The one-plane control makes the same point from the other direction, and its curve is the strangest object in this note:
| Move | Three planes | One plane |
|---|---|---|
| 0–5 | 0.647 | 0.644 |
| 10–15 | 0.823 | 0.776 |
| 20–25 | 0.958 | 0.623 |
| 30+ | 0.998 | 0.657 |
It tracks the real network for the first ten moves and then gets worse as the game progresses. That inversion is exactly what the missing plane predicts. Early on, who is ahead is mostly readable from the stones themselves, and turn order barely matters. Late in the game, the same arrangement of stones can be a win or a loss depending entirely on who moves next — and a network fed a single ±1 matrix has no way to know. It ends up least able to judge the positions that are objectively easiest to judge. Its confidence falls with its accuracy too, from 0.56 down to 0.32: it knows that it doesn't know.
Playing with the policy alone: everything in one forward pass
We now have , so the simplest possible agent is available: at every turn take the most probable legal move, play it, repeat. No search, no lookahead — every decision compressed into one evaluation of a 79 000-parameter network.
It is worth being clear about how well that works, because the obvious expectation is wrong. This agent beats the hand-written engine 60 games out of 60, and beats 100-simulation MCTS 57 out of 60. It puts 0.7% of its probability on illegal moves despite never having been shown the rules — only legal games. It is not a fumbling beginner that occasionally blunders; on this board it is the strongest thing we have built so far.
So the interesting question is not why it plays badly. It is what a single forward pass still cannot do, however good it gets.
The tempting explanation is that a policy "can't plan." It isn't true. In principle a sufficiently good policy encodes the consequences of future play directly in its weights — the optimal policy is a function of the current state alone and still plays perfectly, because everything worth knowing about the future is baked into what it outputs. Looking ahead at inference time is not a requirement for playing well.
The real problem is more specific, and more interesting. Our policy has no explicit planning mechanism and no reason to have acquired an implicit one: it was trained to imitate a limited teacher, and every decision it makes has to be compressed into a single forward pass of a small CNN. Whatever long-horizon reasoning a position demands must already be stored in the weights, fixed at training time, identical for every position it will ever see. A network cannot spend more of itself on a hard position than on an easy one. Search offers something categorically different from more weights or more training — computation performed for this particular position, at the moment the move is needed. That distinction, stored computation versus test-time computation, is what Experiment 3 measures, and it is why an agent that already beats everything in sight still has room to improve without a single weight changing. This is also the point where search stops being a topic in a syllabus and becomes a fix for a problem we just watched happen.
Looking ahead: the tree that cannot be enumerated
Suppose the policy network offers its usual ranked candidates — A at 40%, B at 30%, C at 10%, and a long tail below that. Instead of immediately committing to A, we can spend some computation checking it: if I play A, the opponent presumably answers X, and then my best continuation is... Each answer branches into further answers, and what we are building is a tree.
The trouble is how fast that tree grows. On 5×5, a position past the opening offers roughly 20 legal moves, so looking two plies ahead means positions, which is nothing. Six plies means , which is no longer nothing, and on a full 19×19 board with 200-plus legal moves the same arithmetic becomes absurd within a handful of plies. Exhaustive search is out, and not by a narrow margin.
So the tree has to be explored selectively — some branches deeply, most of them not at all. Which immediately raises the question of who decides. Something has to rank the branches before they are explored, and that something has to be cheap, because it will be consulted thousands of times per move. Plenty of things could fill the role: hand-written heuristics, a classical evaluation function, domain-specific pruning rules — and strong pre-AlphaGo Go programs used exactly those. But we happen to have already built something that does it, a network that outputs a distribution over moves. Neural-guided search arrives here not as a term to be defined but as the natural answer available to us, because the previous section left us holding a learned move prior.
Neural-guided search: the prior decides where computation goes
The division of labour: the policy network proposes which branches to look at. The value network judges: this is how good the position at the end of an explored line is, without playing it out. The search algorithm allocates: given everything explored so far, this is the branch to explore next. Sketched crudely, search concentrates its effort where the policy's prior is high and its own results have been encouraging:
              position
             /   |    \
           A     B     C
        .40     .30   .05
         |       |
       search   search
The policy is used as a prior — it doesn't decide the move, it decides where the computation goes — and the value network removes the need to play any branch out to the end of the game. The interesting claim in this design is not that either half is powerful on its own, but that the prior's real job is deciding what is worth computing about. Search without a prior can spend a large fraction of its budget on moves no competent player would consider — it still works, as the classical Go programs proved, but it pays for that breadth in simulations; a prior without search never checks whether its instinct survives contact with the opponent's reply. Strong human players work the same way — a glance narrows the board to two or three candidates, and only those get read out — but the mechanism stands on its own without the analogy. That is the entry point to Monte Carlo Tree Search.
MCTS: four phases and a five-line loop
Written from scratch, one simulation is four phases: selection, walking down the tree already built by following the most promising child at each node; expansion, adding one new position at the frontier; evaluation, scoring that new position; and backup, propagating the result back up the path so that every node on it updates its statistics. In code, the whole loop is small enough to fit in five lines:
for _ in range(num_simulations):
    node = select(root)
    child = expand(node)
    value = value_network(child.position)
    backup(child, value)
One line of that loop hides a real decision. Classical MCTS — the pre-AlphaGo kind that made computer Go respectable in the late 2000s — evaluated a leaf by playing the position out to the end with random moves and recording who won. Why is a learned value function better? The usual answer is bias versus variance: a rollout is unbiased and noisy, a network is biased and stable, and on a budget of fifty simulations noise is what kills you. That's true as far as it goes, but it quietly skips the more interesting half.
A random rollout is an unbiased estimate of — the value of the position under random play. It is not an unbiased estimate of the position's true value, and no number of samples of that leaf will make it one. Search as a whole does eventually escape this, since a deeper tree pushes the rollouts further from the root, but escaping it that way is paid for in simulations rather than in a better estimator.
A million perfect samples of how random players finish a delicate life-and-death fight tell you what random players do with it, which is close to nothing about who should win. Settling the question by rollout is like settling a chess argument by letting two drunks finish the game: the sample is honest, but it is a sample of the wrong quantity. So the choice between rollouts and a learned value head is not only about how noisy the estimate is — it's about which value function is being estimated at all, and a network trained on real games is at least aiming at the right one. The ablation at the end of the note measures what that swap is worth.
The other line worth unpacking is select(), which is where UCB and its AlphaZero variant PUCT eventually go. The formula deserves a plain-language version before any symbols show up. Choosing which child to descend into is a tug-of-war between two quantities: this move has been winning whenever I tried it — the average value backed up through that child so far — and I have barely looked at this move and the policy likes it — a bonus that is large while the visit count is low and the prior is high, and that shrinks away as visits accumulate. PUCT is those two terms added together, and selection just takes the child with the largest sum. Everybody knows the underlying dilemma from restaurants: return to the place you know is good, or try the promising new one. The only Go-specific twist is that the policy network is what supplies "looks promising," and that is precisely how the network's intuition gets to steer the search.
Experiment 3: Network vs search
This is the central experiment of the note, and its design is deliberately austere: one policy/value network, four players that differ only in how much search they are allowed.
A: policy only
B: policy + 10  MCTS simulations
C: policy + 50  simulations
D: policy + 200 simulations
Play each of them against the reference that isolates the variable: the same network with no search at all. A win rate above 0.5 is precisely what search adds to weights that are otherwise identical.
(The reference matters more than it looks. A first run used the random-rollout player and every configuration won 60 of 60 — a flat line at 1.0 that measures nothing, because the opponent had stopped discriminating long before. A second run returned exactly 40/80 for one cell, which is what happens when both agents are deterministic: eighty games were two games, replayed forty times each. Each pair of games now starts from its own short random opening.)
| Simulations | Win rate vs the no-search agent |
|---|---|
| 10 | 0.550 |
| 50 | 0.900 |
| 200 | 0.900 |
| 800 | 0.887 |
Same weights in every row. Ten simulations barely help; fifty turn the agent into something that beats its own no-search self nine times out of ten; beyond that it flattens. Nothing was retrained, nothing was tuned — the only thing that changed is how much computation the agent was allowed to spend on the position in front of it.
The plateau is as informative as the climb. Search cannot conjure knowledge the network doesn't have: once the tree is deep enough that its leaves are all being judged by the same value head, more simulations mostly re-confirm the same answer. Test-time compute buys a lot, and then it stops buying much.
This is a clean instance of something now familiar from reasoning models: capability at inference time depends not only on the weights, but on how much computation the system is allowed to spend on the particular problem in front of it. Search-heavy game engines have shown the same thing for decades, and AlphaGo's contribution was not the discovery of that trade but the combination — learned policy and value guiding a selective tree search in a domain where conventional search and hand-written evaluation had both stalled.
Self-play: learning without a teacher
Everything so far has been anchored to a fixed teacher — rollout-MCTS, which plays exactly as well on the thousandth game as on the first — and that fixedness is the ceiling identified earlier. Self-play removes it with a change that is smaller than it sounds: the search generating our training data stops using a uniform prior and random rollouts, and starts using the network it just trained. Nothing else about the loop changes, which is why the supervised phase was never scaffolding — classical MCTS is simply this loop with no network in it yet. The agent plays against a copy of itself, MCTS chooses the moves on both sides, and every finished game yields a pile of training examples of the form:
position
MCTS move distribution
eventual winner
The two targets come from two different places. The policy target is what search decided — the visit distribution over moves at that position, which incorporates the result of search rather than just the network's raw prior. The value target is who eventually won the game. Train a new network on that data, then use it to play more games, and the loop closes:
network
   ↓
self-play + search
   ↓
new training examples
   ↓
train network
   ↓
updated network
   ↓
more self-play
That is already a small AlphaZero-like system, and at this point the attentive reader has an objection: the network learns from the search and the search leans on the network, so isn't this a snake eating its own tail? Two things break the circle. The first was left conditional a section ago and Experiment 3 has now settled it: search with this network beats the network alone nine games in ten, so the visit distribution is a strictly better training target than the network's own output, and MCTS is acting as a policy improvement operator. The network is then never imitating itself — it is imitating a better player who happens to be itself with time to think, like a student who solves problems slowly on paper and then trains their gut to produce the considered answer instantly.
That improvement is not guaranteed by the architecture, though. A weak value head, too small a simulation budget, or badly chosen exploration constants can all make search worse than the policy it started from, and then the loop trains on degraded targets and drifts downhill. Which is precisely why Experiment 3 comes before this section rather than after it.
Second, the loop has an external referee. The value targets are not the network's opinion of its own prospects — they are the actual outcomes of finished games, scored by the rules of Go. Ground truth enters the system from outside on every single game. Self-play is circular in how it generates data, but not in how it supervises it, and that distinction is what keeps the whole thing from drifting into confident nonsense.
Two things will break it if we're careless, and both are worth showing honestly rather than hiding. The first is exploration. If the agent always plays the most-visited move, self-play collapses into the same deterministic game repeated forever, and after the first game there is no new training signal at all. The standard fixes exist for exactly this reason: sample moves from the MCTS visit distribution with a temperature — τ = 1 for the opening moves so games diverge, then annealed toward 0 so the endgame is played sharply — and add Dirichlet noise to the policy prior at the root, so every game has a chance to deviate somewhere. Without them the training loop starves quietly, which is worse than failing loudly.
The word root in that sentence is load-bearing, and the first implementation here got it wrong: the noise was wrapped around the prior function itself, so search applied it at every expansion instead of once at the top. That is a different algorithm — noise deep in the tree does not diversify games, it corrupts the very estimates the search is being run to produce. The fix is one argument, and every self-play number below comes from the corrected runs: an algorithm known to be wrong is not a thing to leave underneath your results, however plausible its output looks.
The second is passing, a notorious pathology of small-board self-play. Agents tend to mis-learn the pass move in one of two directions: refusing to pass, so games drag on with self-destructive filling moves, or passing far too early, which is a tempting shortcut whenever the value network briefly believes it is ahead. Since the game ends on two consecutive passes and is scored immediately afterwards, a pass pathology corrupts every value label downstream of it. It's worth monitoring directly — if the games in some generation suddenly get much shorter or much longer, this is the first suspect.
Experiment 4: Does self-play actually improve it?
Save checkpoints as the loop runs, and include the two players that came before it:
rollout-MCTS          ← the original teacher, no network at all
supervised network    ← generation 0, trained to imitate it
generation 10
generation 20
generation 30
generation 40
then hold a round-robin tournament between them and plot generation against Elo, or simply against win rate versus a fixed baseline. Keeping the teacher in the field matters: the moment a self-play generation beats rollout-MCTS is the moment the system has genuinely left its teacher behind, and that is a cleaner milestone than any Elo number in isolation. The shape of that curve is the whole question: monotone improvement, a plateau, or the collapse that the failure modes above produce when they go unnoticed.
Here is what happened, and it took three runs to find out — because the first two asked the wrong question. Run one started from the supervised network and retrained each generation on its own fresh games. Strength held near its starting point for a few generations and then slid without recovering: −89 Elo by generation 10, −195 by 20, −202 by 30. Not noise, not a plateau, a slide. And the diagnostic that should have caught it looked like success instead: validation accuracy on its own self-play data reached 1.000. The network was predicting its own games perfectly while getting worse at Go, which is what a system looks like when it is learning a narrower and narrower distribution.
That number was flattering for a second reason, discovered later and worth naming because it is the commoner of the two mistakes. The split was random over positions, and positions from one game share an outcome and overlap almost completely, so near-copies of the same board with the same label sat on both sides of it. Splitting by game instead, on the same data, moves validation cross-entropy from 1.60 to 1.74 and accuracy from 0.936 to 0.905 — the model is unchanged, the measurement was wrong. Both versions selected the same epoch, so nothing downstream shifted; what shifted is how good the run looked while it was quietly failing.
The cause is not self-play. Each generation retrained on a buffer of about a thousand games, against the twenty thousand that produced the network in the first place, and forgot the rest. Run two mixed the supervised games back into every training set — half old, half fresh, nothing else changed — and the fall disappeared entirely: generations sat within noise of the network they started from, splitting their forty games with it almost exactly evenly.
Which cured the symptom and revealed that the experiment was wrong. Starting from a network that already beats hundred-simulation search 57 games in 60 asks whether self-play can improve something already strong, using a search only slightly better than that thing. The claim the loop actually makes is different: that it builds a player from nothing.
Run three starts from nothing — no trained network, no offline dataset. One deviation from AlphaZero proper is worth naming: there, the randomly initialised network guides search from the very first game; here generation 1 is bootstrapped by classical MCTS — uniform prior, random rollouts — because that is what this loop is before a network exists, and because a random value head returns noise, which flattens the search into uniform tree expansion and wastes the opening generations. From generation 2 the network just trained takes over the search, and the crank turns.
| Elo | vs the rollout-MCTS search | vs the supervised network | |
|---|---|---|---|
| Generation 0 — random weights | −997 | 0/40 | 0/40 |
| rollout-MCTS, 200 simulations | −470 | — | 3/40 |
| Generation 5 | −205 | 36/40 | 11/40 |
| Generation 10 | −112 | 37/40 | 17/40 |
| Generation 20 | −76 | 38/40 | 12/40 |
| Generation 30 | −16 | 39/40 | 17/40 |
| Generation 40 | −60 | 35/40 | 18/40 |
| supervised, 20 000 teacher games | 0 (anchor) | 37/40 | — |
Nearly a thousand Elo from nothing to the peak. By generation 5 the loop has already passed the search it began as — 36 of 40 against the teacher — and from generation 25 onward it sits within a few dozen Elo of the supervised network, taking 17 or 18 of their forty games, and goes no further. At forty games a pairing those last generations are statistically indistinguishable from the anchor and from each other; what is unambiguous is the climb, the crossing, and the stop. The training side tells the same story: policy cross-entropy falls from 2.47 at generation 1 to 1.31 at the end, and by then the games have become so alike that each generation's fresh three hundred add almost nothing new.
The stop is not a disappointment to explain away — it is the imitation ceiling from the supervised section wearing self-play clothes. The loop's teacher is its own hundred-simulation search, and once the network has extracted what that search can show it, further generations redraw the same lesson. The supervised network had a slightly deeper teacher and twenty times the data; landing just below it, from nothing, is what the mechanism predicts. Raising the ceiling itself — more simulations in the loop, a bigger buffer — is the knob this note identifies and does not turn.
Three runs, three different lessons, and the middle one is the one worth keeping in mind. Curing a collapse is not the same as making progress: run two stopped the fall and still went nowhere, because there was nowhere for it to go. Only the run that started with something to learn actually learned — and where it stopped is the same ceiling seen from below.
A solved board lets us ask something sharper than any Elo number: does the system arrive at the answer somebody else proved? For 5×5 Go the optimum is published — with perfect play Black opens in the centre and takes all 25 points at komi 0. Our agents search the restricted action set described in the rules section, so agreement with that result is evidence rather than proof. It is still the sharpest external check available here, because nothing else in this project has an answer key at all.
Watch the first move of every cold-start game, generation by generation:
| Generation | Favourite opening | Share of games | Entropy of the openings |
|---|---|---|---|
| 1 — classical MCTS, no network | C3 | 11% | 3.17 |
| 2 | C3 — the centre | 88% | 2.75 |
| 3 | C3 | 100% | 1.34 |
| 11 | C3 | 100% | 0.01 |
| 40 | C3 | 100% | 0.01 |
The entropy here is of the generation's opening distribution as a whole — how spread the games are across first moves, with a uniform spread over the 26 moves costing 3.26 nats. Generation 1 — classical MCTS, no network at all — sits at 3.17, opening essentially at random: its favourite point starts barely one game in ten. By generation 3 the system plays the centre in every single game, and it never changes its mind again. That is the provably optimal first move, found from nothing. Recall what the same search could not do at the top of this note: rollout MCTS never once chose the centre across twelve runs, ranking it anywhere from third to twenty-second, and its opinion barely moved with budget. The loop found in three generations what more computation of the old kind could not find at all.
The value head converges too, and this is the one number in the note that closes the loop it opened with. Asked what the empty board is worth to Black:
| Value of the empty board | |
|---|---|
| Rollout MCTS, 10 000 simulations | +0.15 |
| Cold start, generation 20 | +0.97 |
| Cold start, generation 40 | +0.989 |
| The truth | +1.0 |
At the empty board — the one state whose is published — the learned estimate has approached the game-theoretic value. The gap between the two, versus — the value under your play versus the value under perfect play — has been the quiet subject of the whole note: it is why the hand-written evaluator failed, why rollouts mislead search, and why a value network was introduced at all. One state does not make the two functions equal, and our agents play the restricted variant, so this is evidence of convergence toward optimal play rather than proof of it. But it is evidence measured against a published answer, which nothing else in this project can offer.
What the network actually contributes to search
The claim that the neural networks are what make search work is easy to assert and easy to test, since each ingredient can be removed independently. The prior can be the policy network or uniform; the leaf evaluation can be the value network or a random rollout. That's a 2×2:
uniform prior + rollout     ← classical MCTS; also our original teacher
policy prior  + rollout
uniform prior + value net
policy prior  + value net   ← the full system
Running that grid at a single budget produces four bars and one weak conclusion. Running it across budgets — 10, 50, 200, 800 simulations — produces something better, because the interesting question isn't whether each component helps but when. Every cell plays the same reference as Experiment 3: the network with no search.
| Configuration | 10 | 50 | 200 | 800 |
|---|---|---|---|---|
| uniform prior + rollout | 0.013 | 0.050 | 0.188 | 0.375 |
| policy prior + rollout | 0.188 | 0.225 | 0.362 | 0.625 |
| uniform prior + value | 0.013 | 0.613 | 0.713 | 0.863 |
| policy prior + value | 0.550 | 0.900 | 0.900 | 0.887 |
The prediction was that the policy prior would dominate at small budgets and the value head's contribution would grow with the budget. The curves say yes, and they cross to prove it. At ten simulations the prior is what matters: policy+rollout scores 0.188 while uniform+value scores 0.013, because with ten simulations there is no point judging leaves precisely if you spent the simulations on nonsense moves. By fifty the order has reversed — 0.225 against 0.613 — and by eight hundred it is not close: 0.625 against 0.863. Two components, two different jobs, and which one is the bottleneck depends entirely on how much computation there is to allocate.
The row that should stop you is the second one. Search with a good prior and random rollouts loses to not searching at all, at every budget below 800. It spends two hundred simulations and arrives at a worse move than a single forward pass would have produced. This is not search being weak; it is search being misdirected. Random playouts estimate faithfully, and that quantity is close to unrelated to who should win — exactly the failure Experiment 0 measured before any network existed, now paid for in lost games. Replacing the rollout with the value head, holding everything else fixed, moves the same configuration from 0.225 to 0.900.
Classical MCTS — the bottom-left corner, uniform prior and rollouts — never gets off the floor. It is the algorithm that made computer Go respectable, and on this board, against this baseline, at these budgets, it cannot beat one forward pass of a small network. That is the whole distance the note has travelled.
The order is the point
Every component of this system appeared because the previous version visibly lacked something, and that ordering is the real content of the note. A hand-written evaluation function turned out to be as hard to write as the opening claimed, so we let the evaluation be learned. A CNN trained on a teacher's moves could pick plausible moves, but every decision had to be compressed into a single forward pass, so we added search to spend extra computation on the particular position in front of us. The tree turned out to be far too large to explore blindly, so the learned move prior we already had was put to work directing it. Playing every branch to the end was expensive and — worse — measured the wrong quantity, so a value network replaced the rollouts. Training all of this needed data better than a mediocre teacher could supply, so the system started playing against itself. And because search with the network is stronger than the network alone, the network can be trained to imitate its own improved search — the loop that closes the design, and the only part of it that needs no teacher at all: started with no trained network and no data, bootstrapped for one generation by classical search, it climbs a thousand Elo, passes the search it began as within five generations, stops just short of the network we spent twenty thousand teacher games building — at the ceiling its own search sets — and lands on the opening and the board value that the published solution proves correct.
Read in that order, the AlphaZero architecture is the obvious solution to a sequence of problems, each of which we watched appear. The note began with a much smaller question — how do you get a little CNN to play Go? — and never needed a bigger one.
The board size, meanwhile, is a single constant. Set it to 7 and everything above runs unchanged: the rules, the network, the search, the self-play loop. The game becomes considerably more interesting to play and considerably slower to train — roughly twice the points, games about twice as long, and a search tree that grows accordingly. The lab says where that constant lives. Beyond 7×7, on a laptop, the honest answer is that this is where the approach starts needing the hardware budget that made the original result news.