Chapter 6 of 7
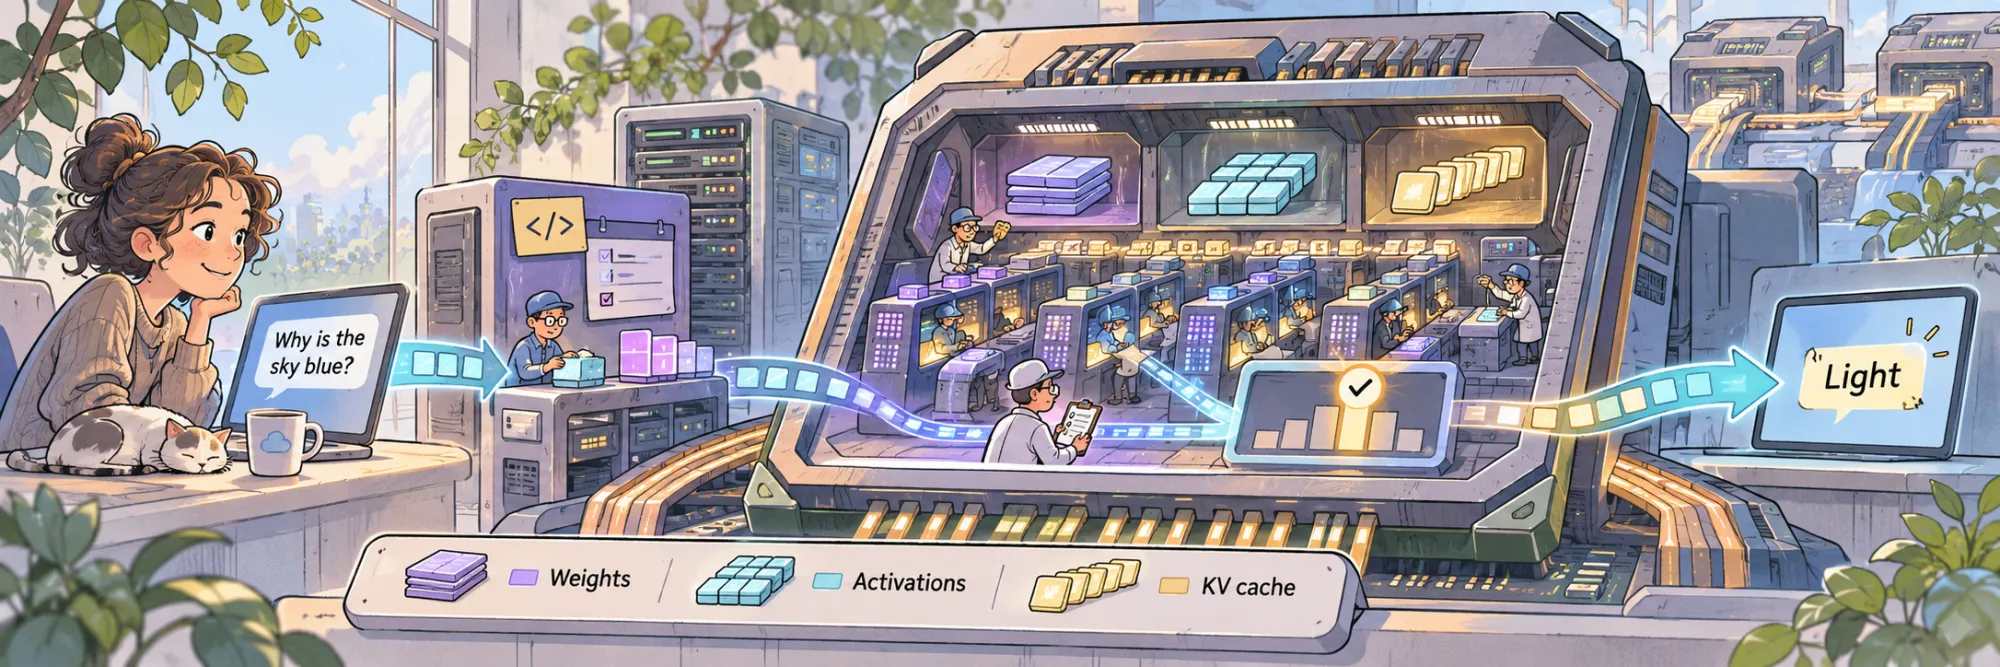
Where Your Prompt Goes: Inside a Modern AI GPU
Created Oct 23, 2026 Updated Oct 26, 2026
You type Why is the sky blue? and press Send. Somewhere, a machine starts answering. But where, physically, is your question now? In a network cable? In a processor? In those small blocks surrounding the large shiny chip? And where was the model before you asked it anything?
Follow this request all the way down: from a message in a browser to numerical arrays in memory, to tiny pieces of those arrays arriving at arithmetic circuits, and back to text. Along the way, the same question keeps becoming a different physical thing.
The route uses the documented NVIDIA Vera Rubin NVL72 layout to give it concrete chips and links; names such as SM, TMA and NVLink belong to that implementation. AMD CDNA 5 / Instinct MI455X organizes the same work differently, and the comparison near the end follows both designs, alongside earlier NVIDIA generations.
The route is a representative text-serving deployment with the model already loaded; a particular chat service may place its frontend, tokenizer and workers differently. The sizes along the way come from sending the same question to a real open model, Qwen2.5-1.5B-Instruct. That model fits on one GPU; where the route crosses between GPUs, it shows how the same kinds of data move once a larger model is split across several. The drawings are original schematics, and specifications were checked on October 23, 2026.
Send a message through the machine
Start with the whole journey. Choose a view and press Animate view to follow its links; turn on Auto-advance views for the full tour. Watch what is stored, what is moving, and what is waiting. The three boxes above the map show how the representation changes, and how large it is. At 6 · First token, the return path already reaches the browser; at 7 · Decode, streaming and further computation overlap.
There are three objects to keep separate throughout the trip:
| Object | What it is | Whose memory is it? |
|---|---|---|
| Weights | The numerical parameters learned during training | Shared by requests using that model replica |
| Activations | Intermediate numerical results computed from the current inputs | Associated with the work being processed; often packed into batches |
| KV cache | Attention keys and values retained for processed tokens | Associated with a sequence; reusable prefixes can be shared |
A chat message creates work and new state. The model's weights are already waiting for it.
Open the machine
Before following the request step by step, open the machine once. An AI rack contains several different kinds of hardware that are easy to collapse into the word “GPU.” Zoom in until each has a place. In Inside an SM, use Step forward to stop where the activation tile has landed in shared memory but the matching weight tile is still being copied. The matrix instruction cannot start until both have arrived; the result is a newly computed tile.
In the documented DGX Vera Rubin NVL72 configuration, 18 compute trays each contain two Vera CPUs and four Rubin GPUs. Nine separate NVLink switch trays connect the GPU fabric. The rack therefore has 72 GPUs, but the serving software chooses how many participate in a particular model replica and request. A small deployment can use a subset. Source: DGX hardware guide.
At the package level, Rubin has two compute dies, linked by NV-HBI, and HBM4 memory beside them. Inside the compute dies are groups of streaming multiprocessors, or SMs, containing execution resources. Tensor Cores provide matrix arithmetic; other instructions run on other GPU execution units. L2 cache and memory controllers help move the data these units need.
HBM means high-bandwidth memory. It is made from stacked memory dies, connected to the processor through a wide interface in the package: 2,048 bits per HBM4 stack. This is where a running model can keep a large collection of weights close to its compute dies. The compute circuits and the memory holding their inputs are distinct physical components.
That distinction is the reason the next sections contain so much movement.
The first stop is ordinary software
Your browser serializes a request and sends it over a network connection. The message can include conversation history, instructions and generation settings as well as the sentence you just typed. Even a minimal chat request wraps the 20-byte question in 117 bytes of JSON. Network hardware receives packets; the service reconstructs the request in memory and runs application code on CPUs.
The service prepares the model's input: it applies the model's conversation format and turns the resulting text into token IDs, integers from that model's vocabulary. A token may represent a word, part of a word, punctuation or a fragment of bytes. For Qwen2.5-1.5B, the five-word question becomes 35 token IDs, and only six of them are the question itself: the conversation format adds a default system message and a marker around each turn, and the model processes those positions like any other. An integer ID is an index, and says nothing by itself about the meaning of the token.
At this point, there are text bytes and arrays of integers in host memory. The frontend CPU may be in a different server from the GPU workers. A software router selects a worker; the worker's scheduler decides when to admit the request and how to batch it with others. The network switches carrying those messages have a different job from this software router.
This is the first possible wait: a queue before GPU work starts. Adding faster matrix units does not by itself remove an overloaded service's queue. Request routing, scheduling and GPU execution are separate responsibilities; NVIDIA Dynamo is one implementation that makes this separation explicit.
The weights arrived before you did
Earlier, when the model worker started, it loaded model files from persistent storage and prepared the weights in GPU memory. Depending on deployment, these files may come from shared storage or a local cache; each Rubin compute tray has its own NVMe drives for caching.
For the warm worker in this example, weights now occupy addresses in HBM. A large model may have its weights split across several GPUs. Those weights remain available while many requests pass through. Ordinary inference reads them; it does not train a new set of weights for your question.
“The model is in the GPU” therefore has a fairly concrete meaning: arrays of encoded numbers occupy GPU memory. There is no separate little copy of the model permanently etched into the arithmetic circuits. Kernels repeatedly bring portions of those arrays to reusable execution units.
The size of a weight array follows ordinary arithmetic. A hypothetical model with 400 billion parameters needs 800 GB for its raw parameters at two bytes each, or 200 GB at half a byte each. The latter is four bits per parameter. Quantization also needs metadata, and inference needs room for caches, activations and temporary buffers, so this calculation is only the raw weight payload.
For orientation, the current product specification gives 288 GB of HBM4 per Rubin GPU. Memory capacity answers how much can be resident; memory bandwidth answers how quickly it can be read. Neither quantity is the number of arithmetic operations the GPU can execute, and which of the limits an operation runs into is the subject of How GPUs Actually Run Machine Learning. Source: current Rubin specifications.
The input reaches the GPU
Once admitted, the request needs input buffers that GPU kernels can access. The worker arranges token IDs, positions and attention metadata and submits the work; how a Python call turns into a launched kernel is taken apart in From Python Call to GPU Kernel. On a Vera Rubin Superchip, NVLink-C2C connects the CPU and GPUs; its coherent memory connectivity makes host and device memory accessible through a closely coupled system. The actual placement and transfers still depend on the runtime.
The diagrams show the inputs staged in GPU memory to make their location explicit; coherent access or a direct transfer can change that detail. The invariant is that the execution units must obtain the numerical inputs from somewhere. For this request, the inputs are tiny: 35 IDs stored as 8-byte integers, 280 bytes.
An embedding operation uses token IDs to retrieve numerical vectors from an embedding table, which is itself part of the model's weights. Now the input has become activations: arrays whose values will change as the model processes them. In the 1.5B model each position becomes 1,536 numbers, so the 35 positions occupy about 108 KB in BF16, and each of the 28 layers produces a new array of that size.
The text has already crossed several representation boundaries. The GPU's matrix units will receive numerical tiles, with no knowledge that the numbers began as a question about the sky.
A few millimetres, repeated many times
During prefill, the model processes the prompt. Within a layer, linear operations multiply activation matrices by weight matrices. Attention combines information from allowed earlier positions; other operations normalize values, apply nonlinear functions and add residual paths.
Take just one matrix operation. The full weight matrix may be far too large for the storage next to an execution unit. The kernel works on tiles: small pieces loaded and reused while calculating portions of the answer. Matrix Multiplication: The Operation Behind Modern AI builds that tiling up step by step on a real GPU.
Physically, an illustrative matrix kernel does something like this:
- Obtain a weight tile and an activation tile from memory. A cache hit can supply data without another HBM read.
- Stage operands in the on-chip storage required by that kernel and its matrix instructions.
- Execute matrix multiply-accumulate operations and keep partial results close to the execution units.
- Reuse resident data where possible; fetch the next tiles and eventually write results or hand them to further computation.
The Tensor Memory Accelerator (TMA, present since Hopper) copies tensor tiles asynchronously into shared memory, and since Blackwell the matrix units can accumulate intermediate results in a dedicated Tensor Memory. Registers, shared memory and caches also have roles, but there is no universal rule that every number must pass through every box in a fixed order. The instruction and kernel determine the path.
Asynchronous movement lets a kernel prepare a later tile while calculating with an earlier one. If the next tile is not ready when needed, the computation has to wait. Other ready work may run in the meantime. Keeping the hardware busy depends on having enough useful work and on feeding it fast enough.
This also explains why a model layer has no permanent physical address in the compute die. Its weights have memory addresses; its operations are work scheduled onto reusable hardware. A neural-network neuron is not a dedicated transistor waiting for its turn to light up.
What the prompt leaves behind
Attention creates keys and values for processed tokens. Keeping them allows later steps to use the preceding context without recalculating all of it. In a conventional transformer, there is attention state for every layer, rather than one universal key/value array for the whole model.
The KV cache commonly lives in HBM beside the weights, but its ownership and lifetime differ. Weight buffers belong to the loaded model replica. KV blocks belong to ongoing sequences or cached prefixes. Temporary activations occupy another part of the memory budget. GPU memory management must account for all of these.
The widget runs the real question and the model's real first sentence: 35 prompt positions, then one more position per generated token. Press Play to run the prompt and then each new token, or use the step button to go one phase at a time. Striped slots are writes still in flight; solid slots have been saved. Notice that the newly selected output token has no K/V yet: it becomes input to the next pass. The weight area stays fixed while the KV area grows: the model has not changed, the sequence has.
For a conventional full-attention model with grouped-query attention, an uncompressed KV payload can be counted as
where is the number of layers, the number of stored positions, the number of key/value heads, the dimension of each head, and the bytes per stored number. The factor of two is for keys and values. This is a logical total before sharding, replication, padding or allocator overhead; sliding windows, compressed attention state and other model designs change the accounting. For the 1.5B model, , , and , so each slot in the widget above holds 28.7 KB. The KV Cache in One Formula works the same count through for other models.
For the models a rack like this one serves, the cache stops being small. Pick a model, a context length and a number of simultaneous conversations:
With Qwen2.5-72B in BF16, every token of context holds 328 KB of K/V, so one 32K-token conversation needs 10.7 GB. Sixteen such conversations need more memory than the 145 GB of weights they all share. DeepSeek-V3, with more than nine times the parameters, caches only 70 KB per token: latent attention stores a 512-number compressed vector and a 64-number positional key per layer instead of full keys and values. The weights fix how many GPUs a model needs at all; the cache decides how many conversations those GPUs can hold.
When one GPU needs another
Suppose the model is distributed. At some points, an operation cannot finish using only the data and results on one GPU. What crosses the connection depends on how the model was divided.
| Parallelism | What lives on different GPUs | What has to move |
|---|---|---|
| Tensor parallelism | Pieces of the same layer's tensors | Partial results or activations needed to combine the operation |
| Pipeline parallelism | Different groups of layers | Activations passed to the next stage |
| Expert parallelism | Different expert networks in a mixture-of-experts model | Routed token activations and the experts' outputs |
In the expert case, “sending a token to another GPU” generally means moving its activation vector. It does not mean sending the original word as an HTTP request to that chip. The selected expert's weights may already be resident there.
These schemes can be combined. They create synchronization points: a consumer waits until the required producer results arrive. This is why the connection between GPUs matters to latency, even when every GPU is individually fast.
Within the Rubin rack, NVLink connects GPUs through switch hardware. Between racks, a deployment can use an InfiniBand or Ethernet fabric. Local HBM, a neighboring GPU's HBM and remote storage remain different destinations with different access costs.
Where the first answer token comes from
After the prompt has passed through the model, the final position's output is projected into scores over the vocabulary: logits. The generation policy selects a token from those scores, either the highest-scoring one or a sample from a transformed distribution. The first output token comes straight out of prefill; no separate decode step is needed to produce it. The loop that follows, and where its time goes on a real GPU, is the subject of How LLM Inference Actually Works.
What matters physically is how little leaves the GPU. For the question above, the final position produces 151,936 scores: about 304 KB in BF16, twice that if the engine upcasts them to FP32 for sampling. Selection runs on the GPU, so what returns to the host is one 8-byte token ID, here the ID for The. Serving software converts IDs back into text fragments and streams them to the browser. Fragment boundaries need not be word boundaries: Rayleigh arrives as Ray and leigh.
That ID then becomes the next input. The model processes its position, adds its K/V to the cache, produces logits again and selects another token, until a stop condition is met. The KV cache avoids repeating the prompt computation; it does not remove the work for each new position.
The answer can change machines halfway through
Modern serving systems can put prefill and decode on different workers. One group handles the prompt and creates its attention state; another continues generation. This is disaggregated serving.
That handoff needs the KV state, not just the few bytes of the original question: for the 72-billion-parameter model above, a 32K-token context is 10.7 GB. The serving engine and available connections determine how it moves; NVIDIA Dynamo, for example, uses NIXL to transfer cache data between GPU memories over whatever transport the topology offers.
The benefit is independent scheduling of two kinds of work. The cost includes transferring state and coordinating the handoff. The main animation keeps prefill and decode on the same worker group so their shared state stays visible; disaggregation adds a physical cache transfer between those phases.
Four places where the answer waits
The pause before the first token and the gaps between later tokens can have different causes. Follow the location of the dependency:
| Where | What is missing | What the user experiences |
|---|---|---|
| Service queue | Admission or a free execution slot | Waiting before model processing starts |
| Inside a GPU | The next operands, or completed arithmetic | Slower prefill or a slower decode iteration |
| Between GPUs or workers | A partial result, expert output or transferred KV state | A synchronization or handoff delay |
| Between generation steps | The preceding selection needed for subsequent work | Limits on how quickly one sequence can progress |
Prefill often has substantial matrix work to perform across many positions. Small-batch decode often has comparatively little arithmetic for the weight data it reads. Long-context attention, batching, mixture-of-experts routing and the selected kernels can move the bottleneck. “The GPU is busy” cannot identify which dependency dominates.
One narrowly defined cost does have a lower bound. Take the hypothetical 200 GB weight payload from earlier, assume a dense pass reads it all from one Rubin GPU's HBM, and divide by the 19.2 TB/s bandwidth in the current product table:
That is an idealized lower bound for that weight traffic alone. It excludes KV reads, other traffic, arithmetic, communication and scheduling; cache reuse, sharding and batching change the traffic per request. It is not a measured token latency. Source for the bandwidth: current Rubin specifications. NVIDIA's Rubin architecture article quotes up to 22 TB/s instead, which would make it 9.1 ms; NVIDIA does not explain the difference, and this note uses the product table throughout.
How close does real software get to such a floor? How LLM Inference Actually Works measured it on a T4: eager PyTorch took up to nine times longer per token than the bytes alone required, and a serving engine closed the gap to 1.5–1.7 times.
Keep the question. Change the machine.
The same model still needs weights, activations, attention state and arithmetic. What changes when that work runs on different hardware?
If H100 and H200 are the names you recognize, they belong to the same family of jobs: training models and running inference. Both use NVIDIA's Hopper architecture; H200 keeps H100's arithmetic and adds memory capacity and bandwidth. To place Rubin among NVIDIA's generations:
| NVIDIA generation | Familiar product names | What to notice for this journey |
|---|---|---|
| Hopper | H100, H200 | The same basic jobs: weights in GPU memory, matrix computation, attention state and communication |
| Blackwell | B200; GB200 systems | Two compute dies form one GPU; GB200 NVL72 connects 72 GPUs at rack scale |
| Blackwell Ultra | B300; GB300 systems | The two-compute-die organization continues; GB300 uses the NVL72 rack design |
| Rubin | Rubin GPU; Vera Rubin systems | HBM4, Vera host CPUs and NVLink 6; the main machine in this note |
GB200 and GB300 name CPU–GPU platforms; they are not simply another name for an isolated GPU die.
Each row brought faster memory, yet the balance between arithmetic and memory has barely moved at 16 bits. Divide a GPU's peak dense arithmetic rate by its peak memory bandwidth, both from the datasheets, and you get the FLOPs an operation must perform per byte it reads before memory stops being its limit: the ridge of the roofline in How GPUs Actually Run Machine Learning. Here is that number at three precisions:
| GPU | Bandwidth | 16-bit | 8-bit | 4-bit |
|---|---|---|---|---|
| T4 (2018) | 0.32 TB/s | 203 | — | — |
| H200 | 4.8 TB/s | 206 | 412 | — |
| Rubin | 19.2 TB/s | 208 | 911 | 1,823 |
| MI455X | 23.3 TB/s | 216 | 864 | 1,728 |
The 4-bit column compares different formats: NVFP4 on Rubin, MXFP4 on MI455X.
From a 2018 inference card to Rubin, the 16-bit ridge stays near 200: Rubin's row is 4 PFLOP/s of dense 16-bit arithmetic against 19.2 TB/s. What outgrew memory is low-precision arithmetic, where an operation now needs four to nine times more work per byte to keep the matrix units busy. At batch 1, the weight matrices of a decode step see two FLOPs per parameter, one to four FLOPs per byte at these precisions, and attention over the cache adds bytes without adding much arithmetic. Batching multiplies the FLOPs per weight byte, which is why serving engines batch; at small batches, every generation leaves decode waiting on bytes. Sources: Rubin NVL72 specifications, AMD CDNA 5 white paper.
Now compare one GPU package with one GPU package, then inspect how operands reach execution and how results reach another GPU.
Start with what Rubin inherits. Blackwell already joined two compute dies into one GPU through NV-HBI. Hopper already had a Tensor Memory Accelerator for asynchronous tensor transfers; Blackwell added dedicated Tensor Memory for matrix intermediates. Those features belong in the explanation of Rubin, but their presence does not distinguish it from every predecessor.
Rubin changes several mechanisms along this route:
- Describing the next transfer. For tensors with a common layout, TMA can reuse a descriptor and override its address or stride in the instruction itself. Earlier kernels that switch between experts patch the descriptor in memory and fence before using it, or keep one descriptor per expert.
- Covering the reduction dimension. In , each result sums products along . Rubin's matrix units process twice as much of that dimension per step, so a loop that took four iterations along on Blackwell takes two. The gain concerns this instruction-level work, not a measured speedup of the whole request.
- Releasing dependent work. Blackwell already lets a dependent kernel start early through programmatic dependent launch; Rubin coordinates dependent kernels at a finer grain than that. A consumer still starts only when its own inputs are ready.
- Knowing a remote transfer is complete. Counted writes let a receiving GPU track completion of device-initiated NVLink transfers. They change how completion is signalled; the consumer still needs the transferred data before it can use it.
These are changes to data movement, instruction granularity and readiness, alongside the move from HBM3E to HBM4. A particular inference engine and kernel must use them for a workload to benefit. Source: Rubin architecture mechanisms.
AMD partitions the same work differently. MI455X divides functions across eight compute chiplets, two fabric/cache dies and two I/O dies. Its compute dies use 3D hybrid bonding. All of those components belong to one GPU package; eight compute chiplets are not eight separate GPUs. The package integrates 432 GB of HBM4 in twelve stacks with up to 23.3 TB/s, against Rubin's 288 GB and 19.2 TB/s in the NVL72 table. The capacity changes the residency budget: in the budget widget above, the same model and conversations fit on fewer packages. The bandwidth moves the floor: the 200 GB pass from earlier would take at least 8.6 ms instead of 10.4. Neither number determines token latency on its own. Sources: AMD CDNA 5 architecture, AMD CDNA 5 white paper.
The local execution organization changes too. CDNA 5 groups work in Work Group Processors (WGPs). Its Tensor Data Mover (TDM) can copy data asynchronously from global memory into Local Data Share (LDS) without staging it through registers. L2 multicast can distribute a fetched tile to several WGPs. NVIDIA's SM, shared memory and TMA provide a useful conceptual comparison, but the components and instructions are not interchangeable one for one.
Keep the connection boundaries separate. NV-HBI joins the two compute dies inside a Rubin GPU; NVLink connects GPUs in its scale-up domain. AMD uses Infinity Fabric for on-package communication; Helios uses UALoE for scale-up between GPUs. The two rack designs each contain 72 GPUs, but that shared count does not make their CPU grouping, links or execution resources identical.
Where your question was
Go back to the question from the start: where, physically, is your question now?
It was never one object. Sent to the small model whose sizes this note has followed, it left your browser as 20 bytes inside a 117-byte request and reached the GPU as 35 integers. The model turned those into 35 vectors of 1,536 numbers and rewrote them in each of its 28 layers, and the prompt left about a megabyte of keys and values in HBM, where they stay for as long as the conversation does. The last layer produced 151,936 scores, and one 8-byte integer came out of the GPU: the ID for The, the moment step 6 of the first animation shows.
The model was not changed by any of it. Its weights were in HBM before you asked and are still there for the next question. What your question added was work for circuits that serve everyone, a cache that belongs to your conversation, and heat: nearly all the electrical power behind every transfer and multiplication becomes heat in the chips, cold plates pass it into the coolant, and the coolant carries it out of the rack while the text travels to your screen.