Chapter 4 of 4
From Python Call to GPU Kernel: The C++ Underneath ML Libraries
Created Sep 19, 2026
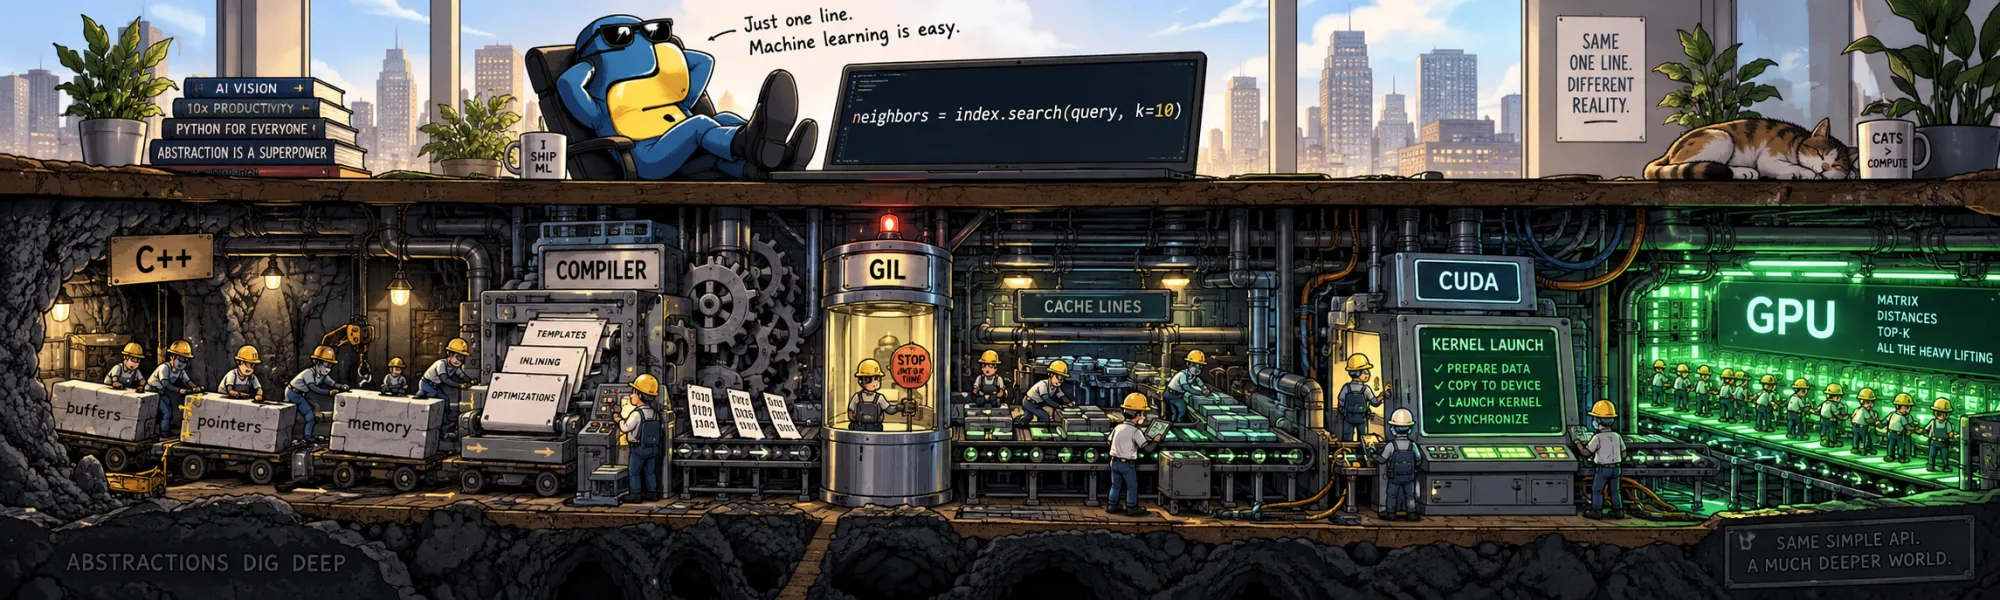
Here is a line that appears, in one spelling or another, in more or less every retrieval system:
neighbors = index.search(query, k=10)On the machine this note was measured on — an ordinary four-thread cloud CPU with a Tesla T4 attached — that line takes about half a millisecond for one query against 100,000 vectors of 128 floats, and tens of microseconds per query when a thousand queries arrive together. Written out in plain Python, the same search takes 1.2 seconds for a single query: a factor of two thousand for one query, and tens of thousands for a batch.
Python is not doing the work. It never was. The interesting question is what is, and the answer is a stack of layers that a Python programmer normally never has to think about — until a model is too slow, or a library segfaults, or an extension refuses to build, and every one of those layers becomes visible at once.
This note goes down through them. Not as a C++ tutorial: the language appears only where a concrete problem forces it to. The vehicle is a small library, tinyknn, written from scratch for this note in about 1,200 lines of C++ and CUDA — an owning buffer, a non-owning view, metrics as types, a templated search, a CUDA kernel, and a Python module. Everything in it has a counterpart in a production vector-search library, with years of work on top of it there. Everything measured below is measured on it.
Runnable companion. Every number in this note comes from one run of the lab, which writes the library, builds it, tests it against NumPy in double precision, and then runs two dozen experiments on it. The C++ is all there; so are the compiler's own diagnostics, the sanitizer's report, and the disassembly.
One line, four speeds
Start by measuring what the line costs, four different ways, on the same machine and the same data: 100,000 vectors of 128 floats, the ten nearest by Euclidean distance.
Pure Python: 1.21 s for one query. NumPy, subtracting the query from the whole database and squaring: 21.7 ms. NumPy again, rewritten around a matrix multiplication: 2.43 ms. The library's C++ on one thread: 4.71 ms — slower than NumPy. On four threads for a batch of a thousand queries: 0.89 ms per query. On the GPU: 18 µs per query.
Two of those numbers are worth pausing on.
The first is Python's 1.21 seconds, which is not a scandal but a measurement of what an interpreter costs: about 82 nanoseconds per number, whatever the number is being used for. The whole of the rest of this note is downstream of that one fact.
The second is that hand-written C++ lost to NumPy. NumPy is not a slow language wrapping a fast one; it is the fast one, and its matrix multiply goes to a BLAS library that has been tuned for this processor by people who do nothing else. This is the honest starting point: writing C++ does not make code fast. What it buys is the right to decide where data lives, who is allowed to touch it, and what can be decided before the program ever runs — and, as the later sections show, that is what eventually gets you the 18 µs.
One convention before going further, because the same GPU call is measured three times in this note and the three numbers are not identical. The comparison above is the fastest of five runs, timed from Python. The top-k section times the library's own stages, as a median of seven runs. The last section times the whole call from Python, as a median of twenty-one. On top of that, the T4 is a 70-watt card whose clock moves with temperature and load: the lab's own calibration caught it running at 914 MHz against a rated 1,590. So the same search costs 0.49 ms in one experiment and 0.50 ms in another, and a thousand queries cost 18 µs each in one and 12.5 µs each in another. Every comparison below is made within one experiment, where both sides ran back to back, and each section says which one it is reading.
What Python pays for every number
In CPython — the interpreter this ran on, and the one nearly everyone means by "Python" — 0.5 is an object on the heap: a type pointer, a reference count, and then eight bytes of actual number, 24 bytes in total on this machine. A list of them is an array of pointers to such objects, which may sit anywhere in memory and, once a program has been running for a while, generally do.
A million floats in a list occupy 32.4 MB and touching one means following a pointer to an object whose neighbours in the list are not its neighbours in memory. The same million as a NumPy float32 array occupy 4 MB, back to back, and the address of element i is the address of element 0 plus four times i.
That difference shows up in the arithmetic in the way you would expect, and in one way you might not:
| Adding up a million numbers | Time per number |
|---|---|
| Python loop over a list | 82.3 ns |
sum(list) | 36.1 ns |
| Python loop over a NumPy array | 99.3 ns |
np.sum on the array | 0.32 ns |
the library's C++ sum | 0.16 ns |
Looping over a NumPy array in Python is slower than looping over a list, because every element has to be wrapped in a fresh Python object on the way out. An array is not faster to iterate; it is faster to hand to someone else. This is the shape of every fast Python library: the data is in a buffer, and the loop happens on the other side of a boundary.
So the first thing C++ is for is the loop. What the next sections are about is everything that turns out to be attached to that.
Where the data actually is
A contiguous buffer of floats has an address. In C++ that address has a type — const float* — and the arithmetic on it is explicit: element i of row n of an N × D matrix is at data + n * D + i. A two-dimensional array is one-dimensional memory plus a rule for reading it. NumPy calls the rule strides and keeps it in the array object; the library calls it stride and keeps it in a view:
template <class T>
struct matrix_view {
  T* data = nullptr;
  std::size_t rows = 0, cols = 0, stride = 0;
  memory where = memory::host;          // host or device — checked before any work starts

  T* row(std::size_t i) const { return data + i * stride; }
};
Because the rule is separate from the data, changing the rule is cheap and changing the data is not. Transposing a NumPy array does not move anything: it returns a new view object with the shape and the strides rearranged, over the same buffer. Reading the transposed array costs a great deal, because the addresses the loop asks for now jump.
How much is worth seeing, because it explains a large fraction of all performance surprises in numerical code. Memory does not arrive one float at a time; it arrives in 64-byte cache lines, sixteen floats at a time, whether the program wants sixteen or one.
Three measurements from that widget, all on the lab's CPU:
- Reading every 16th float of a 256 MiB array takes 21.8 ms; reading all of it takes 30.3 ms. Sixteen times less data, 72% of the time — because the same lines are fetched either way.
- Summing a 4096 × 4096 matrix along its rows takes 5.5 ms; summing the same matrix down its columns takes 30.4 ms. Same additions, same data, 5.6× apart.
- A 128-float row read as part of a sweep costs 46 ns; the same row picked at random costs 119 ns.
That last number is why brute force is a real competitor to approximate indexes far longer than the arithmetic suggests: a scan reads memory in the order the hardware is built for, and a graph index does not.
Where memory comes from matters too. A scratch array on the stack costs 0.8 ns to "allocate" — the stack pointer moves. The same array from new costs 17.8 ns, and a std::vector 30.7 ns, because someone has to find the space and give it back. None of that is visible in Python, where every array is a heap allocation and the allocation is the cheapest part of what happens.
Who owns the bytes
A view is a pointer and a length. It does not know where the memory came from, and it does not know when it goes away. That is the price of not copying, and it is the source of the most expensive class of bug in native code.
Four lines: make a vector of four floats, take a view of the first two, push a fifth float, read through the view. The push exceeds the capacity, so the vector allocates a bigger block, moves the values, and frees the old one. The view still points into the freed block.
The program prints -5.94411e-29 and exits with status 0. No crash, no warning, a number that looks like data. Rebuilt with AddressSanitizer, the same four lines stop exactly there, with the allocation and the free both named. Growing a vector to a million elements without reserve reallocates 20 times and moves 1,048,575 elements — every one of those moves invalidating every pointer anyone held.
C++'s answer is to attach the lifetime of memory to the lifetime of an object, so that freeing is not something anyone remembers to do:
template <class T>
class host_buffer {
 public:
  explicit host_buffer(std::size_t n)
      : data_(static_cast<T*>(::operator new(n * sizeof(T), std::align_val_t{64}))), size_(n) {}
  ~host_buffer() { release(); }

  host_buffer(const host_buffer&) = delete;             // no accidental copies
  host_buffer& operator=(const host_buffer&) = delete;
  host_buffer(host_buffer&& other) noexcept;            // moving hands the bytes over
  host_buffer clone() const;                            // copying has to be asked for, by name
  ...
};
The constructor allocates, the destructor frees, the copy is deleted so that a gigabyte cannot be duplicated by a typo, and the only way to get a second copy is to write clone(). std::unique_ptr is the same idea in the standard library: with the default, stateless deleter it is the size of a raw pointer (8 bytes here) and costs nothing measurable to read through, which is what "zero-overhead abstraction" means in practice. Give it a deleter that carries state and the size grows; the guarantee is about what you don't ask for, not about the name.
std::shared_ptr is the other answer — the memory lives until the last owner goes away — and it is not free. It is 16 bytes, it allocates a control block, and every copy touches an atomic counter: 3.74 ns to pass one by value against 1.32 ns by reference. With four threads copying the same pointer it is 160 ns, because that counter is one cache line that has to travel between cores. Shared ownership is a fine thing to have at the edges of a system and a catastrophe in an inner loop, and that is the whole of the advice.
The same question crosses into Python. When the index hands back a NumPy array that looks directly into its own pinned buffer, nothing is copied — and Python's reference count keeps the index alive as long as the array exists, because the array's base is the index. DLPack, the protocol PyTorch, CuPy and JAX use to pass tensors between each other, is this contract standardised: the consumer gets a pointer and a deleter, and the producer's memory is freed when the deleter runs, not before. In the lab, a NumPy array handed to PyTorch through DLPack shares an address, sees writes made through the tensor, and stays valid after the NumPy name is deleted.
Copies nobody asked for
In Python, b = a never copies and b = a.copy() always does, and the difference is one visible method call. In C++ the difference is punctuation.
With every heap allocation in the program counted, for a 1 GiB buffer:
| time | allocations | |
|---|---|---|
Tensor b = a; | 917 ms | 1 |
Tensor b = std::move(a); | 0.04 µs | 0 |
f(Tensor t) — by value | 946 ms | 1 |
f(const Tensor& t) — by reference | 0.05 µs | 0 |
Tensor make() — returned by value | 813 ms | 1 (the buffer itself) |
A move is not a fast copy; it is a transfer of ownership. Three numbers — pointer, size, capacity — change hands, the source is left empty, and the gigabyte does not move at all. Returning a large object by value is free for the same reason: it is constructed directly in the caller's variable, which is why a function that builds a tensor and returns it costs the same as one that fills a tensor in place (813 ms against 797 ms — the cost of touching a gigabyte of fresh memory, not of copying it).
The other place copies appear is the boundary itself. The binding declares what it accepts:
using farray = py::array_t<float, py::array::c_style | py::array::forcecast>;which reads: C-contiguous float32 — and if it isn't, convert it. That conversion happens before the function body runs, and it is invisible from Python. In the lab, the same call with the same shape:
| array handed in | what happened | cost |
|---|---|---|
float32, C order | used as it is | under 10 µs |
| rows 1000:51000 (still contiguous) | used as it is | under 10 µs |
| every second row (strided) | copied | 5.4 ms |
| Fortran order | copied | 25.2 ms |
float64 | converted and copied | 19.7 ms |
float16 | converted and copied | 44.1 ms |
A float64 array is what np.random.random returns, so this is not an exotic case; it is the default one. The same function written to refuse conversion takes the float32 array and raises TypeError on all four of the others. Both designs are defensible. What is not defensible is not knowing which one a library chose, because the difference is a silent gigabyte per call.
Owning and viewing are different jobs
Out of the last two sections falls the shape of every numerical API worth using. There are two kinds of type, and they answer different questions.
A container answers who owns these bytes and when do they go away: std::vector<T>, the library's host_buffer<T>, a device_buffer<T> for GPU memory, PyTorch's Tensor.
A view answers how do I read these bytes: std::span<T>, the library's matrix_view<T>, C++23's mdspan, NVIDIA's RAFT device_mdspan, a PyTorch tensor that is a slice of another.
The library's search takes only views:
template <TINYKNN_METRIC M, class T>
void search_cpu(matrix_view<const T> queries,      // read-only: the const is in the type
                matrix_view<const T> db,
                matrix_view<std::int64_t> ids,     // written by this call
                matrix_view<float> dists,
                int threads = 1, std::size_t db_block = 512, bool fixed_dim = true);
Everything a caller needs to know is in that signature. Nothing is allocated for the data, nothing is freed, nothing is returned; the two read-only arguments cannot be written through, because matrix_view<float> converts to matrix_view<const float> and never the reverse; and the two output arguments say exactly which memory this call will change. Where the data lives is in the view too, so handing GPU memory to the CPU search is one comparison, made before any work starts, rather than an illegal-access fault halfway through.
This is why the APIs of high-performance libraries look the way they do — a long list of pointers and shapes rather than objects that "hold" things. The verbosity is the contract.
The shape of the data
The layout of a struct is not a detail of style; it decides how much of every fetched cache line a loop can use.
The compiler places each field at an address that satisfies that field's alignment requirement — for the scalar types here, the same as its size — and pads to get there. struct Tagged { bool valid; double score; bool seen; int32_t id; }; is 24 bytes, of which 10 are padding. The same four fields declared biggest-first are 16 bytes. Nothing about the program changed; over a million records the careless order costs 7.6 MiB of memory that holds nothing and that every scan drags through the cache.
Then the bigger question: sixteen million labelled points, stored as an array of structs (x, y, z, label together) or as a struct of arrays (all the x, then all the y):
| the loop reads | array of structs | struct of arrays |
|---|---|---|
x only | 23.5 ms | 10.2 ms |
x, y, z | 27.6 ms | 18.4 ms |
| every field | 28.0 ms | 23.4 ms |
Reading one field out of four is 2.3× more expensive from the array of structs, because three quarters of every line fetched is thrown away. When the loop wants all four fields the gap nearly closes. Neither layout is better; a layout is matched to a loop. Vector databases store dimensions contiguously and embeddings row-wise for exactly this reason, and the choice changes when the access pattern does.
The same fact, inverted, produces the strangest bug in parallel code. Four threads incrementing four separate counters take 187 ms when the counters share a cache line and 41 ms when each gets its own — a 4.6× penalty for data that is not shared at all. The hardware's unit of sharing is the line, not the variable.
What the compiler is allowed to do
Consider the plainest loop in numerical computing:
float s = 0;
for (std::size_t i = 0; i < n; ++i) s += a[i] * b[i];
A modern CPU can multiply eight pairs of floats in one instruction. The compiler will happily do that part. It will not, however, add the eight products together in one instruction, because floating-point addition is not associative: in general, and reassociating the sum would change the answer. Without permission, the compiler emits vector multiplies and then eight scalar additions.
The disassembly in that widget is the whole argument. At -O3 -march=native the plain loop's inner iteration is one vmulps on eight floats followed by eight vaddss — one float at a time. Write the sum as eight independent partial sums, and the inner loop becomes a single vfmadd231ps: multiply and add, eight lanes, one instruction.
| build | time per element | error against the exact sum |
|---|---|---|
-O0, one sum | 3.09 ns | −44.9 |
-O2, one sum | 1.35 ns | −44.9 |
-O3 -march=native, one sum | 1.35 ns | −44.9 |
-O3 -march=native, eight sums | 0.16 ns | −0.80 |
-O3 -march=native -ffast-math, one sum | 0.16 ns | −0.80 |
Two things there are worth keeping. The eight-lane version is 8.3× faster and fifty times more accurate, because eight shorter chains of additions lose fewer low bits than one long one. And -ffast-math reaches the same speed by letting the compiler reorder additions everywhere in the program, including where it is not safe. That is why numerical libraries tend to avoid enabling it globally and instead make the reassociation explicit — writing the lanes out — where they have decided it is acceptable.
This is also the honest answer to "why is my model not bit-reproducible": the order of summation is a choice, different backends choose differently, and the results differ in the last bits by design.
Templates: one kernel, many types
A distance function has to exist for float and for double, for Euclidean and for inner product, and for any dimension. Four ways to arrange that, and only one of them is free.
Write it four times: fast, unmaintainable. Take a function pointer: one indirect call per distance. Take a virtual Metric object: one indirect call per distance, plus no inlining. Or make the metric a type:
struct L2 {
  template <class T>
  TINYKNN_HD static float term(T a, T b) { float d = float(a) - float(b); return d * d; }
  // |q - x|² = |q|² + |x|² - 2·q·x — the form that lets a matrix multiplication do the work
  TINYKNN_HD static float from_dot(float q_norm, float x_norm, float dot) {
    return q_norm + x_norm - 2.0f * dot;
  }
  static constexpr bool needs_norms = true;
};

template <class M, int LANES = 8, class T>
TINYKNN_HD inline float distance(const T* a, const T* b, std::size_t d) { ... }
The metric is chosen when the code is compiled, the call is inlined, and the inner loop contains one metric's arithmetic and nothing else. The same source compiles for the CPU and, with one macro that expands to __host__ __device__, for CUDA.
The run-time choice does not disappear; it moves. It happens once per call, in one switch, outside every loop:
switch (m) {
  case metric::l2:            return search_cpu<L2>(queries, db, ids, dists, threads, ...);
  case metric::inner_product: return search_cpu<InnerProduct>(queries, db, ids, dists, threads, ...);
}
PyTorch does exactly this, in a macro called AT_DISPATCH_FLOATING_TYPES: one run-time decision per operation, then a compiled kernel over a million elements.
Two prices come with it. The first is code. Each combination is a separate copy of the machine code, and the copies multiply: metrics times element types times specialised dimensions. In the lab, instantiating the search for eight (metric, type) pairs instead of one multiplies the object file by 5.5× and the compile time by 2.8× — and the CUDA object, which holds every combination of metric, selection algorithm and compiled k, is 1.0 MB of machine code generated from a few hundred lines of source.
The second is error messages. A template's constraints are implicit: they are whatever the body happens to use, and a type that fails them fails deep inside, in a function nobody wrote. C++20 concepts let the requirement be stated where the call is:
template <class M>
concept Metric = requires(float a, float b) {
  { M::template term<float>(a, b) } -> std::convertible_to<float>;
  { M::from_dot(a, a, b) } -> std::convertible_to<float>;
  { M::needs_norms } -> std::convertible_to<bool>;
};
Handing the search a half-written metric produces 26 lines of diagnostics naming the three requirements that were not met. The same mistake with the same header compiled as C++17 produces 56 lines, pointing inside distance(), two levels down from anything the caller wrote.
What abstraction costs
The dispatch question is usually asked as "are virtual calls slow?", which has no answer. The right question is: how much work happens per indirection?
The same distances, with the metric reached seven ways, at four dimensions and at 128 — the metric's name comes from the command line, so nothing can be devirtualised:
| 4 dims | 128 dims | |
|---|---|---|
| template, dimension also fixed at compile time | 0.61 ns | 16.3 ns |
| written out by hand | 6.57 ns | 17.3 ns |
| template (metric is a type) | 6.42 ns | 19.3 ns |
| one virtual call per batch | 6.45 ns | 19.8 ns |
| function pointer, per pair | 21.4 ns | 24.8 ns |
| virtual call, per pair | 22.1 ns | 25.2 ns |
std::function, per pair | 23.4 ns | 26.3 ns |
Read the columns. At 128 dimensions, per-pair indirection costs about 30% — annoying, not fatal. At four dimensions it costs 3.5×, because the call now dwarfs the work. And one virtual call per batch costs nothing measurable at any of these sizes: the indirection is taken once, and the loop inside it is compiled.
The last row of the first column is the one that matters most. Telling the compiler the dimension as well — a template parameter, not a variable — is worth another 10× at four dimensions. Nothing was made faster; something was made knowable earlier.
Turn the same dial continuously and the shape is clear: a virtual call per distance costs 9.1 ns each, per four distances 5.6 ns, per 1,024 distances 4.5 ns — which is what the work costs on its own. The overhead did not get cheaper; it got amortised.
And this is exactly the law that governs Python. A call from Python into compiled code costs 84 ns — about the same as a call into a Python function (48 ns). Summing one number through it costs 557 ns per number; summing four million costs 0.17 ns per number. Crossing the boundary is not expensive. Crossing it per element is.
From source files to import
Everything above assumes the code exists as machine instructions in a file the interpreter can load. Getting there is a whole subsystem, and it is where most of the time a practitioner loses to C++ actually goes.
A C++ compiler does not have modules in the Python sense. #include is a paste, performed before the compiler parses anything, and what it pastes pastes too:
| one file containing only this include | lines the compiler parses |
|---|---|
<cstdio> | 1,015 |
<vector> | 14,404 |
<algorithm> | 34,989 |
<pybind11/numpy.h> | 116,444 |
<torch/extension.h> | 350,309 |
That last line takes 17.7 seconds just to parse — per source file, every time. Anyone who has built a PyTorch extension has waited for it. The library's own 24-line cpu.cpp becomes 81,809 lines; its 164-line binding becomes 151,049.
Each such file is compiled separately into an object file, and the linker stitches them together by name. Because C++ has overloading and namespaces, the names carry types: tinyknn::search(...) is _ZN7tinyknn6searchENS_6metricENS_11matrix_viewIKfEES3_NS1_IlEENS1_IfEEimb to the linker. Templates complicate this, because a template is a recipe rather than code: machine code exists only for the combinations someone instantiated. A compiled library can export particular instantiations — and libraries do, explicitly — but it cannot supply one for a type it was never compiled for, so the definitions have to be visible to whoever needs a new combination. That is the trade the library's public header makes: templates stay in headers for its own code, and the binary interface is ordinary functions and one class, with everything generic behind them.
And then the part that produces the worst afternoons. Two libraries can be built from identical source and still be incompatible, because a compiler flag changed the layout or the name of a standard type. The lab compiles the same one-line function twice:
_GLIBCXX_USE_CXX11_ABI=0:  _Z4loadRKSs
_GLIBCXX_USE_CXX11_ABI=1:  _Z4loadRKNSt7__cxx1112basic_stringIcSt11char_traitsIcESaIcEEE
Different names for the same function, because std::string is a different type under each setting. Here the linker catches it. When the mismatch is in the layout of a type rather than its name, nothing catches it, and the program crashes somewhere far away — which is the whole reason "rebuild your extension against the same PyTorch" is standard advice rather than superstition.
Crossing the binding
The binding layer itself is small and does three things: check and convert arguments, call the library, wrap the results. In tinyknn it is 164 lines and contains no arithmetic.
It also does a fourth thing, which is the one that decides whether a service scales. In CPython, a thread running Python bytecode holds the global interpreter lock, and a C++ function called from Python keeps holding it unless it says otherwise (the free-threaded builds arriving in 3.13 and later change this picture; the interpreter here is a standard 3.12):
{
  // From here to the end of the scope this thread touches no Python object,
  // so other Python threads may run. The arrays stay alive: this frame holds references.
  py::gil_scoped_release unlocked;
  tinyknn::search(metric_of(metric), qv, dv, iv, sv, threads, db_block, fixed_dim);
}
Four lines. With them, and with several Python threads each calling a single-threaded search:
| Python threads | GIL held | GIL released |
|---|---|---|
| 1 | 366 queries/s | 372 queries/s |
| 2 | 380 | 739 |
| 4 | 374 | 1,031 |
Holding the lock, adding threads does nothing at all — the classic "Python can't do parallelism" result, which is really "this library didn't let go". Releasing it, the same calls scale 2.8× on a machine with two physical cores. Performance-oriented numerical libraries typically release the lock around long-running native work; this is what that line in the changelog means.
Putting it on the GPU
The GPU half of the library is the same vocabulary again: a device_buffer<T> that owns GPU memory with the same move-only contract as the host buffer, a pinned_buffer<T> for page-locked staging memory, views that carry memory::device so a mix-up is caught before a kernel launches, and the same metric types compiled for the device.
What is genuinely different is when things happen.
Launching a kernel takes 9.7 µs of host time. The kernel then runs for 50 ms. Most of the GPU execution model works this way — kernel launches and stream-ordered operations hand over a description of work and return before that work has run, leaving the host free to keep going — which is why the interface in a library like RAFT or FAISS takes a stream:
void search_async(metric m, gpu_algo algo, topk_algo select,
                  matrix_view<const float> queries,   // device memory
                  matrix_view<const float> db,        // device memory
                  const float* db_norms, float* query_norms, float* scratch,
                  matrix_view<std::int64_t> ids,      // device memory, written
                  matrix_view<float> dists,           // device memory, written
                  CUstream_st* stream);               // when, and in what order
Every question a caller needs to ask is answerable from that signature: who owns each buffer (nobody here — the caller), where it lives (device), what may be written (the last two), whether anything is allocated (no), and when the results are valid (when the stream says so, not when the function returns).
Get that last one wrong and nothing complains. The lab queues a search for one batch of queries and reads the result buffer before waiting: it finds, in full, the previous batch's answers — recall 0.001 against the correct answer, no error, no warning. After wait(), recall 1.0. The memory was always real; the values were stale.
The same "when" governs allocation. Ordinary cudaFree waits for the entire device to go idle — 50 ms, in the middle of a 50 ms kernel — while its stream-ordered form returns in 27 µs. A free in a hot path can therefore serialise everything, which is why libraries allocate their scratch space once and keep it, exactly as the index does.
And it governs copies. An "async" copy from ordinary memory is not async at all: the driver has to stage it, so the call waits 42.9 ms for the card. From page-locked memory it returns in 9.6 µs and runs at 12.3 GB/s against 4.7. Neither kind of host memory is free to set up — 33 ms to allocate 64 MiB of page-locked memory, 48 ms to allocate and first-touch the same amount of ordinary memory, both of them the operating system handing out physical pages — so the staging buffer is allocated once when the index is built and reused by every call.
The top-k problem
With the distances on the GPU, the search looked finished. The first version of the index computed them two ways — one thread per (query, row) pair, or one matrix multiplication through cuBLAS — and then picked the ten smallest of each row with one block of threads per query.
Measuring it said something unwelcome: the selection cost more than the distances. For one query, 0.47 ms of top-k against 0.23 ms of distance. For a thousand queries, 26.5 ms against 7.3 ms.
Two causes, and both are things this note has already been about.
The first is that k was a run-time number. Each thread keeps a small sorted list of candidates, and with k unknown at compile time the list is indexed by a variable — so it cannot live in registers, and the compiler puts it in per-thread local memory. The CUDA compiler says so out loud at build time, if anyone is listening: the run-time-k kernel reports a 128-byte stack frame; the version with k as a template argument reports 0 bytes. Making k a template parameter for the common values and keeping the general kernel as a fallback: top-k for a thousand queries goes from 26.5 ms to 6.3 ms.
The second is that one query is one block. A block runs on one of the card's 40 multiprocessors, so a single-query search — exactly the shape of an interactive request — was using one fortieth of the GPU for its selection pass, no matter how large the database. Splitting each row into slices, giving each slice its own block, and merging the slices' candidates in a second pass: top-k for one query goes from 0.47 ms to 61 µs, a 7.8× improvement that changes no arithmetic whatsoever.
Measured the same way, back to back, the whole library call for one query went from 0.74 ms to 0.33 ms — and the same search written in PyTorch, timed in the same experiment, takes 0.47 ms. (These are the library's own stage clocks; the end-to-end figure from Python, measured in its own experiment later in the run, is in the last section.) Every variant returns identical neighbours: recall 1.0 against exact double-precision NumPy.
That is the shape of most real optimisation work. Not a rewrite: two questions — what does the compiler not know that it could? and how much of the machine is actually working? — asked of a profile rather than a hunch.
The whole library
The CPU search went through the same process, one change at a time, each measured. The first rung is what almost anyone would write first: a vector of vectors, a distance function with one running sum, and a sort of all 100,000 distances to take the first ten.
| rung | what changed | per query |
|---|---|---|
| 1 | a vector of vectors, all distances sorted | 25.9 ms |
| 2 | one contiguous block of memory | 24.3 ms |
| 3 | a heap of ten instead of the sort | 13.7 ms |
| 4 | eight partial sums (the loop vectorises) | 4.52 ms |
| 5 | four queries against each database row | 2.70 ms |
| 6 | the dimension as a template argument | 2.67 ms |
| 7 | the database walked in cache-sized blocks | 2.52 ms |
| 8 | all four hardware threads | 1.04 ms |
Twenty-five times, same language, same compiler, same answers — every rung checked against the last one and returning identical neighbours. And two of those rungs did nothing at all on this processor: the compile-time dimension and the cache blocking, both of which were worth 25% on a different machine while this note was being written. An optimisation is a claim about a machine, not about a language, and the only way to know is to measure it there.
Where did NumPy's time go, by comparison? For one query, 17.4 ms to subtract the query from the database and 14.2 ms to square the result — two 51 MB temporary arrays that exist only to be read once and thrown away. For a batch of 256 through the matrix-multiplication route: 54.5 ms in BLAS, 78.2 ms adding the norms, and 121.8 ms in argpartition. The arithmetic everyone talks about is under a quarter of the time.
A C++ library does not do those steps faster. It doesn't do them: the distance and the selection happen in one pass, with nothing written down in between. That is what "fusion" means, and it is the single biggest reason compiled kernels beat a sequence of array operations that are each individually optimal.
The same line, again
neighbors = index.search(query, k=10)Here is what that line does now, with the library's own clock at every boundary it crosses.
This is its own experiment — the median of twenty-one calls, timed from Python, with the library's stage clocks inside — and it is the one to read as the end-to-end cost. For a single query, of the 503 µs the call takes: 6 µs on the Python side, 5 µs in the binding turning arrays into views and allocating the output, 32 µs queueing the work, 354 µs computing the distances — the whole 51 MB database read once, at about 145 GB/s, something over half of what this card's memory can deliver — 104 µs selecting the ten smallest, and 9 µs bringing them back. For a thousand queries the Python side is still 35 µs and the kernels are 12 ms, which is 12.5 µs per query.
The same call was 0.33 ms of library time in the top-k experiment a few minutes earlier in the same run, against 0.49 ms of library time here. Nothing about the code changed between them; the card's clock did. It is worth saying plainly, because a benchmark that cannot be reproduced to the last digit on a shared, thermally limited card is the normal case, not a broken one — what survives across the runs are the ratios, and those were stable: the compile-time k, the split rows, the vectorised sum, the fused pass.
The layers, from the top:
Python holds an object whose search is a C++ function. The call costs the interpreter about as much as any other method call.
The binding checks that the array is float32 and C-contiguous — converting, and therefore copying, if it is not — and builds a view: a pointer, a shape, a stride, a memory space. It allocates the output arrays and releases the GIL.
The library copies the queries into its page-locked staging buffer, queues a copy to the card, the norms, one matrix multiplication and the top-k kernels on its stream, and queues the results coming back. Then it waits.
The card runs the kernels in stream order: the queries arrive, cuBLAS produces a Q × 100,000 matrix of dot products, and the selection kernels turn each row into ten ids — with the dimension, the metric and k all compiled in, on lists that live in registers, spread across enough blocks to keep 40 multiprocessors busy.
Back up: ten ids and ten distances per query cross PCIe, are copied out of the staging buffer into the NumPy arrays the binding made, and are handed to Python, which sees a tuple of two arrays.
The only thing allocated per call in that path is the pair of NumPy arrays the caller is handed; the database, the staging buffers and the scratch space were allocated once, when the index was built. Nothing is copied that does not have to be. Nothing is decided at run time that could have been decided at compile time. And the single line of Python at the top is, by a wide margin, the cheapest thing in the picture.
What this is really about
The reason high-performance ML libraries are written in C++ is not that C++ is fast. NumPy beat hand-written C++ in the first measurement of this note, and PyTorch beat the library's first GPU version in the last one. Speed comes from what the machine is asked to do, not from the syntax it is asked in.
What C++ provides is the vocabulary for saying things the machine needs to know and Python has no way to express:
- where the data is — one contiguous block, this many rows, this stride, host or device;
- who owns it — this object, until its destructor runs; everyone else gets a view;
- how long it lives — tied to a scope, not to a garbage collector's opinion;
- how it is laid out — fields in this order, arrays split this way, aligned to a cache line;
- what can be decided before the program runs — the metric, the element type, the dimension,
k; - and when things happen — this stream, in this order, and the call returning is not the work finishing.
Each of those is a promise the compiler and the hardware can use. Together they are the difference between 1.2 seconds and 18 microseconds — and, more to the point, they are what any of the fast paths in your own stack are made of, whether or not you ever write a line of C++ yourself.
The next time a model is slower than it should be, the question to ask is one of those six.