Lab · runnable experiments
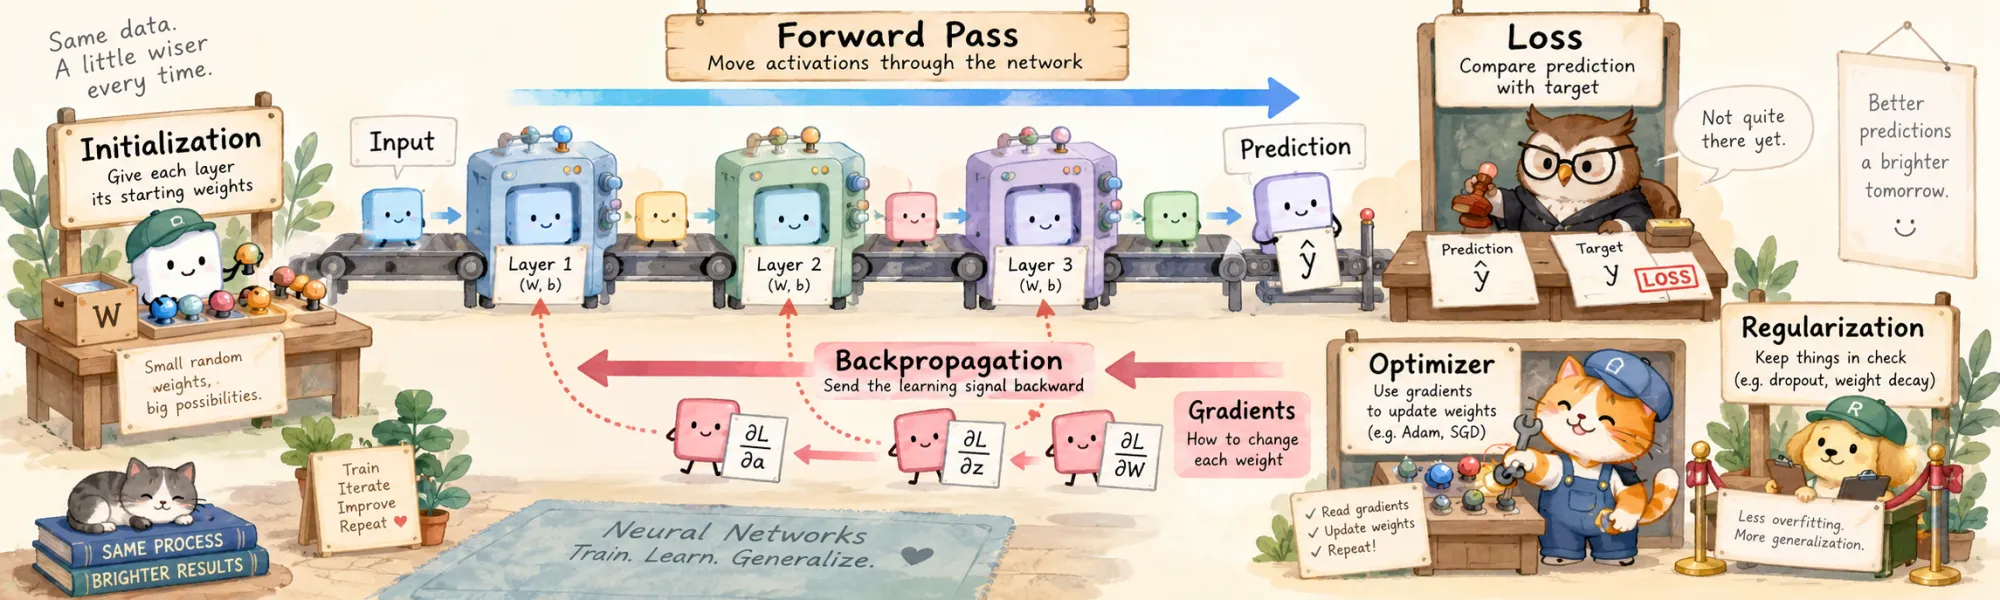
Training Neural Networks: Backprop, Regularization, and Everything in Between
Created Aug 31, 2026 Updated Sep 12, 2026
Read the parent noteThe note argues that training is one accounting problem: a single number at the end has to become an instruction for every number inside. This lab runs every experiment behind that argument, and it is the only place the note’s numbers come from — the widgets on the note page are drawn from the results this notebook writes out at the end.
Part 1 builds backpropagation from nothing: the XOR problem that made it necessary, the note’s two-weight example by hand, a full MLP whose backward pass is written out in numpy and checked against autograd and against central differences, and the price of a gradient measured against the alternative. Part 2 is where the signal dies: gradient flow through forty layers, initialization at two depths, how much of a gradient fp16 can represent, and what training memory is made of. Part 3 is the optimizer’s half: the stability threshold, learning-rate schedules, Adam’s first steps, what clipping catches, normalization, regularization, and the choice of loss.
Where a measurement contradicted the tidy story, the measurement is what is printed.
Setup
pip install torch torchvision numpy pandas matplotlibimport time, datetime, math, json, pathlib
import numpy as np, pandas as pd, torch, torch.nn as nn, torch.nn.functional as F
import matplotlib.pyplot as plt
from torchvision import datasets, transforms
torch.manual_seed(0); np.random.seed(0)
device = "cpu" # everything here is small; CPU keeps the timings comparable
INK, LINE, CREAM = "#2a2a2a", "#d9d3c7", "#f6f2e9"
BLUE, EMBER, FOREST, GRAY, PLUM = "#3b6ea5", "#c4521e", "#2e7d5b", "#9a9384", "#7a4f8c"
plt.rcParams.update({"font.size": 9, "axes.edgecolor": LINE, "axes.spines.top": False,
"axes.spines.right": False, "figure.dpi": 120})
RESULTS = {} # everything the note's widgets are drawn from
SEEDS = 5
print("executed:", datetime.date.today().isoformat(), " torch", torch.__version__,
" CPU threads", torch.get_num_threads())executed: 2026-09-12 torch 2.7.1 CPU threads 12# MNIST, standardized and flattened, cached per size
DATA = "scripts/.cache/mnist"
_tf = transforms.ToTensor()
_tr = datasets.MNIST(DATA, train=True, download=True, transform=_tf)
_te = datasets.MNIST(DATA, train=False, download=True, transform=_tf)
_cache = {}
def mnist(n_train, n_test=2000, seed=0):
if (n_train, n_test) in _cache:
return _cache[(n_train, n_test)]
g = torch.Generator().manual_seed(seed)
idx = torch.randperm(len(_tr), generator=g)[:n_train]
xtr = torch.stack([_tr[i][0] for i in idx]).reshape(len(idx), -1)
ytr = torch.tensor([_tr[i][1] for i in idx])
xte = torch.stack([_te[i][0] for i in range(n_test)]).reshape(n_test, -1)
yte = torch.tensor([_te[i][1] for i in range(n_test)])
mu, sd = xtr.mean(), xtr.std()
_cache[(n_train, n_test)] = ((xtr - mu) / sd, ytr, (xte - mu) / sd, yte)
return _cache[(n_train, n_test)]
X_TR, Y_TR, X_TE, Y_TE = mnist(6000)
print("train", tuple(X_TR.shape), " test", tuple(X_TE.shape))train (6000, 784) test (2000, 784)Most experiments below share one network and one training loop, so they are written once. Stack is a plain MLP with every knob the note talks about exposed — activation, initialization, normalization before or after the residual add, dropout. train is an ordinary minibatch loop that records train loss, train accuracy and test accuracy after every epoch.
ACTS = {"relu": torch.relu, "tanh": torch.tanh, "sigmoid": torch.sigmoid}

def init_(w, kind):
    d_out, d_in = w.shape
    with torch.no_grad():
        if kind == "zeros":    w.zero_()
        elif kind == "normal": w.normal_(0.0, 1.0)                        # naive N(0, 1)
        elif kind == "small":  w.normal_(0.0, 0.01)                       # "just make it small"
        elif kind == "xavier": w.normal_(0.0, math.sqrt(1.0 / d_in))      # forward-only 1/d_in
        elif kind == "he":     w.normal_(0.0, math.sqrt(2.0 / d_in))
        else: raise ValueError(kind)

class Stack(nn.Module):
    def __init__(self, d_in, d_out, depth, width, act="relu", init="he",
                 norm=None, residual=False, dropout=0.0, pre_norm=True):
        super().__init__()
        self.act, self.residual, self.pre_norm, self.dropout = ACTS[act], residual, pre_norm, dropout
        dims = [d_in] + [width] * depth
        self.hidden = nn.ModuleList([nn.Linear(dims[i], dims[i + 1]) for i in range(depth)])
        self.head = nn.Linear(width, d_out)
        Norm = {"bn": nn.BatchNorm1d, "ln": nn.LayerNorm}.get(norm)
        self.norms = nn.ModuleList([Norm(width) for _ in range(depth)]) if Norm else None
        for lin in list(self.hidden) + [self.head]:
            init_(lin.weight, init); nn.init.zeros_(lin.bias)

    def forward(self, x):
        for i, lin in enumerate(self.hidden):
            z = x
            if self.norms is not None and self.pre_norm and z.shape[-1] == lin.out_features:
                z = self.norms[i](z)                                      # pre-norm: x + f(Norm(x))
            h = self.act(lin(z))
            if self.dropout:
                h = F.dropout(h, self.dropout, self.training)
            x = x + h if (self.residual and x.shape == h.shape) else h
            if self.norms is not None and not self.pre_norm and x.shape[-1] == lin.out_features:
                x = self.norms[i](x)                                      # post-norm: Norm(x + f(x))
        return self.head(x)

def shift(x, g):
    """Random ±2-pixel translation of a flattened MNIST batch."""
    dx, dy = torch.randint(-2, 3, (2,), generator=g).tolist()
    return torch.roll(x.reshape(-1, 28, 28), (dy, dx), (1, 2)).reshape(len(x), -1)

def train(model, xtr, ytr, xte, yte, epochs=20, bs=128, lr=1e-3, opt="adam", wd=0.0,
          decoupled=True, seed=0, sched=None, warmup=0, aug=False):
    g = torch.Generator().manual_seed(seed)
    Opt = (torch.optim.AdamW if decoupled else torch.optim.Adam) if opt == "adam" else torch.optim.SGD
    optim = Opt(model.parameters(), lr=lr, weight_decay=wd)
    steps_per_epoch = max(1, len(xtr) // bs)
    total, step = epochs * steps_per_epoch, 0
    hist = {"train_loss": [], "train_acc": [], "test_acc": []}
    for _ in range(epochs):
        model.train()
        perm = torch.randperm(len(xtr), generator=g)
        for b in range(steps_per_epoch):
            idx = perm[b * bs:(b + 1) * bs]
            xb, yb = xtr[idx], ytr[idx]
            if aug:
                xb = shift(xb, g)
            scale = 1.0
            if warmup and step < warmup:
                scale = (step + 1) / warmup
            elif sched == "cosine":
                scale = 0.5 * (1 + math.cos(math.pi * min(1.0, (step - warmup) / max(1, total - warmup))))
            for group in optim.param_groups:
                group["lr"] = lr * scale
            loss = F.cross_entropy(model(xb), yb)
            optim.zero_grad(set_to_none=True); loss.backward(); optim.step()
            step += 1
        model.eval()
        with torch.no_grad():
            out_tr = model(xtr)
            hist["train_loss"].append(F.cross_entropy(out_tr, ytr).item())
            hist["train_acc"].append((out_tr.argmax(1) == ytr).float().mean().item())
            hist["test_acc"].append((model(xte).argmax(1) == yte).float().mean().item())
    return hist

def across(hs, key, fn):
    """Per-epoch statistic across seeds."""
    return [float(fn(v)) for v in zip(*[h[key] for h in hs])]
Part 1 — backpropagation, built and checked
A rule for one layer: the perceptron on XOR
The perceptron rule nudges every weight by η (y − ŷ) x whenever the unit is wrong. It needs a target for the unit it updates, which is why it only works for one layer — and on one layer it can only draw a straight line. XOR has no such line. Below: the rule on XOR, the same rule on AND (which a line can separate), and a 2-2-1 network trained by backpropagation on the same four points, from five random starts.
X4 = torch.tensor([[0., 0.], [0., 1.], [1., 0.], [1., 1.]])
y_xor, y_and = torch.tensor([0., 1., 1., 0.]), torch.tensor([0., 0., 0., 1.])

def perceptron(y, epochs=60, seed=0):
    g = torch.Generator().manual_seed(seed)
    w, b = torch.randn(2, generator=g) * 0.5, torch.zeros(())
    acc, traj = [], []
    for _ in range(epochs):
        for i in range(4):
            err = y[i] - (1.0 if X4[i] @ w + b > 0 else 0.0)
            w, b = w + 0.1 * err * X4[i], b + 0.1 * err
        acc.append(float((((X4 @ w + b) > 0).float() == y).float().mean()))
        traj.append([round(float(w[0]), 4), round(float(w[1]), 4), round(float(b), 4)])
    return acc, traj

def mlp_xor(seed, epochs=600):
    torch.manual_seed(seed)
    net = nn.Sequential(nn.Linear(2, 2), nn.Tanh(), nn.Linear(2, 1))
    opt = torch.optim.Adam(net.parameters(), lr=0.1)
    curve, solved = [], -1
    for ep in range(epochs):
        p = net(X4).squeeze(1)
        loss = F.binary_cross_entropy_with_logits(p, y_xor)
        opt.zero_grad(); loss.backward(); opt.step()
        if solved < 0 and bool((((p > 0).float()) == y_xor).all()):
            solved = ep
        curve.append(round(float(loss), 5))
    return curve, solved

xor_acc, xor_traj = perceptron(y_xor)
and_acc, and_traj = perceptron(y_and)
mlp = [mlp_xor(s) for s in range(SEEDS)]
RESULTS["nn-train-xor"] = {
    "points": X4.tolist(), "labels_xor": y_xor.tolist(), "labels_and": y_and.tolist(),
    "perceptron_xor_acc": xor_acc, "perceptron_xor_weights": xor_traj,
    "perceptron_and_acc": and_acc, "perceptron_and_weights": and_traj,
    "mlp_loss_curves": [c for c, _ in mlp], "mlp_epochs_to_solve": [s for _, s in mlp],
    "note": f"perceptron: 60 epochs over the 4 points, lr 0.1. mlp: 2-2-1 tanh, Adam 0.1, {SEEDS} seeds.",
}
cycle_from = next((i for i in range(1, len(xor_traj)) if all(t == xor_traj[i] for t in xor_traj[i:])), None)
print(f"perceptron on XOR: best accuracy {max(xor_acc):.0%}, final {xor_acc[-1]:.0%}; " +
      (f"from epoch {cycle_from + 1} the end-of-epoch weights never change again" if cycle_from is not None
       else "the end-of-epoch weights keep changing"))
print("perceptron on AND: " + (f"100% from epoch {and_acc.index(1.0) + 1}" if 1.0 in and_acc else "never 100%"))
print("2-2-1 net by backprop, epoch at which all four points are right, per seed:",
      [s if s >= 0 else "not solved in 600" for _, s in mlp])
perceptron on XOR: best accuracy 75%, final 25%; from epoch 10 the end-of-epoch weights never change again
perceptron on AND: 100% from epoch 6
2-2-1 net by backprop, epoch at which all four points are right, per seed: [37, 'not solved in 600', 24, 45, 46]The perceptron on XOR peaks at 75% early, then settles at 25% — worse than guessing — and from the tenth epoch its end-of-epoch weights repeat exactly: a cycle, not a failure to converge. The same rule on AND reaches 100% in six epochs. The 2-2-1 network trained by backprop solves XOR in 24 to 46 epochs on four of five starts, and not at all within 600 on the fifth: two hidden units is a tight budget, and where the weights start decides whether it is enough.
The worked example, by hand
The note’s entire model is two multiplications: h = xw1, ŷ = hw2, L = (ŷ − y)2. No framework, no autograd — just the chain rule written out, so there is nothing to take on trust.
x, w1, w2, y = 2.0, 3.0, 4.0, 20.0

h     = x * w1
yhat  = h * w2
L     = (yhat - y) ** 2

dL_dyhat = 2 * (yhat - y)      # the loss function, and the only place it appears
dL_dw2   = dL_dyhat * h        # chain: what came back, times what came in
dL_dh    = dL_dyhat * w2       # one station further back
dL_dw1   = dL_dh * x

print(f"forward :  h={h}  yhat={yhat}  L={L}")
print(f"backward:  dL/dyhat={dL_dyhat}  dL/dw2={dL_dw2}  dL/dh={dL_dh}  dL/dw1={dL_dw1}")

eta = 0.01
w1_new, w2_new = w1 - eta * dL_dw1, w2 - eta * dL_dw2
h2 = x * w1_new; yhat2 = h2 * w2_new
print(f"update  :  w1 {w1} -> {w1_new:.4f}   w2 {w2} -> {w2_new:.4f}")
print(f"after   :  yhat={yhat2:.4f}  L={(yhat2 - y) ** 2:.4f}   (was {L})")
forward : h=6.0 yhat=24.0 L=16.0
backward: dL/dyhat=8.0 dL/dw2=48.0 dL/dh=32.0 dL/dw1=64.0
update : w1 3.0 -> 2.3600 w2 4.0 -> 3.5200
after : yhat=16.6144 L=11.4623 (was 16.0)One update, and the loss falls from 16 to 11.5. Nothing told the model that w1w2 = 5 would be perfect; it knew how wrong it was and what the local slope looked like.
The same thing, with autograd, to the last decimal
tw1 = torch.tensor(3.0, requires_grad=True)
tw2 = torch.tensor(4.0, requires_grad=True)
tL = (torch.tensor(2.0) * tw1 * tw2 - torch.tensor(20.0)) ** 2
tL.backward()
print(f"autograd:  dL/dw1={tw1.grad.item()}  dL/dw2={tw2.grad.item()}")
print(f"by hand :  dL/dw1={dL_dw1}  dL/dw2={dL_dw2}")
assert (tw1.grad.item(), tw2.grad.item()) == (dL_dw1, dL_dw2)
autograd: dL/dw1=64.0 dL/dw2=48.0
by hand : dL/dw1=64.0 dL/dw2=48.0A whole MLP’s backward pass, written out
Two multiplications are easy to believe. The claim worth testing is that nothing changes at scale — that a real network’s backward pass is the same three lines per layer, ∂L/∂W = δx⊤, ∂L/∂b = δ, ∂L/∂x = W⊤δ, repeated. Here is a three-layer network with the backward pass written by hand in numpy, checked against PyTorch.
rng = np.random.default_rng(0)
dims = [20, 16, 12, 3]
Ws = [rng.normal(0, np.sqrt(2 / dims[i]), (dims[i + 1], dims[i])) for i in range(3)]
bs = [np.zeros(dims[i + 1]) for i in range(3)]
xb = rng.normal(size=(8, dims[0]))
yb = rng.integers(0, 3, size=8)

def forward_np(Ws, bs, x):
    acts, zs = [x], []
    for i, (W, b) in enumerate(zip(Ws, bs)):
        z = acts[-1] @ W.T + b
        zs.append(z)
        acts.append(np.maximum(z, 0) if i < len(Ws) - 1 else z)   # ReLU except the head
    return acts, zs

def softmax_ce(logits, y):
    m = logits.max(1, keepdims=True)
    p = np.exp(logits - m); p /= p.sum(1, keepdims=True)
    n = len(y)
    return -np.log(p[np.arange(n), y] + 1e-12).mean(), p

acts, zs = forward_np(Ws, bs, xb)
loss_np, probs = softmax_ce(acts[-1], yb)

# backward, by hand: start at the loss, walk left
onehot = np.zeros_like(probs); onehot[np.arange(len(yb)), yb] = 1
delta = (probs - onehot) / len(yb)          # the softmax+CE boundary condition: p - y
gW, gb = [None] * 3, [None] * 3
for i in reversed(range(3)):
    gW[i] = delta.T @ acts[i]               # dL/dW = delta * (what came in)
    gb[i] = delta.sum(0)
    if i > 0:
        delta = (delta @ Ws[i]) * (zs[i - 1] > 0)   # back through W^T, then through ReLU

# the same network in torch
tWs = [torch.tensor(W, requires_grad=True) for W in Ws]
tbs = [torch.tensor(b, requires_grad=True) for b in bs]
a = torch.tensor(xb)
for i in range(3):
    a = a @ tWs[i].T + tbs[i]
    if i < 2:
        a = torch.relu(a)
loss_t = F.cross_entropy(a, torch.tensor(yb))
loss_t.backward()

print(f"loss  numpy {loss_np:.10f}   torch {loss_t.item():.10f}")
for i in range(3):
    dW = np.abs(gW[i] - tWs[i].grad.numpy()).max()
    db = np.abs(gb[i] - tbs[i].grad.numpy()).max()
    print(f"layer {i}:  max |dW diff| {dW:.2e}   max |db diff| {db:.2e}")
loss numpy 1.0449740881 torch 1.0449740881
layer 0: max |dW diff| 2.78e-17 max |db diff| 2.78e-17
layer 1: max |dW diff| 2.78e-17 max |db diff| 1.73e-18
layer 2: max |dW diff| 5.55e-17 max |db diff| 5.55e-17Agreement to floating-point noise. The backward pass is not a special algorithm the framework knows and you do not; it is those three lines, per layer, in reverse.
The gradient check: is the derivative even right?
Autograd agreeing with the numpy version only proves the same mistake could have been made twice. The independent check is the definition of a derivative — nudge a parameter by ε in both directions and measure. Central differences are accurate to O(ε2), so in float64 the relative error against backprop should be tiny; how tiny depends on ε and on how much cancellation the subtraction suffers.
def loss_at(Ws, bs, x, y):
    acts, _ = forward_np(Ws, bs, x)
    return softmax_ce(acts[-1], y)[0]

eps = 1e-6
rows = []
for i in range(3):
    for _ in range(4):
        r, c = rng.integers(0, Ws[i].shape[0]), rng.integers(0, Ws[i].shape[1])
        up = [W.copy() for W in Ws]; up[i][r, c] += eps
        dn = [W.copy() for W in Ws]; dn[i][r, c] -= eps
        numeric = (loss_at(up, bs, xb, yb) - loss_at(dn, bs, xb, yb)) / (2 * eps)
        analytic = gW[i][r, c]
        rel = abs(numeric - analytic) / max(1e-12, abs(numeric) + abs(analytic))
        rows.append({"layer": i, "weight": f"[{r},{c}]", "finite difference": numeric,
                     "backprop": analytic, "relative error": rel})
chk = pd.DataFrame(rows)
print(chk.to_string(index=False, float_format=lambda v: f"{v: .3e}"))
print(f"\nworst relative error: {chk['relative error'].max():.2e}")
layer weight finite difference backprop relative error
0 [2,9] 2.431e-02 2.431e-02 6.231e-11
0 [11,14] -6.815e-02 -6.815e-02 5.990e-10
0 [0,11] 3.916e-02 3.916e-02 1.158e-09
0 [1,19] -4.530e-02 -4.530e-02 2.099e-10
1 [6,6] 2.021e-02 2.021e-02 2.145e-09
1 [4,15] -1.461e-01 -1.461e-01 3.599e-10
1 [8,6] 0.000e+00 0.000e+00 0.000e+00
1 [8,2] -4.480e-02 -4.480e-02 1.058e-10
2 [1,9] -2.249e-02 -2.249e-02 3.427e-09
2 [2,3] -8.275e-02 -8.275e-02 3.504e-10
2 [1,6] 3.120e-01 3.120e-01 5.356e-11
2 [2,7] -2.021e-01 -2.021e-01 4.917e-11
worst relative error: 3.43e-09What a gradient costs, and what the alternative costs
The central differences above cost two forward passes per parameter. The cheapest possible version — one-sided, (L(w + ε) − L(w))/ε — costs one per parameter plus one shared baseline, so it is the figure used below: a lower bound on what training without backpropagation would cost.
Two more things are measured on the same networks. The first is what the backward pass costs on its own and together with the forward pass it needs. The second is how much memory autograd actually keeps for the backward pass: every tensor it saves is intercepted with saved_tensors_hooks, each storage is counted once, and the weights themselves are excluded, since they exist whether or not anyone trains.
The extrapolation to 108 parameters is not extrapolated from a small network’s forward pass: a 100-million-parameter MLP is built and its forward pass timed.
def timeit(fn, reps=30):
    fn(); fn()
    t0 = time.perf_counter()
    for _ in range(reps):
        fn()
    return (time.perf_counter() - t0) / reps * 1e3                    # ms

def saved_for_backward(fn, params):
    """Bytes autograd saves for backward while fn() runs; each storage once, parameters excluded."""
    skip = {p.untyped_storage().data_ptr() for p in params}
    seen, total = set(), 0
    def pack(t):
        nonlocal total
        s = t.untyped_storage()
        if s.data_ptr() not in skip and s.data_ptr() not in seen:
            seen.add(s.data_ptr()); total += s.nbytes()
        return t
    with torch.autograd.graph.saved_tensors_hooks(pack, lambda t: t):
        fn()
    return total

xtr_c, ytr_c, _, _ = mnist(1024)
xb_c, yb_c = xtr_c[:128].clone(), ytr_c[:128].clone()

def measure_cost(width, depth, reps=30, fd_sample=200):
    torch.manual_seed(0)
    net = Stack(784, 10, depth, width)
    n_params = sum(p.numel() for p in net.parameters())
    def fwd():
        with torch.no_grad():
            F.cross_entropy(net(xb_c), yb_c)
    def fwd_bwd():
        loss = F.cross_entropy(net(xb_c), yb_c)
        net.zero_grad(set_to_none=True); loss.backward()
    t_f, t_fb = timeit(fwd, reps), timeit(fwd_bwd, reps)
    t_sample = timeit(fwd, fd_sample)                                 # forward passes as finite differences run them
    saved = saved_for_backward(lambda: F.cross_entropy(net(xb_c), yb_c), net.parameters())
    return {"params": n_params, "forward_ms": round(t_f, 4), "forward_backward_ms": round(t_fb, 4),
            "backward_over_forward": round((t_fb - t_f) / t_f, 3),
            "train_step_over_forward": round(t_fb / t_f, 3),
            "finite_diff_ms": round(t_sample * (n_params + 1), 1),
            "finite_diff_over_backward": round(t_sample * (n_params + 1) / t_fb, 1),
            "activation_bytes": saved, "param_bytes": n_params * 4}

cost_rows = [measure_cost(w, d) for w, d in [(32, 2), (128, 3), (512, 4), (1024, 6)]]
huge = measure_cost(4400, 6, reps=5, fd_sample=5)
cost = pd.DataFrame(cost_rows + [huge])
cost["finite differences (h)"] = cost.finite_diff_ms / 3.6e6
print(cost[["params", "forward_ms", "forward_backward_ms", "backward_over_forward", "train_step_over_forward",
            "finite differences (h)", "activation_bytes", "param_bytes"]].to_string(
      index=False, float_format=lambda v: f"{v: .3f}"))

RESULTS["nn-train-cost"] = {
    "rows": cost_rows,
    "extrapolation": {"params": huge["params"], "forward_ms": huge["forward_ms"],
                      "forward_backward_ms": huge["forward_backward_ms"],
                      "finite_diff_hours": round(huge["finite_diff_ms"] / 3.6e6, 1),
                      "finite_diff_hours_central": round(2 * huge["finite_diff_ms"] / 3.6e6, 1),
                      "basis": "a 6x4400 MLP (about 1e8 parameters) built and its forward pass timed; "
                               "one-sided differences, one forward pass per parameter plus one"},
    "note": "batch 128 of MNIST, CPU. Finite differences: one-sided, from timed forward passes. "
            "Activation bytes: tensors autograd saves for backward, parameters excluded.",
}
big = cost_rows[-1]
print(f"\none-sided finite differences at {big['params']:,} params: {big['finite_diff_ms'] / 3.6e6:.1f} h "
      f"(central, as in the check above: {2 * big['finite_diff_ms'] / 3.6e6:.1f} h); "
      f"backpropagation: {big['forward_backward_ms']:.1f} ms for forward and backward together")
print(f"at {huge['params']:,} params: one forward pass {huge['forward_ms']:.0f} ms, so one-sided finite "
      f"differences take {huge['finite_diff_ms'] / 3.6e6:,.0f} h per update "
      f"({huge['finite_diff_ms'] / 8.64e7:.0f} days); forward + backward takes {huge['forward_backward_ms']:.0f} ms")
params forward_ms forward_backward_ms backward_over_forward train_step_over_forward finite differences (h) activation_bytes param_bytes
26506 0.117 0.321 1.751 2.751 0.001 440324 106024
134794 0.197 0.469 1.383 2.383 0.007 604164 539176
1195018 0.930 2.524 1.714 2.714 0.333 1456132 4780072
6062090 2.630 7.884 1.998 2.998 4.634 3553284 24248360
100320010 18.420 65.962 2.581 3.581 507.237 13924356 401280040
one-sided finite differences at 6,062,090 params: 4.6 h (central, as in the check above: 9.3 h); backpropagation: 7.9 ms for forward and backward together
at 100,320,010 params: one forward pass 18 ms, so one-sided finite differences take 507 h per update (21 days); forward + backward takes 66 msOn the four small networks the backward pass alone costs 1.4 to 2.0 forward passes, and a full forward-and-backward step 2.4 to 3.0 — a constant factor, not something that grows with the parameter count; the hundred-million-parameter network lands at 3.6. Finite differences grow with the parameter count instead: at 6 million parameters, one one-sided gradient takes 4.6 hours (9.3 with the central differences used in the check above) against 8 milliseconds for backpropagation. At 108 parameters the forward pass alone is 18 ms, so one update by finite differences is about 500 hours — three weeks.
The memory column says the same thing about space: at batch 128, what autograd keeps for the backward pass is 3.6 MB on the 6-million-parameter network, next to 24 MB of weights.
(Wall-clock numbers depend on the machine and on what else it is doing; the ratios are what transfer, not the milliseconds.)
Part 2 — where the signal dies
Forty layers, one backward pass
The gradient reaching layer ℓ is a product of the Jacobians above it. Below is that product, measured: gradient norm at every hidden layer of a 40-layer, 128-wide network on a real MNIST batch of 256, in float64 so that twenty orders of magnitude stay legible — for three activations, three initialization scales, with and without residual connections, each from five random initializations. The chart shows the median across the five.
torch.set_default_dtype(torch.float64)
xg, yg = mnist(512)[0][:256].double(), mnist(512)[1][:256]
DEPTH, WIDTH = 40, 128
series = {}
for act in ["sigmoid", "tanh", "relu"]:
    for init in ["small", "xavier", "he"]:
        for res in [False, True]:
            norms = []
            for seed in range(SEEDS):
                torch.manual_seed(seed)
                net = Stack(784, 10, DEPTH, WIDTH, act=act, init=init, residual=res)
                loss = F.cross_entropy(net(xg), yg)
                net.zero_grad(set_to_none=True); loss.backward()
                norms.append([float(l.weight.grad.norm()) for l in net.hidden])
            arr = np.array(norms)
            series[f"{act}|{init}|{'res' if res else 'plain'}"] = {
                "median": np.median(arr, 0).tolist(),
                "p10": np.percentile(arr, 10, 0).tolist(), "p90": np.percentile(arr, 90, 0).tolist()}
torch.set_default_dtype(torch.float32)
RESULTS["nn-train-gradflow"] = {"depth": DEPTH, "width": WIDTH, "seeds": SEEDS, "series": series,
    "note": "gradient norm at each hidden layer, one backward pass on a real MNIST batch of 256, float64."}

show = {"relu · He": "relu|he|plain", "relu · 1/d_in": "relu|xavier|plain", "sigmoid · He": "sigmoid|he|plain",
        "relu · N(0, 0.01)": "relu|small|plain", "relu · He · residual": "relu|he|res"}
fig, ax = plt.subplots(figsize=(7, 3.6))
for label, key in show.items():
    ax.semilogy(range(1, DEPTH + 1), np.maximum(series[key]["median"], 1e-70), label=label, lw=1.8)
ax.axhspan(1e-2, 1e1, color=FOREST, alpha=.07)
ax.set_xlabel("layer  (1 = nearest the input)"); ax.set_ylabel("gradient norm (median of 5)")
ax.legend(fontsize=7.5, frameon=False); plt.tight_layout(); plt.show()

# layer 1 reads the 784 raw pixels, so the comparison starts at layer 2, the first 128-in, 128-out layer
print(pd.DataFrame([{"configuration": label, "layer 2": series[key]["median"][1],
                     "layer 40": series[key]["median"][-1]} for label, key in show.items()]
                   ).to_string(index=False, float_format=lambda v: f"{v: .2e}"))
he, fwd_only = series["relu|he|plain"]["median"], series["relu|xavier|plain"]["median"]
print(f"\nHe against 1/d_in at layer 2: {he[1] / fwd_only[1]:,.0f}x;  the arithmetic, one factor of 2 "
      f"in variance per ReLU layer over forty layers: 2^20 = {2 ** 20:,}")
       configuration   layer 2  layer 40
           relu · He  6.99e-01  1.10e+00
       relu · 1/d_in  5.36e-07  2.69e-07
        sigmoid · He  5.03e-20  4.71e-01
   relu · N(0, 0.01)  1.85e-44  9.28e-45
relu · He · residual  7.25e+08  5.54e+09

He against 1/d_in at layer 2: 1,304,223x;  the arithmetic, one factor of 2 in variance per ReLU layer over forty layers: 2^20 = 1,048,576
The sigmoid stack loses nineteen orders of magnitude between the top of the network and the bottom. The forward-only 1/din initialization costs about 1.3 million against He at layer 2 — the arithmetic predicts 220 ≈ 1.05 million, one factor of two per ReLU layer compounded over forty, and the measurement lands within 25% of it. And the residual stack, with no normalization anywhere, does not vanish: it explodes, because adding x to f(x) adds their variances too.
Initialization: the constant that does nothing, until it does
The same ReLU network, 128 wide, at depth 8 and depth 40, trained on 6,000 MNIST digits for 15 epochs with AdamW, from four initializations and three seeds each. xavier here is the forward-only 1/din, not Glorot’s 2/(din + dout): in the square hidden layers the two are identical, at the 784-wide input they are not, so it is labelled by what it actually is.
by_depth = {}
rows = []
for depth in [8, 40]:
    runs = {}
    for init in ["zeros", "normal", "xavier", "he"]:
        hs = []
        for seed in range(3):
            torch.manual_seed(seed)
            hs.append(train(Stack(784, 10, depth, 128, init=init), X_TR, Y_TR, X_TE, Y_TE, epochs=15, seed=seed))
        runs[init] = {"test_acc_mean": across(hs, "test_acc", np.mean),
                      "test_acc_std": across(hs, "test_acc", np.std),
                      "train_loss_mean": across(hs, "train_loss", np.mean)}
        rows.append({"depth": depth, "init": init, "test accuracy": runs[init]["test_acc_mean"][-1],
                     "± across seeds": runs[init]["test_acc_std"][-1],
                     "first-epoch train loss": runs[init]["train_loss_mean"][0],
                     "final train loss": runs[init]["train_loss_mean"][-1]})
    by_depth[str(depth)] = runs
print(pd.DataFrame(rows).to_string(index=False, float_format=lambda v: f"{v: .4g}"))

torch.manual_seed(0)
znet = Stack(784, 10, 8, 128, init="zeros")
ranks = []
for ep in range(6):
    W0 = znet.hidden[0].weight.detach()
    ranks.append({"epoch": ep, "rank": int(torch.linalg.matrix_rank(W0)), "distinct_rows": len(torch.unique(W0, dim=0))})
    train(znet, X_TR, Y_TR, X_TE, Y_TE, epochs=1, seed=ep)
RESULTS["nn-train-init"] = {"runs": by_depth["8"], "by_depth": by_depth, "zero_init_symmetry": ranks,
    "arch": "128-wide ReLU MLP at depth 8 and depth 40, MNIST 6000 train / 2000 test, AdamW lr 1e-3, 15 epochs, 3 seeds"}
depth init test accuracy ± across seeds first-epoch train loss final train loss
8 zeros 0.117 0 2.302 2.3
8 normal 0.5468 0.01719 8.098e+07 1.818e+06
8 xavier 0.9175 0.001472 0.412 0.03035
8 he 0.9153 0.006276 0.3963 0.02653
40 zeros 0.117 0 2.302 2.3
40 normal 0.1015 0.01206 inf inf
40 xavier 0.6413 0.1261 2.233 0.8344
40 he 0.7437 0.03494 1.826 0.7096At eight layers xavier (1/din) and He are a dead heat: 91.8% ± 0.1 against 91.5% ± 0.6. At forty layers the same two constants are ten points apart, 64.1% against 74.4%. Naive N(0, 1) starts with a training loss near 8 × 10⁷ at depth 8 and claws back to 55%; at depth 40 its forward pass overflows float32 on the first step and every loss in the run is infinite. Zero initialization sits at 11.7% at both depths.
Zero initialization deserves its own look, because the usual explanation — identical units get identical gradients — accounts for the units staying identical, not for them staying at zero.
W0 = znet.hidden[0].weight.detach()
print(f"first layer under zero init after {len(ranks)} epochs: rank {int(torch.linalg.matrix_rank(W0))}, "
      f"distinct rows {len(torch.unique(W0, dim=0))}")
with torch.no_grad():
    pred = znet(X_TE).argmax(1)
top = torch.bincount(Y_TE).argmax().item()
print(f"it predicts class {pred.unique().tolist()} for every test image; "
      f"class {top} is {(Y_TE == top).float().mean():.4f} of the test set")

# is it ReLU'(0) = 0? tanh has derivative 1 at zero, so if the weights still get no
# gradient under tanh, the activation is not the reason
for act in (nn.ReLU, nn.Tanh):
    net = nn.Sequential(nn.Linear(784, 64), act(), nn.Linear(64, 64), act(), nn.Linear(64, 10))
    for m in net:
        if isinstance(m, nn.Linear):
            nn.init.zeros_(m.weight); nn.init.zeros_(m.bias)
    F.cross_entropy(net(X_TR[:256]), Y_TR[:256]).backward()
    gw = [f"{m.weight.grad.abs().max():.1e}" for m in net if isinstance(m, nn.Linear)]
    gb = [f"{m.bias.grad.abs().max():.1e}" for m in net if isinstance(m, nn.Linear)]
    print(f"  {act.__name__:<5} max |dW| per layer {gw}   max |db| per layer {gb}")
first layer under zero init after 6 epochs: rank 0, distinct rows 1
it predicts class [1] for every test image; class 1 is 0.1170 of the test set
ReLU max |dW| per layer ['0.0e+00', '0.0e+00', '0.0e+00'] max |db| per layer ['0.0e+00', '0.0e+00', '4.8e-02']
Tanh max |dW| per layer ['0.0e+00', '0.0e+00', '0.0e+00'] max |db| per layer ['0.0e+00', '0.0e+00', '4.8e-02']The reason is blunter than symmetry. With every weight zero, every layer’s input is zero, so each weight gradient δ x⊤ is zero; and every error signal sent further back, W⊤δ, is zero as well. Exactly one set of numbers ever moves — the output layer’s bias — so the network learns the class frequencies and nothing else, answering the most common digit for every image. The tanh row settles that it has nothing to do with ReLU’s derivative at zero. And the zero biases are not the problem: they start at zero in every network in this lab. Zero weights are.
How much of a gradient fp16 can represent
Half precision has a narrow exponent range, and a gradient that shrinks exponentially with depth is exactly the quantity that falls out of the bottom of it. The test: take every individual weight gradient of the 40-layer sigmoid stack above (He initialization, seed 0), computed in float64, multiply by a loss scale, cast to each format, and count what is left — values that are still non-zero and finite, since a loss scale large enough to lift the smallest gradients also pushes the largest ones past the format’s maximum.
This is an optimistic test. A real fp16 backward pass would also round the intermediate error signals on the way down, so the damage there can only be larger than what a single cast at the end shows.
torch.set_default_dtype(torch.float64)
torch.manual_seed(0)
snet = Stack(784, 10, DEPTH, WIDTH, act="sigmoid", init="he")
F.cross_entropy(snet(xg), yg).backward()
grads = [l.weight.grad.detach().clone() for l in snet.hidden]
torch.set_default_dtype(torch.float32)

n_values = sum(g.numel() for g in grads)
n_nonzero = sum(int((g != 0).sum()) for g in grads)
rows, per_layer = [], {}
for scale in (1, 2 ** 8, 2 ** 16, 2 ** 24):
    for name, dt in (("fp16", torch.float16), ("bf16", torch.bfloat16), ("fp32", torch.float32)):
        cast = [(g * scale).to(dt) for g in grads]
        kept = [int(((c != 0) & torch.isfinite(c)).sum()) for c in cast]
        overflow = [int(torch.isinf(c).sum()) for c in cast]
        rows.append({"loss scale": scale, "format": name,
                     "gradient values kept": sum(kept) / n_nonzero,
                     "overflowed to inf": sum(overflow) / n_nonzero,
                     "layers with nothing left": sum(k == 0 for k in kept),
                     "layers with an overflow": sum(o > 0 for o in overflow)})
        per_layer[(scale, name)] = [k / max(1, int((g != 0).sum())) for k, g in zip(kept, grads)]
fp_tab = pd.DataFrame(rows)
print(f"{n_nonzero:,} non-zero weight gradients in float64 across {DEPTH} layers\n")
print(fp_tab.to_string(index=False, float_format=lambda v: f"{v: .3f}"))

tiny = lambda dt: torch.tensor([1], dtype=torch.int16 if dt != torch.float32 else torch.int32).view(dt).item()
print(f"\nfp16: smallest normal {torch.finfo(torch.float16).tiny:.2e}, smallest subnormal {tiny(torch.float16):.2e}, "
      f"max {torch.finfo(torch.float16).max:.0f}")
print(f"bf16: smallest normal {torch.finfo(torch.bfloat16).tiny:.2e}, smallest subnormal {tiny(torch.bfloat16):.2e}")
print(f"largest |gradient| {max(g.abs().max() for g in grads):.2e}, smallest non-zero "
      f"{min(g[g != 0].abs().min() for g in grads):.2e}")

fig, ax = plt.subplots(figsize=(7, 3))
for (scale, name), col, ls in [((1, "fp16"), EMBER, "-"), ((2 ** 16, "fp16"), PLUM, "-"), ((2 ** 24, "fp16"), GRAY, "--"),
                               ((1, "bf16"), FOREST, "-")]:
    ax.plot(range(1, DEPTH + 1), per_layer[(scale, name)], color=col, ls=ls, lw=1.6,
            label=f"{name}, loss scale {scale:,}")
ax.set_xlabel("layer  (1 = nearest the input)"); ax.set_ylabel("share of gradient values kept")
ax.legend(fontsize=7.5, frameon=False); plt.tight_layout(); plt.show()
RESULTS["lab_fp16"] = rows
739,328 non-zero weight gradients in float64 across 40 layers
loss scale format gradient values kept overflowed to inf layers with nothing left layers with an overflow
1 fp16 0.219 0.000 28 0
1 bf16 1.000 0.000 0 0
1 fp32 1.000 0.000 0 0
256 fp16 0.324 0.000 23 0
256 bf16 1.000 0.000 0 0
256 fp32 1.000 0.000 0 0
65536 fp16 0.427 0.000 19 0
65536 bf16 1.000 0.000 0 0
65536 fp32 1.000 0.000 0 0
16777216 fp16 0.533 0.005 14 2
16777216 bf16 1.000 0.000 0 0
16777216 fp32 1.000 0.000 0 0
fp16: smallest normal 6.10e-05, smallest subnormal 5.96e-08, max 65504
bf16: smallest normal 1.18e-38, smallest subnormal 9.18e-41
largest |gradient| 1.58e-02, smallest non-zero 1.09e-27
At a loss scale of 1, fp16 keeps 22% of the gradient values, and in 28 of the 40 layers it keeps none at all — not a rounding error but a deleted instruction. bf16 keeps every value, while being less precise than fp16: fewer mantissa bits, the same exponent range as fp32, and it is the range that matters here. Loss scaling helps and does not rescue. At 216, 43% of the values survive and 19 layers are still empty; at 224 it is 53% and 14 empty layers, and the scale has now pushed the largest gradients past fp16’s maximum of 65,504, so two layers contain infinities. That is why real loss scaling is dynamic: it lowers the scale whenever an overflow appears. Precision is what you lose; range is what kills you.
What training memory is made of
Training holds four kinds of memory: the parameters, their gradients, the optimizer’s state (two more copies for Adam), and whatever autograd saves during the forward pass for use in the backward pass. The first three are arithmetic. The fourth is measured, with the same saved_tensors_hooks counter as above, on a 784-512-512-512-10 network as the batch grows. It is an accounting of what autograd keeps, not a peak-memory measurement — temporary buffers and allocator overhead come on top.
torch.manual_seed(0)
mnet = nn.Sequential(nn.Linear(784, 512), nn.ReLU(), nn.Linear(512, 512), nn.ReLU(),
                     nn.Linear(512, 512), nn.ReLU(), nn.Linear(512, 10))
P = sum(p.numel() for p in mnet.parameters())
rows = []
for bsz in (32, 128, 512, 2048, 8192):
    xm, ym = torch.randn(bsz, 784), torch.zeros(bsz, dtype=torch.long)
    saved = saved_for_backward(lambda: F.cross_entropy(mnet(xm), ym), mnet.parameters())
    rows.append({"batch": bsz, "parameters (MB)": P * 4 / 1e6, "gradients (MB)": P * 4 / 1e6,
                 "Adam state (MB)": 2 * P * 4 / 1e6, "saved for backward (MB)": saved / 1e6,
                 "of which the input batch (MB)": bsz * 784 * 4 / 1e6})
mem = pd.DataFrame(rows)
mem["total (MB)"] = mem.iloc[:, 1:5].sum(axis=1)
mem["saved share"] = mem["saved for backward (MB)"] / mem["total (MB)"]
print(mem.to_string(index=False, float_format=lambda v: f"{v: .2f}"))
print(f"\nparameters alone: {P:,} × 4 bytes = {P * 4 / 1e6:.1f} MB; gradients and Adam add three more copies.")
RESULTS["lab_memory"] = mem.to_dict("records")
batch parameters (MB) gradients (MB) Adam state (MB) saved for backward (MB) of which the input batch (MB) total (MB) saved share
32 3.73 3.73 7.46 0.30 0.10 15.22 0.02
128 3.73 3.73 7.46 1.19 0.40 16.11 0.07
512 3.73 3.73 7.46 4.78 1.61 19.69 0.24
2048 3.73 3.73 7.46 19.10 6.42 34.02 0.56
8192 3.73 3.73 7.46 76.41 25.69 91.33 0.84
parameters alone: 932,362 × 4 bytes = 3.7 MB; gradients and Adam add three more copies.At batch 32, what autograd saves is 2% of the total, next to three copies of the weights held for the optimizer. At batch 8192 it is 84%. The crossover is a property of the batch, not of the model, and gradient checkpointing trades against exactly that column. Note what the column is made of: a third of it at every batch size is simply the input batch, which the first linear layer has to keep to compute its weight gradient.
Part 3 — the optimizer’s half
The exact stability threshold
For L(w) = (2w − 10)2 one gradient-descent step maps the distance to the optimum e = w − 5 to e(1 − 8η). Everything about learning rates is in that factor, and it is exact, so it can be checked rather than believed.
ETAS = [0.01, 0.05, 0.15, 0.24, 0.25, 0.26, 0.30]
def walk(eta, steps=25, w=3.0):
    out = []
    for _ in range(steps):
        out.append(w if abs(w) < 1e12 else None)
        w = w - eta * (8 * w - 40)
    return out

fig, ax = plt.subplots(figsize=(7, 3.2))
ws = np.linspace(-1, 11, 300)
ax.plot(ws, (2 * ws - 10) ** 2, color=INK, lw=1.5)
for eta, col in [(0.05, FOREST), (0.15, BLUE), (0.25, EMBER), (0.30, GRAY)]:
    t = [w for w in walk(eta, 9) if w is not None and abs(w) < 12]
    ax.plot(t, [(2 * w - 10) ** 2 for w in t], "o--", ms=4, lw=.9, color=col,
            label=f"η = {eta}  (factor {1 - 8 * eta:+.2f})")
ax.set_ylim(-5, 170); ax.set_xlabel("w"); ax.set_ylabel("loss")
ax.legend(fontsize=7.5, frameon=False); plt.tight_layout(); plt.show()

tab = pd.DataFrame({f"η={e}": walk(e, 9) for e in ETAS})
tab.index.name = "step"
print(tab.to_string(float_format=lambda v: f"{v: .4f}"))
print("\nanalytic threshold  η = 2/L'' = 2/8 =", 2 / 8)
toy = {str(e): [None if v is None else round(v, 6) for v in walk(e)] for e in ETAS}
      η=0.01  η=0.05  η=0.15  η=0.24  η=0.25  η=0.26    η=0.3
step
0     3.0000  3.0000  3.0000  3.0000  3.0000  3.0000   3.0000
1     3.1600  3.8000  5.4000  6.8400  7.0000  7.1600   7.8000
2     3.3072  4.2800  4.9200  3.3072  3.0000  2.6672   1.0800
3     3.4426  4.5680  5.0160  6.5574  7.0000  7.5194  10.4880
4     3.5672  4.7408  4.9968  3.5672  3.0000  2.2790  -2.6832
5     3.6818  4.8445  5.0006  6.3182  7.0000  7.9387  15.7565
6     3.7873  4.9067  4.9999  3.7873  3.0000  1.8263 -10.0591
7     3.8843  4.9440  5.0000  6.1157  7.0000  8.4276  26.0827
8     3.9736  4.9664  5.0000  3.9736  3.0000  1.2981 -24.5158

analytic threshold  η = 2/L'' = 2/8 = 0.25
Learning rate against schedule, on a real network
The one-weight model has an exact threshold. A real network has curvature that varies across parameters and across training, so the same question has to be asked empirically: a 6-layer, 128-wide ReLU network, 10 epochs, seven learning rates, three schedules — constant, cosine decay, and 100 steps of linear warmup followed by cosine — two seeds each.
grid = []
for lr in [1e-4, 3e-4, 1e-3, 3e-3, 1e-2, 3e-2, 1e-1]:
    for sched, warm in [("constant", 0), ("cosine", 0), ("warmup_cosine", 100)]:
        losses, accs = [], []
        for seed in range(2):
            torch.manual_seed(seed)
            h = train(Stack(784, 10, 6, 128), X_TR, Y_TR, X_TE, Y_TE, epochs=10, lr=lr, seed=seed,
                      sched=None if sched == "constant" else "cosine", warmup=warm)
            losses.append(h["train_loss"][-1]); accs.append(h["test_acc"][-1])
        ok = all(np.isfinite(losses))
        grid.append({"lr": lr, "schedule": sched,
                     "final_train_loss": round(float(np.mean(losses)), 5) if ok else None,
                     "final_test_acc": round(float(np.mean(accs)), 5) if ok else None,
                     "diverged": (not ok) or float(np.mean(losses)) > 10.0})
RESULTS["nn-train-lr"] = {"toy": toy, "toy_meta": {"optimum": 5.0, "curvature": 8.0, "analytic_threshold": 0.25,
                          "contraction": {str(e): round(1 - 8 * e, 4) for e in ETAS}},
                          "grid": grid, "arch": "6x128 ReLU MLP, MNIST 6000 train, 10 epochs, batch 128, 2 seeds"}
print(pd.DataFrame(grid).pivot(index="lr", columns="schedule", values="final_test_acc").to_string(
      float_format=lambda v: f"{v: .4f}"))
schedule constant cosine warmup_cosine
lr
0.0001 0.8775 0.8455 0.8405
0.0003 0.9067 0.8920 0.8878
0.0010 0.9215 0.9210 0.9187
0.0030 0.9227 0.9315 0.9355
0.0100 0.8878 0.9297 0.9347
0.0300 0.8355 0.8720 0.9155
0.1000 0.1060 0.1235 0.1170The best result in the grid is 93.6%, at η = 0.003 with warmup and cosine decay. At η = 0.1 every schedule collapses to chance. The clearest argument for a schedule is at η = 0.03: constant gets 83.6%, warmup plus cosine 91.6%, from an identical start. At the other end, at η = 10−4, constant beats cosine — 87.8% against 84.6% — because decay only helps when there is a large learning rate worth decaying from.
One reason warmup helps: Adam’s first steps
The early steps are where an adaptive optimizer’s statistics are least trustworthy. That is measurable: watch the ratio Adam actually applies — m̂ / (√v̂ + ε), the bias-corrected first moment over the root of the second — over the first steps of a real run, and see how long it takes to settle.
torch.manual_seed(0)
net = nn.Sequential(nn.Linear(784, 128), nn.ReLU(), nn.Linear(128, 10))
opt = torch.optim.Adam(net.parameters(), lr=1e-3)
p0 = net[0].weight
ratios = []
g = torch.Generator().manual_seed(0)
for step in range(300):
    idx = torch.randint(0, 6000, (128,), generator=g)
    loss = F.cross_entropy(net(X_TR[idx]), Y_TR[idx])
    opt.zero_grad(set_to_none=True); loss.backward(); opt.step()
    st = opt.state[p0]
    b1, b2 = 0.9, 0.999
    mhat = st["exp_avg"] / (1 - b1 ** st["step"].item())
    vhat = st["exp_avg_sq"] / (1 - b2 ** st["step"].item())
    r = mhat.abs() / (vhat.sqrt() + 1e-8)
    if step == 0:                  # one gradient in: m̂ = g, v̂ = g², so r = |g| / (|g| + ε)
        live = st["exp_avg"] != 0
        first_step = (r[live] > 0.999).float().mean().item()
    ratios.append(r.mean().item())

fig, ax = plt.subplots(figsize=(7, 2.8))
ax.plot(ratios, color=EMBER, lw=1.4)
ax.set_xlabel("step"); ax.set_ylabel("mean |update| / lr")
plt.tight_layout(); plt.show()
print(f"first 10 steps: mean {np.mean(ratios[:10]):.3f}, max {np.max(ratios[:10]):.3f}")
print(f"steps 200-300 : mean {np.mean(ratios[200:]):.3f}, max {np.max(ratios[200:]):.3f}")
print(f"the ratio starts {np.mean(ratios[:10]) / np.mean(ratios[200:]):.1f}x larger than it ends")
print(f"step 1: of the weights with a non-zero gradient, {first_step:.1%} moved by at least 99.9% of the learning rate")
RESULTS["lab_adam"] = {"first10": float(np.mean(ratios[:10])), "last100": float(np.mean(ratios[200:])),
                       "first_step_share": first_step}
first 10 steps: mean 0.588, max 1.000
steps 200-300 : mean 0.122, max 0.161
the ratio starts 4.8x larger than it ends
step 1: of the weights with a non-zero gradient, 99.9% moved by at least 99.9% of the learning rate
Bias correction fixes the expected size of Adam’s moment estimates, not their noise. On the first step each estimate is a single gradient, m̂ = g and v̂ = g2, so the update is η g/(|g| + ϵ): for any gradient much larger than ϵ, that is one learning rate in the direction of the gradient’s sign, however small the gradient was. The last line above counts it. The ratio then takes a few hundred steps to fall to where it settles. This is one mechanism warmup answers, not the only one: keep the learning rate small until neither the network nor the optimizer is in that atypical early state.
What clipping is actually for
Clipping is usually explained as insurance against a tail, so the thing to look at is the distribution of gradient norms across a run rather than the average.
torch.manual_seed(0)
net = nn.Sequential(nn.Linear(784, 256), nn.ReLU(), nn.Linear(256, 256), nn.ReLU(), nn.Linear(256, 10))
opt = torch.optim.SGD(net.parameters(), lr=0.1)
norms = []
g = torch.Generator().manual_seed(1)
for step in range(1200):
    idx = torch.randint(0, 6000, (32,), generator=g)
    loss = F.cross_entropy(net(X_TR[idx]), Y_TR[idx])
    opt.zero_grad(set_to_none=True); loss.backward()
    norms.append(float(torch.nn.utils.clip_grad_norm_(net.parameters(), 1e9)))  # measure, don't clip
    opt.step()
norms = np.array(norms)
q = np.percentile(norms, [50, 90, 99, 99.9])
print(f"median {q[0]:.3f}   p90 {q[1]:.3f}   p99 {q[2]:.3f}   p99.9 {q[3]:.3f}   max {norms.max():.3f}")
print(f"the largest batch gradient is {norms.max() / q[0]:.1f}x the median")
print(f"a clip at 1.0 would touch {100 * (norms > 1).mean():.1f}% of steps")
RESULTS["lab_clip"] = {"median": q[0], "max": float(norms.max()), "share_above_1": float((norms > 1).mean())}

fig, ax = plt.subplots(figsize=(7, 2.6))
ax.hist(np.log10(norms), bins=60, color=BLUE, alpha=.85)
ax.axvline(0, color=EMBER, lw=1.2, label="clip threshold 1.0")
ax.set_xlabel("log10 gradient norm"); ax.set_ylabel("steps")
ax.legend(fontsize=8, frameon=False); plt.tight_layout(); plt.show()
median 1.438 p90 2.402 p99 3.639 p99.9 4.648 max 4.938
the largest batch gradient is 3.4x the median
a clip at 1.0 would touch 69.4% of steps
There is no tail here. The largest gradient across twelve hundred steps is about three times the median, the distribution is a single tight bump, and the conventional threshold of 1.0 sits below the median — it would rescale more than two thirds of all steps. That is not insurance against a rare disaster; it is a quiet change to the effective learning rate.
Clipping earned its place where the norm distribution really is heavy-tailed: recurrent networks, transformers on long sequences, anything with a multiplicative path deep enough to produce the occasional enormous batch. A small feed-forward net on MNIST is not that. Clipping on most steps is a legitimate choice in its own right — it behaves like normalized gradient descent — but it is a different tool from the insurance the threshold was copied for.
Normalization, and the batch-size cliff
A 12-layer, 128-wide ReLU network with He initialization, with no normalization, batch norm and layer norm, three seeds, 15 epochs. Then batch norm on its own as the batch shrinks (6 layers, 2,000 examples, 6 epochs, two seeds). Then the gradient reaching every layer of a 24-layer residual stack with layer norm placed before the residual add and after it.
runs, rows = {}, []
for norm in [None, "bn", "ln"]:
    hs = []
    for seed in range(3):
        torch.manual_seed(seed)
        hs.append(train(Stack(784, 10, 12, 128, norm=norm), X_TR, Y_TR, X_TE, Y_TE, epochs=15, seed=seed))
    key = norm or "none"
    runs[key] = {"test_acc_mean": across(hs, "test_acc", np.mean), "test_acc_std": across(hs, "test_acc", np.std),
                 "train_loss_mean": across(hs, "train_loss", np.mean)}
    rows.append({"normalization": key, "test accuracy": runs[key]["test_acc_mean"][-1],
                 "± across seeds": runs[key]["test_acc_std"][-1], "final train loss": runs[key]["train_loss_mean"][-1]})
print(pd.DataFrame(rows).to_string(index=False, float_format=lambda v: f"{v: .4f}"))

bs_rows = []
for bsz in [2, 8, 32, 128]:
    accs = []
    for seed in range(2):
        torch.manual_seed(seed)
        accs.append(train(Stack(784, 10, 6, 128, norm="bn"), X_TR[:2000], Y_TR[:2000], X_TE, Y_TE,
                          epochs=6, bs=bsz, seed=seed)["test_acc"][-1])
    bs_rows.append({"batch_size": bsz, "test_acc": round(float(np.mean(accs)), 5)})
print(); print(pd.DataFrame(bs_rows).to_string(index=False, float_format=lambda v: f"{v: .4f}"))

prepost = {}
for pre in [True, False]:
    g0 = []
    for seed in range(3):
        torch.manual_seed(seed)
        net = Stack(784, 10, 24, 128, norm="ln", residual=True, pre_norm=pre)
        F.cross_entropy(net(X_TR[:256]), Y_TR[:256]).backward()
        g0.append([float(l.weight.grad.norm()) for l in net.hidden])
    prepost["pre" if pre else "post"] = np.median(np.array(g0), 0).tolist()
for k, v in prepost.items():
    print(f"{k}-norm: gradient at layer 2 is {v[1] / v[-1]:.2f}x the gradient at layer 24; layer-2 norm {v[1]:.3e}")
RESULTS["nn-train-norm"] = {"runs": runs, "batch_size_rows": bs_rows, "prepost_gradnorm": prepost,
    "arch": "12x128 ReLU MLP, MNIST 6000 train, AdamW lr 1e-3, 3 seeds; pre/post on a 24-layer residual stack"}
normalization test accuracy ± across seeds final train loss
none 0.9103 0.0077 0.0482
bn 0.8912 0.0031 0.0248
ln 0.9005 0.0025 0.0530
batch_size test_acc
2 0.4120
8 0.8265
32 0.8550
128 0.8425
pre-norm: gradient at layer 2 is 4.84x the gradient at layer 24; layer-2 norm 1.128e+01
post-norm: gradient at layer 2 is 4.86x the gradient at layer 24; layer-2 norm 3.777e+00On a well-initialized twelve-layer network, batch norm reaches the lowest training loss of the three and the worst test accuracy: it optimized better and generalized slightly worse, because there was no scale problem left for it to solve. The batch-size table is the part that behaves exactly as advertised — 85.5% at batch 32, 41.2% at batch 2, where a mean and a variance estimated from two examples is noise injection wearing a normalization layer’s name. Pre-norm and post-norm give the same profile shape across 24 layers, differing by a constant factor of about 3; at this depth the measurement does not separate them.
Regularization: what actually closes the gap
200 training examples and a 784-256-256-10 network large enough to memorize them, 60 epochs, five seeds per configuration, so every accuracy comes with its spread.
xs, ys, xst, yst = mnist(200)
runs, rows = {}, []
for name, cfg in {"none": {}, "dropout": {"dropout": 0.5}, "weight_decay": {"wd": 0.05}, "augment": {"aug": True}}.items():
    hs = []
    for seed in range(SEEDS):
        torch.manual_seed(seed)
        hs.append(train(Stack(784, 10, 2, 256, dropout=cfg.get("dropout", 0.0)), xs, ys, xst, yst,
                        epochs=60, bs=32, seed=seed, wd=cfg.get("wd", 0.0), aug=cfg.get("aug", False)))
    r = {"train_acc_mean": across(hs, "train_acc", np.mean), "test_acc_mean": across(hs, "test_acc", np.mean),
         "test_acc_std": across(hs, "test_acc", np.std)}
    r["final_gap"] = r["train_acc_mean"][-1] - r["test_acc_mean"][-1]
    r["best_test_acc"] = max(r["test_acc_mean"]); r["best_epoch"] = r["test_acc_mean"].index(r["best_test_acc"])
    runs[name] = r
    rows.append({"regularizer": name, "train": r["train_acc_mean"][-1], "test": r["test_acc_mean"][-1],
                 "± (test)": r["test_acc_std"][-1], "gap": r["final_gap"]})
print(pd.DataFrame(rows).to_string(index=False, float_format=lambda v: f"{v: .4f}"))

decay = {}
for decoupled in [True, False]:
    accs, wnorms = [], []
    for seed in range(SEEDS):
        torch.manual_seed(seed)
        net = Stack(784, 10, 2, 256)
        accs.append(train(net, xs, ys, xst, yst, epochs=60, bs=32, seed=seed, wd=0.05, decoupled=decoupled)["test_acc"][-1])
        wnorms.append(float(torch.cat([p.detach().reshape(-1) for p in net.parameters()]).norm()))
    decay["adamw" if decoupled else "adam_l2"] = {"test_acc_mean": float(np.mean(accs)), "test_acc_std": float(np.std(accs)),
                                                  "weight_norm_mean": float(np.mean(wnorms)), "test_accs": accs}
print()
print(pd.DataFrame([{"decay": k, "test accuracy": v["test_acc_mean"], "± across seeds": v["test_acc_std"],
                     "final ‖w‖": v["weight_norm_mean"]} for k, v in decay.items()]
                   ).to_string(index=False, float_format=lambda v: f"{v: .4f}"))
print(f"\nsame λ = 0.05, and the weight norms differ by "
      f"{decay['adamw']['weight_norm_mean'] / decay['adam_l2']['weight_norm_mean']:.1f}x")
RESULTS["nn-train-reg"] = {"runs": runs, "decay": decay,
    "arch": f"2x256 ReLU MLP, MNIST 200 train / 2000 test, 60 epochs, batch 32, lr 1e-3, {SEEDS} seeds; lambda 0.05"}
regularizer train test ± (test) gap
none 1.0000 0.7628 0.0064 0.2372
dropout 1.0000 0.7695 0.0089 0.2305
weight_decay 1.0000 0.7633 0.0055 0.2367
augment 1.0000 0.8014 0.0060 0.1986
decay test accuracy ± across seeds final ‖w‖
adamw 0.7633 0.0055 32.1405
adam_l2 0.7718 0.0081 4.8480
same λ = 0.05, and the weight norms differ by 6.6xEvery run memorizes all 200 training images. On unseen digits, dropout (77.0% ± 0.9) and weight decay (76.3% ± 0.5) land within their spread of doing nothing (76.3% ± 0.6); the random two-pixel shift reaches 80.1% ± 0.6, the only gain that clears the spread across seeds, and the only one that encodes something true about digits.
The decay comparison is about what λ means, not about which optimizer wins. Folding L2 into the loss sends the decay through Adam’s preconditioner; decoupled decay never touches it. At the same λ = 0.05 the final weight norms are 4.8 and 32.1, a factor of 6.6. The accuracies, 77.2% ± 0.8 and 76.3% ± 0.5, are close, and a task this small is not the place to decide between them.
Squared error against cross-entropy, where it matters
z = torch.linspace(-8, 8, 161)
p = torch.sigmoid(z)
mse = (2 * (p - 1) * p * (1 - p)).abs()
ce = (p - 1).abs()

fig, ax = plt.subplots(figsize=(7, 2.9))
ax.semilogy(z, ce, color=FOREST, lw=2, label="cross-entropy")
ax.semilogy(z, mse, color=EMBER, lw=2, label="squared error")
ax.axvspan(-8, 0, color=EMBER, alpha=.06)
ax.set_xlabel("logit z  (true label 1)"); ax.set_ylabel("|dL/dz|")
ax.legend(fontsize=8, frameon=False); plt.tight_layout(); plt.show()

for zz in (-6, -4, -2, 0):
    i = int(round((zz - z[0].item()) / (z[1] - z[0]).item()))
    print(f"z={zz:>3}  p={p[i]:.4f}   CE {ce[i]:.6f}   MSE {mse[i]:.6f}   ratio {ce[i] / mse[i]:.0f}x")
analytic = {"logit": [round(float(v), 4) for v in z], "mse_abs_grad": [round(float(v), 8) for v in mse],
            "ce_abs_grad": [round(float(v), 8) for v in ce]}
z= -6  p=0.0025   CE 0.997527   MSE 0.004921   ratio 203x
z= -4  p=0.0180   CE 0.982014   MSE 0.034690   ratio 28x
z= -2  p=0.1192   CE 0.880797   MSE 0.184956   ratio 5x
z=  0  p=0.5000   CE 0.500000   MSE 0.250000   ratio 2x
The same binary task — threes against fives, 800 training images — trained with each loss, from an ordinary start and from a confidently wrong one (the output bias set to −6), three seeds, 60 epochs.
keep = [i for i in range(4000) if _tr[i][1] in (3, 5)][:800]
xb3 = torch.stack([_tr[i][0] for i in keep]).reshape(len(keep), -1)
yb3 = torch.tensor([1.0 if _tr[i][1] == 5 else 0.0 for i in keep])
keep_te = [i for i in range(2000) if _te[i][1] in (3, 5)]
xt3 = torch.stack([_te[i][0] for i in keep_te]).reshape(len(keep_te), -1)
yt3 = torch.tensor([1.0 if _te[i][1] == 5 else 0.0 for i in keep_te])
mu, sd = xb3.mean(), xb3.std(); xb3, xt3 = (xb3 - mu) / sd, (xt3 - mu) / sd

def run_loss(kind, bad, seed, epochs=60):
    torch.manual_seed(seed)
    net = nn.Sequential(nn.Linear(784, 64), nn.ReLU(), nn.Linear(64, 1))
    if bad:
        with torch.no_grad():
            net[2].bias.fill_(-6.0)
    opt = torch.optim.SGD(net.parameters(), lr=0.05)
    curve = []
    for _ in range(epochs):
        for b in range(0, len(xb3), 64):
            zb, yy = net(xb3[b:b + 64]).squeeze(1), yb3[b:b + 64]
            loss = (F.binary_cross_entropy_with_logits(zb, yy) if kind == "ce"
                    else ((torch.sigmoid(zb) - yy) ** 2).mean())
            opt.zero_grad(set_to_none=True); loss.backward(); opt.step()
        with torch.no_grad():
            curve.append((((net(xt3).squeeze(1)) > 0).float() == yt3).float().mean().item())
    return curve

curves = {}
for bad in [False, True]:
    for kind in ["mse", "ce"]:
        curves[f"{kind}|{'bad_start' if bad else 'normal_start'}"] = [
            round(float(np.mean(v)), 5) for v in zip(*[run_loss(kind, bad, s) for s in range(3)])]
RESULTS["nn-train-loss"] = {"analytic": analytic, "curves": curves,
    "arch": "784-64-1 ReLU, MNIST 3-vs-5, 800 train, SGD lr 0.05, 3 seeds; bad_start sets the output bias to -6 (confidently wrong)"}

fig, ax = plt.subplots(figsize=(7, 2.9))
for k, v in curves.items():
    ax.plot(range(1, len(v) + 1), v, lw=1.9 if "bad" in k else 1.2, ls="-" if "bad" in k else "--",
            color=FOREST if k.startswith("ce") else EMBER, label=k.replace("|", " · ").replace("_", " "))
ax.set_xlabel("epoch"); ax.set_ylabel("test accuracy (mean of 3)")
ax.legend(fontsize=7.5, frameon=False); plt.tight_layout(); plt.show()

first = lambda c, t: next((i + 1 for i, v in enumerate(c) if v > t), None)
mb, cb = curves["mse|bad_start"], curves["ce|bad_start"]
print(f"bad start, cross-entropy: epoch 1 {cb[0]:.3f}, above 90% from epoch {first(cb, .9)}")
print(f"bad start, squared error: epoch 1 {mb[0]:.3f}, above 60% from epoch {first(mb, .6)}, "
      f"above 90% from epoch {first(mb, .9)}, final {mb[-1]:.3f}")
print(f"normal start, final:      squared error {curves['mse|normal_start'][-1]:.3f}   "
      f"cross-entropy {curves['ce|normal_start'][-1]:.3f}")
bad start, cross-entropy: epoch 1 0.815, above 90% from epoch 3
bad start, squared error: epoch 1 0.536, above 60% from epoch 15, above 90% from epoch 25, final 0.946
normal start, final:      squared error 0.951   cross-entropy 0.946
From a confidently wrong start, cross-entropy is at 81.5% after one epoch; squared error sits at 53.6% for twelve epochs before it finds the exit, passes 90% at epoch 25, and ends level. From an ordinary start the two land within half a point of each other. The gradient argument is real, and narrower than it is usually told: the difference appears exactly where the model is confidently wrong — which is where a bad initialization, a hard example, or a shift in the data will put it.
What we just did
Backpropagation was built twice — by hand on two weights, then as a full MLP backward pass in numpy — and checked against the definition of a derivative, with a worst relative error of 3.4 × 10⁻⁹. Its price was measured: a forward-and-backward step costs 2.4 to 3.0 forward passes, against weeks per update for finite differences at 108 parameters. Then the failure modes, in the order they bite: nineteen orders of magnitude lost through a sigmoid stack, a factor of a million to one constant in the initializer, fp16 unable to hold most of a deep gradient that bf16 keeps whole, and the batch size at which saved activations overtake the optimizer’s copies. Then the optimizer’s half: the exact learning rate at which descent stops descending, what a schedule buys, Adam’s oversized first steps, a gradient-norm distribution with no tail for clipping to catch, a normalization layer that did nothing useful on a network that was already well scaled, and three regularizers, of which only the one that encodes something true about the data made a difference.