Lab · runnable experiments
RLCR from Scratch: A One-Pass Decision Model with Honest Probabilities
Created Sep 20, 2026 Updated Sep 22, 2026
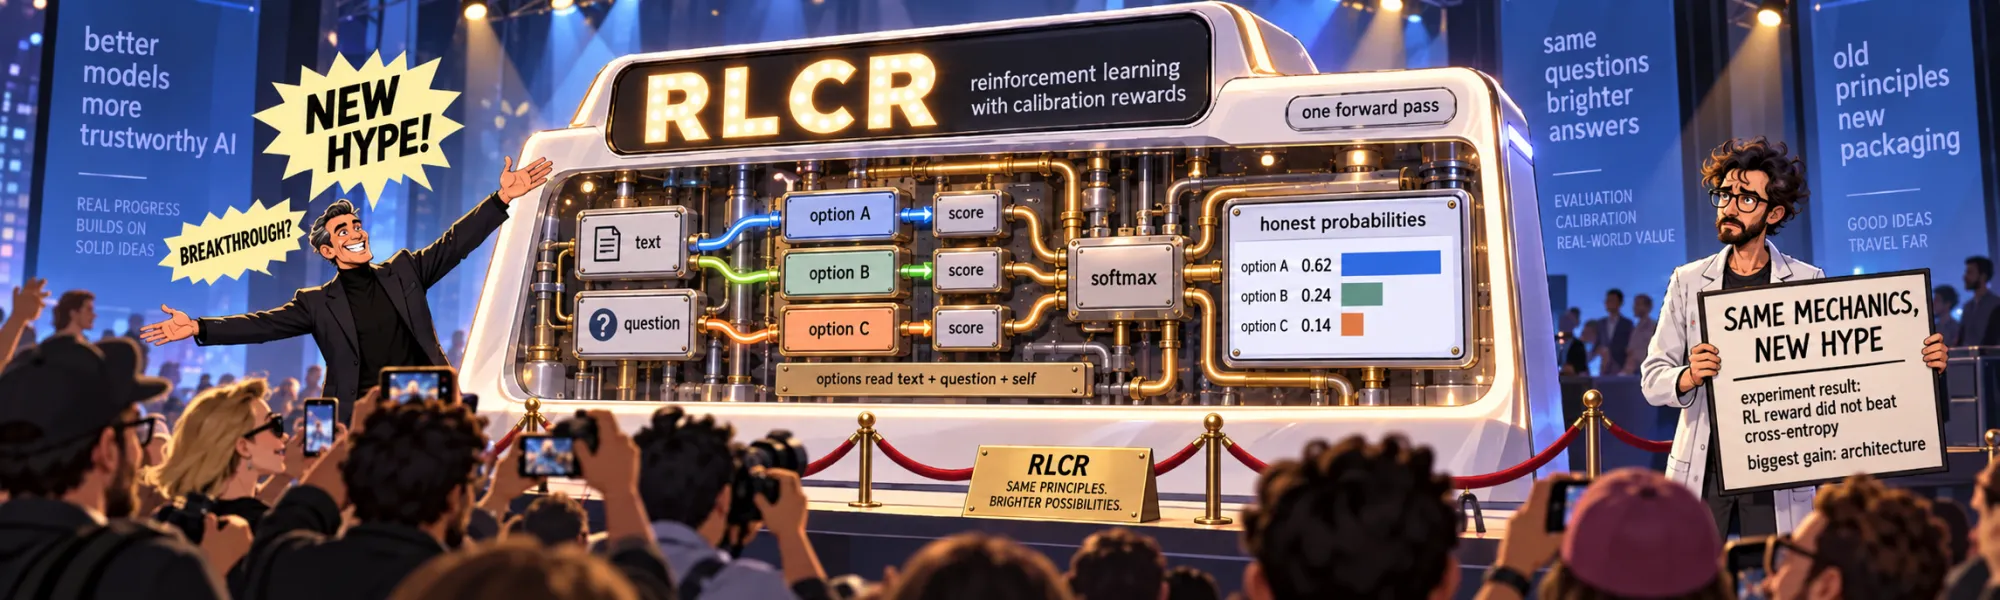
Read the parent noteA decision model answers typed questions about a piece of text — which department, how urgent, is this spam — and returns a probability with every answer. It does not generate text: the options arrive with the request, every option is scored in the same forward pass, and the probabilities are what the caller thresholds on.
This lab builds one from an ordinary encoder, around one idea: every option is a parallel branch of the same sequence. The text comes first, then the question, then all the options side by side, and every option starts at the same position, so none of them comes first. A mask decides who reads whom: the text reads only the text, the question reads the text and itself, each option reads everything. Three properties follow by construction rather than by training — the order of the options cannot change an answer, every option keeps its full name however many there are, and the text’s own representation does not depend on the question’s options at all.
Then the lab asks the question the method rests on: does training the probabilities with a reinforcement-learning reward buy anything over minimising the same proper scoring rule directly?
Part 1 builds the layout, the masks and the model, and checks the three properties numerically. Part 2 builds the training data: twelve label sets from eleven datasets, subsampled and reworded, and a narrow control on three. Part 3 builds the training signals: cross-entropy, the proper score as a loss, and the proper score as a reward, earned by a policy that reports whole distributions drawn from a Dirichlet — under three baselines, with and without a correction that makes the reward’s expectation exactly the score of the distribution the model ships. Part 4 trains all of them, and one larger model. Part 5 measures what each is worth. Part 6 confirms the answers do not move with the options. Part 7 asks about two label sets no model saw in training. Part 8 times it. Part 9 builds the final model: one change to the mask, trained again, and every measurement repeated.
Setup
Run on Kaggle with Settings → Accelerator → GPU T4 (one card is used) and Internet on: the encoder and the datasets are downloaded from the Hub. The first cell pins the library version the model code was written and checked against.
# Housekeeping, in a cell that actually runs: a bash block in a notebook is only documentation.
# transformers is pinned: the model passes its own attention masks and position ids to the encoder,
# and the way the encoder accepts them is version-specific. Kaggle's preinstalled torchao breaks
# transformers and nothing here needs it, so it is removed.
import os, subprocess, sys
os.environ.setdefault("PYTORCH_ALLOC_CONF", "expandable_segments:True")
os.environ.setdefault("TOKENIZERS_PARALLELISM", "false")
subprocess.run([sys.executable, "-m", "pip", "install", "-q", "transformers==5.12.1", "datasets>=4"], check=False)
subprocess.run([sys.executable, "-m", "pip", "uninstall", "-y", "-q", "torchao"], check=False)
import transformers
import transformers.utils.import_utils as _iu
_iu.is_torchao_available = lambda *a, **k: False
for _m in list(sys.modules.values()):
    if getattr(_m, "is_torchao_available", None) is not None:
        _m.is_torchao_available = lambda *a, **k: False
assert transformers.__version__ == "5.12.1", f"transformers {transformers.__version__}: restart the session and run again"
print("environment ready, transformers", transformers.__version__)
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 11.2/11.2 MB 35.4 MB/s eta 0:00:00
environment ready, transformers 5.12.1import functools, json, math, os, random, time
import numpy as np, pandas as pd, torch, torch.nn as nn, torch.nn.functional as F
import matplotlib.pyplot as plt
torch._dynamo.config.disable = True # sequences of every length: compiling would only recompile
SMOKE = os.environ.get("LAB_SMOKE") == "1"
DEV = "cuda" if torch.cuda.is_available() else ("mps" if torch.backends.mps.is_available() else "cpu")
ENCODER = "answerdotai/ModernBERT-base" # 149M parameters; every comparison uses this one
ENCODER_LARGE = ENCODER if SMOKE else "answerdotai/ModernBERT-large" # 395M; one run, for the published comparison
TEXT_TOKENS, QUESTION_TOKENS, OPTION_TOKENS = 256, 48, 12
EPOCHS = 1 if SMOKE else 2
BATCH = 8 if SMOKE else 32
LR = 2e-5
TRAIN_N = 240 if SMOKE else 32000 # training questions per epoch, drawn fresh each epoch
POOL_N = 80 if SMOKE else 6000 # texts kept per training dataset
EVAL_N = 60 if SMOKE else 666 # held-out questions per test task (a third fits temperatures)
ZS_N = 40 if SMOKE else 800 # questions per unseen label set
CONCENTRATION = 10.0 # the Dirichlet policy's total concentration: larger explores less
ALPHA_FLOOR = 1e-3 # keeps every Dirichlet parameter positive
REPORTS = 4 # noisy reports per question, for the per-question baselines
SEEDS = [0] if SMOKE else [0, 1]
INK, LINE = "#2a2a2a", "#d9d3c7"
BLUE, EMBER, FOREST, GRAY, PLUM, GOLD = "#3b6ea5", "#c4521e", "#2e7d5b", "#9a9384", "#7a4f8c", "#b8860b"
plt.rcParams.update({"font.size": 9, "axes.edgecolor": LINE, "axes.spines.top": False,
"axes.spines.right": False, "figure.dpi": 120})
RESULTS = {"meta": {"device": DEV, "encoder": ENCODER, "encoder_large": ENCODER_LARGE, "torch": torch.__version__,
"smoke": SMOKE, "epochs": EPOCHS, "batch": BATCH, "lr": LR, "train_n": TRAIN_N,
"text_tokens": TEXT_TOKENS, "option_tokens": OPTION_TOKENS, "concentration": CONCENTRATION,
"reports": REPORTS, "seeds": SEEDS}}
T0 = time.time()
print(RESULTS["meta"])
if DEV == "cuda":
print(torch.cuda.get_device_name(0))
elif os.environ.get("KAGGLE_KERNEL_RUN_TYPE"):
raise SystemExit("No GPU: set Settings -> Accelerator -> GPU T4."){'device': 'cuda', 'encoder': 'answerdotai/ModernBERT-base', 'encoder_large': 'answerdotai/ModernBERT-large', 'torch': '2.10.0+cu128', 'smoke': False, 'epochs': 2, 'batch': 32, 'lr': 2e-05, 'train_n': 32000, 'text_tokens': 256, 'option_tokens': 12, 'concentration': 10.0, 'reports': 4, 'seeds': [0, 1]}
Tesla T4Part 1 — options as parallel branches
A request is laid out as one sequence. Every option restarts at the same position — the one right after the question — so for the encoder, whose positions are rotary, no option is earlier or later than another.
position:  0     1 … n      n+1    n+2 … m     m+1  │ m+2 …        │ m+2 …        │ m+2 …
token:     [CLS] the text   [SEP]  question    [SEP]│ option 0 [SEP]│ option 1 [SEP]│ option 2 [SEP]
from transformers import AutoModel, AutoTokenizer
KINDS_OF_QUESTION = ("choice", "scale", "binary") # unordered labels, an ordered scale, yes or no
tok = AutoTokenizer.from_pretrained(ENCODER)
@functools.lru_cache(maxsize=None)
def ids_of(text):
"""Token ids, cached: option names and texts come back many times."""
return tuple(tok(text, add_special_tokens=False)["input_ids"])
def lay_out(text, question, options):
"""-> token ids, position ids, and a segment per token: 0 the text, 1 the question, 2 + i option i."""
t = list(ids_of(text))[:TEXT_TOKENS]
q = list(ids_of(question))[:QUESTION_TOKENS]
ids = [tok.cls_token_id] + t + [tok.sep_token_id] + q + [tok.sep_token_id]
seg = [0] * (len(t) + 2) + [1] * (len(q) + 1)
pos = list(range(len(ids)))
start = len(ids)
for i, o in enumerate(options):
o_ids = list(ids_of(" " + o))[:OPTION_TOKENS] + [tok.sep_token_id]
ids += o_ids
seg += [2 + i] * len(o_ids)
pos += range(start, start + len(o_ids))
return ids, pos, seg
ids, pos, seg = lay_out("Oil prices climb after supply cuts", "Which section does this headline belong to?",
["world news", "sports", "business", "science and technology"])
print(len(ids), "tokens; positions of the options' first tokens:", [pos[i] for i in range(len(seg)) if seg[i] >= 2 and (seg[i - 1] != seg[i])])29 tokens; positions of the options' first tokens: [18, 18, 18, 18]The mask is the whole trick. On the encoder’s global layers it says who reads whom; on its local layers, which only look a fixed distance away, the distance is measured in positions, so an option sees the end of the question and its neighbours the same way wherever it sits in the sequence.
ATTN = "eager" if DEV == "mps" else "sdpa"   # fused attention on Apple's backend mishandles custom masks
LOCAL_REACH = 64                              # this encoder's local layers see 64 positions either way

def who_reads_whom(seg, pos):
    """[B, L, L] booleans, query token i may read key token j. The text reads the text; the question reads
    the text and itself; an option reads everything, the other options included."""
    qs, ks = seg[:, :, None], seg[:, None, :]
    real = ks >= 0
    full = torch.where(qs == 0, ks == 0, torch.where(qs == 1, (ks == 0) | (ks == 1), real)) & real
    full = full | torch.eye(seg.size(1), dtype=torch.bool, device=seg.device)[None]    # padding reads itself
    local = full & ((pos[:, :, None] - pos[:, None, :]).abs() <= LOCAL_REACH)
    return full, local

def encoder_masks(seg, pos, dtype):
    out = {}
    for name, allowed in zip(("full_attention", "sliding_attention"), who_reads_whom(seg, pos)):
        m = allowed[:, None]
        out[name] = m if ATTN == "sdpa" else torch.zeros(m.shape, dtype=dtype, device=m.device).masked_fill(~m, torch.finfo(dtype).min)
    return out
Each option is read out as the average of its own final token states, next to the summary token’s state, and a small network turns that pair into one number. A softmax over the numbers is the answer.
class DecisionModel(nn.Module):
    def __init__(self, encoder_name=ENCODER):
        super().__init__()
        self.encoder = AutoModel.from_pretrained(encoder_name, attn_implementation=ATTN)
        d = self.encoder.config.hidden_size
        self.read = nn.Sequential(nn.Linear(2 * d, d), nn.GELU(), nn.LayerNorm(d), nn.Linear(d, 1))

    def forward(self, b):
        dtype = self.encoder.embeddings.tok_embeddings.weight.dtype
        h = self.encoder(input_ids=b["ids"], position_ids=b["pos"],
                         attention_mask=encoder_masks(b["seg"], b["pos"], dtype)).last_hidden_state
        K = b["k_max"]
        member = (b["seg"][:, :, None] == (2 + torch.arange(K, device=h.device))[None, None, :]).to(h.dtype)
        opt = torch.einsum("blk,bld->bkd", member, h) / member.sum(1).clamp(min=1)[..., None]
        summary = h[:, :1].expand(-1, K, -1)
        logits = self.read(torch.cat([opt, opt * summary], -1)).squeeze(-1).float()
        return logits.masked_fill(~b["present"], -1e4)          # options that do not exist cannot win

def collate(items, device):
    L = max(len(it["ids"]) for it in items)
    K = max(len(it["options"]) for it in items)
    B = len(items)
    ids = torch.full((B, L), tok.pad_token_id, dtype=torch.long)
    pos = torch.zeros((B, L), dtype=torch.long)
    seg = torch.full((B, L), -1, dtype=torch.long)
    for i, it in enumerate(items):
        n = len(it["ids"])
        ids[i, :n] = torch.tensor(it["ids"]); pos[i, :n] = torch.tensor(it["pos"]); seg[i, :n] = torch.tensor(it["seg"])
    k = torch.tensor([len(it["options"]) for it in items])
    label = torch.tensor([it["label"] for it in items])
    kind = torch.tensor([KINDS_OF_QUESTION.index(it["type"]) for it in items])
    b = {"ids": ids, "pos": pos, "seg": seg, "k": k, "label": label, "kind": kind,
         "present": torch.arange(K)[None] < k[:, None]}
    b = {name: v.to(device) for name, v in b.items()}
    b["k_max"] = K
    b["meta"] = [{"task": it["task"], "k": len(it["options"]), "label": it["label"]} for it in items]
    return b

def batches(items, batch_size, device, shuffle=True, seed=0):
    """Mini-batches. When shuffling, questions of similar length go together, so a batch of short
    questions is not padded to the length of one with sixty options."""
    order = list(range(len(items)))
    if shuffle:
        rng = random.Random(seed)
        rng.shuffle(order)
        window = batch_size * 50
        order = [j for w in range(0, len(order), window)
                 for j in sorted(order[w:w + window], key=lambda j: len(items[j]["ids"]))]
    chunks = [order[i:i + batch_size] for i in range(0, len(order), batch_size)]
    if shuffle:
        random.Random(seed + 1).shuffle(chunks)
    for c in chunks:
        yield collate([items[j] for j in c], device)

def encode(questions):
    out = []
    for q in questions:
        ids, pos, seg = lay_out(q["state"], q["instructions"], q["options"])
        out.append({**q, "ids": ids, "pos": pos, "seg": seg})
    return out
Three checks before anything is trained, on the untrained model: the options’ order changes nothing, the text’s states do not depend on the options, and a question gives the same numbers alone as in a padded batch.
torch.manual_seed(0)
_m = DecisionModel().to(DEV).eval()
_q = {"task": "check", "type": "choice", "label": 0, "state": "The central bank raised interest rates again.",
      "instructions": "Which section does this news item belong to?",
      "options": ["world news", "sports", "business", "science and technology"]}
_perm = [2, 0, 3, 1]
_short = {"task": "check", "type": "scale", "label": 0, "state": "I loved every minute of it.",
          "instructions": "How positive is this review?", "options": ["negative", "neutral", "positive"]}
def _states(q):
    b = collate(encode([q]), DEV)
    return _m.encoder(input_ids=b["ids"], position_ids=b["pos"],
                      attention_mask=encoder_masks(b["seg"], b["pos"], torch.float32)).last_hidden_state[0]

with torch.no_grad():
    a = _m(collate(encode([_q]), DEV))[0]
    b = _m(collate(encode([{**_q, "options": [_q["options"][i] for i in _perm]}]), DEV))[0]
    order_gap = max(abs(float(a[i]) - float(b[_perm.index(i)])) for i in range(4))
    n_text = len(ids_of(_q["state"])) + 2
    text_gap = float((_states(_q)[:n_text] - _states({**_q, "options": ["cars", "cooking"]})[:n_text]).abs().max())
    alone = _m(collate(encode([_short]), DEV))[0, :3]
    batched = _m(collate(encode([_q, _short]), DEV))[1, :3]
    batch_gap = float((alone - batched).abs().max())
print(f"options permuted: largest change in a logit {order_gap:.1e}")
print(f"other options: largest change in the text's states {text_gap:.1e}")
print(f"alone vs in a batch: largest change in a logit {batch_gap:.1e}")
RESULTS["checks"] = {"order": order_gap, "text": text_gap, "batch": batch_gap}
del _m
options permuted: largest change in a logit 1.3e-07
other options: largest change in the text's states 0.0e+00
alone vs in a batch: largest change in a logit 3.0e-07Part 2 — the training data
Twelve label sets from eleven datasets, from two options to sixty, three kinds of question. Each label has one or more names and each dataset a few ways of asking; a training question picks one at random, and half the time a choice question offers only some of its labels, always including the right one. Every choice dataset also yields yes/no questions — does “sports” describe this text? — half of them true. Two label sets are kept out of training entirely: six emotions and seventy-seven banking intents. A narrow control is trained on three datasets with one fixed name for every label.
from datasets import load_dataset

def take(ds, n, seed=0):
    ds = ds.shuffle(seed=seed)
    return ds.select(range(min(n, len(ds))))

NEWSGROUPS = {"alt.atheism": "atheism", "comp.graphics": "computer graphics",
              "comp.os.ms-windows.misc": "microsoft windows", "comp.sys.ibm.pc.hardware": "pc hardware",
              "comp.sys.mac.hardware": "mac hardware", "comp.windows.x": "x window system",
              "misc.forsale": "for sale", "rec.autos": "cars", "rec.motorcycles": "motorcycles",
              "rec.sport.baseball": "baseball", "rec.sport.hockey": "hockey", "sci.crypt": "cryptography",
              "sci.electronics": "electronics", "sci.med": "medicine", "sci.space": "space",
              "soc.religion.christian": "christianity", "talk.politics.guns": "gun politics",
              "talk.politics.mideast": "middle east politics", "talk.politics.misc": "politics",
              "talk.religion.misc": "religion"}

def names_by_index(ds, label_col, text_col, rename=lambda s: s):
    """Label names in label order, from a dataset that stores both the index and the text."""
    m = {}
    for r in ds:
        m.setdefault(int(r[label_col]), rename(r[text_col]))
    return [[m[i]] for i in range(len(m))]

def rows(ds, text, label):
    return [{"text": text(r)[:600], "label": int(label(r))} for r in ds]

def load_schemas():
    S = {}
    ag = take(load_dataset("fancyzhx/ag_news", split="train"), POOL_N, 0)
    S["ag_news"] = dict(type="choice", rows=rows(ag, lambda r: r["text"], lambda r: r["label"]),
        names=[["world news", "world", "international news"], ["sports", "sport"],
               ["business", "economy and business"], ["science and technology", "sci/tech", "technology"]],
        instructions=["Which section does this news item belong to?", "What is this article about?",
                      "Pick the news category."])
    db = take(load_dataset("fancyzhx/dbpedia_14", split="test"), POOL_N, 0)
    S["dbpedia"] = dict(type="choice", rows=rows(db, lambda r: r["title"] + ". " + r["content"], lambda r: r["label"]),
        names=[["company", "business"], ["school or university", "educational institution"], ["artist"],
               ["athlete", "sportsperson"], ["politician", "office holder"], ["vehicle", "means of transport"],
               ["building"], ["natural place", "landform"], ["village"], ["animal"], ["plant"],
               ["music album", "album"], ["film", "movie"], ["book", "written work"]],
        instructions=["What kind of thing does this encyclopedia entry describe?", "Which category is this entry in?"])
    ya = take(load_dataset("community-datasets/yahoo_answers_topics", split="test"), POOL_N, 0)
    S["yahoo"] = dict(type="choice",
        rows=rows(ya, lambda r: (r["question_title"] + " " + (r["question_content"] or "")).strip(), lambda r: r["topic"]),
        names=[[n.lower()] for n in ya.features["topic"].names],
        instructions=["Which forum topic does this question belong to?", "What is this question about?"])
    ng = load_dataset("SetFit/20_newsgroups", split="train").filter(lambda r: len(r["text"].strip()) > 20)
    S["newsgroups"] = dict(type="choice", rows=rows(take(ng, POOL_N, 0), lambda r: r["text"], lambda r: r["label"]),
        names=names_by_index(ng, "label", "label_text", lambda s: NEWSGROUPS[s]),
        instructions=["Which newsgroup was this posted to?", "What is this post about?"])
    trec = load_dataset("SetFit/TREC-QC", split="train")
    S["trec_coarse"] = dict(type="choice", rows=rows(take(trec, POOL_N, 0), lambda r: r["text"], lambda r: r["label_coarse"]),
        names=names_by_index(trec, "label_coarse", "label_coarse_text"),
        instructions=["What kind of answer does this question ask for?"])
    S["trec_fine"] = dict(type="choice", rows=rows(take(trec, POOL_N, 1), lambda r: r["text"], lambda r: r["label"]),
        names=names_by_index(trec, "label", "label_text"),
        instructions=["What exactly is this question asking for?"])
    ms = load_dataset("mteb/amazon_massive_intent", "en", split="train")
    intents = sorted(set(ms["label"]))
    S["massive"] = dict(type="choice", rows=rows(take(ms, POOL_N, 0), lambda r: r["text"], lambda r: intents.index(r["label"])),
        names=[[i.replace("_", " ")] for i in intents],
        instructions=["What does the user want the assistant to do?", "Which intent is this request?"])
    sst = take(load_dataset("SetFit/sst5", split="train"), POOL_N, 0)
    S["sst5"] = dict(type="scale", rows=rows(sst, lambda r: r["text"], lambda r: r["label"]),
        names=[["very negative", "terrible"], ["negative", "bad"], ["neutral"], ["positive", "good"],
               ["very positive", "excellent"]],
        instructions=["How positive is the sentiment of this review?", "Rate the sentiment of this text."])
    yelp = take(load_dataset("Yelp/yelp_review_full", split="test"), POOL_N, 0)
    S["yelp"] = dict(type="scale", rows=rows(yelp, lambda r: r["text"], lambda r: r["label"]),
        names=[["1 star", "one star"], ["2 stars", "two stars"], ["3 stars", "three stars"],
               ["4 stars", "four stars"], ["5 stars", "five stars"]],
        instructions=["How many stars did this reviewer give?", "What rating goes with this review?"])
    tw = load_dataset("mteb/tweet_sentiment_extraction", split="train").filter(lambda r: len(r["text"].strip()) > 0)
    tw_names = names_by_index(tw, "label", "label_text")
    assert [n[0] for n in tw_names] == ["negative", "neutral", "positive"], tw_names
    S["tweets"] = dict(type="scale", rows=rows(take(tw, POOL_N, 0), lambda r: r["text"], lambda r: r["label"]),
        names=tw_names, instructions=["What is the sentiment of this tweet?"])
    # sms_spam has a single split: a held-out part is fixed first, so no test message is ever trained on
    spam = load_dataset("ucirvine/sms_spam", split="train").shuffle(seed=123)
    spam_test = spam.select(range(1500))
    S["sms_spam"] = dict(type="binary", rows=rows(spam.select(range(1500, len(spam))), lambda r: r["sms"], lambda r: r["label"]),
        names=[["no"], ["yes"]], instructions=["Is this message spam?", "Is this text message unsolicited advertising?"])
    imdb = take(load_dataset("stanfordnlp/imdb", split="train"), POOL_N, 0)
    S["imdb"] = dict(type="binary", rows=rows(imdb, lambda r: r["text"], lambda r: r["label"]),
        names=[["no"], ["yes"]], instructions=["Is this movie review positive?", "Did the reviewer like the film?"])
    if SMOKE:
        for s in S.values():
            s["rows"] = s["rows"][:POOL_N]
    return S, spam_test

SCHEMAS, SPAM_TEST = load_schemas()
print(pd.DataFrame([{"schema": k, "kind": s["type"], "labels": len(s["names"]), "texts": len(s["rows"])}
                    for k, s in SCHEMAS.items()]).to_string(index=False))
schema kind labels texts
ag_news choice 4 6000
dbpedia choice 14 6000
yahoo choice 10 6000
newsgroups choice 20 6000
trec_coarse choice 6 5452
trec_fine choice 50 5452
massive choice 60 6000
sst5 scale 5 6000
yelp scale 5 6000
tweets scale 3 6000
sms_spam binary 2 4074
imdb binary 2 6000A question is built from a text, its schema and a random generator. The narrow form always uses the first name of every label and the first way of asking; the broad form varies both and subsamples the labels. Option order is left as the dataset lists it: the model cannot see it anyway.
def make_question(task, schema, row, rng, broad=True):
    names, label = schema["names"], row["label"]
    keep = list(range(len(names)))
    if broad and schema["type"] == "choice" and len(names) > 2 and rng.random() < 0.5:
        size = rng.randint(2, len(names))             # a subset, always holding the right answer
        keep = sorted([label] + rng.sample([i for i in keep if i != label], size - 1))
    options = [rng.choice(names[i]) if broad else names[i][0] for i in keep]
    instructions = rng.choice(schema["instructions"]) if broad else schema["instructions"][0]
    return {"task": task, "type": schema["type"], "state": row["text"], "instructions": instructions,
            "options": options, "label": keep.index(label)}

def make_yes_no(task, schema, row, rng):
    """From any choice question: does one named label describe this text? Half of them do."""
    true = row["label"]
    asked = true if rng.random() < 0.5 else rng.choice([i for i in range(len(schema["names"])) if i != true])
    return {"task": task + "_yes_no", "type": "binary", "state": row["text"],
            "instructions": f'Does "{rng.choice(schema["names"][asked])}" describe this text?',
            "options": ["no", "yes"], "label": int(asked == true)}

NARROW = ["ag_news", "sst5", "sms_spam"]
CHOICE = [k for k, s in SCHEMAS.items() if s["type"] == "choice"]

def epoch_questions(seed, epoch, broad=True):
    """TRAIN_N questions: a schema at random (the derived yes/no questions count as one more), a text
    from it at random, then the question built around them."""
    rng = random.Random(7919 * seed + 104729 * epoch + 1)
    pool = list(SCHEMAS) + ["yes_no"] if broad else NARROW
    out = []
    for _ in range(TRAIN_N):
        name = rng.choice(pool)
        if name == "yes_no":
            src = rng.choice(CHOICE)
            out.append(make_yes_no(src, SCHEMAS[src], rng.choice(SCHEMAS[src]["rows"]), rng))
        else:
            out.append(make_question(name, SCHEMAS[name], rng.choice(SCHEMAS[name]["rows"]), rng, broad))
    return encode(out)

t = time.time()
EPOCH_DATA = {"broad": {s: [epoch_questions(s, e) for e in range(EPOCHS)] for s in SEEDS},
              "narrow": {SEEDS[0]: [epoch_questions(SEEDS[0], e, broad=False) for e in range(EPOCHS)]}}
sample = EPOCH_DATA["broad"][SEEDS[0]][0]
print(f"built {sum(len(e) for d in EPOCH_DATA.values() for s in d.values() for e in s):,} training questions in "
      f"{time.time() - t:.0f}s; median length {int(np.median([len(q['ids']) for q in sample]))} tokens, "
      f"longest {max(len(q['ids']) for q in sample)}")
for q in sample[:3]:
    print(f"  [{q['task']}] {q['instructions']}  options: {q['options'][:6]}{' …' if len(q['options']) > 6 else ''}")
built 192,000 training questions in 24s; median length 74 tokens, longest 323
[yahoo] Which forum topic does this question belong to? options: ['society & culture', 'science & mathematics', 'health', 'education & reference', 'computers & internet', 'sports'] …
[massive] What does the user want the assistant to do? options: ['alarm query', 'alarm remove', 'alarm set', 'audio volume down', 'audio volume mute', 'audio volume other'] …
[yelp] What rating goes with this review? options: ['1 star', 'two stars', 'three stars', 'four stars', 'five stars']The questions the models are judged on come from the test splits, written the way a caller would write them: the first name of every label, in the dataset’s order.
def eval_questions(n, seed=7):
    fixed = random.Random(0)
    qs = []
    ag = take(load_dataset("fancyzhx/ag_news", split="test"), n, seed)
    qs += [make_question("ag_news", SCHEMAS["ag_news"], {"text": r["text"][:600], "label": r["label"]}, fixed, broad=False) for r in ag]
    sst = take(load_dataset("SetFit/sst5", split="test"), n, seed)
    qs += [make_question("sst5", SCHEMAS["sst5"], {"text": r["text"][:600], "label": r["label"]}, fixed, broad=False) for r in sst]
    sp = SPAM_TEST.select(range(min(n, len(SPAM_TEST))))
    qs += [make_question("sms_spam", SCHEMAS["sms_spam"], {"text": r["sms"][:600], "label": r["label"]}, fixed, broad=False) for r in sp]
    random.Random(seed).shuffle(qs)
    return encode(qs)

eval_items = eval_questions(EVAL_N)
fit_items = eval_items[: len(eval_items) // 3]           # for the temperatures only
test_items = eval_items[len(eval_items) // 3:]
print(pd.Series([q["task"] for q in test_items]).value_counts().to_string())
sms_spam 451
sst5 451
ag_news 430Part 3 — the training signals
The proper score used here is the one the note derives: the squared error between the reported distribution and what happened — the Brier score, summed over all options — and, for an ordered scale, the same squared error on the cumulative distribution, the ranked probability score, so that positive for a very positive review costs less than negative. Both are strictly proper and both are bounded, which matters once the score becomes a reward: a bounded reward has bounded variance.
As a reward, the score needs a policy that reports distributions and explores. Here the policy is a Dirichlet whose mean is the model’s softmax: a report q is drawn from Dir(κp), so on average it is exactly p, the distribution the model will ship. That alone is not enough. The squared error is convex, so a noisy report scores worse on average than its mean, and the gap is its variance, pi(1 − pi)/(κ + 1) per option. A policy rewarded with the plain score of its reports is therefore paid for shrinking that variance, which it does by sharpening p: a push toward overconfidence built into the estimator. For a Dirichlet the variance is known in closed form and has an unbiased estimate from the sample itself, qi(1 − qi)/κ, so it can be added back. With the correction, the expected reward is exactly the proper score of p. Both versions are trained, to see whether the bias is visible.
def proper_score(p, b, concentration=None):
    """Negative Brier score (choice, binary) or negative ranked probability score (scale), per question;
    higher is better, 0 is a perfect report. With `concentration` (the Dirichlet's total, per question),
    every squared error is corrected by its sampling variance, estimated from the report itself, so the
    expectation over reports is exactly the score of the policy's mean."""
    y = F.one_hot(b["label"], p.size(-1)).to(p.dtype) * b["present"]
    p = p * b["present"]
    def squared(a, t):
        e = (a - t) ** 2
        if concentration is not None:
            e = e - a * (1 - a) / concentration[:, None]
        return (e * b["present"]).sum(-1)
    brier = squared(p, y)
    ranked = squared(p.cumsum(-1), y.cumsum(-1)) / (b["k"] - 1).clamp(min=1)
    return -torch.where(b["kind"] == KINDS_OF_QUESTION.index("scale"), ranked, brier)

def loss_cross_entropy(model, b):
    logits = model(b)
    return F.cross_entropy(logits, b["label"]), logits

def loss_proper(model, b):
    """The proper score used as a loss: its gradient flows through the softmax."""
    logits = model(b)
    return -proper_score(torch.softmax(logits, -1), b).mean(), logits

def draw_dirichlet(alpha, present, reports):
    """`reports` samples of Dir(alpha) per question over the options present, via normalised Gamma
    draws. Apple's backend has no Gamma sampler, so there the draw happens on the CPU."""
    m = present[:, None, :].expand(-1, reports, -1)
    a = alpha.detach()[:, None, :].expand(-1, reports, -1).masked_fill(~m, 1.0)   # absent options: drawn, then dropped
    where = "cpu" if a.device.type == "mps" else a.device
    g = torch.distributions.Gamma(a.to(where), torch.ones_like(a, device=where)).sample().to(a.device) * m
    return g / g.sum(-1, keepdim=True)

def dirichlet_log_density(q, alpha, present):
    """log Dir(q; alpha) over the options present, as a function of alpha (and so of the logits)."""
    a = alpha.masked_fill(~present, 1.0)
    return (torch.lgamma((alpha * present).sum(-1)) - (torch.lgamma(a) * present).sum(-1)
            + ((a - 1) * torch.log(q.clamp_min(1e-12)) * present).sum(-1))

def reinforce(model, b, reports, baseline, corrected=True):
    """The proper score as a reward. The policy is Dir(kappa * softmax(logits)); each question gets
    `reports` draws, each draw is scored and compared with a baseline, and the policy moves toward the
    draws that beat it."""
    logits = model(b)
    present = b["present"]
    alpha = (CONCENTRATION * torch.softmax(logits, -1) + ALPHA_FLOOR) * present
    q = draw_dirichlet(alpha, present, reports)
    with torch.no_grad():
        flat = {k: v.repeat_interleave(reports, 0) for k, v in b.items() if torch.is_tensor(v) and v.dim() > 0}
        total = alpha.sum(-1).repeat_interleave(reports, 0) if corrected else None
        r = proper_score(q.flatten(0, 1), flat, total).view(-1, reports)
        if baseline == "batch":                          # every report against the whole batch
            adv = (r - r.mean()) / (r.std() + 1e-6)
        elif baseline == "question_std":                 # against the same question, scaled by that question's spread
            adv = (r - r.mean(1, keepdim=True)) / (r.std(1, keepdim=True) + 1e-6)
        else:                                            # against the same question, one scale for the batch
            centred = r - r.mean(1, keepdim=True)
            adv = centred / (centred.std() + 1e-6)
    log_density = dirichlet_log_density(q, alpha[:, None, :], present[:, None, :])
    return -(adv * log_density).mean(), logits

TRAINERS = {
    "cross_entropy": loss_cross_entropy,
    "proper_loss": loss_proper,
    "reinforce_batch": lambda m, b: reinforce(m, b, 1, "batch"),
    "reinforce_question_std": lambda m, b: reinforce(m, b, REPORTS, "question_std"),
    "reinforce_centered": lambda m, b: reinforce(m, b, REPORTS, "centered"),
    "reinforce_centered_uncorrected": lambda m, b: reinforce(m, b, REPORTS, "centered", corrected=False),
}
# seeds: two where the comparison rests on it, one where a single run already settles the question
JOBS = ([("narrow", SEEDS[0])] + [(k, s) for s in SEEDS for k in ("cross_entropy", "reinforce_centered")]
        + [(k, SEEDS[0]) for k in ("proper_loss", "reinforce_batch", "reinforce_question_std", "reinforce_centered_uncorrected")]
        + [("cross_entropy_large", SEEDS[0])])
print(len(JOBS), "runs:", JOBS)
10 runs: [('narrow', 0), ('cross_entropy', 0), ('reinforce_centered', 0), ('cross_entropy', 1), ('reinforce_centered', 1), ('proper_loss', 0), ('reinforce_batch', 0), ('reinforce_question_std', 0), ('reinforce_centered_uncorrected', 0), ('cross_entropy_large', 0)]The correction, checked on its own: draws from one Dirichlet, the plain and the corrected score, against the score of the mean.
_b = {"label": torch.tensor([0, 0]), "present": torch.ones(2, 3, dtype=torch.bool), "k": torch.tensor([3, 3]),
      "kind": torch.tensor([KINDS_OF_QUESTION.index("choice"), KINDS_OF_QUESTION.index("scale")])}
_p = torch.tensor([[0.7, 0.2, 0.1], [0.7, 0.2, 0.1]])
_alpha = CONCENTRATION * _p
_q = draw_dirichlet(_alpha, _b["present"], 200000)
_many = {k: v.repeat_interleave(200000, 0) for k, v in _b.items()}
_plain = proper_score(_q.flatten(0, 1), _many).view(2, -1).mean(1)
_fixed = proper_score(_q.flatten(0, 1), _many, _alpha.sum(-1).repeat_interleave(200000, 0)).view(2, -1).mean(1)
print(pd.DataFrame({"score of the mean": proper_score(_p, _b).tolist(), "plain reward, average": _plain.tolist(),
                    "corrected reward, average": _fixed.tolist()}, index=["choice (Brier)", "scale (RPS)"]).to_string(float_format=lambda v: f"{v:.4f}"))
score of the mean plain reward, average corrected reward, average
choice (Brier) -0.1400 -0.1821 -0.1402
scale (RPS) -0.0500 -0.0635 -0.0499Part 4 — train every run
The runs go one after another on one card; each finished model is parked in main memory. Everything a run draws at random — its data, its initial read-out, its dropout and its Dirichlet draws — comes from its own seed. The larger model trains with half the batch per step and two steps per update, the same effective batch.
TRAIN_DEV = "cuda" if DEV == "cuda" else DEV

def train(kind, seed):
    large = kind == "cross_entropy_large"
    data = EPOCH_DATA["narrow" if kind == "narrow" else "broad"][seed]
    loss_fn = loss_cross_entropy if kind in ("narrow", "cross_entropy_large") else TRAINERS[kind]
    torch.manual_seed(seed)
    model = DecisionModel(ENCODER_LARGE if large else ENCODER).to(TRAIN_DEV)
    micro, accum = (BATCH // 2, 2) if large else (BATCH, 1)
    lr = LR * 0.75 if large else LR
    amp = TRAIN_DEV == "cuda"
    scaler = torch.amp.GradScaler("cuda", enabled=amp)
    opt = torch.optim.AdamW(model.parameters(), lr=lr, weight_decay=0.01)
    updates = sum(math.ceil(len(e) / micro) for e in data) // accum
    sched = torch.optim.lr_scheduler.OneCycleLR(opt, max_lr=lr, total_steps=updates + 1, pct_start=0.1)
    log, t0, step, n_micro = [], time.time(), 0, 0
    model.train()
    opt.zero_grad(set_to_none=True)
    for ep, items in enumerate(data):
        for b in batches(items, micro, TRAIN_DEV, seed=1000 * seed + ep):
            with torch.amp.autocast("cuda", dtype=torch.float16, enabled=amp):
                loss, logits = loss_fn(model, b)
            scaler.scale(loss / accum).backward()
            n_micro += 1
            if n_micro % accum:
                continue
            scaler.unscale_(opt)
            nn.utils.clip_grad_norm_(model.parameters(), 1.0)
            scaler.step(opt); scaler.update(); sched.step(); step += 1
            opt.zero_grad(set_to_none=True)
            if step % 25 == 0 or step == updates:
                acc = (logits.argmax(-1) == b["label"]).float().mean().item()
                log.append({"step": step, "loss": float(loss.detach()), "batch_acc": acc,
                            "minutes": (time.time() - t0) / 60})
                if step % 250 == 0 or step == 25:
                    pace = log[-1]["minutes"] / step
                    print(f"  [{kind}/{seed}] step {step}/{updates} loss {log[-1]['loss']:.4f} acc {acc:.3f} · "
                          f"{log[-1]['minutes']:.1f}m · this run ≈ {pace * updates:.0f}m", flush=True)
    model.zero_grad(set_to_none=True)
    return model, log

models, training = {}, {}
for kind, seed in JOBS:
    print(f"=== {kind}, seed {seed} ({(time.time() - T0) / 60:.0f} min since the start) ===", flush=True)
    m, log = train(kind, seed)
    models[(kind, seed)] = m.cpu()                     # parked in RAM: the card holds one model at a time
    training[f"{kind}|{seed}"] = log
    del m
    if TRAIN_DEV == "cuda":
        torch.cuda.empty_cache()
RESULTS["training"] = training
print(f"trained {len(models)} models in {(time.time() - T0) / 60:.0f} min since the start")
=== narrow, seed 0 (1 min since the start) === [narrow/0] step 25/2000 loss 1.3287 acc 0.250 · 0.1m · this run ≈ 7m
[narrow/0] step 250/2000 loss 0.6919 acc 0.781 · 0.8m · this run ≈ 7m
[narrow/0] step 500/2000 loss 0.1436 acc 0.969 · 1.7m · this run ≈ 7m
[narrow/0] step 750/2000 loss 0.5057 acc 0.812 · 2.5m · this run ≈ 7m
[narrow/0] step 1000/2000 loss 0.3025 acc 0.938 · 3.4m · this run ≈ 7m
[narrow/0] step 1250/2000 loss 0.3332 acc 0.906 · 4.3m · this run ≈ 7m
[narrow/0] step 1500/2000 loss 0.1977 acc 0.938 · 5.2m · this run ≈ 7m
[narrow/0] step 1750/2000 loss 0.1653 acc 0.969 · 6.1m · this run ≈ 7m
[narrow/0] step 2000/2000 loss 0.4580 acc 0.812 · 7.0m · this run ≈ 7m
=== cross_entropy, seed 0 (8 min since the start) === [cross_entropy/0] step 25/2000 loss 1.6557 acc 0.375 · 0.2m · this run ≈ 13m
[cross_entropy/0] step 250/2000 loss 0.4726 acc 0.875 · 1.5m · this run ≈ 12m
[cross_entropy/0] step 500/2000 loss 0.5593 acc 0.625 · 2.9m · this run ≈ 12m
[cross_entropy/0] step 750/2000 loss 0.3734 acc 0.875 · 4.3m · this run ≈ 12m
[cross_entropy/0] step 1000/2000 loss 0.3815 acc 0.906 · 5.7m · this run ≈ 11m
[cross_entropy/0] step 1250/2000 loss 0.7557 acc 0.719 · 7.2m · this run ≈ 12m
[cross_entropy/0] step 1500/2000 loss 0.3793 acc 0.875 · 8.7m · this run ≈ 12m
[cross_entropy/0] step 1750/2000 loss 0.1698 acc 0.906 · 10.1m · this run ≈ 12m
[cross_entropy/0] step 2000/2000 loss 0.4298 acc 0.781 · 11.5m · this run ≈ 11m
=== reinforce_centered, seed 0 (20 min since the start) === [reinforce_centered/0] step 25/2000 loss 0.2995 acc 0.375 · 0.2m · this run ≈ 14m
[reinforce_centered/0] step 250/2000 loss 0.6748 acc 0.750 · 1.5m · this run ≈ 12m
[reinforce_centered/0] step 500/2000 loss -0.2807 acc 0.594 · 2.9m · this run ≈ 12m
[reinforce_centered/0] step 750/2000 loss -0.5183 acc 0.750 · 4.4m · this run ≈ 12m
[reinforce_centered/0] step 1000/2000 loss 0.9431 acc 0.844 · 5.7m · this run ≈ 11m
[reinforce_centered/0] step 1250/2000 loss -2.4038 acc 0.688 · 7.2m · this run ≈ 12m
[reinforce_centered/0] step 1500/2000 loss -0.5470 acc 0.906 · 8.7m · this run ≈ 12m
[reinforce_centered/0] step 1750/2000 loss -1.1673 acc 0.844 · 10.1m · this run ≈ 12m
[reinforce_centered/0] step 2000/2000 loss -0.5769 acc 0.781 · 11.4m · this run ≈ 11m
=== cross_entropy, seed 1 (31 min since the start) === [cross_entropy/1] step 25/2000 loss 1.9468 acc 0.250 · 0.2m · this run ≈ 13m
[cross_entropy/1] step 250/2000 loss 0.7632 acc 0.625 · 1.5m · this run ≈ 12m
[cross_entropy/1] step 500/2000 loss 0.7491 acc 0.719 · 2.9m · this run ≈ 11m
[cross_entropy/1] step 750/2000 loss 0.3750 acc 0.844 · 4.4m · this run ≈ 12m
[cross_entropy/1] step 1000/2000 loss 0.7105 acc 0.625 · 5.7m · this run ≈ 11m
[cross_entropy/1] step 1250/2000 loss 0.4357 acc 0.844 · 7.2m · this run ≈ 12m
[cross_entropy/1] step 1500/2000 loss 0.3619 acc 0.906 · 8.6m · this run ≈ 11m
[cross_entropy/1] step 1750/2000 loss 0.2996 acc 0.938 · 9.9m · this run ≈ 11m
[cross_entropy/1] step 2000/2000 loss 0.6995 acc 0.719 · 11.5m · this run ≈ 11m
=== reinforce_centered, seed 1 (43 min since the start) === [reinforce_centered/1] step 25/2000 loss 0.4036 acc 0.219 · 0.2m · this run ≈ 13m
[reinforce_centered/1] step 250/2000 loss 1.1769 acc 0.656 · 1.5m · this run ≈ 12m
[reinforce_centered/1] step 500/2000 loss -0.1145 acc 0.562 · 2.8m · this run ≈ 11m
[reinforce_centered/1] step 750/2000 loss -1.3168 acc 0.844 · 4.3m · this run ≈ 12m
[reinforce_centered/1] step 1000/2000 loss -0.0028 acc 0.688 · 5.7m · this run ≈ 11m
[reinforce_centered/1] step 1250/2000 loss 0.2092 acc 0.781 · 7.2m · this run ≈ 11m
[reinforce_centered/1] step 1500/2000 loss -0.6382 acc 0.812 · 8.5m · this run ≈ 11m
[reinforce_centered/1] step 1750/2000 loss -2.5903 acc 0.844 · 9.9m · this run ≈ 11m
[reinforce_centered/1] step 2000/2000 loss 0.5365 acc 0.750 · 11.4m · this run ≈ 11m
=== proper_loss, seed 0 (54 min since the start) === [proper_loss/0] step 25/2000 loss 0.6530 acc 0.375 · 0.2m · this run ≈ 13m
[proper_loss/0] step 250/2000 loss 0.2895 acc 0.656 · 1.5m · this run ≈ 12m
[proper_loss/0] step 500/2000 loss 0.1382 acc 0.625 · 2.9m · this run ≈ 12m
[proper_loss/0] step 750/2000 loss 0.0955 acc 0.906 · 4.3m · this run ≈ 11m
[proper_loss/0] step 1000/2000 loss 0.1081 acc 0.844 · 5.7m · this run ≈ 11m
[proper_loss/0] step 1250/2000 loss 0.3446 acc 0.719 · 7.1m · this run ≈ 11m
[proper_loss/0] step 1500/2000 loss 0.0649 acc 0.906 · 8.6m · this run ≈ 11m
[proper_loss/0] step 1750/2000 loss 0.1494 acc 0.844 · 10.0m · this run ≈ 11m
[proper_loss/0] step 2000/2000 loss 0.1756 acc 0.812 · 11.3m · this run ≈ 11m
=== reinforce_batch, seed 0 (65 min since the start) === [reinforce_batch/0] step 25/2000 loss 22.6877 acc 0.375 · 0.2m · this run ≈ 13m
[reinforce_batch/0] step 250/2000 loss 12.8280 acc 0.281 · 1.5m · this run ≈ 12m
[reinforce_batch/0] step 500/2000 loss -0.2258 acc 0.469 · 2.9m · this run ≈ 12m
[reinforce_batch/0] step 750/2000 loss 72.4730 acc 0.125 · 4.3m · this run ≈ 12m
[reinforce_batch/0] step 1000/2000 loss 77.4877 acc 0.469 · 5.7m · this run ≈ 11m
[reinforce_batch/0] step 1250/2000 loss 54.7648 acc 0.219 · 7.1m · this run ≈ 11m
[reinforce_batch/0] step 1500/2000 loss 19.6525 acc 0.281 · 8.6m · this run ≈ 11m
[reinforce_batch/0] step 1750/2000 loss 144.9347 acc 0.531 · 9.9m · this run ≈ 11m
[reinforce_batch/0] step 2000/2000 loss 73.1988 acc 0.156 · 11.2m · this run ≈ 11m
=== reinforce_question_std, seed 0 (77 min since the start) === [reinforce_question_std/0] step 25/2000 loss 0.6083 acc 0.375 · 0.2m · this run ≈ 12m
[reinforce_question_std/0] step 250/2000 loss 0.2255 acc 0.594 · 1.4m · this run ≈ 11m
[reinforce_question_std/0] step 500/2000 loss 0.6565 acc 0.594 · 2.8m · this run ≈ 11m
[reinforce_question_std/0] step 750/2000 loss 2.6503 acc 0.875 · 4.2m · this run ≈ 11m
[reinforce_question_std/0] step 1000/2000 loss 1.6094 acc 0.875 · 5.6m · this run ≈ 11m
[reinforce_question_std/0] step 1250/2000 loss 1.1635 acc 0.688 · 7.1m · this run ≈ 11m
[reinforce_question_std/0] step 1500/2000 loss 0.5186 acc 0.875 · 8.6m · this run ≈ 11m
[reinforce_question_std/0] step 1750/2000 loss 1.0123 acc 0.875 · 10.1m · this run ≈ 11m
[reinforce_question_std/0] step 2000/2000 loss -1.2671 acc 0.781 · 11.4m · this run ≈ 11m
=== reinforce_centered_uncorrected, seed 0 (88 min since the start) === [reinforce_centered_uncorrected/0] step 25/2000 loss 0.2907 acc 0.375 · 0.2m · this run ≈ 13m
[reinforce_centered_uncorrected/0] step 250/2000 loss 0.1182 acc 0.562 · 1.5m · this run ≈ 12m
[reinforce_centered_uncorrected/0] step 500/2000 loss -0.0208 acc 0.594 · 2.9m · this run ≈ 12m
[reinforce_centered_uncorrected/0] step 750/2000 loss 0.4496 acc 0.719 · 4.3m · this run ≈ 11m
[reinforce_centered_uncorrected/0] step 1000/2000 loss 1.2423 acc 0.875 · 5.7m · this run ≈ 11m
[reinforce_centered_uncorrected/0] step 1250/2000 loss -2.8315 acc 0.781 · 7.1m · this run ≈ 11m
[reinforce_centered_uncorrected/0] step 1500/2000 loss 0.1082 acc 0.875 · 8.6m · this run ≈ 11m
[reinforce_centered_uncorrected/0] step 1750/2000 loss -0.7550 acc 0.812 · 10.0m · this run ≈ 11m
[reinforce_centered_uncorrected/0] step 2000/2000 loss -0.6070 acc 0.781 · 11.3m · this run ≈ 11m
=== cross_entropy_large, seed 0 (99 min since the start) === [cross_entropy_large/0] step 25/2000 loss 1.3885 acc 0.438 · 0.4m · this run ≈ 33m
[cross_entropy_large/0] step 250/2000 loss 2.1035 acc 0.375 · 3.7m · this run ≈ 30m
[cross_entropy_large/0] step 500/2000 loss 0.8047 acc 0.750 · 7.4m · this run ≈ 30m
[cross_entropy_large/0] step 750/2000 loss 0.1754 acc 0.875 · 11.1m · this run ≈ 30m
[cross_entropy_large/0] step 1000/2000 loss 0.7141 acc 0.812 · 14.8m · this run ≈ 30m
[cross_entropy_large/0] step 1250/2000 loss 0.4158 acc 0.812 · 18.5m · this run ≈ 30m
[cross_entropy_large/0] step 1500/2000 loss 0.6548 acc 0.750 · 22.3m · this run ≈ 30m
[cross_entropy_large/0] step 1750/2000 loss 0.4419 acc 0.875 · 25.9m · this run ≈ 30m
[cross_entropy_large/0] step 2000/2000 loss 0.2465 acc 0.812 · 29.6m · this run ≈ 30m
trained 10 models in 129 min since the startPart 5 — what each training signal is worth
Each model is judged on the same held-out questions: accuracy, calibration error, the Brier score of the stated number split into reliability and resolution, AUROC, accuracy on the answers it is surest of — and the log loss over all options. Then one temperature per task is fitted on separate questions, the cheap fix any of them can have afterwards.
EVAL_DEV = TRAIN_DEV

def bands(conf, n):
    """Index of the confidence band each value falls in, n equal bands over [0, 1]."""
    return np.minimum((np.asarray(conf) * n).astype(int), n - 1)

def ece(conf, correct, n=15):
    conf, correct = np.asarray(conf, float), np.asarray(correct, float)
    idx = bands(conf, n)
    return float(sum((idx == i).mean() * abs(conf[idx == i].mean() - correct[idx == i].mean())
                     for i in range(n) if (idx == i).any()))

def brier_parts(conf, correct, n=10):
    conf, correct = np.asarray(conf, float), np.asarray(correct, float)
    base, idx = correct.mean(), bands(conf, n)
    rel = sum((idx == i).mean() * (conf[idx == i].mean() - correct[idx == i].mean()) ** 2 for i in range(n) if (idx == i).any())
    res = sum((idx == i).mean() * (correct[idx == i].mean() - base) ** 2 for i in range(n) if (idx == i).any())
    return {"brier": float(((conf - correct) ** 2).mean()), "reliability": float(rel),
            "resolution": float(res), "uncertainty": float(base * (1 - base))}

def auroc(conf, correct):
    """Chance that a right answer gets a higher number than a wrong one (ties count half)."""
    conf, correct = np.asarray(conf, float), np.asarray(correct, bool)
    pos, neg = conf[correct], conf[~correct]
    if len(pos) == 0 or len(neg) == 0:
        return None
    return float((pos[:, None] > neg[None, :]).mean() + 0.5 * (pos[:, None] == neg[None, :]).mean())

def reliability_curve(conf, correct, n=10):
    conf, correct = np.asarray(conf, float), np.asarray(correct, float)
    idx = bands(conf, n)
    return [{"lo": i / n, "n": int((idx == i).sum()),
             "conf": float(conf[idx == i].mean()) if (idx == i).any() else None,
             "acc": float(correct[idx == i].mean()) if (idx == i).any() else None} for i in range(n)]

def selective(conf, correct, steps=20):
    c = np.asarray(correct, float)[np.argsort(-np.asarray(conf, float), kind="stable")]
    return [{"coverage": k / steps, "accuracy": float(c[:max(1, round(len(c) * k / steps))].mean())} for k in range(1, steps + 1)]

@torch.no_grad()
def predict(model, items, temps=None, batch_size=32):
    """-> one row per question: the chosen option and the full distribution."""
    model.eval()
    out = []
    for b in batches(items, batch_size, EVAL_DEV, shuffle=False):
        with torch.amp.autocast("cuda", dtype=torch.float16, enabled=EVAL_DEV == "cuda"):
            logits = model(b).float()
        for i, meta in enumerate(b["meta"]):
            z = logits[i, :meta["k"]]
            if temps:
                z = z / temps.get(meta["task"], 1.0)
            p = torch.softmax(z, -1).cpu().numpy()
            out.append({"task": meta["task"], "k": meta["k"], "label": meta["label"], "pred": int(p.argmax()),
                        "p_top": float(p.max()), "p_true": float(p[meta["label"]]),
                        "correct": int(p.argmax() == meta["label"]), "probs": p})
    return out

def summarize(rows):
    conf, corr = [r["p_top"] for r in rows], [r["correct"] for r in rows]
    return {"n": len(rows), "accuracy": float(np.mean(corr)), "mean_conf": float(np.mean(conf)),
            **brier_parts(conf, corr), "ece": ece(conf, corr), "auroc": auroc(conf, corr),
            "log_loss": float(np.mean([-math.log(max(r["p_true"], 1e-6)) for r in rows])),
            "brier_full": float(np.mean([((r["probs"] - np.eye(r["k"])[r["label"]]) ** 2).sum() for r in rows])),
            "curve": reliability_curve(conf, corr), "selective": selective(conf, corr)}

def fit_temperatures(model, items):
    """One temperature per task: the one that minimises the log loss on held-out questions."""
    rows = predict(model, items)
    grid = np.exp(np.linspace(np.log(0.25), np.log(8.0), 61))
    temps = {}
    for task in sorted({r["task"] for r in rows}):
        sub = [r for r in rows if r["task"] == task]
        logp = [np.log(np.clip(r["probs"], 1e-12, 1)) for r in sub]
        def nll(t):
            return np.mean([-(lp[r["label"]] / t - np.log(np.exp(lp / t - (lp / t).max()).sum()) - (lp / t).max())
                            for lp, r in zip(logp, sub)])
        temps[task] = float(grid[int(np.argmin([nll(t) for t in grid]))])
    return temps

def answers(rows):
    return [{"pred": r["pred"], "probs": [round(float(x), 4) for x in r["probs"]], "p_top": r["p_top"],
             "correct": r["correct"]} for r in rows]

RESULTS["questions"] = [{"task": q["task"], "type": q["type"], "state": q["state"][:300],
                         "options": q["options"], "label": q["label"]} for q in test_items]
evals = {}
for (kind, seed), model in models.items():
    model.to(EVAL_DEV)
    temps = fit_temperatures(model, fit_items)
    raw, cal = predict(model, test_items), predict(model, test_items, temps=temps)
    tasks = sorted({r["task"] for r in raw})
    evals[f"{kind}|{seed}"] = {"temperatures": temps, "raw": summarize(raw), "calibrated": summarize(cal),
        "by_task": {t: summarize([r for r in raw if r["task"] == t]) for t in tasks},
        "by_task_calibrated": {t: summarize([r for r in cal if r["task"] == t]) for t in tasks},
        "answers": answers(raw)}
    model.cpu()
    m, c = evals[f"{kind}|{seed}"]["raw"], evals[f"{kind}|{seed}"]["calibrated"]
    print(f"[{kind}/{seed}] acc {m['accuracy']:.3f} log loss {m['log_loss']:.3f} | raw: ece {m['ece']:.3f} "
          f"res {m['resolution']:.3f} auroc {m['auroc']:.3f} | after temperature: ece {c['ece']:.3f}", flush=True)
RESULTS["eval"] = evals
print("\naccuracy by task\n" + pd.DataFrame({k: {t: v["by_task"][t]["accuracy"] for t in v["by_task"]}
                                             for k, v in evals.items()}).T.to_string(float_format=lambda v: f"{v:.3f}"))
[narrow/0] acc 0.819 log loss 0.509 | raw: ece 0.091 res 0.038 auroc 0.883 | after temperature: ece 0.018
[cross_entropy/0] acc 0.816 log loss 0.427 | raw: ece 0.021 res 0.047 auroc 0.882 | after temperature: ece 0.017
[reinforce_centered/0] acc 0.803 log loss 0.472 | raw: ece 0.024 res 0.052 auroc 0.881 | after temperature: ece 0.025
[cross_entropy/1] acc 0.824 log loss 0.436 | raw: ece 0.013 res 0.041 auroc 0.870 | after temperature: ece 0.014
[reinforce_centered/1] acc 0.797 log loss 0.460 | raw: ece 0.024 res 0.059 auroc 0.888 | after temperature: ece 0.018
[proper_loss/0] acc 0.806 log loss 0.465 | raw: ece 0.027 res 0.050 auroc 0.871 | after temperature: ece 0.029
[reinforce_batch/0] acc 0.461 log loss 4.139 | raw: ece 0.337 res 0.062 auroc 0.551 | after temperature: ece 0.195
[reinforce_question_std/0] acc 0.792 log loss 0.584 | raw: ece 0.105 res 0.045 auroc 0.851 | after temperature: ece 0.020
[reinforce_centered_uncorrected/0] acc 0.799 log loss 0.509 | raw: ece 0.059 res 0.052 auroc 0.873 | after temperature: ece 0.021
[cross_entropy_large/0] acc 0.825 log loss 0.425 | raw: ece 0.026 res 0.042 auroc 0.869 | after temperature: ece 0.021
accuracy by task
ag_news sms_spam sst5
narrow|0 0.923 0.989 0.550
cross_entropy|0 0.928 0.993 0.532
reinforce_centered|0 0.926 0.998 0.490
cross_entropy|1 0.919 0.991 0.568
reinforce_centered|1 0.909 0.996 0.490
proper_loss|0 0.923 0.993 0.506
reinforce_batch|0 0.237 0.973 0.162
reinforce_question_std|0 0.907 0.989 0.486
reinforce_centered_uncorrected|0 0.912 0.993 0.497
cross_entropy_large|0 0.912 0.996 0.572kinds = ["narrow", "cross_entropy", "proper_loss", "reinforce_batch", "reinforce_question_std", "reinforce_centered", "reinforce_centered_uncorrected"]
fig, axes = plt.subplots(1, len(kinds), figsize=(14, 2.6), sharey=True)
for ax, kind in zip(axes, kinds):
key = f"{kind}|{SEEDS[0]}"
if key not in evals: continue
for which, col in (("raw", EMBER), ("calibrated", FOREST)):
pts = [(c["conf"], c["acc"]) for c in evals[key][which]["curve"] if c["n"] > 0]
ax.plot([p[0] for p in pts], [p[1] for p in pts], marker="o", ms=3, color=col, label=which)
ax.plot([0, 1], [0, 1], color=LINE, ls="--", lw=1)
ax.set_title(kind.replace("_", " "), loc="left", fontsize=8); ax.set_xlabel("stated probability")
axes[0].set_ylabel("observed accuracy"); axes[0].legend(frameon=False, fontsize=7)
plt.tight_layout(); plt.show()
Part 6 — the order of the options
The same held-out questions with the options shuffled and the right answer moved along. By construction nothing should change; this measures it on every trained model.
def shuffled(items, seed=11):
    rng = random.Random(seed)
    out = []
    for q in items:
        idx = list(range(len(q["options"])))
        while len(idx) > 1 and idx == sorted(idx):
            rng.shuffle(idx)
        out.append({**q, "options": [q["options"][i] for i in idx], "label": idx.index(q["label"])})
    return encode(out)

shuffled_items = shuffled(test_items)
order_test = {}
for (kind, seed), model in models.items():
    model.to(EVAL_DEV)
    a, b = predict(model, test_items), predict(model, shuffled_items)
    model.cpu()
    same = float(np.mean([x["correct"] == y["correct"] for x, y in zip(a, b)]))
    gap = float(max(abs(x["p_true"] - y["p_true"]) for x, y in zip(a, b)))
    order_test[f"{kind}|{seed}"] = {"same_verdict": same, "largest_change_in_p_true": gap,
                                    "by_task": {t: {"trained": float(np.mean([x["correct"] for x in a if x["task"] == t])),
                                                    "shuffled": float(np.mean([y["correct"] for y in b if y["task"] == t]))}
                                                for t in sorted({x["task"] for x in a})}}
RESULTS["option_order"] = order_test
print(pd.DataFrame({k: {"same answer": v["same_verdict"], "largest change in p(true)": v["largest_change_in_p_true"]}
                    for k, v in order_test.items()}).T.to_string(float_format=lambda v: f"{v:.2e}"))
same answer largest change in p(true)
narrow|0 9.99e-01 2.67e-03
cross_entropy|0 1.00e+00 2.34e-03
reinforce_centered|0 1.00e+00 1.91e-03
cross_entropy|1 1.00e+00 1.82e-03
reinforce_centered|1 1.00e+00 1.68e-03
proper_loss|0 1.00e+00 3.09e-03
reinforce_batch|0 9.99e-01 2.70e-03
reinforce_question_std|0 1.00e+00 2.26e-03
reinforce_centered_uncorrected|0 1.00e+00 2.11e-03
cross_entropy_large|0 1.00e+00 1.80e-03Part 7 — label sets no model has seen
Two schemas that appear nowhere in training: six emotions, and the seventy-seven intents of a bank’s customer-support inbox. No temperature can be fitted for them without their own labelled questions, so the probabilities are reported as they come.
emo = take(load_dataset("dair-ai/emotion", split="test"), ZS_N, 3)
EMO = [n.lower() for n in emo.features["label"].names]
emo_items = encode([{"task": "emotion", "type": "choice", "state": r["text"][:600],
                     "instructions": "Which emotion does this message express?",
                     "options": EMO, "label": int(r["label"])} for r in emo])
bank_all = load_dataset("mteb/banking77", split="test")
BANK = [n[0].replace("_", " ") for n in names_by_index(bank_all, "label", "label_text")]
bank = take(bank_all, ZS_N, 3)
bank_items = encode([{"task": "banking77", "type": "choice", "state": r["text"][:600],
                      "instructions": "Which banking request is this customer making?",
                      "options": BANK, "label": int(r["label"])} for r in bank])
print(f"emotion: {len(emo_items)} questions, {len(EMO)} options; banking: {len(bank_items)} questions, "
      f"{len(BANK)} options, {len(bank_items[0]['ids'])} tokens for the first one")

zero_shot = {"emotion": {}, "banking77": {}}
for (kind, seed), model in models.items():
    model.to(EVAL_DEV)
    e_rows, b_rows = predict(model, emo_items), predict(model, bank_items, batch_size=16)
    model.cpu()
    zero_shot["emotion"][f"{kind}|{seed}"] = {**summarize(e_rows), "answers": answers(e_rows),
                                              "pred_counts": np.bincount([r["pred"] for r in e_rows], minlength=len(EMO)).tolist()}
    top5 = [np.argsort(-r["probs"])[:5] for r in b_rows]
    zero_shot["banking77"][f"{kind}|{seed}"] = {**summarize(b_rows),
        "top5": float(np.mean([r["label"] in t for r, t in zip(b_rows, top5)])),
        "labels_used": len({r["pred"] for r in b_rows}),
        "answers": [{"pred": r["pred"], "p_top": r["p_top"], "p_true": round(r["p_true"], 4), "correct": r["correct"],
                     "top5": [[int(i), round(float(r["probs"][i]), 4)] for i in t]} for r, t in zip(b_rows, top5)]}
    e, bk = zero_shot["emotion"][f"{kind}|{seed}"], zero_shot["banking77"][f"{kind}|{seed}"]
    print(f"[{kind}/{seed}] emotion acc {e['accuracy']:.3f} conf {e['mean_conf']:.3f} ece {e['ece']:.3f} | "
          f"banking acc {bk['accuracy']:.3f} top-5 {bk['top5']:.3f} conf {bk['mean_conf']:.3f} ece {bk['ece']:.3f}", flush=True)
RESULTS["zero_shot"] = zero_shot
RESULTS["zero_shot_questions"] = {
    "emotion": {"options": EMO, "items": [{"state": q["state"][:300], "label": q["label"]} for q in emo_items]},
    "banking77": {"options": BANK, "items": [{"state": q["state"][:300], "label": q["label"]} for q in bank_items]}}
emotion: 800 questions, 6 options; banking: 800 questions, 77 options, 361 tokens for the first one
[narrow/0] emotion acc 0.403 conf 0.456 ece 0.060 | banking acc 0.045 top-5 0.106 conf 0.031 ece 0.014
[cross_entropy/0] emotion acc 0.527 conf 0.565 ece 0.062 | banking acc 0.209 top-5 0.477 conf 0.381 ece 0.172
[reinforce_centered/0] emotion acc 0.569 conf 0.536 ece 0.050 | banking acc 0.164 top-5 0.340 conf 0.240 ece 0.078
[cross_entropy/1] emotion acc 0.496 conf 0.532 ece 0.055 | banking acc 0.176 top-5 0.494 conf 0.402 ece 0.228
[reinforce_centered/1] emotion acc 0.550 conf 0.518 ece 0.072 | banking acc 0.089 top-5 0.346 conf 0.263 ece 0.174
[proper_loss/0] emotion acc 0.568 conf 0.599 ece 0.052 | banking acc 0.307 top-5 0.524 conf 0.356 ece 0.063
[reinforce_batch/0] emotion acc 0.163 conf 0.182 ece 0.019 | banking acc 0.010 top-5 0.066 conf 1.000 ece 0.990
[reinforce_question_std/0] emotion acc 0.520 conf 0.650 ece 0.137 | banking acc 0.116 top-5 0.341 conf 0.295 ece 0.181
[reinforce_centered_uncorrected/0] emotion acc 0.497 conf 0.643 ece 0.145 | banking acc 0.381 top-5 0.657 conf 0.307 ece 0.074
[cross_entropy_large/0] emotion acc 0.531 conf 0.574 ece 0.044 | banking acc 0.241 top-5 0.444 conf 0.458 ece 0.216Part 8 — what it costs to answer
@torch.no_grad()
def latency(model, items, batch_size, half, reps=20):
    model.eval()
    b = collate(items[:batch_size], EVAL_DEV)
    on_cuda = EVAL_DEV == "cuda"
    def run():
        with torch.amp.autocast("cuda", dtype=torch.float16, enabled=half and on_cuda):
            model(b)
    for _ in range(3): run()
    if on_cuda: torch.cuda.synchronize()
    t = time.time()
    for _ in range(reps): run()
    if on_cuda: torch.cuda.synchronize()
    dt = (time.time() - t) / reps
    return {"batch": batch_size, "precision": "fp16" if half else "fp32", "ms_total": dt * 1e3,
            "ms_per_question": dt * 1e3 / batch_size}

# the first seed of every model, so they outlive the session
import pathlib as _pl
outdir = _pl.Path("/kaggle/working") if _pl.Path("/kaggle/working").exists() else _pl.Path(".")
saved = []
for (kind, seed), model in models.items():
    if seed != SEEDS[0]: continue
    path = outdir / f"decision-{kind}.pt"
    torch.save({k: v.half().cpu() for k, v in model.state_dict().items()}, path)
    saved.append({"kind": kind, "file": path.name, "mb": round(path.stat().st_size / 2**20, 1)})
print(pd.DataFrame(saved).to_string(index=False))
RESULTS["checkpoints"] = saved

cost = {}
for kind in ("cross_entropy", "cross_entropy_large"):
    if (kind, SEEDS[0]) not in models: continue
    model = models[(kind, SEEDS[0])].to(EVAL_DEV)
    cost[kind] = {"test": [latency(model, test_items, bs, half) for half in (False, True) for bs in (1, 5, 10, 50)],
                  "banking77": [latency(model, bank_items, bs, True) for bs in (1, 10)]}
    model.cpu()
    print(kind); print(pd.DataFrame(cost[kind]["test"] + cost[kind]["banking77"]).to_string(index=False, float_format=lambda v: f"{v: .2f}"))
RESULTS["latency"] = cost
RESULTS["meta"]["minutes"] = (time.time() - T0) / 60
print(f"\nwhole notebook: {RESULTS['meta']['minutes']:.0f} min")
kind file mb
narrow decision-narrow.pt 286.5
cross_entropy decision-cross_entropy.pt 286.5
reinforce_centered decision-reinforce_centered.pt 286.5
proper_loss decision-proper_loss.pt 286.5
reinforce_batch decision-reinforce_batch.pt 286.5
reinforce_question_std decision-reinforce_question_std.pt 286.5
reinforce_centered_uncorrected decision-reinforce_centered_uncorrected.pt 286.5
cross_entropy_large decision-cross_entropy_large.pt 757.1
cross_entropy
batch precision ms_total ms_per_question
1 fp32 23.09 23.09
5 fp32 46.52 9.30
10 fp32 93.66 9.37
50 fp32 507.62 10.15
1 fp16 22.90 22.90
5 fp16 25.49 5.10
10 fp16 29.17 2.92
50 fp16 167.37 3.35
1 fp16 23.20 23.20
10 fp16 129.88 12.99
cross_entropy_large
batch precision ms_total ms_per_question
1 fp32 37.17 37.17
5 fp32 143.99 28.80
10 fp32 254.14 25.41
50 fp32 1298.63 25.97
1 fp16 29.81 29.81
5 fp16 39.61 7.92
10 fp16 71.86 7.19
50 fp16 370.76 7.42
1 fp16 34.75 34.75
10 fp16 282.00 28.20
whole notebook: 137 minPart 9 — the final model: options that do not read each other
Parts 4–8 found one weak spot: on the seventy-seven banking intents the models above are right about one time in five. An option there reads the text, the question and all seventy-six other options — some four hundred tokens of other labels’ names against a couple of dozen of the message. The final model changes one thing, the mask: an option reads the text, the question and its own tokens, and nothing else. From each option’s point of view a question with seventy-seven options then looks exactly like one with four, and an option’s logit no longer depends on which others are offered (its probability still does, through the softmax).
This part ran as a second session on the same kind of card, with the same code as Parts 1–3, the new mask below, and cross-entropy with both seeds and with the large encoder. The cells after the mask are the ones from Parts 4–8, unchanged; they are folded. In one fresh run of this whole notebook, this part would replace the models of Parts 4–8, so each part’s outputs here are the ones its own session printed.
def who_reads_whom(seg, pos):
    """[B, L, L] booleans, query token i may read key token j. The text reads the text; the question reads
    the text and itself; an option reads the text, the question and its own tokens — not the other options."""
    qs, ks = seg[:, :, None], seg[:, None, :]
    real = ks >= 0
    context = (ks == 0) | (ks == 1)
    full = torch.where(qs == 0, ks == 0, torch.where(qs == 1, context, context | (ks == qs))) & real
    full = full | torch.eye(seg.size(1), dtype=torch.bool, device=seg.device)[None]
    local = full & ((pos[:, :, None] - pos[:, None, :]).abs() <= LOCAL_REACH)
    return full, local

JOBS = [("cross_entropy", s) for s in SEEDS] + [("cross_entropy_large", SEEDS[0])]
print(len(JOBS), "runs:", JOBS)

# the same three checks, with the new mask, on an untrained model — plus one more: an option's logit no
# longer depends on which other options are offered
torch.manual_seed(0)
_m = DecisionModel().to(DEV).eval()
with torch.no_grad():
    a = _m(collate(encode([_q]), DEV))[0]
    b = _m(collate(encode([{**_q, "options": [_q["options"][i] for i in _perm]}]), DEV))[0]
    c = _m(collate(encode([{**_q, "options": _q["options"][:2]}]), DEV))[0]
print(f"options permuted: largest change in a logit {max(abs(float(a[i]) - float(b[_perm.index(i)])) for i in range(4)):.1e}")
print(f"two options instead of four: largest change in their logits {float((a[:2] - c[:2]).abs().max()):.1e}")
del _m
3 runs: [('cross_entropy', 0), ('cross_entropy', 1), ('cross_entropy_large', 0)]options permuted: largest change in a logit 2.1e-07
two options instead of four: largest change in their logits 0.0e+00Training — the same cell as in Part 4
TRAIN_DEV = "cuda" if DEV == "cuda" else DEV

def train(kind, seed):
    large = kind == "cross_entropy_large"
    data = EPOCH_DATA["narrow" if kind == "narrow" else "broad"][seed]
    loss_fn = loss_cross_entropy if kind in ("narrow", "cross_entropy_large") else TRAINERS[kind]
    torch.manual_seed(seed)
    model = DecisionModel(ENCODER_LARGE if large else ENCODER).to(TRAIN_DEV)
    micro, accum = (BATCH // 2, 2) if large else (BATCH, 1)
    lr = LR * 0.75 if large else LR
    amp = TRAIN_DEV == "cuda"
    scaler = torch.amp.GradScaler("cuda", enabled=amp)
    opt = torch.optim.AdamW(model.parameters(), lr=lr, weight_decay=0.01)
    updates = sum(math.ceil(len(e) / micro) for e in data) // accum
    sched = torch.optim.lr_scheduler.OneCycleLR(opt, max_lr=lr, total_steps=updates + 1, pct_start=0.1)
    log, t0, step, n_micro = [], time.time(), 0, 0
    model.train()
    opt.zero_grad(set_to_none=True)
    for ep, items in enumerate(data):
        for b in batches(items, micro, TRAIN_DEV, seed=1000 * seed + ep):
            with torch.amp.autocast("cuda", dtype=torch.float16, enabled=amp):
                loss, logits = loss_fn(model, b)
            scaler.scale(loss / accum).backward()
            n_micro += 1
            if n_micro % accum:
                continue
            scaler.unscale_(opt)
            nn.utils.clip_grad_norm_(model.parameters(), 1.0)
            scaler.step(opt); scaler.update(); sched.step(); step += 1
            opt.zero_grad(set_to_none=True)
            if step % 25 == 0 or step == updates:
                acc = (logits.argmax(-1) == b["label"]).float().mean().item()
                log.append({"step": step, "loss": float(loss.detach()), "batch_acc": acc,
                            "minutes": (time.time() - t0) / 60})
                if step % 250 == 0 or step == 25:
                    pace = log[-1]["minutes"] / step
                    print(f"  [{kind}/{seed}] step {step}/{updates} loss {log[-1]['loss']:.4f} acc {acc:.3f} · "
                          f"{log[-1]['minutes']:.1f}m · this run ≈ {pace * updates:.0f}m", flush=True)
    model.zero_grad(set_to_none=True)
    return model, log

models, training = {}, {}
for kind, seed in JOBS:
    print(f"=== {kind}, seed {seed} ({(time.time() - T0) / 60:.0f} min since the start) ===", flush=True)
    m, log = train(kind, seed)
    models[(kind, seed)] = m.cpu()                     # parked in RAM: the card holds one model at a time
    training[f"{kind}|{seed}"] = log
    del m
    if TRAIN_DEV == "cuda":
        torch.cuda.empty_cache()
RESULTS["training"] = training
print(f"trained {len(models)} models in {(time.time() - T0) / 60:.0f} min since the start")
=== cross_entropy, seed 0 (2 min since the start) === [cross_entropy/0] step 25/2000 loss 1.6257 acc 0.469 · 0.1m · this run ≈ 12m
[cross_entropy/0] step 250/2000 loss 0.6905 acc 0.688 · 1.4m · this run ≈ 11m
[cross_entropy/0] step 500/2000 loss 0.4748 acc 0.688 · 2.8m · this run ≈ 11m
[cross_entropy/0] step 750/2000 loss 0.2923 acc 0.906 · 4.2m · this run ≈ 11m
[cross_entropy/0] step 1000/2000 loss 0.4016 acc 0.906 · 5.6m · this run ≈ 11m
[cross_entropy/0] step 1250/2000 loss 0.7730 acc 0.750 · 7.0m · this run ≈ 11m
[cross_entropy/0] step 1500/2000 loss 0.3623 acc 0.906 · 8.5m · this run ≈ 11m
[cross_entropy/0] step 1750/2000 loss 0.2537 acc 0.844 · 9.9m · this run ≈ 11m
[cross_entropy/0] step 2000/2000 loss 0.4655 acc 0.781 · 11.2m · this run ≈ 11m
=== cross_entropy, seed 1 (13 min since the start) === [cross_entropy/1] step 25/2000 loss 1.8705 acc 0.469 · 0.2m · this run ≈ 12m
[cross_entropy/1] step 250/2000 loss 0.7267 acc 0.781 · 1.4m · this run ≈ 12m
[cross_entropy/1] step 500/2000 loss 0.6664 acc 0.750 · 2.8m · this run ≈ 11m
[cross_entropy/1] step 750/2000 loss 0.3656 acc 0.812 · 4.3m · this run ≈ 11m
[cross_entropy/1] step 1000/2000 loss 0.6018 acc 0.688 · 5.7m · this run ≈ 11m
[cross_entropy/1] step 1250/2000 loss 0.3945 acc 0.812 · 7.1m · this run ≈ 11m
[cross_entropy/1] step 1500/2000 loss 0.3759 acc 0.875 · 8.4m · this run ≈ 11m
[cross_entropy/1] step 1750/2000 loss 0.2461 acc 0.906 · 9.8m · this run ≈ 11m
[cross_entropy/1] step 2000/2000 loss 0.6821 acc 0.719 · 11.3m · this run ≈ 11m
=== cross_entropy_large, seed 0 (24 min since the start) === [cross_entropy_large/0] step 25/2000 loss 1.3746 acc 0.438 · 0.4m · this run ≈ 33m
[cross_entropy_large/0] step 250/2000 loss 2.1322 acc 0.375 · 3.6m · this run ≈ 29m
[cross_entropy_large/0] step 500/2000 loss 0.7482 acc 0.750 · 7.3m · this run ≈ 29m
[cross_entropy_large/0] step 750/2000 loss 0.1205 acc 0.938 · 10.9m · this run ≈ 29m
[cross_entropy_large/0] step 1000/2000 loss 0.8666 acc 0.812 · 14.5m · this run ≈ 29m
[cross_entropy_large/0] step 1250/2000 loss 0.3232 acc 0.875 · 18.1m · this run ≈ 29m
[cross_entropy_large/0] step 1500/2000 loss 0.6665 acc 0.688 · 21.9m · this run ≈ 29m
[cross_entropy_large/0] step 1750/2000 loss 0.3939 acc 0.875 · 25.4m · this run ≈ 29m
[cross_entropy_large/0] step 2000/2000 loss 0.3271 acc 0.875 · 28.9m · this run ≈ 29m
trained 3 models in 53 min since the startEvaluation — the same cell as in Part 5
EVAL_DEV = TRAIN_DEV

def bands(conf, n):
    """Index of the confidence band each value falls in, n equal bands over [0, 1]."""
    return np.minimum((np.asarray(conf) * n).astype(int), n - 1)

def ece(conf, correct, n=15):
    conf, correct = np.asarray(conf, float), np.asarray(correct, float)
    idx = bands(conf, n)
    return float(sum((idx == i).mean() * abs(conf[idx == i].mean() - correct[idx == i].mean())
                     for i in range(n) if (idx == i).any()))

def brier_parts(conf, correct, n=10):
    conf, correct = np.asarray(conf, float), np.asarray(correct, float)
    base, idx = correct.mean(), bands(conf, n)
    rel = sum((idx == i).mean() * (conf[idx == i].mean() - correct[idx == i].mean()) ** 2 for i in range(n) if (idx == i).any())
    res = sum((idx == i).mean() * (correct[idx == i].mean() - base) ** 2 for i in range(n) if (idx == i).any())
    return {"brier": float(((conf - correct) ** 2).mean()), "reliability": float(rel),
            "resolution": float(res), "uncertainty": float(base * (1 - base))}

def auroc(conf, correct):
    """Chance that a right answer gets a higher number than a wrong one (ties count half)."""
    conf, correct = np.asarray(conf, float), np.asarray(correct, bool)
    pos, neg = conf[correct], conf[~correct]
    if len(pos) == 0 or len(neg) == 0:
        return None
    return float((pos[:, None] > neg[None, :]).mean() + 0.5 * (pos[:, None] == neg[None, :]).mean())

def reliability_curve(conf, correct, n=10):
    conf, correct = np.asarray(conf, float), np.asarray(correct, float)
    idx = bands(conf, n)
    return [{"lo": i / n, "n": int((idx == i).sum()),
             "conf": float(conf[idx == i].mean()) if (idx == i).any() else None,
             "acc": float(correct[idx == i].mean()) if (idx == i).any() else None} for i in range(n)]

def selective(conf, correct, steps=20):
    c = np.asarray(correct, float)[np.argsort(-np.asarray(conf, float), kind="stable")]
    return [{"coverage": k / steps, "accuracy": float(c[:max(1, round(len(c) * k / steps))].mean())} for k in range(1, steps + 1)]

@torch.no_grad()
def predict(model, items, temps=None, batch_size=32):
    """-> one row per question: the chosen option and the full distribution."""
    model.eval()
    out = []
    for b in batches(items, batch_size, EVAL_DEV, shuffle=False):
        with torch.amp.autocast("cuda", dtype=torch.float16, enabled=EVAL_DEV == "cuda"):
            logits = model(b).float()
        for i, meta in enumerate(b["meta"]):
            z = logits[i, :meta["k"]]
            if temps:
                z = z / temps.get(meta["task"], 1.0)
            p = torch.softmax(z, -1).cpu().numpy()
            out.append({"task": meta["task"], "k": meta["k"], "label": meta["label"], "pred": int(p.argmax()),
                        "p_top": float(p.max()), "p_true": float(p[meta["label"]]),
                        "correct": int(p.argmax() == meta["label"]), "probs": p})
    return out

def summarize(rows):
    conf, corr = [r["p_top"] for r in rows], [r["correct"] for r in rows]
    return {"n": len(rows), "accuracy": float(np.mean(corr)), "mean_conf": float(np.mean(conf)),
            **brier_parts(conf, corr), "ece": ece(conf, corr), "auroc": auroc(conf, corr),
            "log_loss": float(np.mean([-math.log(max(r["p_true"], 1e-6)) for r in rows])),
            "brier_full": float(np.mean([((r["probs"] - np.eye(r["k"])[r["label"]]) ** 2).sum() for r in rows])),
            "curve": reliability_curve(conf, corr), "selective": selective(conf, corr)}

def fit_temperatures(model, items):
    """One temperature per task: the one that minimises the log loss on held-out questions."""
    rows = predict(model, items)
    grid = np.exp(np.linspace(np.log(0.25), np.log(8.0), 61))
    temps = {}
    for task in sorted({r["task"] for r in rows}):
        sub = [r for r in rows if r["task"] == task]
        logp = [np.log(np.clip(r["probs"], 1e-12, 1)) for r in sub]
        def nll(t):
            return np.mean([-(lp[r["label"]] / t - np.log(np.exp(lp / t - (lp / t).max()).sum()) - (lp / t).max())
                            for lp, r in zip(logp, sub)])
        temps[task] = float(grid[int(np.argmin([nll(t) for t in grid]))])
    return temps

def answers(rows):
    return [{"pred": r["pred"], "probs": [round(float(x), 4) for x in r["probs"]], "p_top": r["p_top"],
             "correct": r["correct"]} for r in rows]

RESULTS["questions"] = [{"task": q["task"], "type": q["type"], "state": q["state"][:300],
                         "options": q["options"], "label": q["label"]} for q in test_items]
evals = {}
for (kind, seed), model in models.items():
    model.to(EVAL_DEV)
    temps = fit_temperatures(model, fit_items)
    raw, cal = predict(model, test_items), predict(model, test_items, temps=temps)
    tasks = sorted({r["task"] for r in raw})
    evals[f"{kind}|{seed}"] = {"temperatures": temps, "raw": summarize(raw), "calibrated": summarize(cal),
        "by_task": {t: summarize([r for r in raw if r["task"] == t]) for t in tasks},
        "by_task_calibrated": {t: summarize([r for r in cal if r["task"] == t]) for t in tasks},
        "answers": answers(raw)}
    model.cpu()
    m, c = evals[f"{kind}|{seed}"]["raw"], evals[f"{kind}|{seed}"]["calibrated"]
    print(f"[{kind}/{seed}] acc {m['accuracy']:.3f} log loss {m['log_loss']:.3f} | raw: ece {m['ece']:.3f} "
          f"res {m['resolution']:.3f} auroc {m['auroc']:.3f} | after temperature: ece {c['ece']:.3f}", flush=True)
RESULTS["eval"] = evals
print("\naccuracy by task\n" + pd.DataFrame({k: {t: v["by_task"][t]["accuracy"] for t in v["by_task"]}
                                             for k, v in evals.items()}).T.to_string(float_format=lambda v: f"{v:.3f}"))
[cross_entropy/0] acc 0.815 log loss 0.432 | raw: ece 0.027 res 0.046 auroc 0.877 | after temperature: ece 0.019
[cross_entropy/1] acc 0.815 log loss 0.435 | raw: ece 0.022 res 0.047 auroc 0.878 | after temperature: ece 0.024
[cross_entropy_large/0] acc 0.818 log loss 0.426 | raw: ece 0.032 res 0.044 auroc 0.870 | after temperature: ece 0.026
accuracy by task
ag_news sms_spam sst5
cross_entropy|0 0.923 0.993 0.534
cross_entropy|1 0.914 0.993 0.543
cross_entropy_large|0 0.902 0.993 0.563The order of the options — the same cell as in Part 6
def shuffled(items, seed=11):
    rng = random.Random(seed)
    out = []
    for q in items:
        idx = list(range(len(q["options"])))
        while len(idx) > 1 and idx == sorted(idx):
            rng.shuffle(idx)
        out.append({**q, "options": [q["options"][i] for i in idx], "label": idx.index(q["label"])})
    return encode(out)

shuffled_items = shuffled(test_items)
order_test = {}
for (kind, seed), model in models.items():
    model.to(EVAL_DEV)
    a, b = predict(model, test_items), predict(model, shuffled_items)
    model.cpu()
    same = float(np.mean([x["correct"] == y["correct"] for x, y in zip(a, b)]))
    gap = float(max(abs(x["p_true"] - y["p_true"]) for x, y in zip(a, b)))
    order_test[f"{kind}|{seed}"] = {"same_verdict": same, "largest_change_in_p_true": gap,
                                    "by_task": {t: {"trained": float(np.mean([x["correct"] for x in a if x["task"] == t])),
                                                    "shuffled": float(np.mean([y["correct"] for y in b if y["task"] == t]))}
                                                for t in sorted({x["task"] for x in a})}}
RESULTS["option_order"] = order_test
print(pd.DataFrame({k: {"same answer": v["same_verdict"], "largest change in p(true)": v["largest_change_in_p_true"]}
                    for k, v in order_test.items()}).T.to_string(float_format=lambda v: f"{v:.2e}"))
same answer largest change in p(true)
cross_entropy|0 1.00e+00 1.45e-03
cross_entropy|1 9.99e-01 1.28e-03
cross_entropy_large|0 1.00e+00 1.33e-03Label sets no model has seen — the same cell as in Part 7
emo = take(load_dataset("dair-ai/emotion", split="test"), ZS_N, 3)
EMO = [n.lower() for n in emo.features["label"].names]
emo_items = encode([{"task": "emotion", "type": "choice", "state": r["text"][:600],
                     "instructions": "Which emotion does this message express?",
                     "options": EMO, "label": int(r["label"])} for r in emo])
bank_all = load_dataset("mteb/banking77", split="test")
BANK = [n[0].replace("_", " ") for n in names_by_index(bank_all, "label", "label_text")]
bank = take(bank_all, ZS_N, 3)
bank_items = encode([{"task": "banking77", "type": "choice", "state": r["text"][:600],
                      "instructions": "Which banking request is this customer making?",
                      "options": BANK, "label": int(r["label"])} for r in bank])
print(f"emotion: {len(emo_items)} questions, {len(EMO)} options; banking: {len(bank_items)} questions, "
      f"{len(BANK)} options, {len(bank_items[0]['ids'])} tokens for the first one")

zero_shot = {"emotion": {}, "banking77": {}}
for (kind, seed), model in models.items():
    model.to(EVAL_DEV)
    e_rows, b_rows = predict(model, emo_items), predict(model, bank_items, batch_size=16)
    model.cpu()
    zero_shot["emotion"][f"{kind}|{seed}"] = {**summarize(e_rows), "answers": answers(e_rows),
                                              "pred_counts": np.bincount([r["pred"] for r in e_rows], minlength=len(EMO)).tolist()}
    top5 = [np.argsort(-r["probs"])[:5] for r in b_rows]
    zero_shot["banking77"][f"{kind}|{seed}"] = {**summarize(b_rows),
        "top5": float(np.mean([r["label"] in t for r, t in zip(b_rows, top5)])),
        "labels_used": len({r["pred"] for r in b_rows}),
        "answers": [{"pred": r["pred"], "p_top": r["p_top"], "p_true": round(r["p_true"], 4), "correct": r["correct"],
                     "top5": [[int(i), round(float(r["probs"][i]), 4)] for i in t]} for r, t in zip(b_rows, top5)]}
    e, bk = zero_shot["emotion"][f"{kind}|{seed}"], zero_shot["banking77"][f"{kind}|{seed}"]
    print(f"[{kind}/{seed}] emotion acc {e['accuracy']:.3f} conf {e['mean_conf']:.3f} ece {e['ece']:.3f} | "
          f"banking acc {bk['accuracy']:.3f} top-5 {bk['top5']:.3f} conf {bk['mean_conf']:.3f} ece {bk['ece']:.3f}", flush=True)
RESULTS["zero_shot"] = zero_shot
RESULTS["zero_shot_questions"] = {
    "emotion": {"options": EMO, "items": [{"state": q["state"][:300], "label": q["label"]} for q in emo_items]},
    "banking77": {"options": BANK, "items": [{"state": q["state"][:300], "label": q["label"]} for q in bank_items]}}
emotion: 800 questions, 6 options; banking: 800 questions, 77 options, 361 tokens for the first one
[cross_entropy/0] emotion acc 0.492 conf 0.509 ece 0.065 | banking acc 0.551 top-5 0.799 conf 0.559 ece 0.050
[cross_entropy/1] emotion acc 0.453 conf 0.542 ece 0.090 | banking acc 0.530 top-5 0.782 conf 0.597 ece 0.077
[cross_entropy_large/0] emotion acc 0.540 conf 0.668 ece 0.131 | banking acc 0.565 top-5 0.811 conf 0.583 ece 0.055Checkpoints and timing — the same cell as in Part 8
@torch.no_grad()
def latency(model, items, batch_size, half, reps=20):
    model.eval()
    b = collate(items[:batch_size], EVAL_DEV)
    on_cuda = EVAL_DEV == "cuda"
    def run():
        with torch.amp.autocast("cuda", dtype=torch.float16, enabled=half and on_cuda):
            model(b)
    for _ in range(3): run()
    if on_cuda: torch.cuda.synchronize()
    t = time.time()
    for _ in range(reps): run()
    if on_cuda: torch.cuda.synchronize()
    dt = (time.time() - t) / reps
    return {"batch": batch_size, "precision": "fp16" if half else "fp32", "ms_total": dt * 1e3,
            "ms_per_question": dt * 1e3 / batch_size}

# the first seed of every model, so they outlive the session
import pathlib as _pl
outdir = _pl.Path("/kaggle/working") if _pl.Path("/kaggle/working").exists() else _pl.Path(".")
saved = []
for (kind, seed), model in models.items():
    if seed != SEEDS[0]: continue
    path = outdir / f"decision-{kind}.pt"
    torch.save({k: v.half().cpu() for k, v in model.state_dict().items()}, path)
    saved.append({"kind": kind, "file": path.name, "mb": round(path.stat().st_size / 2**20, 1)})
print(pd.DataFrame(saved).to_string(index=False))
RESULTS["checkpoints"] = saved

cost = {}
for kind in ("cross_entropy", "cross_entropy_large"):
    if (kind, SEEDS[0]) not in models: continue
    model = models[(kind, SEEDS[0])].to(EVAL_DEV)
    cost[kind] = {"test": [latency(model, test_items, bs, half) for half in (False, True) for bs in (1, 5, 10, 50)],
                  "banking77": [latency(model, bank_items, bs, True) for bs in (1, 10)]}
    model.cpu()
    print(kind); print(pd.DataFrame(cost[kind]["test"] + cost[kind]["banking77"]).to_string(index=False, float_format=lambda v: f"{v: .2f}"))
RESULTS["latency"] = cost
RESULTS["meta"]["minutes"] = (time.time() - T0) / 60
print(f"\nwhole notebook: {RESULTS['meta']['minutes']:.0f} min")
kind file mb
cross_entropy decision-cross_entropy.pt 286.5
cross_entropy_large decision-cross_entropy_large.pt 757.1
cross_entropy
batch precision ms_total ms_per_question
1 fp32 19.63 19.63
5 fp32 46.10 9.22
10 fp32 91.22 9.12
50 fp32 487.24 9.74
1 fp16 23.96 23.96
5 fp16 24.17 4.83
10 fp16 28.64 2.86
50 fp16 156.90 3.14
1 fp16 23.04 23.04
10 fp16 123.90 12.39
cross_entropy_large
batch precision ms_total ms_per_question
1 fp32 35.84 35.84
5 fp32 137.98 27.60
10 fp32 245.61 24.56
50 fp32 1294.83 25.90
1 fp16 30.25 30.25
5 fp16 39.42 7.88
10 fp16 70.97 7.10
50 fp16 367.73 7.35
1 fp16 34.95 34.95
10 fp16 281.61 28.16
whole notebook: 57 min