Chapter 15 of 15
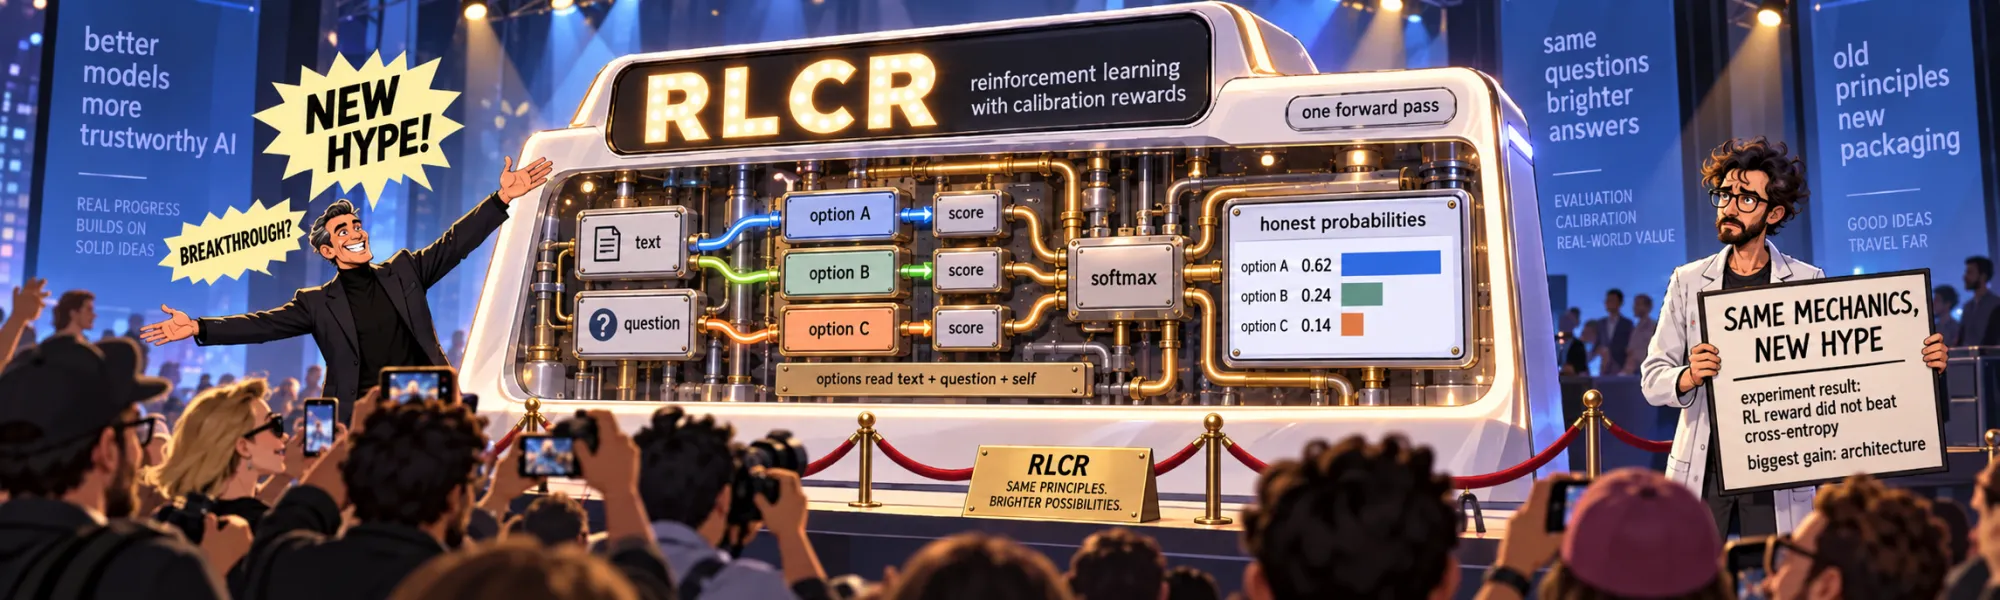
RLCR from Scratch: A One-Pass Decision Model with Honest Probabilities
Created Sep 20, 2026 Updated Sep 22, 2026
A model reads a support ticket, decides it belongs to billing, and returns 0.94. The program
downstream is happy: it has a decision and a number to threshold on, so it knows when to hand the
ticket to a person instead. Everything rests on what that number is a statement about, and on
whether anything in the model's training ever made it true.
A wave of commercial "calibrated decision" models made this concrete: a request goes in with a few typed questions, a typed answer comes out with a probability, in tens of milliseconds, and the probability is claimed to be trustworthy because the model was trained with reinforcement learning against a reward that pays only for honest probabilities. Jev is the loudest of them right now, in September 2026.
I don't know how Jev was actually built. This note works out how I would build such a model myself, from scratch, and then uses it to take the claim apart. I set out to reproduce the calibration-reward idea; the reward turned out not to be the important part. The model is kept small enough to train on a single free T4 GPU in about twelve minutes a run. That matters because one training run proves little here. The questions the note asks are comparisons: the same model trained with different signals, each with more than one random seed where it counts, next to a control trained the naive way. That makes thirteen training runs, not one.
What gets built. The base is ModernBERT-base, an ordinary pretrained 149-million-parameter encoder, never fine-tuned for a decision task. A request goes in as one sequence: the text being judged, the question, and then every option as its own parallel branch. All the branches start at the same position, so no option comes first, and a mask decides who reads whom. A small read-out turns each branch into one number, and a softmax over those numbers gives the answer and its probability. Nothing is generated, so every decision costs one forward pass.
What it is trained on. Public labelled text, turned into typed questions:
- news sections, encyclopedia categories, forum topics, newsgroups, question types, and the intents of voice-assistant requests (up to sixty options) as choice questions;
- movie-review sentiment, Yelp star ratings and tweet sentiment as scale questions;
- spam, positive movie reviews, and "does this label describe this text?" questions built from the choice datasets as yes/no questions.
Label names and questions are reworded from one question to the next, and choice questions often offer only some of their labels. Two label sets are never used as options in training, to test what the model does with labels it was not trained on: six emotions, and the seventy-seven intents of a bank's support inbox.
How it is trained, and how it ends. The same model is trained seven ways: with cross-entropy, with a proper scoring rule as the loss, with that rule as a reinforcement-learning reward under three baselines and with and without one correction, and a narrow control on three datasets. That comparison finds what the reward adds. Then one thing changes for the final model, the mask between options, and the final model is trained once more, also with an encoder two and a half times larger.
Step 0 — three different numbers, all called confidence
Before any code, three things that a single field called confidence can mean:
- Probability of an event. "It will rain tomorrow: 0.8." A statement about the world.
- Probability of a class. A softmax entry for billing among four departments. A statement about one label under a fixed set of labels.
- Probability that this answer is correct. "I chose billing; I am 0.94 likely to be right." A statement about the model's own output.
For a model that picks among given options, the second and third coincide for the chosen option: the probability assigned to billing is the claimed chance that billing is right. That is what makes the typed-decision design attractive — and it is only true if the probabilities were trained to mean it.
Step 1 — why a reward for being right does not ask for probabilities
Take the simplest possible decision: a yes/no question whose answer is yes with probability . Reward the model 1 for a correct answer and 0 otherwise. If its policy says yes with probability , it earns on average
which for is largest at . The best policy under a correctness reward always says yes. That is correct behaviour for that reward — and it means the policy's probability of an action has been pushed to 1 while the probability of the event is still . Reading one as the other is the classic mistake, and nothing in a correctness reward prevents it.
Step 2 — a reward that only an honest probability can maximise
Change what the model outputs. Instead of choosing, it reports a probability , and is scored against what happened, , with the squared error. For an event of true probability :
The second term does not depend on . The first is smallest exactly at . A score with this property — its unique optimum is the true distribution — is called strictly proper, and it is the whole mechanism. The model never needs to be shown the hidden ; observed outcomes are enough. It is a property of the average, though: the best possible report, over the whole distribution the data come from, is the true probability. A finite network trained on finite data, then asked about data a little unlike its training set, is promised nothing — which is why the rest of this note measures instead of assuming.
The logarithmic score, , is strictly proper too, and so is the spherical score, . For ordered answers — not urgent, soon, critical — the ranked probability score compares cumulative distributions, so that predicting soon when the truth is critical costs less than predicting not urgent.
RLCR — reinforcement learning with calibration rewards — is the idea of using such a score as the reward. In its best-known form the model writes an answer and a stated confidence , and receives
which pays for being right () and for stating an honest confidence at the same time. For an answer that is correct with probability , the expectation is
honesty () is optimal whatever the answer's quality, and once the confidence is honest a better answer still earns more (). One reward, two jobs, no coefficient to tune.
A frequent objection: if the answer turns out to be right, stating 1.0 would have scored better than stating 0.8. True — but only after the outcome is known. A proper score is a statement about the average over outcomes, which is the only thing a model can optimise before seeing them.
Step 3 — the model: one forward pass, one score per option
The model does not generate text. It reads the request once, and every option it could choose gets a score from that single pass. Two decisions make that work: where the options go, and who reads whom.
The options go into the input, as parallel branches. The text comes first, then the question, then every option. Each option is a short branch of its own, and every branch starts at the same position, the one right after the question. The encoder here encodes positions as rotations, so to it no option is earlier or later than another.
position:  0     1 … n      n+1    n+2 … m     m+1  │ m+2 …         │ m+2 …         │ m+2 …
token:     [CLS] the text   [SEP]  question    [SEP]│ option 0 [SEP] │ option 1 [SEP] │ option 2 [SEP]
def lay_out(text, question, options):
"""-> token ids, position ids, and a segment per token: 0 the text, 1 the question, 2 + i option i."""
t, q = ids_of(text)[:256], ids_of(question)[:48]
ids = [CLS] + t + [SEP] + q + [SEP]
seg = [0] * (len(t) + 2) + [1] * (len(q) + 1)
pos = list(range(len(ids)))
start = len(ids)
for i, o in enumerate(options):
o_ids = ids_of(" " + o)[:12] + [SEP]
ids += o_ids
seg += [2 + i] * len(o_ids)
pos += range(start, start + len(o_ids)) # every option restarts at the same position
return ids, pos, segA mask decides who reads whom. The text reads only the text. The question reads the text and itself. An option reads the text, the question and — in the first version of the model — every other option too. The encoder takes the mask and the positions as they are.
def who_reads_whom(seg):
    q, k = seg[:, :, None], seg[:, None, :]
    return torch.where(q == 0, k == 0,                          # the text reads the text
           torch.where(q == 1, (k == 0) | (k == 1),             # the question: text and itself
                       k >= 0))                                 # an option: everything
The read-out is small. Each option's final token states are averaged into one vector, a small network turns that vector (next to the summary token's) into one number, and a softmax over the numbers is the answer.
Three properties follow by construction rather than by training, and the lab checks each numerically before anything is trained. Reordering the options changes no number: the largest change in any logit was 1.3 × 10⁻⁷, rounding. The text's own states do not depend on the options at all, exactly. And because the text never reads the question either, a text asked several questions only needs to be read once.
Three kinds of question share this model — the primitives of a decision model:
| primitive | answers | example |
|---|---|---|
| choice | one of several unordered labels | which department |
| scale | a level on an ordered scale | how urgent |
| yes/no | whether something is true | is this spam |
Step 4 — seven ways to train the same weights
This is where the method either earns its name or does not. A strictly proper score is a reward, and with its sign flipped it is also a perfectly good loss. The score used here is the one Step 2 derives, the squared error between the reported distribution and what happened, summed over the options — the Brier score — and, for an ordered scale, the same squared error on the cumulative distribution, so that positive for a very positive review costs less than negative.
Cross-entropy. The ordinary classification loss. It is the logarithmic score in disguise, so it is already strictly proper.
loss = F.cross_entropy(logits, target)The Brier score as a loss. Differentiated straight through the softmax.
loss = -proper_score(torch.softmax(logits, -1), batch).mean()The Brier score as a reward. The model becomes a policy that reports a distribution. It explores by drawing reports from a Dirichlet whose mean is its own softmax, , scores each report, compares the score with a baseline, and moves toward reports that beat it.
alpha = kappa * torch.softmax(logits, -1)
q = dirichlet_draws(alpha, reports)                      # reports per question, drawn without gradient
r = proper_score(q, batch, correction=alpha.sum(-1))     # the correction is explained in Step 5
adv = baseline(r)
loss = -(adv * dirichlet_log_density(q, alpha)).mean()   # the log-density is a function of the logits
On average a report is exactly , the distribution the model will ship. The one line that has to be right for anything to be learned is the last: the log-density of the drawn report has to be a function of the model's own logits, with the report itself held fixed.
The last run is a narrow control: cross-entropy on only three datasets, each label always under the same name.
Cross-entropy reaches 82% over the three test tasks — 92% on news sections, 53–57% on the five sentiment levels, 99% on spam — with a calibration error of 0.013–0.021 that a fitted temperature barely improves. The Brier score as a loss ends slightly behind, at 81% with a log loss of 0.47 against 0.43: it punishes a confident mistake less, so it learns less from one. The narrow control is just as accurate on the tasks it was trained for, 82%, but it states 91% on average, a calibration error of 0.091, and it knows much less of the world: 40% on the unseen emotions against 50–53%, and 5% on the banking intents against about 20%. Breadth costs nothing on familiar questions and pays on everything else, including honesty.
Step 5 — what the reward is compared against
REINFORCE does not follow the reward itself. It follows the advantage: how much better a report scored than some reference. Three references were tried.
The whole batch. A batch mixes label sets whose scores live on different scales: at the start of training a two-option question scores near −0.5 and a sixty-option one near −1. Most of the spread of rewards in a batch is then which kind of question this is, not which report was made. A baseline that does not depend on the report cannot bias the average gradient, but it leaves that whole between-task spread inside the advantage, and the signal about which report was better drowns in it. In these runs that coincided with a model that gives up whole tasks: it names science and technology for every news item (24%), very positive for every review (16%), and a single intent for every banking question while stating a probability of 1.0 for it.
The same question's other reports, each question divided by its own spread. Every task survives, at 79%, but the model states 86% on average, a calibration error of 0.105. The division is the cause. Once the model is sure of an answer, its four reports score almost alike, the spread is tiny, and dividing by it turns a negligible difference into a full-size push toward an even sharper report: every question pulls equally hard however little is at stake.
The same question's other reports, one scale for the whole batch. This one works: 80% overall, a calibration error of 0.024, fitted temperatures between 0.6 and 1.3 — within a point or two of cross-entropy, and ahead of it on the unseen emotions, 55–57% against 50–53%.
There is one more thing the reward needs, and it is easy to miss. The squared error is convex, so a drawn report scores worse on average than its mean, and the gap is the report's variance, per option. A policy paid the plain score of its reports is therefore paid for shrinking that variance, which it does by sharpening : a push toward overconfidence built into the estimator. For a Dirichlet the variance has an unbiased estimate from the report itself, , so it can be added back, and then the expected reward is exactly the proper score of . For an ordered scale the same correction goes on the cumulative probabilities, which under a Dirichlet have variance of the same form. On a report of (0.7, 0.2, 0.1) with the first option right, the lab measures the score of the mean at −0.1400, the plain reward averaging −0.1821, and the corrected reward −0.1402.
The same run without the correction shows the bias in the trained model: it states 86% where the corrected one states 80–82%, needs temperatures up to 1.7, and on the unseen emotions says 64% while being right 50% of the time.
centred = r - r.mean(1, keepdim=True)                    # the same question's other reports
adv = centred / (centred.std() + 1e-6)                    # one scale for the whole batch
The mean here includes the report's own reward. With a fixed number of reports that is exactly times the leave-one-out comparison, so it only rescales the step.
Done carefully — the right baseline and the correction — the reward gets back to where cross-entropy already was, a little behind on the trained tasks and a little ahead on unseen emotions. It does not get past it.
Step 6 — how to judge the number
A model's probabilities can be judged in several ways, and the ways disagree. Calibration error here is the usual estimate: answers grouped into 15 equal bands by stated probability, and the gap between stated and observed accuracy averaged over the bands, weighted by their size. On a finite sample, a value near 0 means this estimator finds no gap, not that there is none. The widget below puts eight common measures side by side, pooled over the three test tasks or one task at a time, before and after a temperature refit.
Resolution cannot compare models of different accuracy. Resolution measures how much the stated number separates questions that turn out right from ones that turn out wrong. That is meaningful for one fixed forecasting problem, but here the event being forecast is each model's own correctness, so every model forecasts an event with a different base rate — and a model that is wrong more often has more to separate. Pooled over the three tasks, the batch-baseline model, which gave up on two of them, has the highest resolution in the table, 0.062 against 0.047 for cross-entropy — and the lowest AUROC, 0.55 against 0.88. Its number separates the task it kept from the tasks it gave up, not right answers from wrong ones.
Perfect calibration, no information. On sentiment, the same model says the same thing about every review: its resolution there is 0.000. What it says could even be accurate on average; calibration alone would not reveal that the number carries nothing.
A Brier score that rewards being bad. The Brier score of the stated number, on the chosen option alone, is lower for that model on sentiment (0.17) than for cross-entropy (0.24): a model that is right 16% of the time and says 36% makes smallish squared errors. It mixes calibration, discrimination and each model's own base rate, so it is not a clean comparison between models. The Brier score over all options is, and it puts that model last.
The proper score of the whole distribution does not pool its way into a wrong answer. Log loss over all options is measured against the same true answers for every model and does not depend on how often a model is right; cross-entropy has the lowest.
Step 7 — the final model: options that do not read each other
The one weak spot in the numbers so far is seventy-seven options. On the banking intents the models above are right about one time in five. An option there reads the text, the question and all seventy-six other options — some four hundred tokens of other labels' names against a couple of dozen of the message.
So the final model changes one thing, the mask: an option reads the text, the question and its own tokens, and nothing else.
option = torch.where(q >= 2, (k == 0) | (k == 1) | (k == q), ...) # text, question, itselfFrom each option's point of view, a question with seventy-seven options now looks exactly like one with four, and an option's logit no longer depends on which other options are offered — checked on the untrained model, dropping two of four options changed the other two logits by exactly zero. Its probability still does: the softmax divides by a sum over whatever options are present, so adding an option can only take probability from the others, and in proportion — the odds between any two of them stay exactly as they were. The final model is trained with cross-entropy, two seeds, and once more with the large encoder, 395 million parameters.
On the banking intents accuracy goes from about 20% to 53–55%, and to 56.5% with the large encoder, with the right intent among the five most likely in about 80% of the questions. The stated probabilities there become honest: a calibration error of 0.05–0.08 instead of about 0.2. On the trained tasks nothing moves, 81.5%. On the six emotions the base model loses a few points, 45–49% against 50–53%, and the large model is at 54%. For a model meant to take any label set, that is a clear trade.
This is also the opposite of what outside measurements suggest Jev does: there, adding an unrelated option shifts the balance between the others, and an option's place in the list changes how often it is picked. Here an added option changes neither the others' logits nor the odds between them, and the order cannot matter.
Step 8 — label sets it was not trained on
The options are text in the input, so the same weights can be asked a question whose labels were in no training task. This is what is usually called zero-shot classification: label sets never used as options in training, described only by their names. The words themselves are not new to the encoder — joy and exchange rate are everywhere in its pretraining text — and that is what lets it match an unfamiliar label to a message at all. Two such label sets are held out: six emotions, and the seventy-seven intents of a bank's support inbox, such as card arrival or exchange rate.
The final model is right 45–49% of the time on the emotions (54% with the large encoder) and 53–57% on the banking intents. For scale: a random guess gets 17% and 1.3%, always answering the most common label 36% and 2%, and the narrow control 40% and 5%.
The probabilities travel less well than the answers. On banking the final model's numbers are close to honest, a calibration error of 0.05–0.08. On the emotions the large model states 67% and is right 54%. A temperature fitted on news, sentiment and spam says nothing about either, so a new label set needs its own held-out questions before its numbers can be trusted.
Step 9 — what it costs to answer
One decision is one forward pass, with no generation loop. Measured on a Kaggle T4, the final model:
| questions per call | base, half precision | base, full precision | large, half precision |
|---|---|---|---|
| 1 | 24 ms | 20 ms | 30 ms |
| 10 | 2.9 ms per question | 9.1 ms per question | 7.1 ms per question |
| 50 | 3.1 ms per question | 9.7 ms per question | 7.4 ms per question |
A single question pays mostly for launching the pass. In batches, in half precision, the base model settles at about 3 ms a question, over three hundred decisions a second on a small inference card from 2018. A seventy-seven-option banking question is longer: 23 ms alone, 12 ms each in batches of ten. If the same decision is asked of a generative model through a text interface — write the answer, then the confidence — every generated token is another decoding step of the network, usually a far larger one than this encoder. A generative model can also be used as a classifier, by reading its probabilities for each candidate answer instead of generating; the point is the interface, not the architecture. For typed decisions, the speed of this design comes from not generating.
Try it
Four of the trained models, first seed, answering the same held-out questions side by side: the final model, the narrow control, the reward with the working baseline, and the reward with the batch baseline. Sure and wrong jumps to answers that were confident and mistaken. The emotions and banking intents are the unseen label sets from Step 8.
If you are shipping one of these
- Say which number you are promising, whether the probability of the chosen option or a separate confidence, and write it in the API documentation.
- Train on many label sets. Breadth cost nothing on familiar questions here and paid for everything else: accuracy on unseen labels, and honest probabilities.
- Start from cross-entropy, and check it with a temperature. Here that matched or beat every fancier use of a proper score, and the temperature it needed was about 1.
- Compare models with a proper score over all options, task by task. Pooled resolution and the Brier score of the stated number both favoured a model that had given up on two tasks.
- Never report calibration without resolution. A model that says the same thing about everything can be perfectly calibrated and worth nothing.
- If the score becomes a reward, look at what it is compared against, and correct for the exploration. A baseline shared across kinds of question abandons tasks; a per-question baseline divided by its own spread, or a reward on noisy reports without a variance correction, makes the model overconfident.
- Do not let options read each other when there can be many. Seventy-seven options that read each other drowned the message; options that do not were right on more than twice as many questions.
- Treat every new label set as uncalibrated until it has held-out questions of its own.
- Set the gate threshold on validation data and report the coverage, not only the accuracy of the answers above it.
How far this is from Jev
Jev's makers publish no standard benchmark table, but a small independent pilot, with 100 questions per task, tested it on three of the datasets used in this note. The Laya column is Laya's own published numbers. "Built here" is the final model: the base encoder with two seeds, and the large one.
Accuracy (higher is better):
| label set | Jev | Laya | built here, base | built here, large | was a dataset on this topic in training here? |
|---|---|---|---|---|---|
| news sections | 0.91 | 0.947 | 0.91–0.92 | 0.90 | yes: the same dataset, but these test questions were never trained on |
| five sentiment levels | — | 0.372 | 0.53–0.54 | 0.56 | yes: the same dataset, but these test questions were never trained on |
| six emotions | 0.48 | 0.573 | 0.45–0.49 | 0.54 | no; the nearest is tweet sentiment (negative, neutral, positive) |
| 77 banking intents | 0.87 (on 72 of them) | 0.425 | 0.53–0.55 | 0.565 | no; the nearest is voice-assistant intents, of which only two touch money (currency and stock questions) |
Calibration error (lower is better; 0 means the estimate finds no gap between stated and observed):
| label set | Jev | built here, base | built here, large |
|---|---|---|---|
| news sections | 0.064 | 0.029–0.041 | 0.024 |
| six emotions | 0.35 | 0.065–0.090 | 0.13 |
| 77 banking intents | 0.054 (on 72 of them) | 0.050–0.077 | 0.055 |
Accuracy is how often the answer is right. Calibration error is the average gap between the probability a model states and how often it turns out right.
The news and sentiment rows flatter the model built here: it was trained on other questions from those very datasets, while Jev presumably met them cold. The emotions and banking rows are less confounded, since no model was trained on those label sets, though the models still differ in training data, size, exact questions and inference stack. On emotions the three are close, with Laya ahead. On banking the model built here is ahead of Laya and far behind Jev, with probabilities about as honest as Jev's; Jev's pilot used 72 of the 77 intents, a slightly easier question. Jev's emotion numbers are the more overconfident: in the pilot it gave the true emotion a probability of zero in 16% of the questions.
| questions per call, one T4 | Laya, per question | built here, large, half precision, per question |
|---|---|---|
| 1 | 39.5 ms | 30 ms |
| 10 | 15.9 ms | 7.1 ms |
| 50 | 15.4 ms | 7.4 ms |
Speed against Jev can only be compared roughly. Jev's service reports its own evaluation time with every answer: 76–221 ms on seven calls from its public playground, each with a few questions. An independent benchmark puts the median full call, network included, at 0.65 s. The model built here is a bare forward pass on one T4, with no network, no queue and no server around it. Neither measurement includes what the other does, so which one is faster is not settled here.
What it would probably take to close the gap, roughly in order of payoff:
- Many more kinds of question. Going from three label sets to twelve took the unseen emotions from 40% to about half and the banking intents from 5% to about 20% on the same model; the right mask then took banking to 55%. Hundreds or thousands of question types, which in practice means generating training questions synthetically, is the obvious next step. Jev's makers say their training data is generated in-house.
- Calibration that travels. A temperature per task works only for tasks with held-out data. Honest numbers on an unseen schema need training across so many schemas that calibration itself generalises, or a fitting step for every new schema.
- A much bigger model. Outside measurements of Jev's API suggest a network far larger than anything here, with billions of active parameters rather than hundreds of millions. If that estimate is right, it is probably a large part of the gap. I deliberately stay with models I can train on a single free T4: the large version of the encoder, at 395 million parameters, is as far as that goes.
- Several questions per pass. The text here never reads the question, so a text asked several questions could be read once and shared; the model is built for it, the experiments do not use it yet. It would make answering faster, not better.
- Reinforcement learning last, if at all. In this note it added nothing over the plain loss. Two of its three baselines broke something, the third needed a correction to stay honest, and then it only matched cross-entropy (Step 5).
Laya, found along the way
While writing this note I came across Laya, an open-source model of the same kind: typed questions, options in the request, one pass, a probability per option, trained with a proper-score reward. I read its code after building the model here. Where the model here is small or simple on purpose, to keep every experiment cheap enough to run many times, that simplicity is the point, and only its advantage is listed.
1. How the options enter the input
- Here: every option is a parallel branch of the sequence, starting at the same position, read out as the average of its own tokens; in the final model an option reads the text, the question and itself, not the other options.
- Laya: the options follow one another, each behind a marker token, in a fixed slice of the input that is shortened when there are many; the model reads the markers, and the order of the options is visible to it.
- Advantages here: the order of the options cannot change an answer, by construction rather than by training; no option name is cut to make room for the others; and an option's logit does not depend on which others are offered. On seventy-seven banking intents the final model is right 53–57% of the time, where Laya reports 42.5%.
- Advantages of Laya: its options read each other, and options that read each other did a few points better on the six emotions here (50–53% against 45–49% at the base size); Laya reports 57% there.
2. Size of the model
- Here: the base encoder, 149 million parameters, for every comparison; the large one, 395 million, for a single run.
- Laya: the large encoder with extra layers, 421 million parameters.
- Advantages here: a run takes twelve minutes on a free T4, so thirteen runs fit in an afternoon and a half, and each conclusion rests on more than one run.
3. How much text is read
- Here: 256 tokens of text.
- Laya: 512 tokens, or 1,024 in some versions.
- Advantages here: shorter sequences, faster training and answers; every dataset here fits.
4. The head
- Here: a small read-out that turns each option into one number.
- Laya: an embedding for the kind of question, two extra transformer layers, the scorer, and a second head that decides whether to answer or escalate, weighing fixed costs.
- Advantages here: fewer parts, each easy to test on its own; the decision to answer or hand over is a threshold on the probability.
5. Scope
- Here: one question about one text, options as bare names.
- Laya: multi-turn conversations with targets propagated through the episode, and a description for every option.
- Advantages here: one clean question per experiment: what the reward adds.
6. The scoring rule
- Here: the squared error — the Brier score, and its ranked form for ordered scales.
- Laya: a mix of the logarithmic and spherical scores, minus a ranked term for ordered scales.
- Advantages here: it is the rule the note derives, and it is bounded, so as a reward it has bounded variance.
- Advantages of Laya: the logarithmic score punishes a confident mistake far harder, a stronger signal to learn from; used as a plain loss here, the squared error ended slightly behind cross-entropy.
7. Exploration in the reward
- Here: reports drawn from a Dirichlet whose mean is the distribution the model ships, with the variance correction from Step 6; no cross-entropy term, so the reward's own effect is visible.
- Laya: Gaussian noise on the logits, shrinking over training, and a full cross-entropy term added to the reward's loss.
- Advantages here: the expected reward is exactly the proper score of the distribution shipped; without the correction, the model here was measurably overconfident, and noise on the logits carries the same kind of bias.
- Advantages of Laya: the cross-entropy term steadies training, and the results here say that term does most of the work anyway.
8. Temperatures
- Here: one per task, fitted on its held-out questions.
- Laya: one per kind of question and number of options, clamped to a safe range.
- Advantages here: more exact wherever a task has labelled questions to fit on.
- Advantages of Laya: it gives a temperature to a new label set that has no labelled questions of its own.
9. Speed
- Here: the final model with the large encoder, in batches of ten on a T4, 7.1 ms per question in half precision and 25 ms in full precision.
- Laya: 15.9 ms per question in batches of ten on a T4, precision not stated.
- The published numbers cannot settle which is faster: about twice as fast if both are in half precision, somewhat slower if Laya measured in full precision.