01
Data Storage Formats
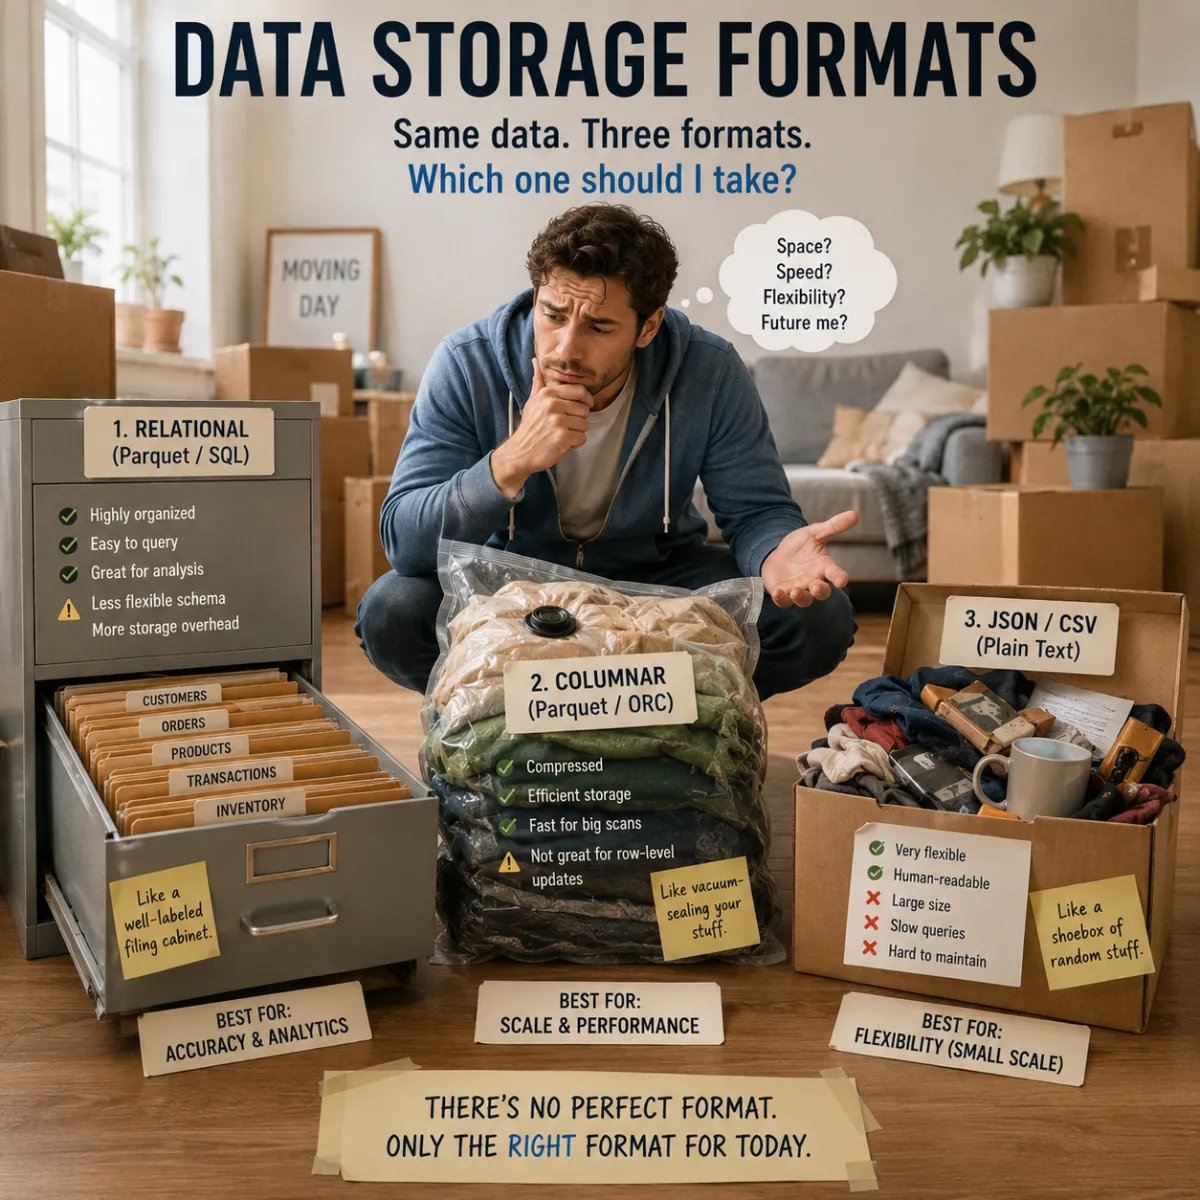
Why CSV, JSON, and Parquet all coexist in real pipelines: file size, read speed, and tool compatibility rarely peak in the same format.
- csv
- json
- parquet
Read
Updated May 4, 2026 Section 1 of 8
Storage formats, streaming, object stores, relational databases.
6 items in this section.
Why CSV, JSON, and Parquet all coexist in real pipelines: file size, read speed, and tool compatibility rarely peak in the same format.
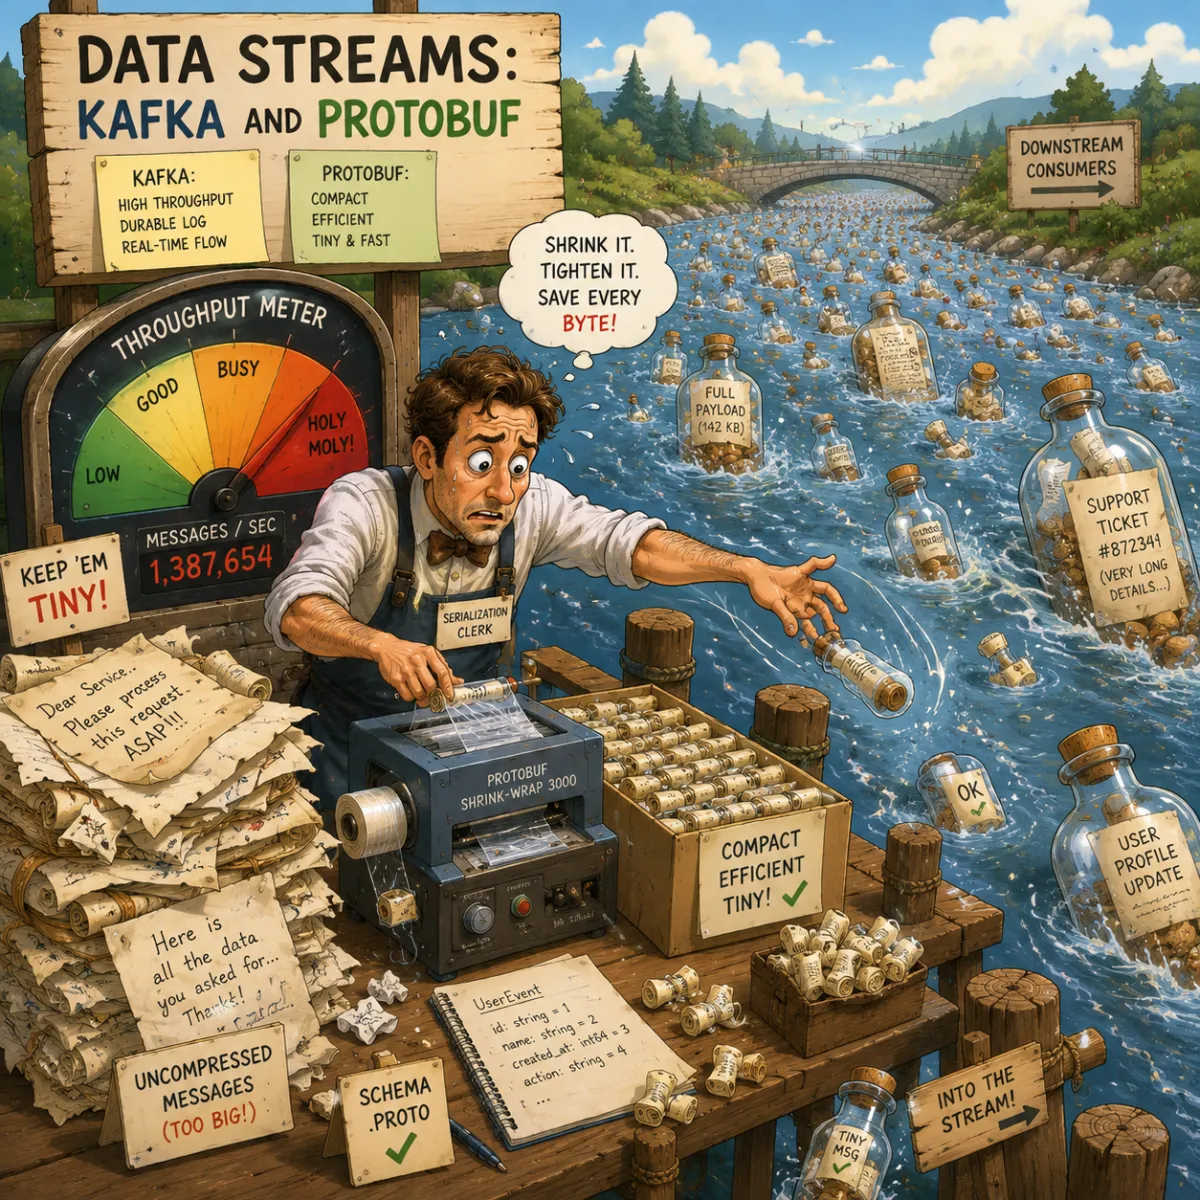
Kafka as a distributed log for streaming data transport, and Protobuf as a compact binary serialization format — how each works, when to use them, and why they pair well together.
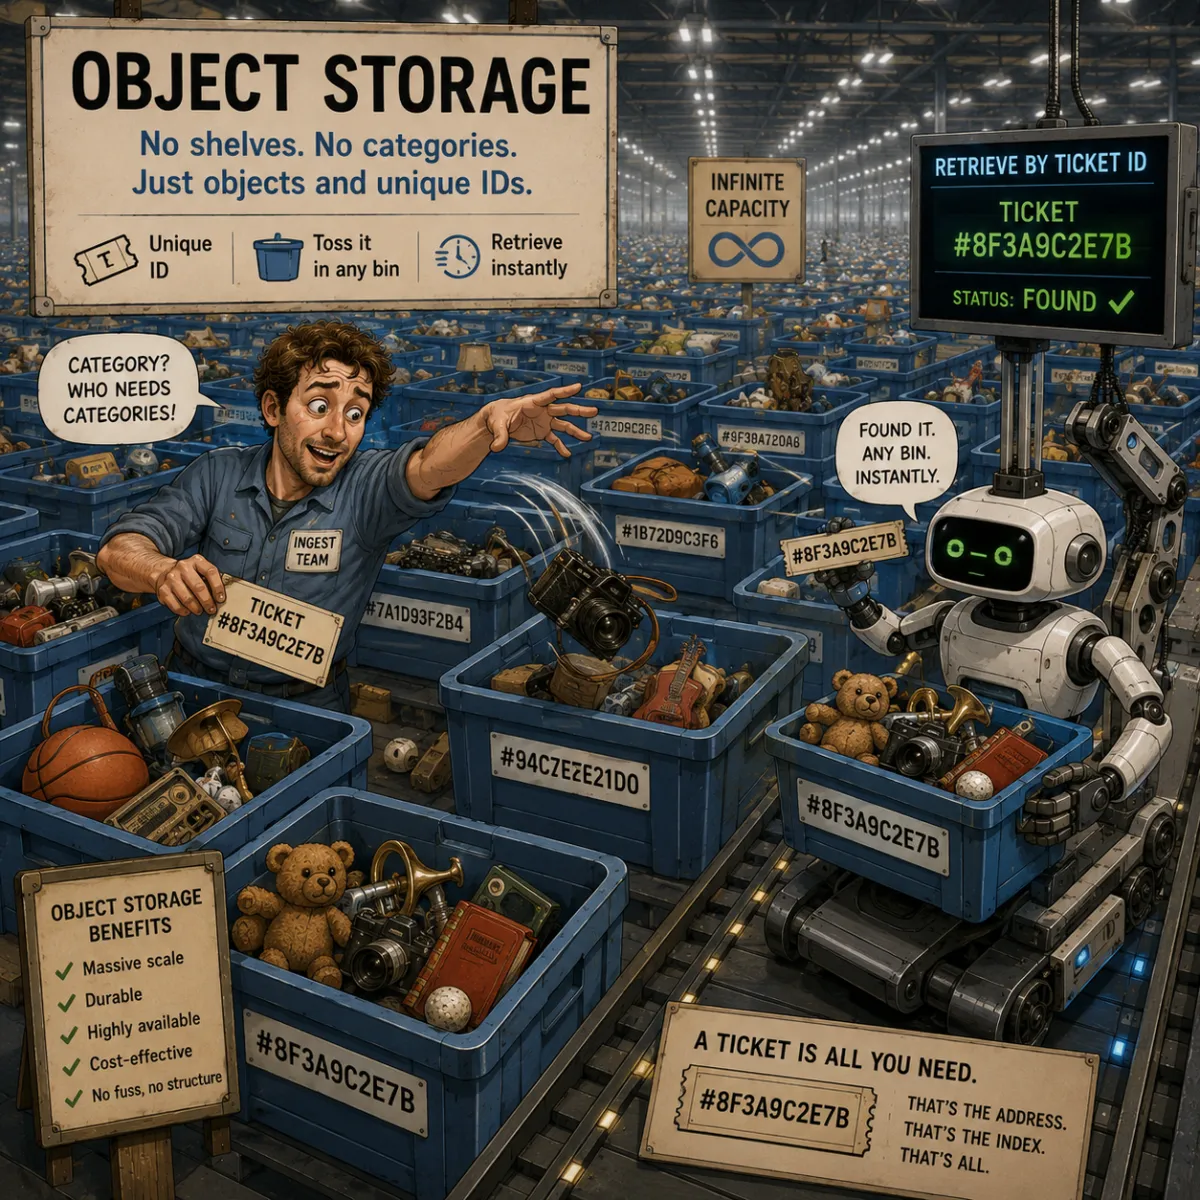
Covers the object storage model — buckets, keys, versioning, lifecycle policies — and Minio as a self-hosted S3-compatible implementation.
A practitioner's overview of PostgreSQL: how it handles concurrency (MVCC), its type system, index types, and the Python tooling stack for working with it.
The same data, two layouts on disk. For analytical queries that touch a few columns out of many, Parquet reads tens of times less from disk than CSV — and that gap is structural, not a benchmark artifact.
Partition count is the ceiling on parallel consumption. Ordering is a per-partition guarantee, not a per-topic one. Two facts that decide most Kafka architecture questions.